Working With Synonym Lists In Practice
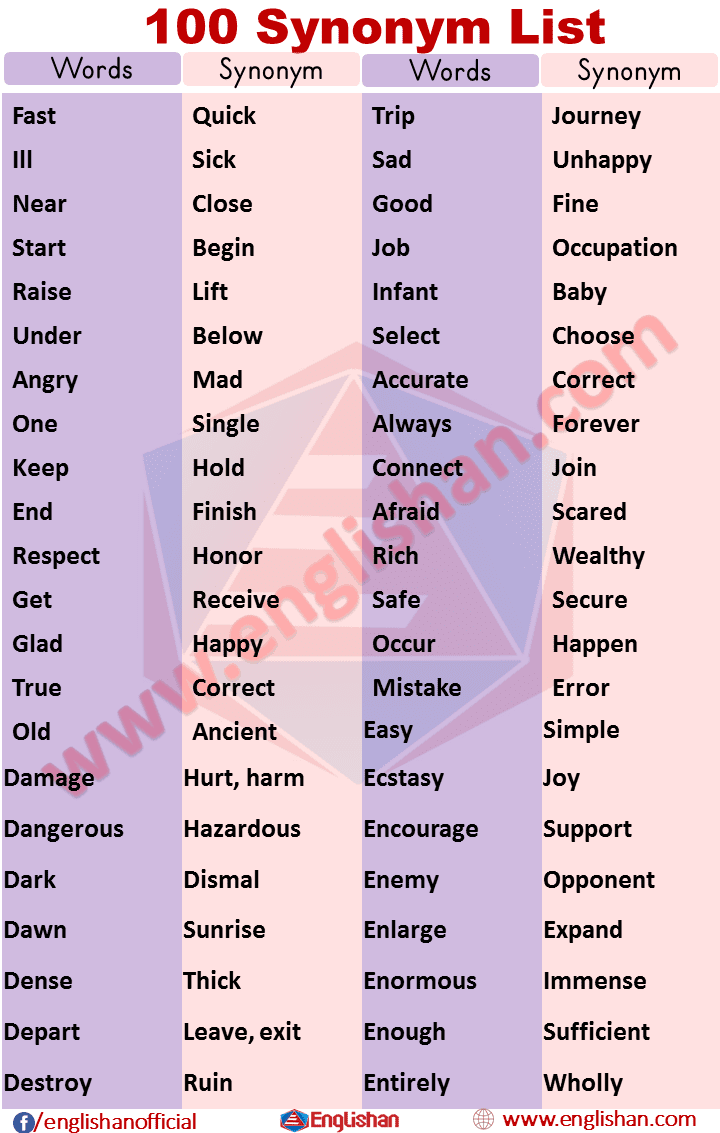
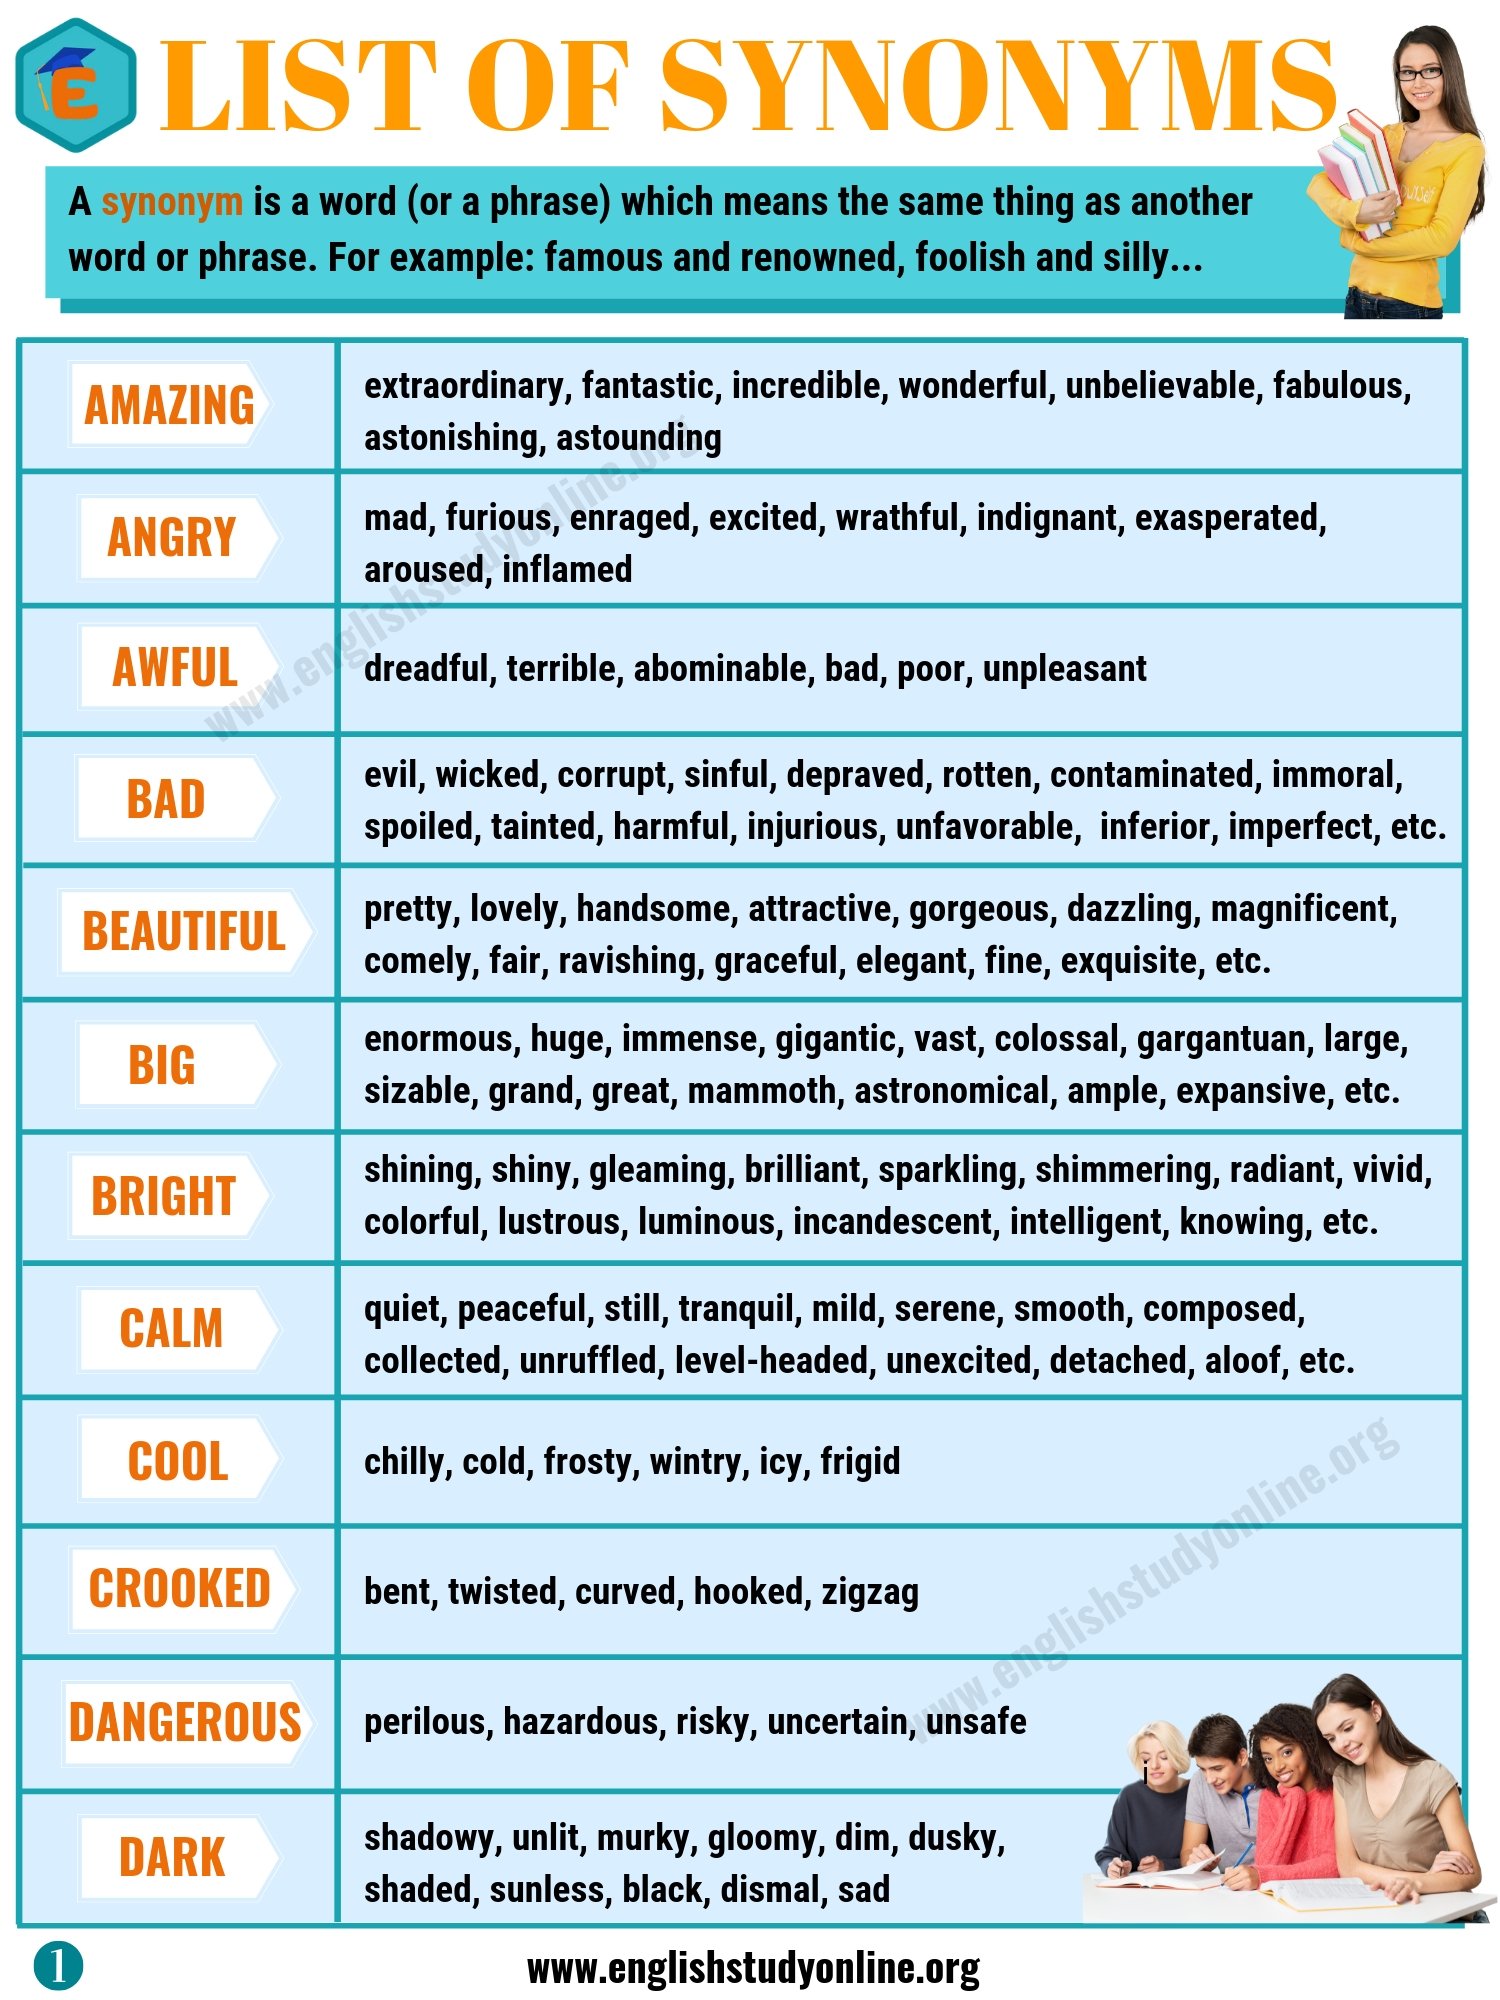
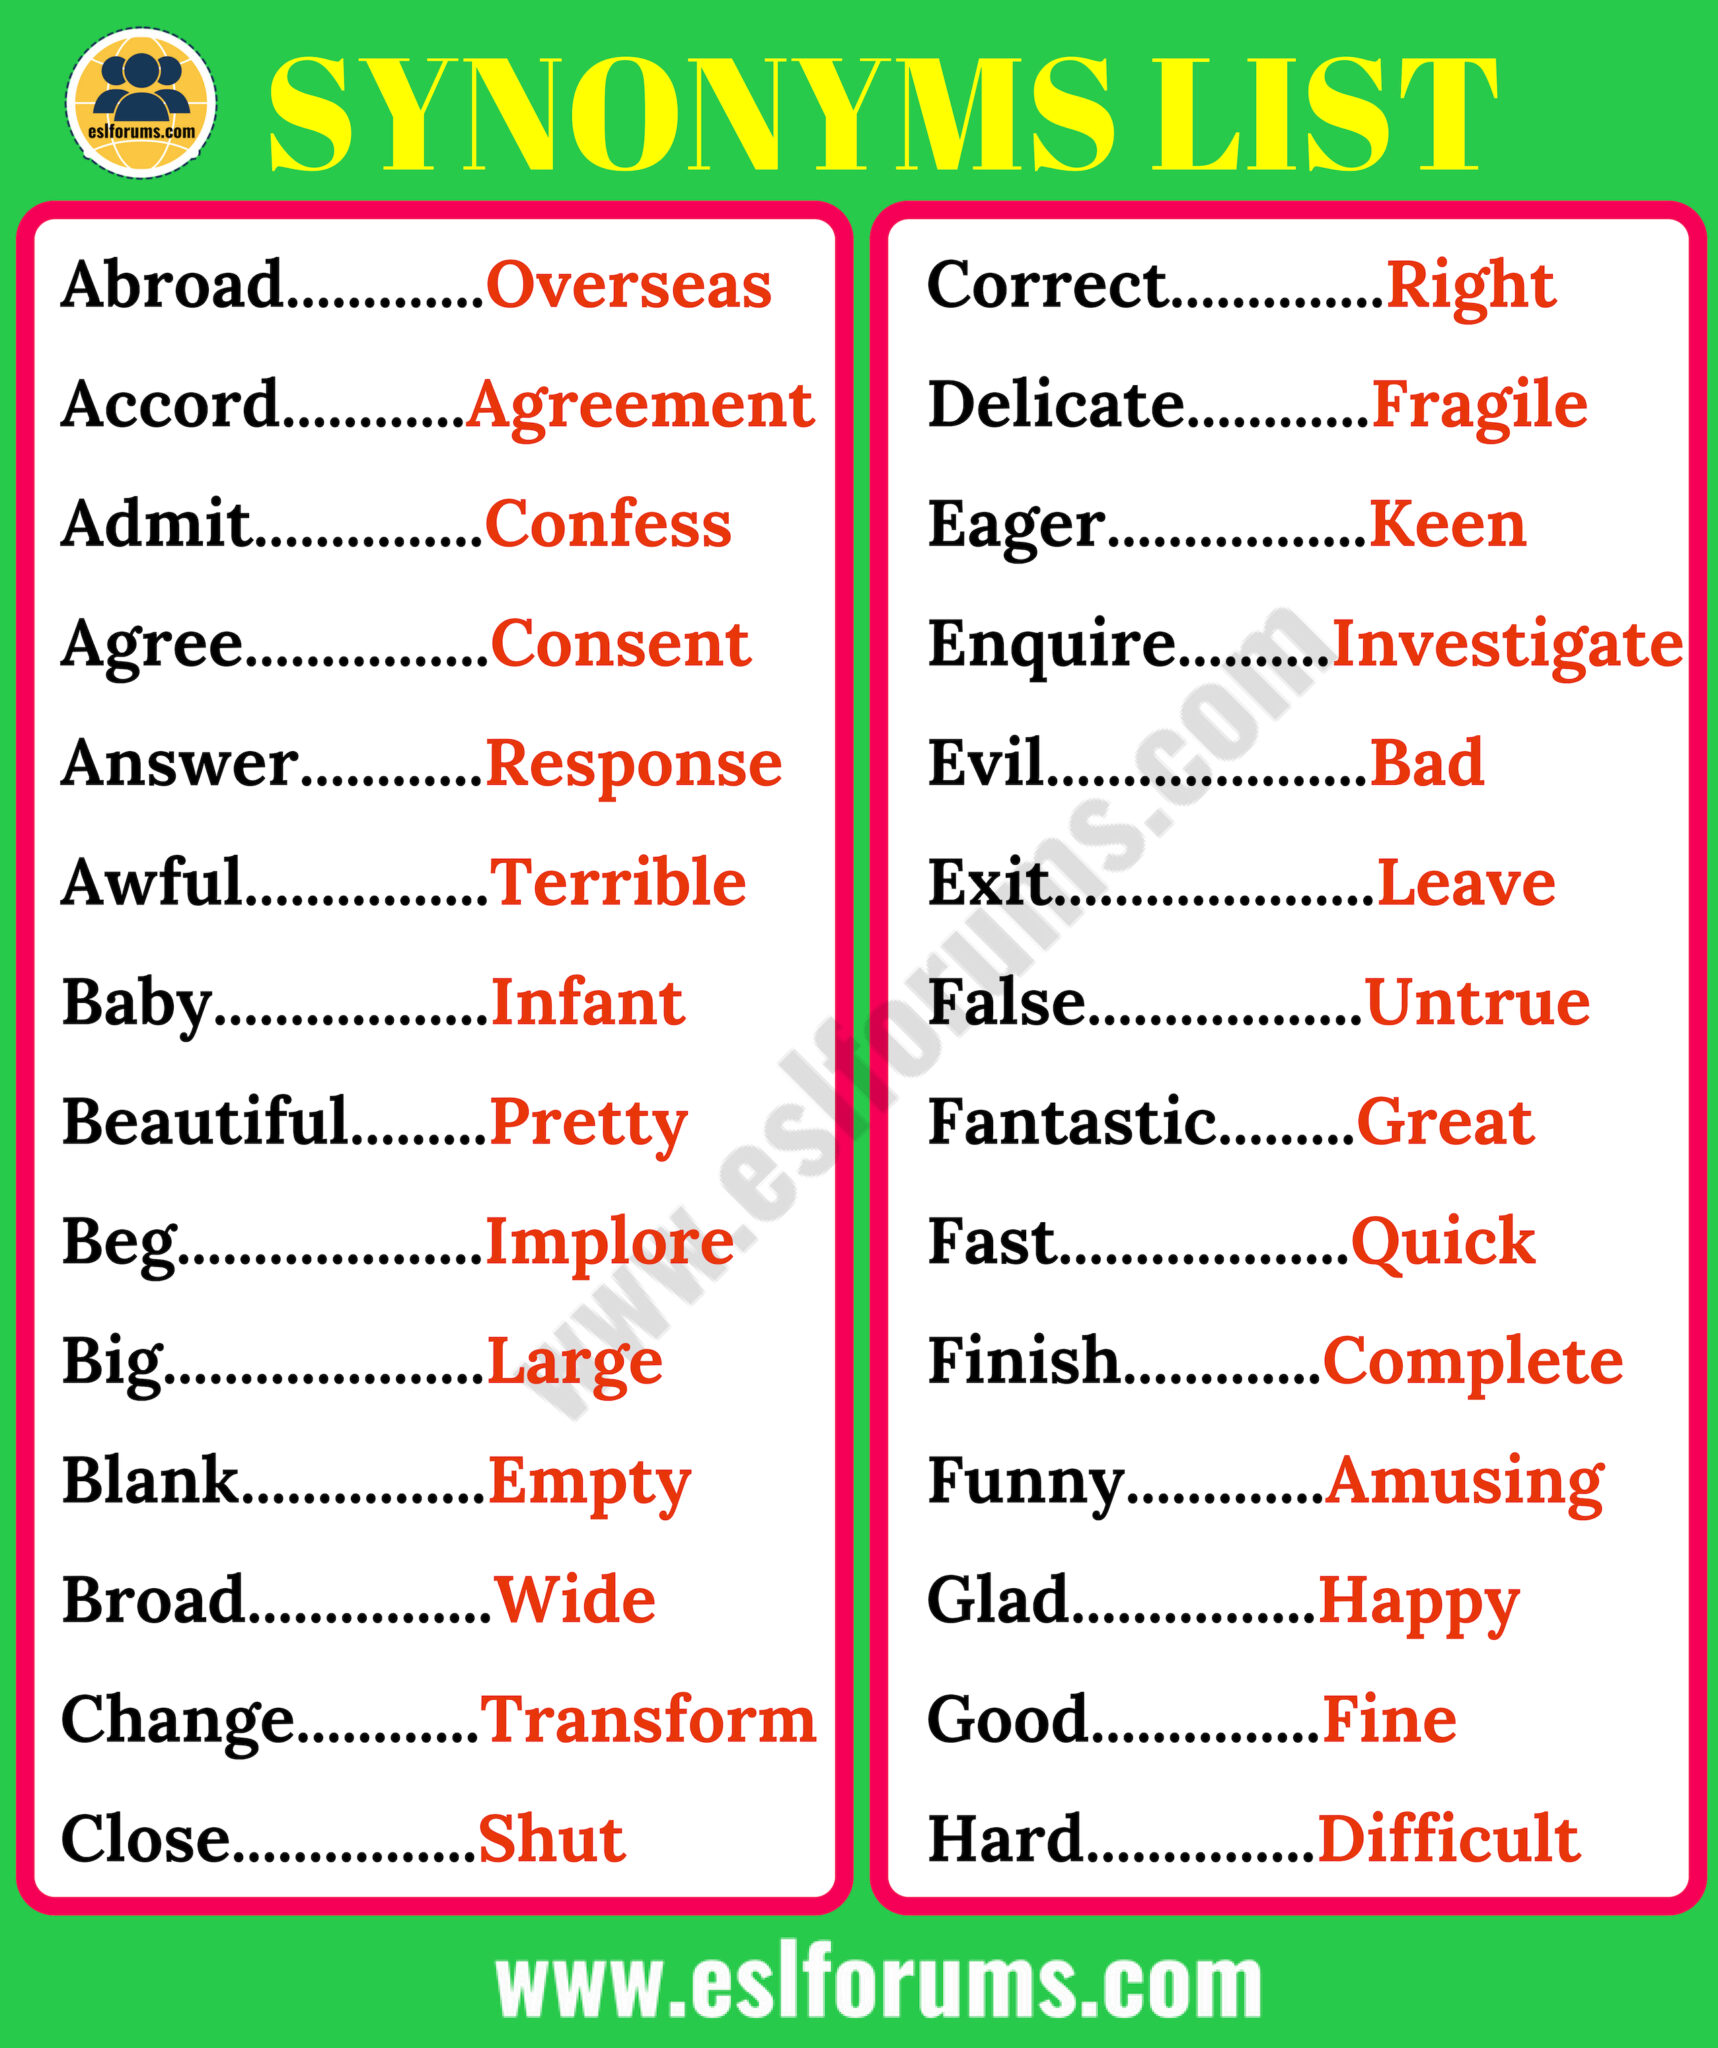
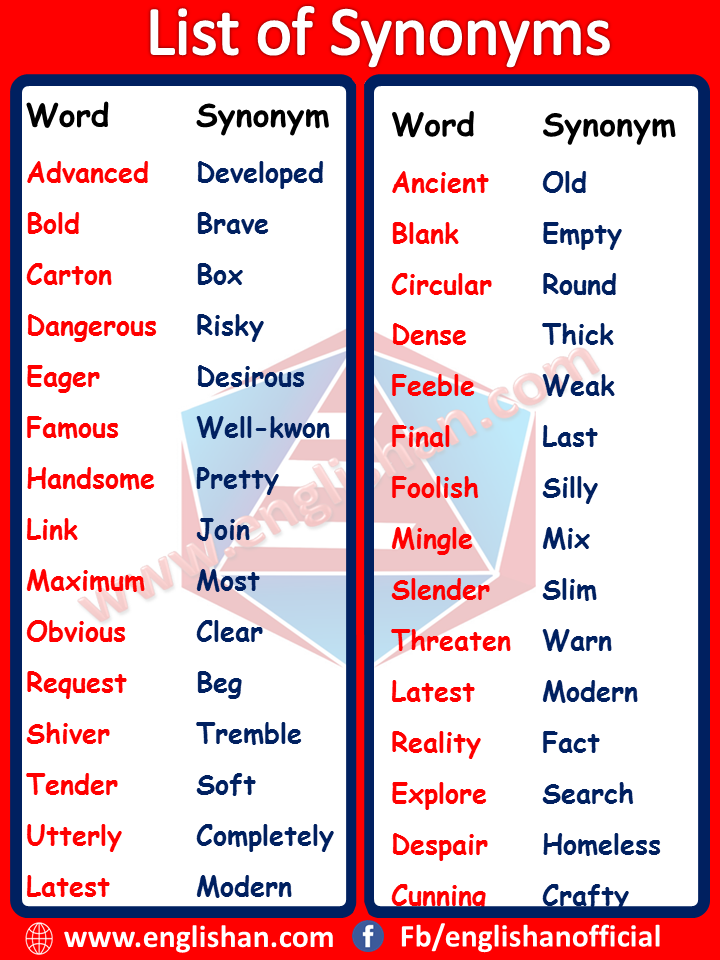
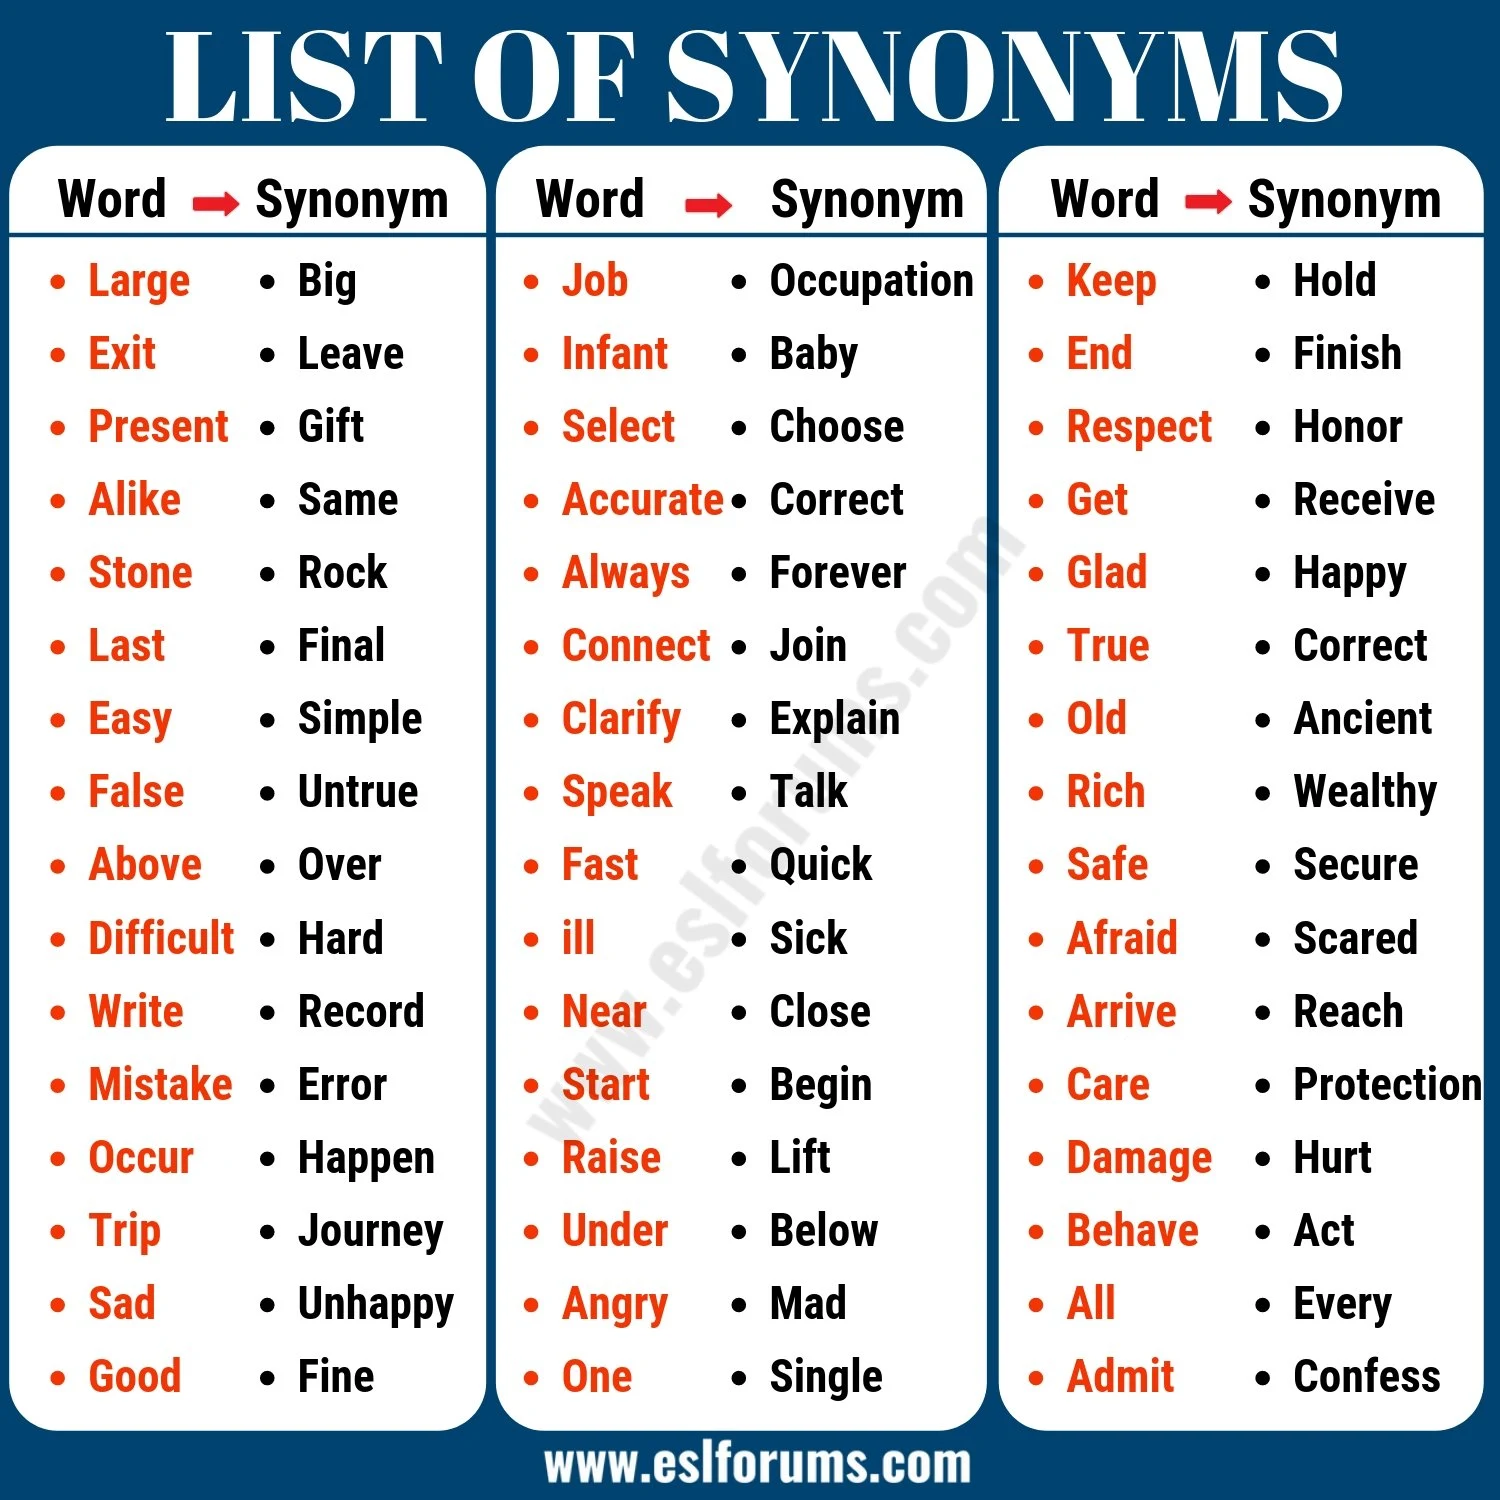
Everyone tells you to grab a synonym list and plug it into your search or NLP pipeline, but nobody warns you about what happens when you actually try to maintain one past the first week. The List Of The Synonyms is useful only if you understand how thin the surface is between a working system and one that quietly breaks your outputs. Below is the unglamorous version of how I deal with this stuff. The concept itself is straightforward. You have a primary term and a set of alternate words that map to it. The value is in query expansion, fuzzy matching, and deduplication of user input. Where people trip up is treating the list as static. It is not static. Even well-curated internal glossaries drift within a quarter if you are pulling them from user-generated content or auto-extracting terms from logs. In my own work, I run a small thesaurus layer over a product search system. The list sits as a flat JSON file because that was the quickest thing to deploy in year one. It grew to about 18,000 entries before we started seeing odd ranking behavior. The problem was not the size. It was that several entries had circular mappings. "Sneakers" mapped to "shoes," "shoes" mapped to "footwear," and "footwear" mapped back to "sneakers." The deduplication code ran three full passes and returned inconsistent canonical IDs depending on the processing order. I fixed it by switching to a directed graph representation and running a topological sort to assign canonical roots. Once I did that, the flaky results stopped. Took about four hours to refactor and reindex. The old flat file approach saved time upfront but cost weeks of troubleshooting later.
How To Build Something That Does Not Break Immediately
I prefer to keep the workflow simple rather than architectural. The steps below are what I actually use, not what a textbook would suggest. Start with whatever you have. Internal documentation, help articles, user-submitted tags, existing metadata fields. Pull everything into a single dump. Do not clean it yet. Cleaning too early removes the noise you actually need to see. I keep the raw dump for at least two weeks before removing anything. It helps you spot patterns like duplicate entries with slight spelling variations or domain-specific slang that shows up in unexpected places. Lowercase everything. Strip punctuation. Collapse whitespace. Handle accent variations with something like unicodedata normalization if your audience uses accented text. This step usually removes about thirty percent of false duplicates before you even run a merge pass. I run a quick Unicode NFKC pass and then a custom regex to strip non-alphanumeric characters except for apostrophes inside words.
Use a union-find structure or a simple BFS traversal across terms to group synonyms. If term A relates to B and B relates to C, they all belong in the same group regardless of whether A and C are directly linked. I wrote a small Python script using networkx for the graph traversal, then output each component as a single canonical group. The script runs on a 15,000-entry file in roughly twenty seconds on a modern laptop. For larger files, I shard by language prefix and process in parallel. This is the step most people skip. Take a sample of actual user queries from your logs and run them through your synonym expansion. Check whether the expansion helps or hurts. I keep a small dashboard that tracks hit rate and relevance score before and after applying the list. If expansion improves recall but tanks precision, you have over-broad mappings. Trim them. I usually cut entries that link unrelated domains, like mapping "bank" to both financial institution and river edge without context. One issue that comes up constantly is polysemy. The word "crane" means a bird and a machine. A naive synonym list will merge these into the same group and confuse any downstream system. I solve this by tagging entries with a domain or part-of-speech field, then splitting the group during expansion based on context. If your system does not support tagging, at least maintain two separate list files for ambiguous terms and load them conditionally.
Get the Full Details
Another problem is stale cross-references. When someone retires a product name or rebrands a category, their old synonym entries become dead weight. Dead entries cause unnecessary expansion and slow down lookups. I run a monthly diff against our active catalog and remove any term that has not appeared in the last sixty days of query logs. This keeps the list lean without requiring manual curation of every entry.
What This Approach Cannot Do For You
A synonym list will not fix poor semantic understanding. If your search ranking depends on intent detection, expanding "laptop" to "notebook" and "computer" does not make the system smarter. It makes it wider. You still need embeddings, BM25, or some form of intent classification to handle cases where the expanded terms are technically correct but contextually irrelevant. The list is a tactical tool, not a strategy. It also struggles with low-resource languages. If you are maintaining a multilingual list and one language has fewer mapped entries, your expansion will be uneven. Users searching in that language will get noticeably worse results. The workaround is to set language-specific thresholds or to rely on a separate retrieval model for underrepresented languages rather than forcing the synonym list to carry weight it was not designed for.
Practical Notes On File Format And Maintenance
I store the final output as a JSON Lines file with one object per line. Each object contains a canonical_id, a list of variants, and optional metadata like domain tags and last_updated. JSON Lines is easier to stream and shard than a monolithic JSON array. Loading a million lines takes about eight seconds with a standard parser. CSV works too but handling nested variant arrays becomes messy quickly. Schedule a quarterly review even if you automate the cleanup. Automation catches obvious drift. Human review catches the edge cases that the scripts miss, like new slang, regulatory term changes, or internal rebranding that was never documented properly. I spend about three hours per quarter doing this. It is not glamorous work. It prevents months of degraded performance later. If you need a starting point rather than building from scratch, public datasets like WordNet or OpenThesaurus can seed your list, but expect to spend significant time curating them for your specific domain. Generic word lists contain a lot of entries that will not match your use case. Start with your own data whenever possible, then supplement from external sources only where you have gaps.