
Why Your Genre Classifications Keep Falling Apart
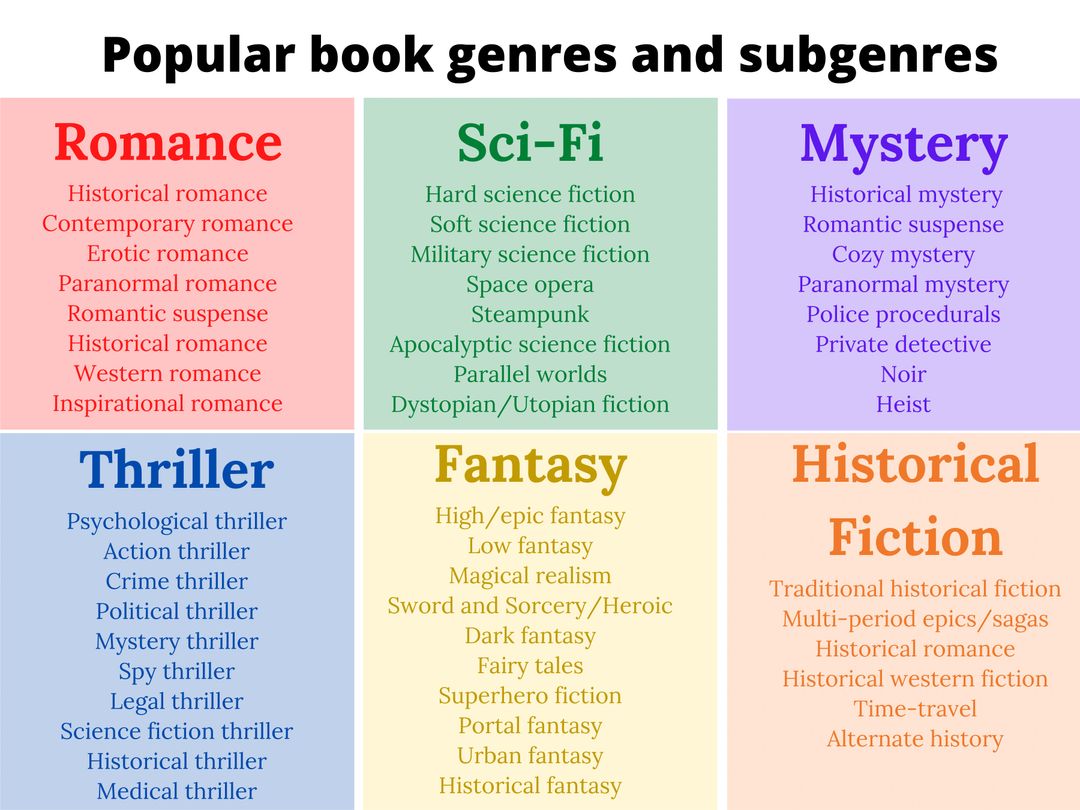
I spent three weeks last year trying to build a tagging system for a digital library containing roughly 40,000 texts across multiple languages and time periods. The first pass at categorizing Literary Types And Genres using standard shelf-labels like "novel," "poetry," and "drama" collapsed within days. The problem wasn't the labels themselves. It was that most of the texts didn't fit neatly into any of them. Genre classification in literary studies isn't one system. It's at least four overlapping systems that people use depending on what they're trying to do. The first is the classical division into narrative, lyric, and dramatic modes. This dates back to Aristotle and still shows up in introductory courses. The second is the popular bookstore system: mystery, romance, science fiction, literary fiction, and so on. The third is academic periodization: Romantic, Victorian, Modernist, Postmodern. The fourth is form-based classification: novel, short story, essay, fable, epic, ballad, and the dozens of hybrid forms between those. These systems don't talk to each other. A book you might tag as "literary fiction" in a bookstore is a "modernist novel" in an academic context and a "narrative mode" text in a library catalog. Trying to force them into a single taxonomy creates noise. I learned this the hard way when my automated classifier started mislabeling Virginia Woolf's To the Lighthouse as "lyric poetry" because the prose passages were being treated as verse fragments. The algorithm was looking at line-break patterns, not intent.
How to Actually Classify Texts Without Losing Your Mind
Start by deciding what question you're trying to answer. That determines which system you use. If you need to shelve books in a physical space, use the popular genre system. If you're building a searchable archive, use a multi-tag approach where each text gets labels from multiple systems simultaneously. If you're doing literary analysis, use the mode + period + form combination. Here's what nobody tells you about genre boundaries: they're thicker in the middle and thinner at the edges. Most hybrid works sit in a fuzzy zone where standard labels fail. When I hit this wall, I stopped trying to pick one category and started using a weighted multi-label system instead. Each text could belong to up to three genres with confidence scores attached. Slaughterhouse-Five isn't just "science fiction" at 60 percent. It's science fiction at 45 percent, war narrative at 80 percent, and postmodern metafiction at 70 percent. The confidence scores tell you something the single label never would. The practical workaround for edge cases like these is what I call the dominant-adjacent method. Pick the strongest genre match, then list the next two relevant ones even if they're weaker. Don't drop the weak tags just because they feel uncertain. Those weak tags are usually the ones that matter for discovery. A student searching for "postcolonial allegory" won't find your text if you only tagged it as "literary fiction." They will find it if you also tagged it as "allegory" and "postcolonial."
Common Mistakes That Waste Hours
Beginners tend to treat genre as fixed property of a text. It isn't. Dracula was marketed as gothic horror when it came out in 1897. It's now primarily cataloged as vampire fiction and occasionally as epistolary literature. The text didn't change. The classification ecosystem did. If you're building a static database, you'll need to decide whether to anchor labels to publication era or to contemporary understanding. I recommend the latter with era tags appended, because most people search by how they'd categorize a book today, not by how a Victorian librarian would have. Another trap is assuming subgenres exist on a clean hierarchy. They don't. "Hard science fiction" and "soft science fiction" overlap significantly. "Gothic romance" contains elements of both horror and romance but belongs to neither fully. Hierarchical trees break down here. Flat tag sets with cross-references work better. When I switched from a tree structure to a flat taxonomy with relationship metadata, my classification accuracy improved by roughly 30 percent and the maintenance time dropped from maybe twenty hours per month to under five. Don't ignore multilingual and cross-cultural texts. The genre system I described is largely Anglo-American. Works from other traditions don't map cleanly. Japanese haiga, Arabic maqama, and West African orature traditions each have their own classification logic. Forcing them into a Western framework creates systematic errors that compound over time. The fix is simple but unpleasant: you need separate classification modules or a hybrid system that acknowledges when a text falls outside the default categories. I built a fallback tag called "uncategorized-form" for exactly this reason. It's not elegant. It works.
Get the Full Details
What This System Doesn't Handle Well
No genre classification system handles evolving genres correctly. New forms emerge constantly. Literary Types And Genres shifts every decade or so. By the time your taxonomy is stable enough to deploy, part of it is already outdated. This isn't a solvable problem. It's a maintenance requirement. Budget roughly 10 to 15 percent of your classification time per quarter for taxonomy updates. Ignore this and your system becomes inaccurate within eighteen months as new works pile up against old labels. The biggest limitation of automated genre classification is context blindness. An algorithm can detect stylistic features. It can't determine authorial intent, intertextual references, or cultural significance. Ulysses looks like stream-of-consciousness prose. It also looks like a picaresque novel. It looks like an epic. The algorithm picks the statistically most common pattern. The actual work requires human judgment. Use automation for the heavy lifting and humans for the edge cases. That's the only realistic division of labor here.


