Building a Slide Deck That Actually Explains How Transformers Work
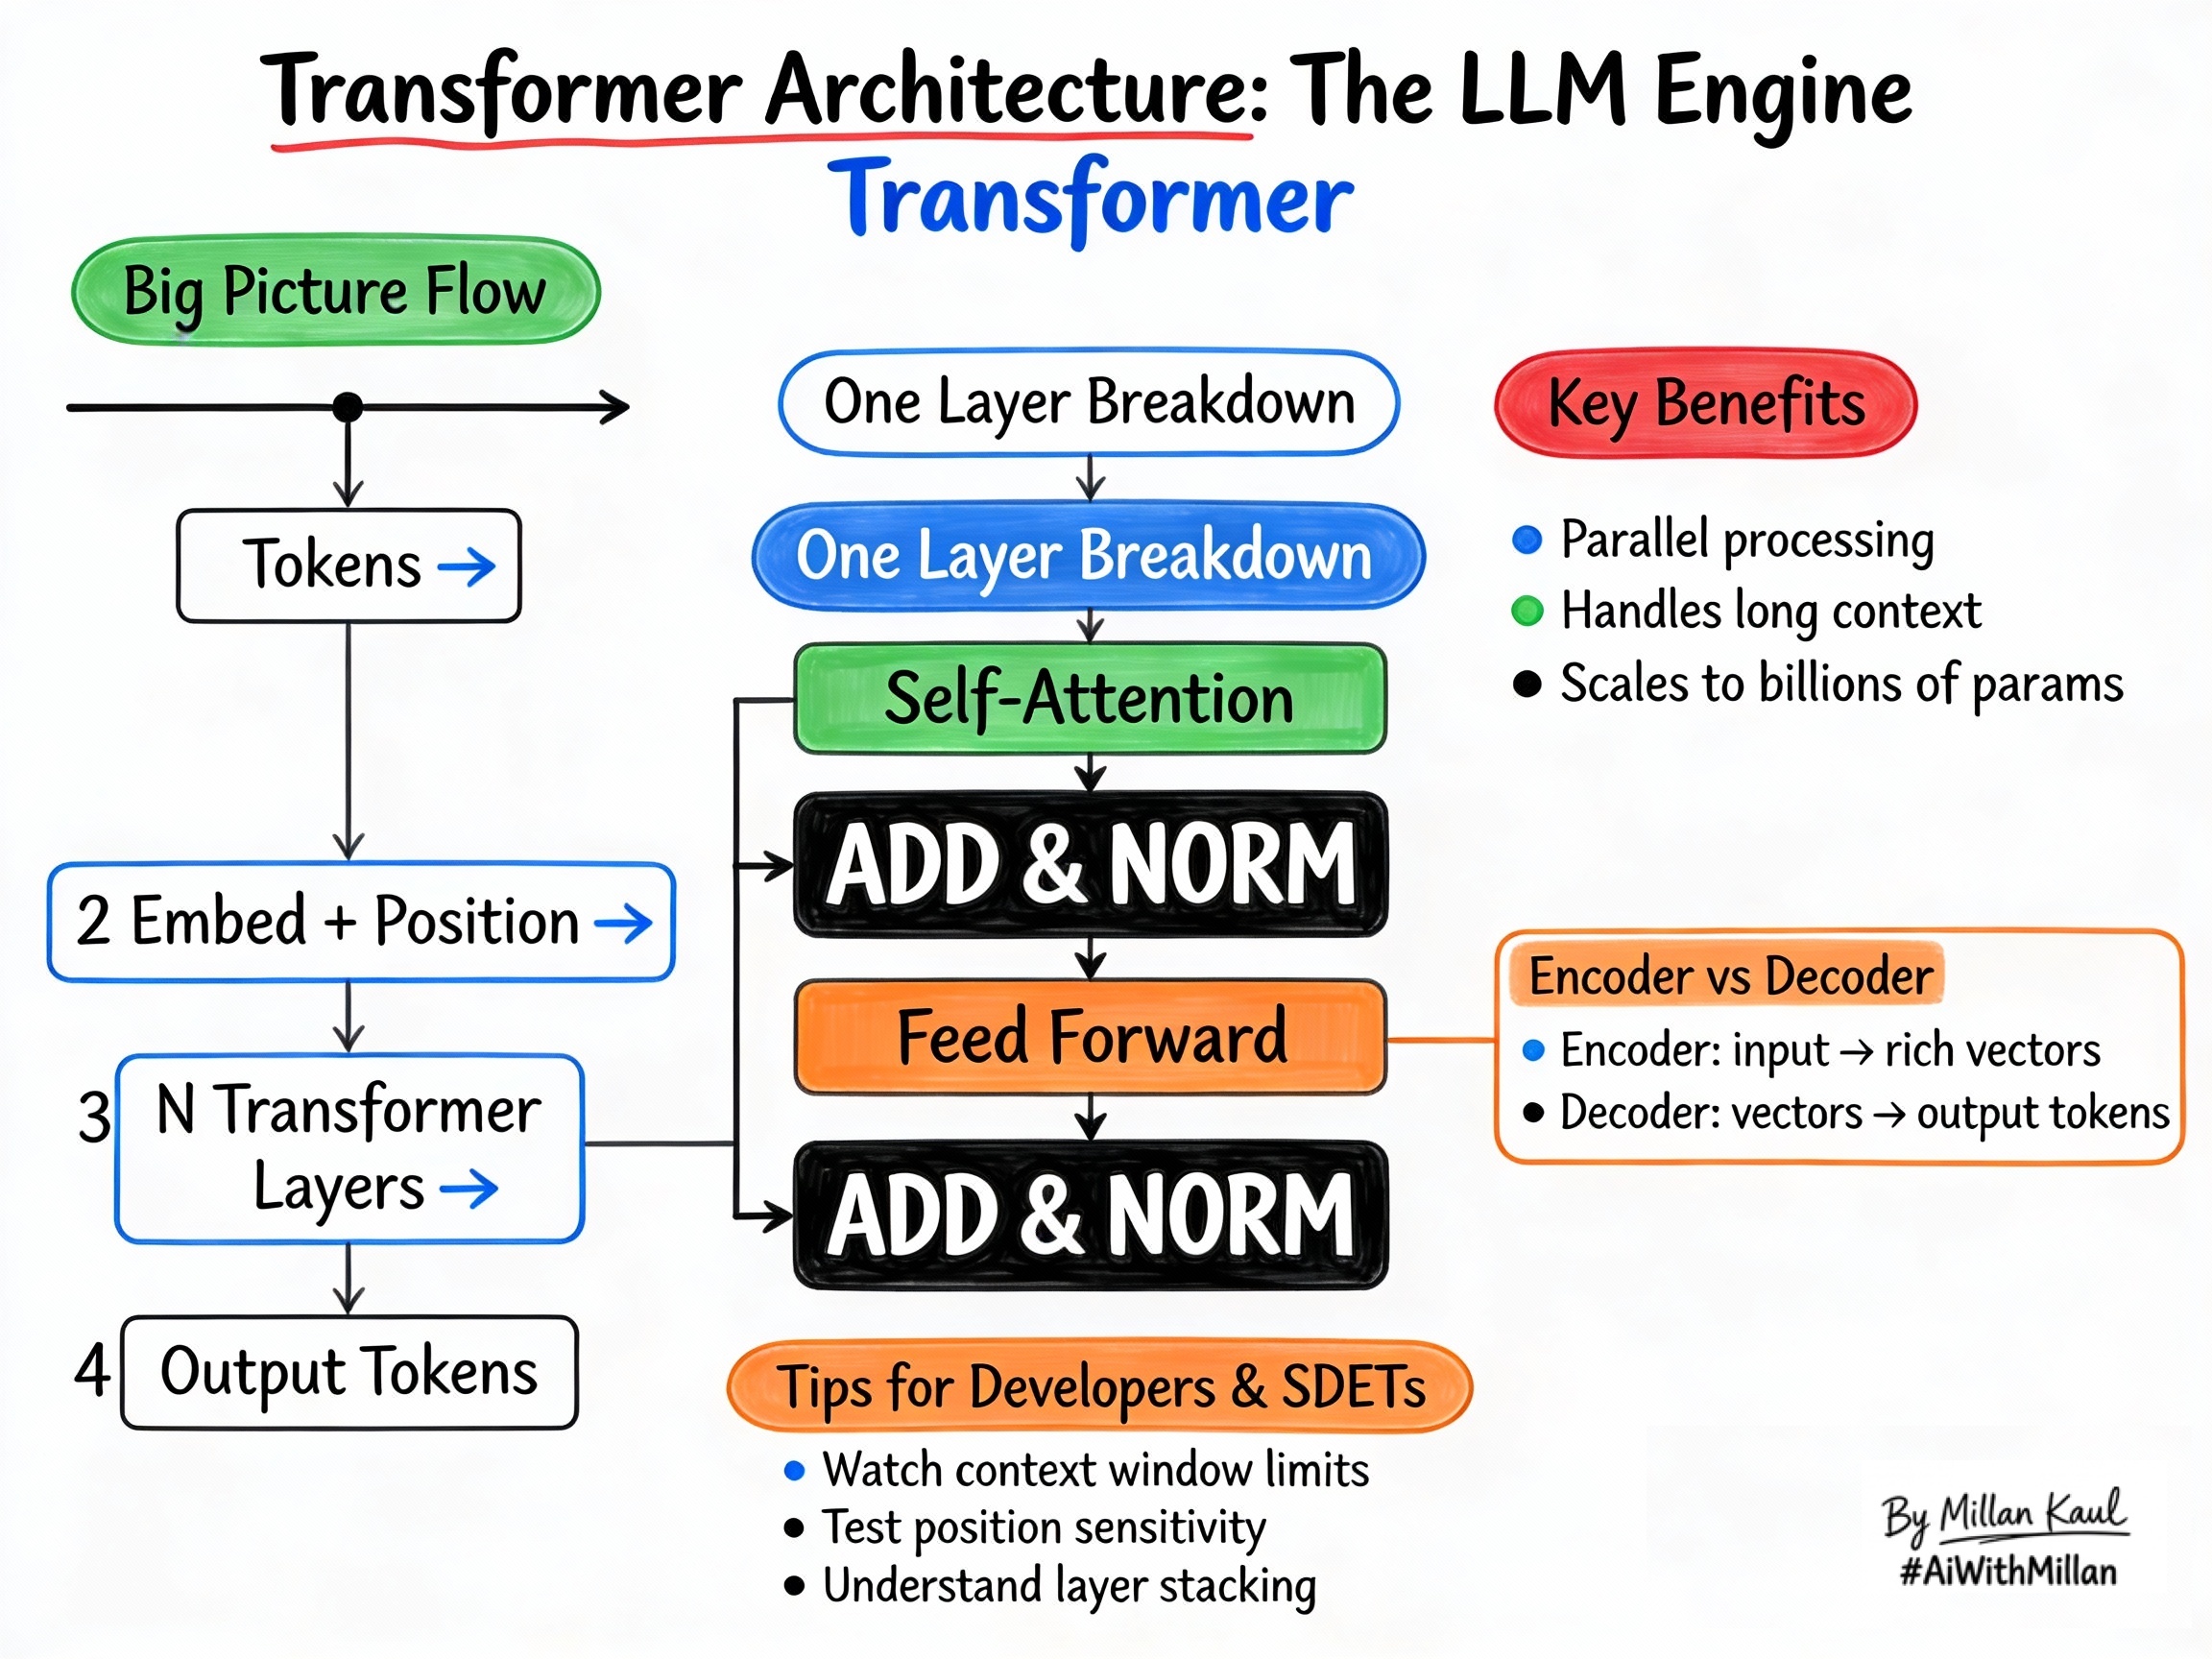
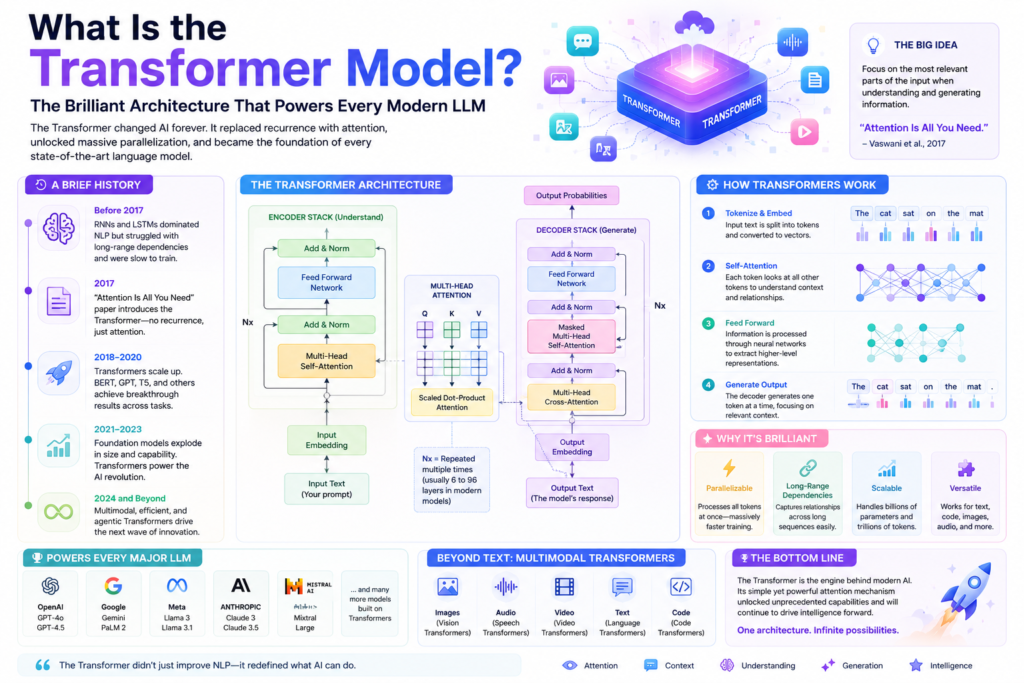
Most people trying to explain the Transformer architecture in a presentation end up dumping attention mechanism diagrams on an audience that has never seen a matrix multiplication. It does not go well. I spent a few weeks building a clear Llm Transformer Explain Ppt walkthrough, tearing down a dozen existing decks in the process, and ended up with something that actually lands with both engineers and non-engineers in the room. I looked at maybe twenty free slide decks online before settling on building my own. The ones made by startups are sales pitches disguised as education. The academic ones assume you already know what positional encoding is and skip straight to layer normalization tricks. Neither camp is helpful if you are starting from zero and need to convey the full picture in 20 to 30 slides. Here is a specific thing that drove me nuts. I was trying to explain the multi-head self-attention mechanism to a room of product managers, and I kept using the standard query-key-value diagram. Nobody caught it. Not one person. I tried rephrasing. Same result. Eventually I just abandoned the QKV formalism entirely for that audience and described it as "the model looking at every other word in the sentence and deciding which ones matter right now." Two minutes, total buy-in. The formal notation came later, and even then only as a footnote. That was my first lesson: the diagram that looks correct on paper is not always the one that communicates.
How I structured the deck
I did not follow a linear textbook path. Here is the order that actually worked for me when presenting: Slide 1-3: What the model does, not how it works. Show a raw input string and the raw output probabilities. Let people see the thing they are trying to understand in action first. This takes about three slides. You are establishing context, not diving into mechanics. Slide 4-6: The core insight, stated plainly. Language is relational. A word's meaning depends on the words around it. Attention is just a mechanism for computing those dependencies efficiently. Three slides, no equations yet. If your audience gets this, the rest is implementation detail.
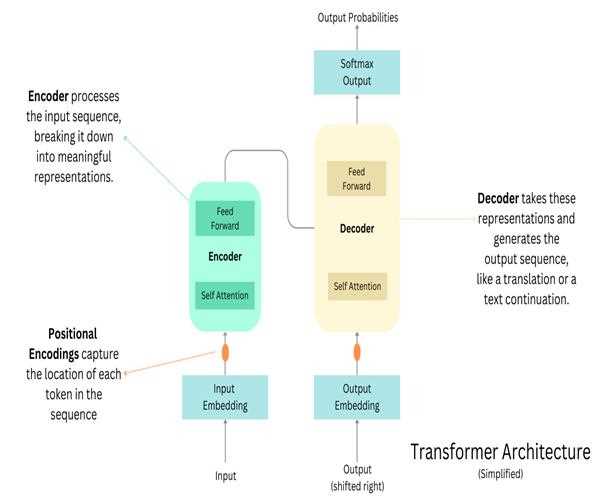
Slide 7-12: The encoder architecture, broken down piece by piece. I started with the single-head attention block, showed the math only after the intuition, then expanded to multi-head. The positional encoding slide came after people understood why position mattered, not before. Embedding dimension, sequence length, and the actual attention score computation each got their own slide. Trying to cram them together produced confusion. Spreading them out took more slides but cut presentation time because people stopped asking clarifying questions mid-flow. Slide 13-18: The decoder, causal masking, and the generation process. This is where most decks lose people. I treated causal masking as a separate concept from the decoder itself. Explained it as "the model is not allowed to see future tokens," showed the masked attention matrix visually, then moved on. The autoregressive generation loop got its own animated diagram. Static images failed here because the process is sequential by nature. Slide 19-22: Scaling up. From the original 2017 paper to what modern LLMs actually use. FlashAttention, KV cache, grouped query attention. These are not optional if your audience works in the field. Skipping them makes the deck feel dated. Adding them without context makes it feel like a feature dump. I kept each to a single slide with a one-line takeaway.
Get the Full Details
Slide 23-25: Limitations. This is the part nobody includes but should. Transformers are computationally expensive. They do not generalize well out of distribution. The attention mechanism can degenerate into near-uniform distributions on noisy inputs. Memory usage scales quadratically with sequence length unless you use approximations. Stating these honestly builds credibility faster than any polished success story.
What I changed after the first few presentations
My first attempt included the full derivation of the scaled dot-product attention formula on a single slide. The formula is: Attention(Q, K, V) = softmax(QK^T / sqrt(d_k))V I put it there because it is technically complete. Nobody read it. Four people in the room asked what d_k was. Two asked what the transpose meant. I lost about four minutes explaining linear algebra basics that had nothing to do with the Transformer. I moved that slide to an appendix and replaced it with a visual showing how the query vectors interact with key vectors as a similarity surface. Same information, zero prerequisites needed. The formula is still there for people who want it, but it no longer blocks the explanation.
Another change: I stopped using the standard "mechanical translation" example. It is from the original paper and everyone has seen it. I swapped it for a code generation example because the room I was presenting to consisted mostly of software engineers. Showing that the same architecture handles both natural language and programming felt more relevant and sparked better questions.

Practical tips that actually matter
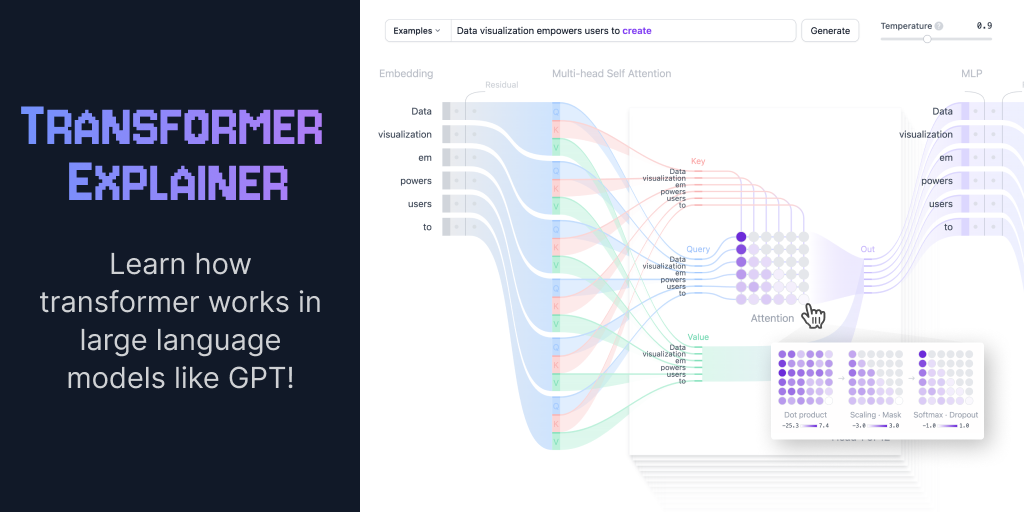
Use Consistent color coding across every slide. I assigned blue to queries, orange to keys, green to values, and kept it that way for the entire deck. When someone is seeing the third attention diagram, they should not have to relearn what each color means. This saved me maybe five minutes of dead air over a 45-minute presentation, but it added up. Include at least one slide showing the actual parameter count progression. From the original Transformer's 65 million parameters to modern models with trillions. A single comparison slide with a horizontal bar chart does more to convey scale than three paragraphs of text. People understand magnitude when they can see it visually. Do not try to cover fine-tuning, RLHF, or prompt engineering in this deck. Those are separate topics. I learned that the hard way when a presenter I watched tried to fit instruction tuning into a Transformer architecture talk. The deck became 40 slides and nobody remembered anything from the first half. Keep the scope tight. If you need to mention downstream applications, do it in one slide at the end and move on.
Where this approach breaks down
If your audience is already familiar with the basics, this deck will feel slow. The first half is deliberately gentle, and advanced practitioners will zone out. In that case, start at the scaling slides and work backward only where gaps appear. I have run this modified version in about 20 minutes for a team that had already read the original paper. It works, but you need to know which slides to skip, and you will only know that by actually running through the full deck once first. Another limitation: this assumes you have access to a projection screen or a well-calibrated monitor. The attention visualizations are detail-heavy and small fonts kill them. Projecting on a dimmed room screen with 14-point minimum text is the threshold. Anything less and the diagrams become unreadable during a live presentation. I found this out when I tried presenting the same deck on a laptop screen in a coffee shop. Half the attention head diagrams were illegible from the back row. Do not skip the venue check.
Where to find the materials
I do not have a single downloadable file to point to. What I ended up with was a collection of custom-built slides, some hand-drawn diagrams I redrew in Figma, and a few Python scripts I used to generate the attention heatmaps from actual model outputs. The heatmap generation took about an hour of setup the first time and runs in under two minutes after that. If you want the actual slides, I can walk you through the structure so you can rebuild them for your own context. The exact tooling matters less than the sequencing decisions I outlined above. A different slide deck with the same logic will serve you better than a pre-made one with a different flow. The most useful single resource I found was the original "Attention Is All You Need" paper itself, specifically Figure 1. Everything else is commentary on that figure. If you understand what that diagram is showing, the rest of the deck is just expanding each component to the size it deserves.