Starting from the equation itself
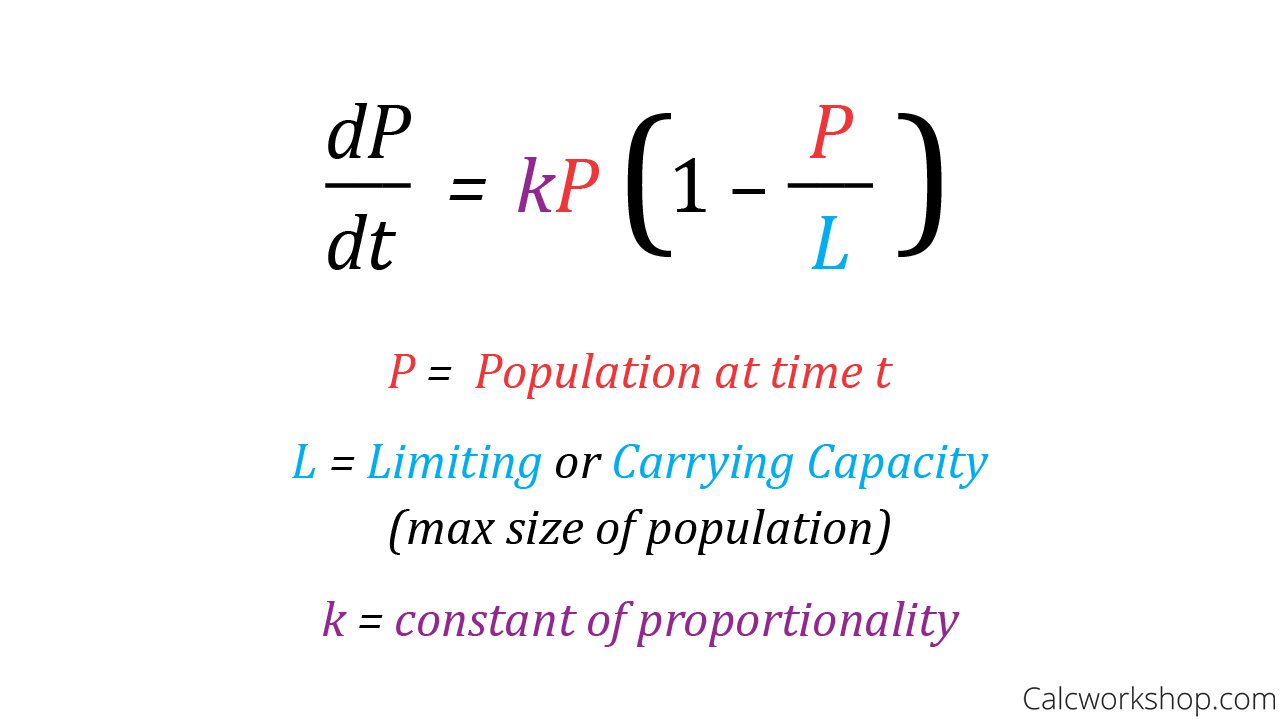
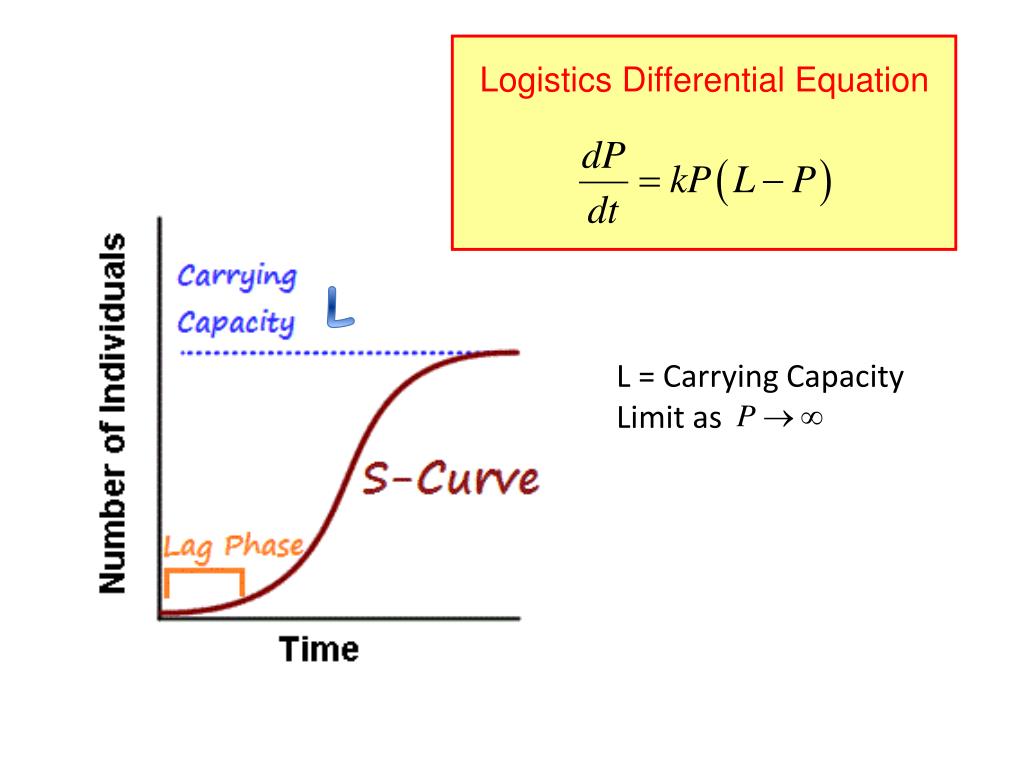
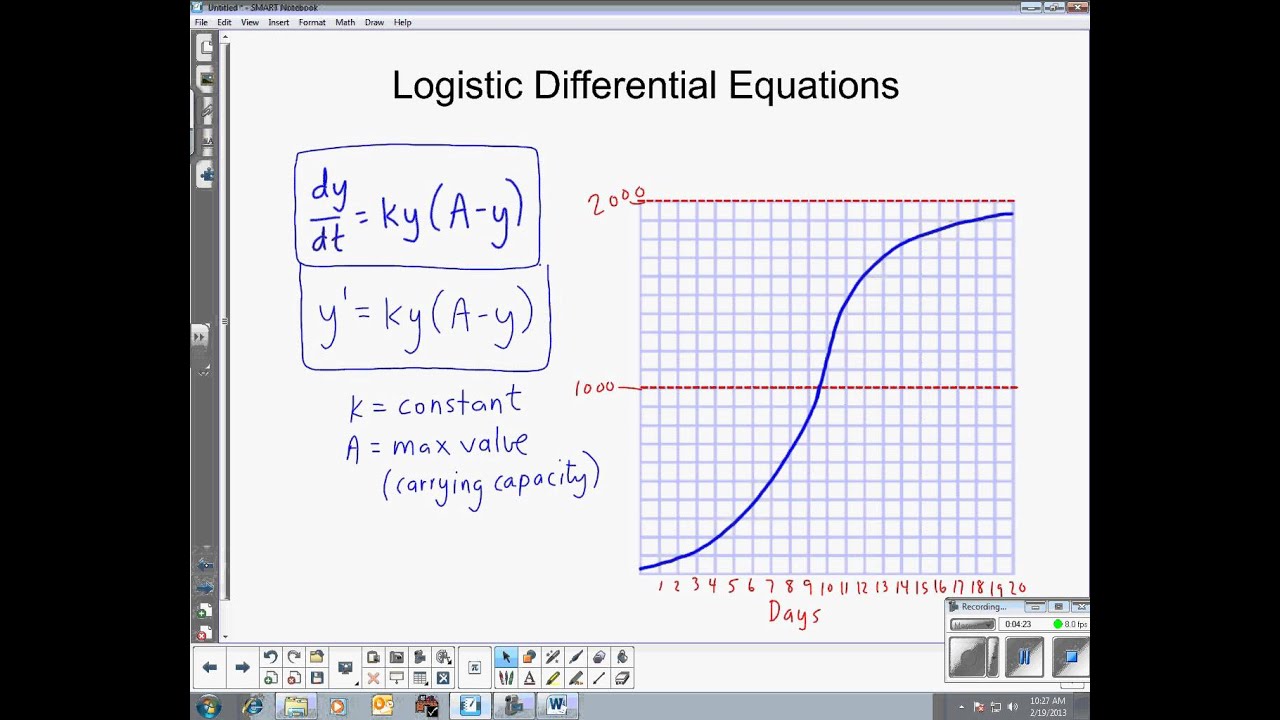
The logistic equation differential equations describe population growth with a carrying capacity constraint. You see it written as dN/dt = rN(1 - N/K), where N is the population, r is the intrinsic growth rate, and K is the carrying capacity. The standard solution is N(t) = K / (1 + Ae^(-rt)), with A determined by your initial condition. That looks straightforward. It is straightforward, until you try to implement it for anything that isn't a textbook problem. Let me walk through what actually happens when you put this into practice.
Setting up the Logistic Equation Differential Equations
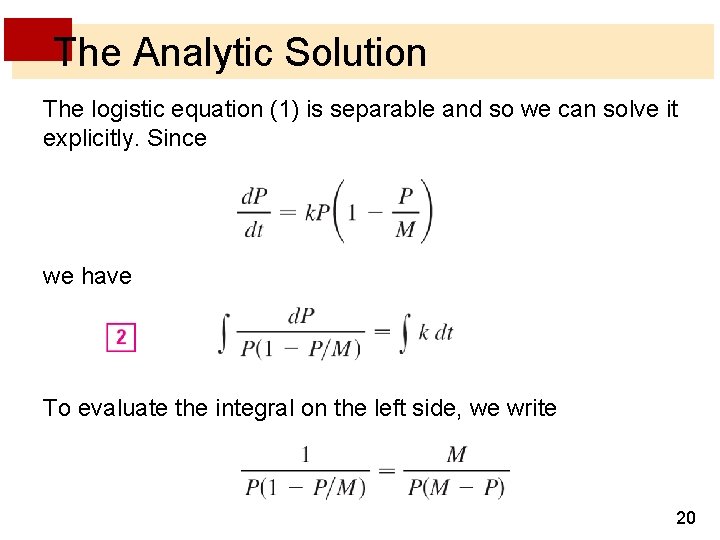
First, you need to define your parameters correctly. The most common mistake people make is initializing the equation with N(0) = 0 or N(0) = K. Both of those are equilibrium points. If you start at N(0) = 0, your derivative is zero everywhere and the solution never moves. If you start at N(0) = K, same thing — the derivative stays zero. You need N(0) strictly between 0 and K for anything interesting to happen. I once spent an afternoon debugging a model that produced flat output, only to discover the initial condition had been set to exactly the carrying capacity due to a rounding error in the input file. Not a typo. An actual float comparison that evaluated to true. Here's something most beginner resources don't mention: the logistic equation can be transformed into a linear ODE using the substitution u = ln(N/(K - N)). When you do that, du/dt = r, which is trivially integrable. The solution for u is just rt + C, and exponentiating back gives you the standard logistic form. This transformation is useful because it reveals the structure of the equation more clearly than the raw nonlinear form does. It also means that if r is time-dependent, say r(t), you can still solve it exactly as long as you can integrate r(t) analytically. The equation becomes du/dt = r(t), and u(t) = u(0) + integral from 0 to t of r(s) ds. Then N(t) = K * exp(u) / (1 + exp(u)). This is genuinely powerful. I've used it to handle seasonal growth models where r varies sinusoidally over the year. You get an exact closed-form solution without any numerical integration, and it's numerically stable across the entire domain. The only catch is that the logarithmic term blows up as N approaches K, so you need to handle the boundary cases carefully in code.
Numerical solutions and where they go wrong
When you can't get an analytical solution — and most real-world variants don't allow it — you need a numerical integrator. The logistic equation is a classic example of a stiff ODE when r is large relative to the timescale of interest. "Stiff" here means the solution has components that decay at very different rates, and explicit methods like Euler or even RK4 require impractically small time steps to stay stable. I ran into this when modeling a bacterial culture with r = 5 per hour and a carrying capacity of 10^9 cells. Using a standard RK4 solver with a fixed step size of 0.01 hours, the solution oscillated wildly around the equilibrium before eventually diverging. Switching to an implicit method — specifically the backward Euler method or a built-in stiff solver like VODE or CVODE — stabilized everything immediately. The computational cost per step went up, but the number of steps dropped by roughly two orders of magnitude, so the net effect was a speedup. For my particular setup, going from explicit RK4 to CVODE cut runtime from about 40 seconds down to under 2 seconds on a standard laptop. Another practical issue: overflow. When N is very small compared to K, the exponential term e^(-rt) in the analytical solution can exceed the floating-point range if rt gets large enough. At r = 1 and t = 750, e^(-750) underflows to zero in double precision, which is fine. But if you're computing N(0) * e^(rt) in the numerator for early-time behavior and rt exceeds about 709, you get overflow. The workaround is to compute everything in log-space or use the transformed variable u = ln(N/(K-N)) throughout your calculation. This avoids both the underflow and overflow problems entirely.
Get the Full Details

A concrete implementation approach
Here's how I typically structure a logistic model implementation. First, define the right-hand side function. In Python with SciPy, that looks like a simple lambda or function that takes N and returns r*N*(1 - N/K). Then choose your integrator based on the regime: Small r, smooth behavior: Use scipy.integrate.solve_ivp with the 'RK45' method. Default tolerances work fine. Set max_step to something reasonable like 0.1 divided by r to avoid missing the inflection point, which occurs at N = K/2. Larger r or sharp transients: Switch to 'BDF' or 'Radau'. These are implicit methods designed for stiff systems. Tighten atol to 1e-10 and rtol to 1e-8 if you need high precision near the equilibrium. For most applications, the default tolerances are adequate and save significant compute time.
Parametric studies: If you're running this for many parameter combinations — say, in a parameter sweep or optimization loop — pre-allocate your output arrays and avoid creating new array objects inside the integration call. This alone can reduce wall-clock time by 30 to 50 percent in Python because the integrator spends less time managing memory and more time computing derivatives.
Common edge case: asymmetric initial conditions near zero
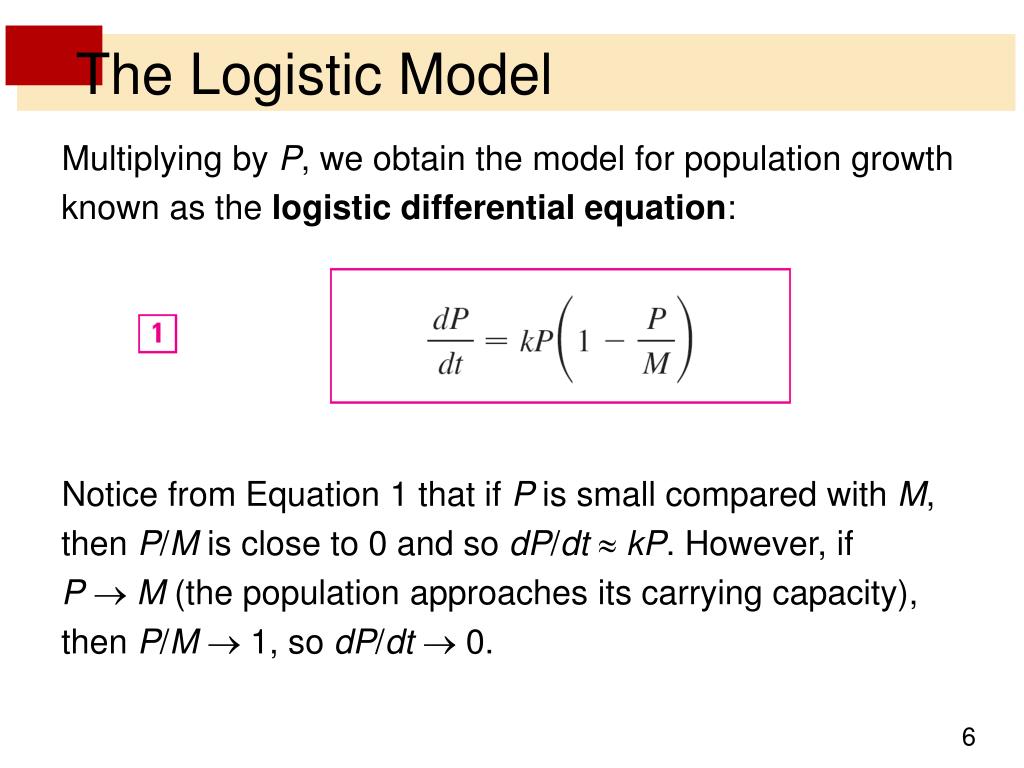
When N(0) is extremely small — say, 10^-6 relative to K — the early dynamics are dominated by exponential growth. The logistic term (1 - N/K) is essentially 1, so the equation behaves like dN/dt rN for a significant period. This means the solution initially grows exponentially and only bends toward the carrying capacity when N becomes a non-negligible fraction of K. Many people miss this and expect the logistic curve to start curving immediately. It doesn't. The inflection point is always at N = K/2, regardless of the initial condition. If N(0) <
K, you'll see a long nearly-exponential phase followed by a relatively sharp transition. This is important for applications like tumor growth modeling or invasive species introduction, where the early phase determines whether a population establishes or dies out due to stochastic extinction. I worked on a project modeling the introduction of an invasive plant species into a new habitat. The initial population was about 0.001 percent of the carrying capacity. A naive simulation with a coarse time step missed the establishment phase entirely and predicted extinction. The issue was that the time step was too large to resolve the slow initial growth before the inflection point. Reducing the max_step by a factor of 100 and using a stiff solver fixed it. The corrected model showed that the species would reach observable levels within 3 to 5 years, not 15 to 20 as the coarse simulation suggested. This difference changed the management recommendation from "monitor quarterly" to "immediate intervention required."
Limitations and when the logistic model fails
The logistic equation is useful, but it's not a universal model. It assumes constant r and K, which is almost never true in nature. Growth rates change with temperature, resource availability, and competition. Carrying capacities shift with environmental conditions. If you're fitting this to real data and the residuals show systematic patterns, the model structure itself is wrong, not just your parameter estimates. For time-varying carrying capacity, you can extend the model to N' = rN(1 - N/K(t)), but this loses the nice analytical properties and requires numerical integration for any nontrivial K(t). For time-varying r, use the logarithmic transformation I described above — it gives you an exact solution if r(t) is integrable. Another failure mode: the logistic equation predicts symmetric growth around the inflection point. Real populations often grow faster on the way up than they decline on the way down, or vice versa. If you need asymmetric dynamics, consider the generalized logistic function (Richards curve) or the Gompertz model. The Richards curve adds a shape parameter that controls asymmetry and reduces to the logistic when the parameter equals 1. It's only one additional parameter and provides significantly better fits for many biological datasets.
Code and resources
For anyone wanting to implement this, the scipy.integrate.solve_ivp function is the standard starting point. Here's a minimal example that handles the key cases I've discussed: import numpy as np
from scipy.integrate import solve_ivp def logistic(t, N, r, K):
return r * N * (1 - N / K)
r = 1.0
K = 1000.0
N0 = 10.0 t_span = (0, 10)
t_eval = np.linspace(0, 10, 500) sol = solve_ivp(logistic, t_span, [N0], args=(r, K), t_eval=t_eval, method='RK45')
N = sol.y[0]
For stiff cases, replace 'RK45' with 'BDF' and add max_step=0.01/r. For the log-transformed approach, solve du/dt = r directly and convert back with N = K*exp(u)/(1+exp(u)). There are no standalone downloads needed for this — it's all standard scientific Python. If you're working in R, the deSolve package handles the same integrators. MATLAB's ode15s is the stiff solver equivalent. All of these are well-documented and have been battle-tested for decades. The key thing to remember is that the logistic equation is a tool, not a truth. It works well for population dynamics with density-dependent regulation and constant parameters. When those assumptions break, the model breaks with them. Know when to switch to a more flexible formulation rather than forcing a square peg into a round hole.