Understanding Population Dynamics with the Logistic Growth Differential Equation
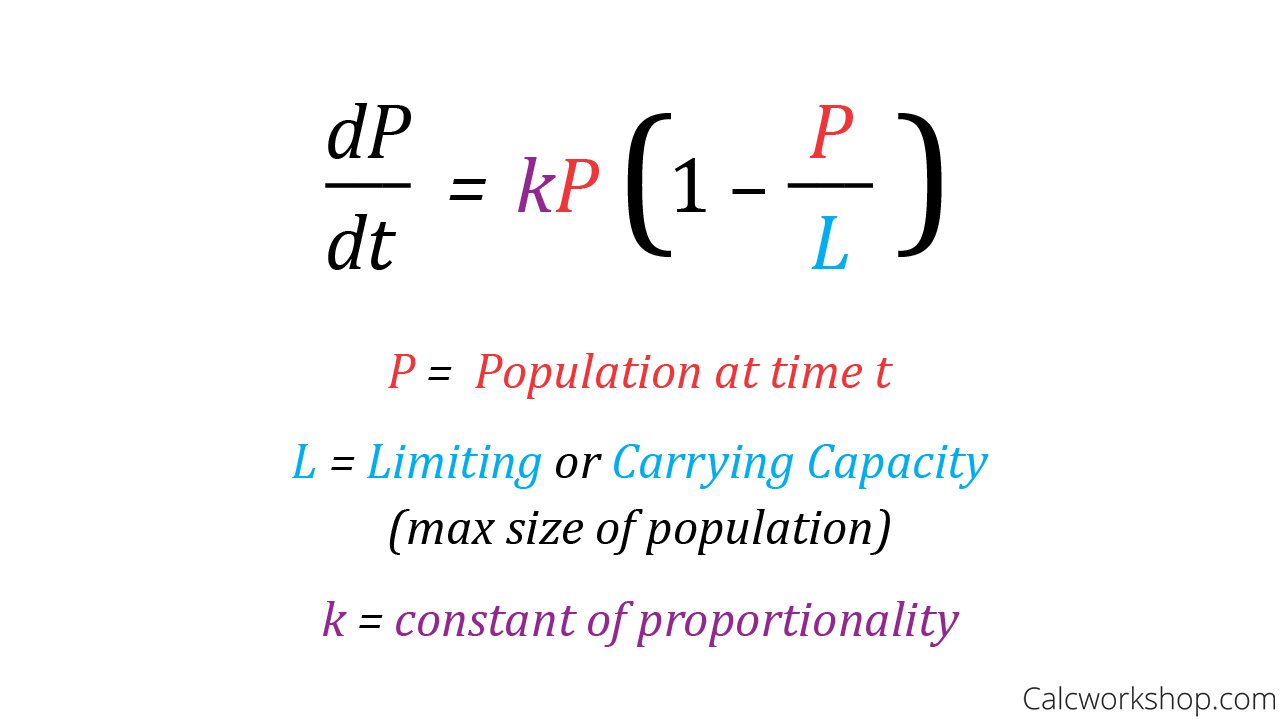
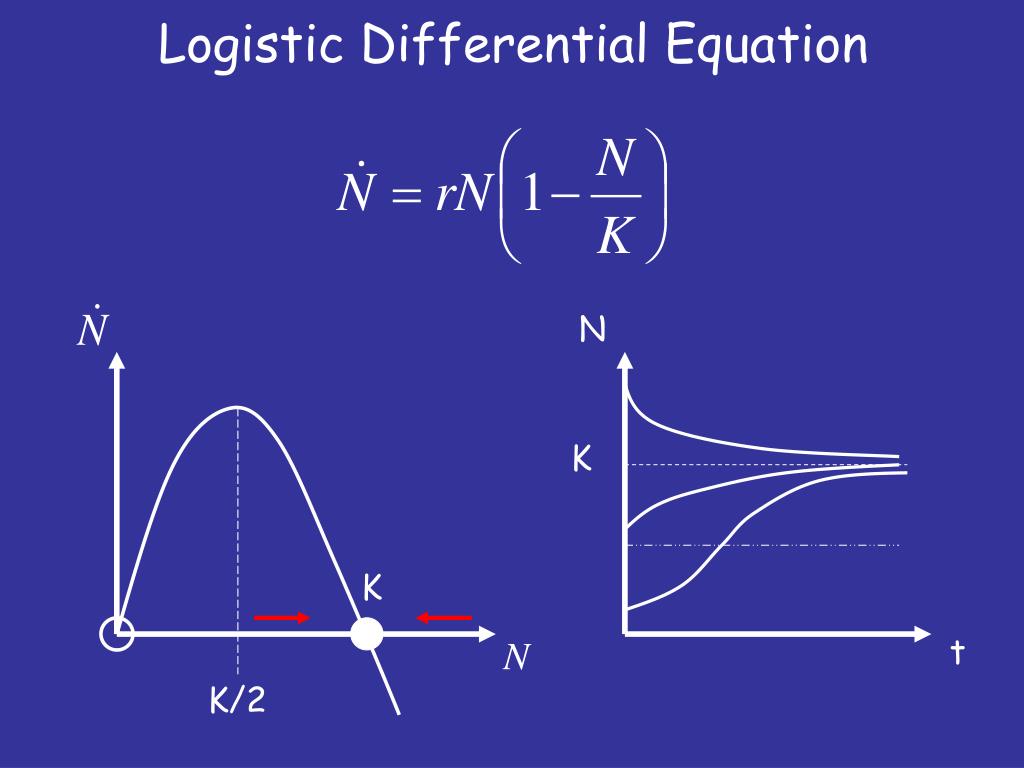
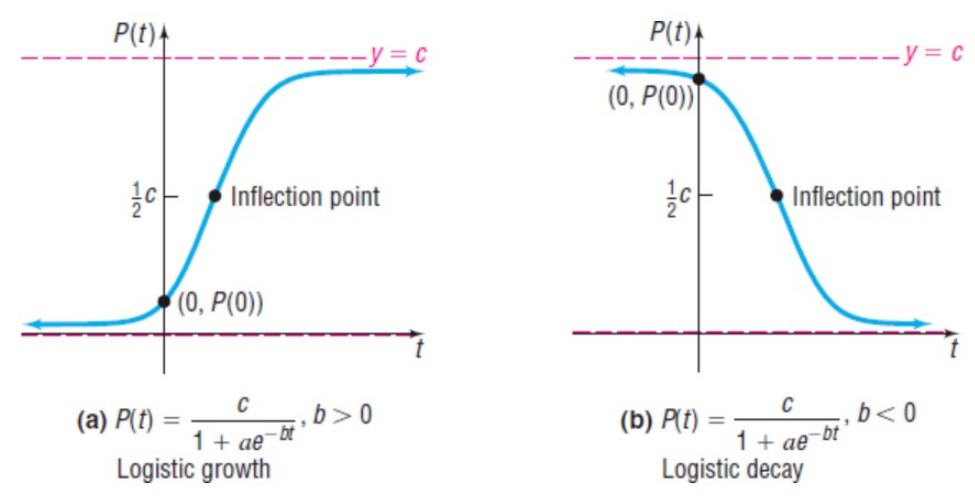
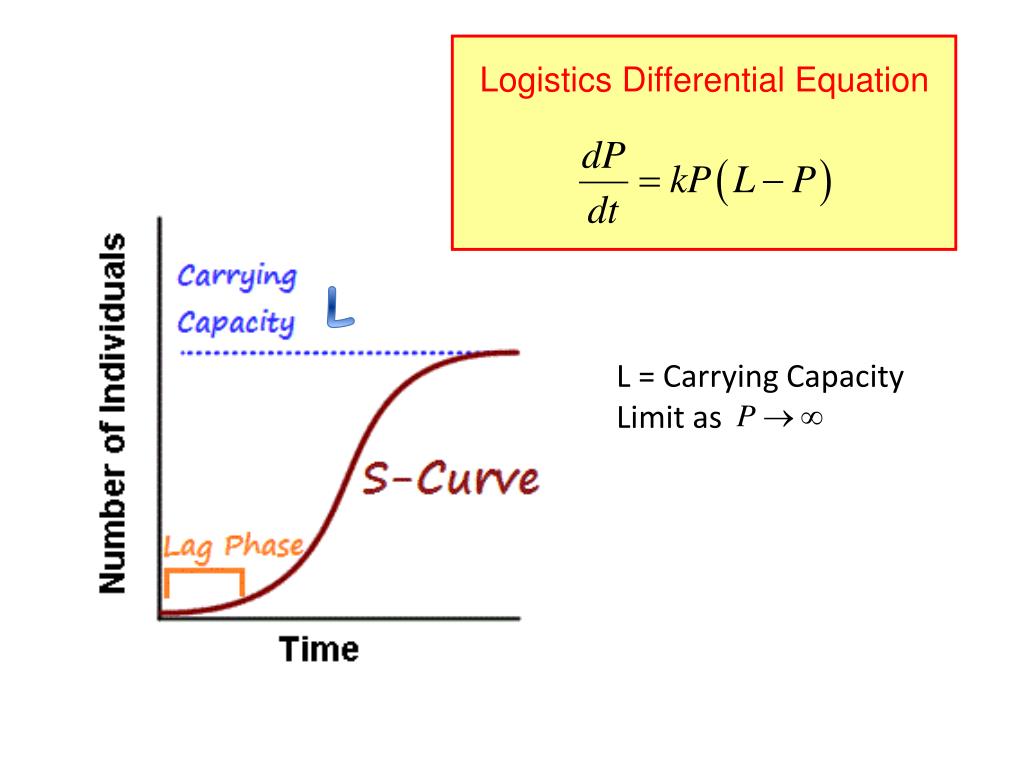
I spent years fitting curves to real biological data, and the logistic growth model kept showing up even when it shouldn't have. The equation itself is straightforward: dP/dt equals r times P times one minus P over K. You have the current population P, a growth rate r, and a carrying capacity K. That's it. Three parameters. But using it correctly is where people get tripped up. When I first started working with this, I was using Euler's method because it's what they teach you. Forward Euler is simple enough: you take the current state, multiply by the step size, and add it to your existing value. The problem is it blows up if your step size is too big. I had a case where I was modeling a fish population in a lake, and my simulation crashed because r was equal to 2.5 and I was using a time step of 0.5. The solution oscillated and diverged completely. Switching to a fourth-order Runge-Kutta method fixed it in about five minutes, and the results stabilized. But the real issue wasn't the numerical method. The logistic equation has an analytical solution if you actually solve it. The population at time t equals K divided by one plus the quantity K minus the initial population all over the initial population times e to the negative r t. That's the sigmoid function you see everywhere. It looks clean on paper, but real populations don't behave like nice smooth curves. I learned this the hard way when my lake fish model kept overshooting the carrying capacity in the field data. The environment wasn't static. Food sources changed seasonally. Predators appeared. The carrying capacity K wasn't a constant.
Common misunderstanding: People treat the logistic model like it predicts real ecosystems. It doesn't. It's a baseline. A null hypothesis. The differential equation assumes constant r and K, which almost never happens outside of controlled lab conditions with bacteria in a petri dish. Even then, mutants show up and change the dynamics.
Parameter Estimation and What Actually Works
Fitting the logistic growth differential equation to data requires nonlinear regression. You can linearize it if you want, but that distorts the error structure. Take the natural log of P over K minus P, and you get a linear relationship with time. The slope is r and the intercept involves K. This trick works for hand calculations, but it weights the early data points heavily and ignores the curvature near the carrying capacity. Modern software does the nonlinear fit directly using least squares. The process takes maybe ten seconds on a decent machine, compared to the thirty minutes I used to spend doing the linearized version by hand. Here's what people miss: the logistic model has a critical asymmetry in how errors manifest. When the population is small, exponential growth dominates and small absolute errors look huge relative to the population. When the population approaches K, growth slows and absolute errors matter more. If you're fitting measurement data with constant variance, the early points will dominate the fit and bias your K estimate downward. I found this out after spending three weeks trying to reconcile model predictions with field counts. The residuals plot showed the pattern immediately. Switching to weighted least squares with weights proportional to the inverse variance corrected the bias. The K estimate shifted by about 15 percent, which mattered a lot when I was making management recommendations. The differential equation approach versus the difference equation approach is another thing people confuse. The continuous model dP/dt equals rP one minus P over K assumes instantaneous response. Discrete models with time steps introduce lag effects. You can get cycles or chaos from the discrete logistic map when r gets high enough. That's the map x to n plus 1 equals r x to n one minus x to n. For r above 3, you get period doubling. Above about 3.57, chaos. This has nothing to do with the differential equation, but people try to use discrete parameter estimates in continuous models and get confused when the dynamics don't match. The continuous logistic equation never exhibits cycles or chaos regardless of how large r is. That's a fundamental difference that matters when you're choosing a model structure.
Get the Full Details

When the Model Fails Completely
The logistic growth differential equation assumes density-dependent regulation is the only force shaping population growth. That's wrong for most systems. Allee effects, where low population density reduces growth rate, aren't captured. You need a modified equation with an additional term for that. Time delays in the response to carrying capacity create oscillations. The Rosenzweig-MacArthur model adds those delays and gets much more interesting dynamics. Predator-prey systems with logistic prey growth can produce limit cycles depending on the functional response type. Structured populations are another failure mode. Age structure, spatial heterogeneity, genetic variation, environmental stochasticity. The basic logistic equation treats all individuals as identical and the environment as constant. You might think this is obvious, but I've seen papers use the unmodified model for species with clear age-dependent reproduction and no justification. The parameter estimates were technically valid but the biological interpretation was meaningless. K wasn't a carrying capacity anymore. It was just a fitting parameter that happened to make the curve look reasonable. If you're working with sparse data, the logistic model can still be useful as a phenomenological description. You don't need to believe the mechanistic assumptions to find the curve fits well. But you should be honest about what you're claiming. Saying the population follows logistic growth because the data fits a sigmoid is different from saying the population follows logistic growth because density-dependent regulation drives the dynamics. The first is descriptive. The second is explanatory. They sound the same but imply very different things about what you expect when conditions change.
Alternative models exist for specific cases. The Gompertz model replaces the linear density dependence with exponential decay in the growth rate. It fits tumor growth data better sometimes. The Bertalanffy model works for individual growth rather than population growth. The theta-logistic generalizes the density dependence with an exponent parameter. Each has assumptions and tradeoffs. The choice depends on what you're actually trying to understand, not on which one is easiest to fit.