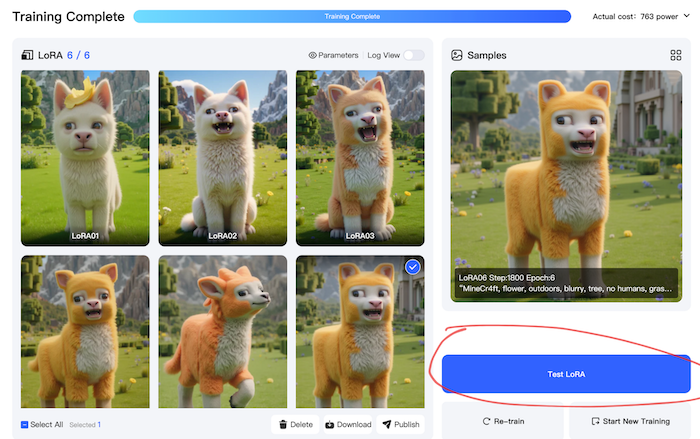
Training LoRAs is mostly waiting and debugging
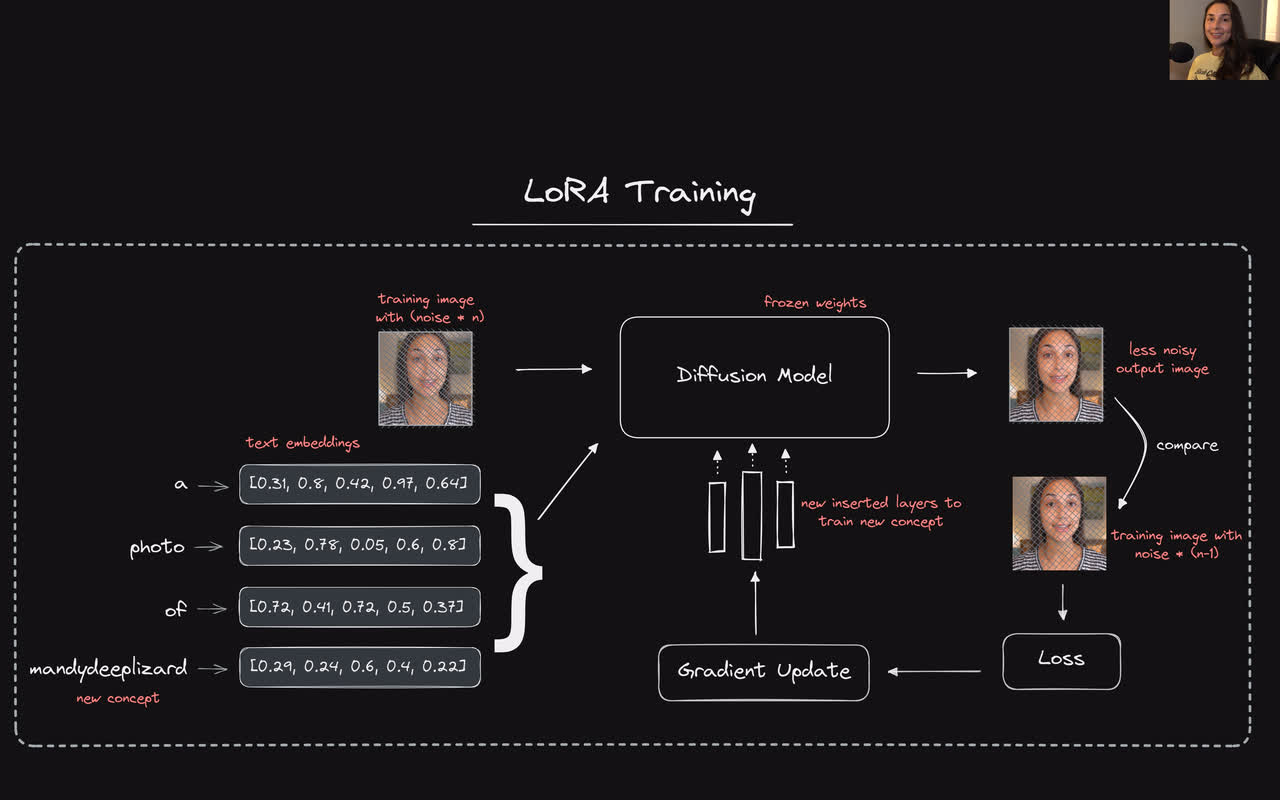
I spent three weeks last year trying to get a consistent character LoRA trained. The results ranged from garbage to passable depending on which seed I used, and I eventually figured out the problem wasn't the network architecture or the dataset size. It was the regularization images and the learning rate schedule. Now when I train a LoRA, the whole thing takes about 45 minutes on a single 4090, and I know exactly what knobs matter. The core idea behind Lora Training Stable Diffusion is straightforward enough. You freeze the pretrained diffusion model weights and insert tiny trainable adapter modules into the attention layers. These adapters are usually rank-4 or rank-16 matrices that learn only the difference between your target concept and whatever the base model already knows. The original weights stay untouched. After training, you get a small file, typically between 50 and 150 megabytes, that plugs into any pipeline that supports the format.
Getting Lora Training Stable Diffusion to actually work for you
First, you need images. Not hundreds of them, not thousands either. For a character concept, I usually shoot or collect between 15 and 30 images. They should show the subject from different angles, under different lighting, in different poses, but doing relatively ordinary things. The worst mistake I see people make is using images that are too similar to each other. If all your training images look like front-facing portraits on a white background, the LoRA will bake that exact composition into its weights and you will get nothing but stiff front-facing outputs forever. Cap the images at 1024x1024 resolution. Anything larger slows things down without improving quality because the base model itself was trained at 512 or 1024. Cropping to square is fine. I use a simple script that resizes and batches everything, which takes about three minutes for a 25-image dataset. For captioning, use something likeWD-14 Tagger or BLIP, but do not trust it blindly. I had a project once where the auto-captions labeled every image with "blurry" and "low quality" because the source photos had slight motion blur, and the LoRA spent the first half of training trying to reproduce bad image quality. I spent an hour manually correcting the captions and that fixed the problem entirely. You can automate this with a cleanup script that strips common unwanted tags, but manual review of the first 20 captions will save you days of debugging later.
The trainer I use is Kohya_ss. The config that consistently works for me looks like this: network rank set to 32, alpha set to 16, learning rate of 1e-4 for the UNet and 5e-5 for the text encoder. I run about 1000 to 2000 epochs depending on dataset diversity. That is a lot of epochs, but with mixed precision on a 4090 and a well-sized batch, each epoch finishes in roughly 15 seconds, so the whole run completes in under an hour. VAE tiling enabled, gradient accumulation set to 4, and mixed precision AMP turned on. Here is the thing nobody mentions enough. The text encoder training is where most people fail, not the UNet. If you want your LoRA to respond correctly to a specific prompt phrase, you need to train the text encoder alongside the UNet. A common configuration is to set text encoder learning rate to 5e-5 and UNet to 1e-4. The UNet learns the visual concept faster, and if you stop training too early, the text encoder has not learned to associate the trigger word with the actual visual features. I usually let both run for the full epoch count rather than stopping the UNet early. For the base model, SDXL works better than SD1.5 for most use cases in 2025 and beyond, but it requires more VRAM and roughly doubles training time. If you are working with character LoRAs and have 24GB of VRAM, train on SDXL. If you are on 12GB, stick with SD1.5 and accept that you will hit a ceiling on detail and composition quality. There is no workaround for that hardware constraint.
Get the Full Details
I ran into a particularly nasty issue last year where my LoRA was overfitting badly but validation samples looked fine at every checkpoint. The problem was that I was generating validation images using the same seed every time, and the seed happened to align well with the overfitted directions. I switched to generating five validation samples per checkpoint with random seeds, and the overfitting became immediately obvious at epoch 600 instead of epoch 1500 where I would have caught it otherwise. Checkpoint saving every 200 epochs with validation overrides saved me from wasting the last nine hundred epochs of training. Saving intermediate checkpoints is essential. I save every 200 steps and also enable the early stopping callback based on validation loss. When the validation loss starts climbing while training loss continues to drop, you are overfitting and should stop. In practice, this happens around epoch 800 to 1200 for a well-prepared dataset of 20 to 30 images. The output file format matters. Stick with the .safetensors format. It is safer, loads faster, and is compatible with everything from ComfyUI to Automatic1111 to Forge. Do not bother with the older .ckpt format unless you have a legacy pipeline that cannot handle safetensors.
One counter-intuitive detail about LoRA Training Stable Diffusion that most guides skip. The alpha value does not control overfitting the way people think. Alpha mainly scales the effective learning rate of the adapter. Setting alpha equal to rank gives you a direct 1:1 scaling. Setting alpha lower, like rank divided by two, dampens the effect and lets you push the training longer without blowing up the output. I often set rank to 64 and alpha to 32 for complex concepts that need deep training, which effectively halves the impact of each update and lets me train for more epochs with stable results. Regularization images are another thing that gets misunderstood. You do not need hundreds of them. For a specific character, you might use 20 generic human images as regularization to prevent the model from forgetting how to render other people. For a clothing style or artistic technique, zero regularization images often works better because the base model already knows those general categories and regularization just adds noise. I learned this the hard way when a fashion LoRA I trained started producing muddy, generic clothes after I added a regularization set. Removing the regularization images and retraining for 400 fewer epochs gave me much sharper results. If you want to test a LoRA before committing to a full train, run a 100-epoch trial first. It takes about six minutes on a 4090 and tells you immediately whether your dataset or captioning approach is sound. If the 100-epoch trial produces nothing recognizable, no amount of additional training will fix it. The issue is in the data, not the training duration.
The main limitation of this approach is that LoRAs are tied to their base model. A LoRA trained on SD1.5 will not load into an SDXL pipeline without conversion, and the conversion is lossy. A LoRA trained on one checkpoint variant, like Realistic Vision, will not transfer cleanly to a different variant, like DreamShaper. Always train on the exact base model you plan to use for inference. I once spent two days debugging poor LoRA quality before realizing the model I was generating with was a completely different checkpoint than what I trained on. Another limitation is that LoRAs struggle with complex multi-subject compositions. If you train on images with multiple characters or objects, the LoRA tends to bleed concepts together. I had a portrait LoRA that kept inserting the subject into landscapes and pairing it with random background elements because my dataset had a 40 percent mix of portrait and environmental shots. Splitting the dataset into pure portrait and pure environmental subsets and training separate LoRAs fixed the issue. For download sources, CivitAI remains the largest repository and the quality there varies enormously. Check the metadata section on each model page to see what base model and rank it was trained with. Models without metadata are usually amateur uploads and tend to be lower quality. Hugging Face has better curated collections but a smaller volume. I prefer CivitAI for finding inspiration on training approaches and Hugging Face for downloading specific base models I need.
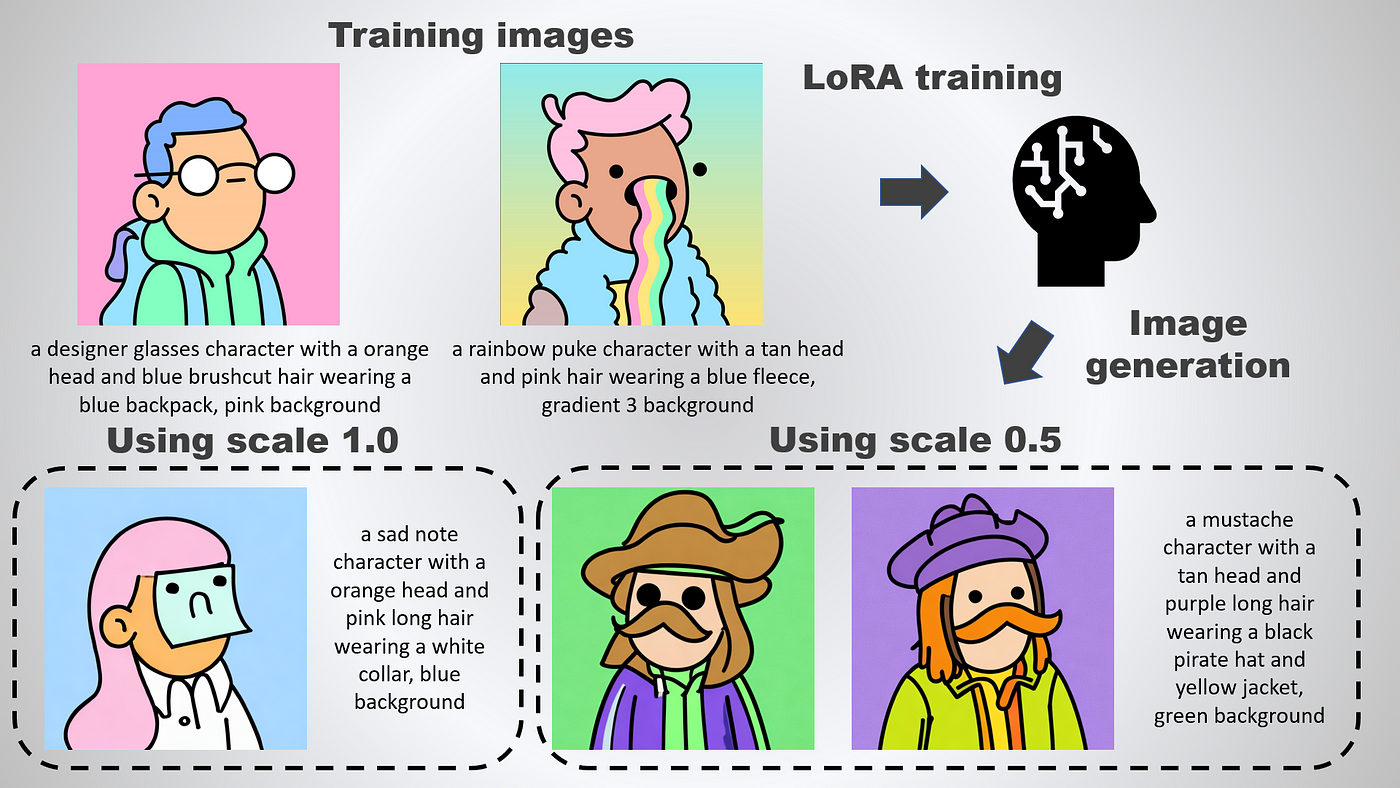
The practical workflow I use now is nearly automated. I drop new images into a folder, run the captioning script with manual review, feed everything into Kohya_ss with a saved config template, and walk away for an hour. The validation callbacks catch overfitting automatically. I pull the best checkpoint, convert it to safetensors, and test it with a handful of prompts that use the trigger word in different contexts. If the trigger word does not produce consistent results across five different prompt structures, I go back and adjust the text encoder learning rate or add more diverse training images. Most failures come down to insufficient prompt diversity in the training data, not insufficient training time.