Why Your Loss Numbers Keep Lying to You
I've spent twelve years watching teams run root cause analysis after root cause analysis and still end up with the same gap between theoretical throughput and actual output. The problem is rarely the methodology itself. More often it's the way people treat loss data as a report card instead of a map. Here's the thing most people skip: before you do anything else, verify your baseline. I once sat through a three-week investigation into a packaging line that showed a 14% efficiency drop every Thursday afternoon. We found a broken bearing, replaced it, and the line was fine for two days. Then it happened again. Turns out the bearing was a red herring. The real issue was a temperature-sensitive adhesive that softened at a specific time of day when the HVAC cycled on. I ended up tracking ambient conditions against downtime logs for a month before the pattern surfaced. If you don't log environmental variables and shift-level context from the start, you're guessing with extra steps. Start with OEE, not somewhere in the middle. Overall Equipment Effectiveness breaks into Availability, Performance, and Quality. Most teams jump straight into performance speed losses or quality rejects without establishing whether the equipment was actually running for the planned production window. That's backwards. A machine that's down twenty percent of the shift because of micro-stops will look like a performance problem even though the root cause is maintenance-related. Map the downtime categories first. Categorize every stop as planned or unplanned, then further split unplanned into component failure, changeover, material supply, operator error, or environmental. This categorization step alone cuts diagnosis time roughly in half compared to teams that start asking "why" without a structured category to hang the answer on.
Don't aggregate losses too early. I see a lot of reports that lump thirty minutes of unplanned downtime into a single bucket labeled "other." That bucket becomes a graveyard for real problems. Every unclassifiable loss is a sign you either missed a data field or the event doesn't belong in the same analysis. Create new buckets until they stop spawning. It usually means around six to eight categories before you find the right granularity. Going beyond that just adds reporting noise. Here's a counter-intuitive point: sometimes the biggest losses aren't the ones making the biggest single contribution. There's a phenomenon I call loss multiplication, where multiple small losses compound in ways the data doesn't show unless you track them sequentially. A line that runs five percent slow for forty minutes, then stops for seven minutes, then drops another three percent quality yield, might look acceptable in isolation but actually costs more than a single thirty-minute failure event. Track sequences, not just totals. Pull event logs in chronological order and look for clusters. Clusters are where the money hides. Another thing people consistently get wrong is assuming losses are independent. They aren't. A changeover delay causes a rushed startup, which causes a quality spike, which causes rework downtime. If you analyze each loss type separately, you'll propose fixes that only address one link in the chain. Build causal chains before proposing interventions. Even a simple arrow diagram from your logs can reveal that three separate loss categories share one upstream trigger. Fixing that trigger eliminates all three.
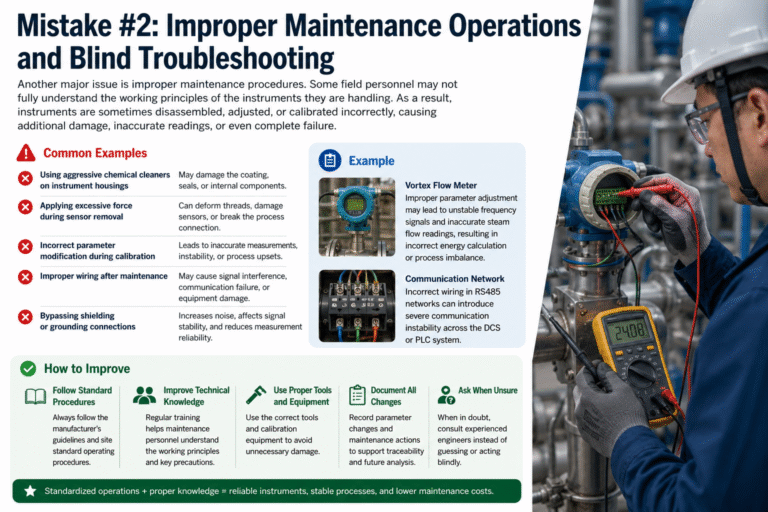
I want to be blunt about where this approach breaks down. Loss troubleshooting using OEE and event logging works well for discrete manufacturing and continuous processes with clean instrumentation. It falls apart quickly in batch processes where changeovers dominate and cycle times are unpredictable, or in environments where manual data entry is the primary source. In those cases, the noise in the input data swamps any signal you're trying to extract. I've worked in facilities that tried to force OEE-style tracking onto hand-written shift logs and ended up with worse decisions than if they'd just skipped the framework entirely. If your data isn't instrumented to at least the component level, consider starting with simple time studies before investing in an MES or SCADA integration. There's also a human factor that doesn't show up in any methodology. Operators know why the line stops more often than the data reflects. I've found that spending ten minutes at the start of an investigation asking the team on the floor to describe the last three downtime events before looking at any logs will surface at least one cause the instruments missed. Sensors don't always record what humans see as obvious. A misaligned guide rail that causes intermittent jams, a operator workaround that bypasses a safety interlock causing unexpected stops, a material batch variation that the system doesn't flag. Treat the data and the people as complementary sources, not competing ones. When they disagree, the disagreement is usually the most useful data point in the entire analysis. The practical workflow I use, and recommend, looks like this:
Get the Full Details

First, define the scope. Pick one line, one shift, one product family. Narrow scope reduces noise and makes patterns visible. Broad investigations produce broad conclusions that solve nothing. Second, confirm your instrumentation. Check that every sensor and counter is actually recording. I've walked into facilities where the "performance" channel was logging zero values for an entire month because of a broken encoder. You won't know unless you verify against a physical stop clock for at least one shift. Third, classify every loss event. Use the categories I mentioned earlier. This takes time but it's the single highest-return step. Teams that skip classification spend weeks going in circles.
Fourth, build causal chains. Connect events that follow each other within a tight window. Look for repeated sequences, not one-off correlations. Fifth, prioritize by impact and fixability. Not all losses are worth pursuing equally. A loss that accounts for eight percent of downtime but requires a capital expenditure to address is often a lower priority than a five percent loss you can fix with a procedural change this week. Sixth, implement, measure, repeat. Every fix changes the loss profile. New dominant losses will surface. The process isn't linear. It's a loop.
One last note on tools. Spreadsheet-based analysis works fine for the first few months of this work. You don't need specialized software to start. Once you're doing this regularly across multiple lines, a proper manufacturing execution system pays for itself within six to eight months through reduced diagnosis time and more accurate root cause identification. Until then, keep it simple and document everything you learn about your specific process. That institutional knowledge is worth more than any tool you'll ever buy.