Understanding Loss Functions in Machine Learning
When you start training any model, the first thing you need to figure out is how it will measure its mistakes. That measurement is called the loss function, and getting it wrong is one of the most common reasons beginners' models simply refuse to learn anything useful. I spent about three weeks debugging a classifier last year that kept outputting the same class for every single input. The dataset was fine, the architecture was fine, but I had been using mean squared error on a multi-class classification problem. The gradients were essentially flatlining, so the model never updated its weights meaningfully. Once I switched to categorical cross-entropy, it learned in two epochs. That's the kind of thing nobody warns you about until it happens to you. A loss function takes your model's predictions and the true labels as inputs and outputs a single number representing how far off the predictions are from reality. That number gets minimized during training through backpropagation and an optimizer. That's the entire loop. Everything else is just selecting the right function for your problem type. The most basic category is regression loss, where the target is a continuous value. Mean Squared Error, or MSE, is the default here. You subtract the predicted value from the actual value, square it, and average across all samples. Squaring the differences means larger errors get penalized disproportionately, which is usually what you want. A model that's off by 10 gets penalized 100 times more than a model off by 1, which forces it to focus on the worst predictions. The downside is that MSE is extremely sensitive to outliers. One bad data point can dominate the loss landscape and pull your weights in an unproductive direction. If your dataset has even a modest number of outliers, Mean Absolute Error, or MAE, is a safer default. It doesn't exaggerate large errors, though it can be slower to converge because the gradient is constant rather than growing with the error magnitude.
Loss Ultimate Guide For Beginners
For classification problems, the standard is cross-entropy loss, sometimes called log loss. There are two variants you need to know about. Binary cross-entropy is for yes-or-no problems where the output is a single probability between 0 and 1. Categorical cross-entropy is for multi-class problems where each sample belongs to exactly one of many classes. Sparse categorical cross-entropy is the same thing, but it accepts integer labels instead of one-hot encoded vectors, which saves you a preprocessing step and is what you'll use in practice 99% of the time. The mathematical form looks like this: L = -sum(y_true * log(y_pred)). When the model is confident and correct, y_pred is close to 1 and the log term approaches 0, so the loss is near zero. When the model is confident and wrong, y_pred approaches 0 and log(y_pred) approaches negative infinity, so the loss explodes. That explosion is actually helpful. It gives the optimizer a very strong signal to adjust the weights aggressively when the model is badly wrong. Hinge loss is another option you'll encounter, mostly in support vector machines but occasionally in neural networks for binary classification. It doesn't use probabilities, it uses raw scores. The loss is max(0, 1 - y_true * prediction). This pushes correctly classified samples to have a margin of at least 1, and anything within that margin gets penalized. It tends to produce sparser solutions, meaning fewer features end up with non-zero weights, which can be useful for interpretability. But it's less commonly used with deep learning because it doesn't produce a well-calibrated probability distribution.
When Standard Loss Functions Break Down
Most beginner tutorials stop at MSE and cross-entropy, but real datasets don't always cooperate. Here are a few situations where you'll need something more specific. Focal loss was originally designed for object detection, specifically to address class imbalance at the level of individual examples rather than whole categories. In datasets where 95% of samples belong to one class, cross-entropy will still train mostly on the majority class because the absolute number of correct predictions from that class dominates the loss. Focal loss adds a modulation factor that reduces the contribution of easy examples, forcing the model to focus on hard-to-classify samples. The formula is FL = -(1 - p_t)^gamma * log(p_t), where gamma is a focusing parameter you tune. I used focal loss on a fraud detection problem where positive cases were about 0.3% of the data. Switching from categorical cross-entropy to focal loss with gamma set to 2 increased our recall on the minority class from about 41% to 78%, which was the difference between the model being useless and being deployable. Contrastive loss is used when you're not classifying discrete categories but learning similarity relationships. Face recognition systems, recommendation engines, and embedding models all use variations of this. The idea is simple: pull similar pairs closer together in representation space and push dissimilar pairs apart. The loss is typically d + lambda * max(0, margin - d), where d is the distance between two embeddings. This is fundamentally different from classification loss because there are no fixed categories during training. You're optimizing relative distances, not absolute labels.
Get the Full Details

Troubleshooting Loss Behavior
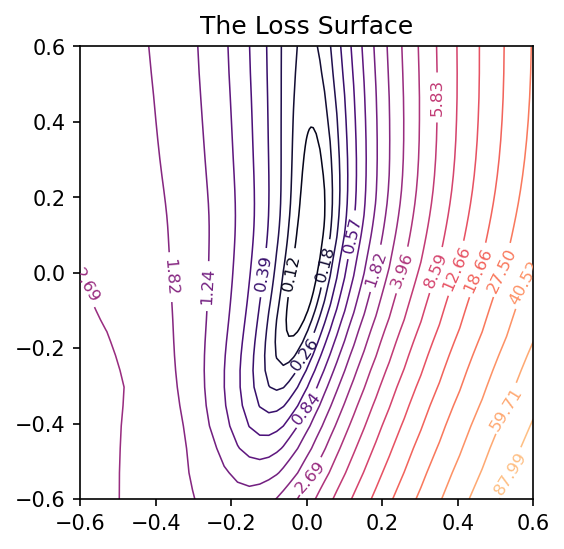
Watching your loss curve during training is the primary diagnostic tool, but the curve itself can be misleading if you don't know what you're looking at. Here are the patterns I see most often and what they actually mean. If your loss starts high and drops quickly, then plateaus at a suboptimal value, your learning rate is probably too high. The optimizer is bouncing around the loss landscape instead of settling into a minimum. Lower it by an order of magnitude and watch the curve smooth out. Conversely, if the loss decreases extremely slowly over many epochs, your learning rate might be too low. You're making tiny updates that barely move the weights. A loss curve that fluctuates wildly between epochs usually indicates a batch size that's too small. With fewer samples per batch, the gradient estimate has higher variance. Bumping your batch size from 16 to 64 typically stabilizes things noticeably, though you'll use more memory. If you're memory-constrained, a learning rate warmup schedule can help more than increasing batch size. Ramp the learning rate up linearly over the first few thousand steps before settling into the main value. This prevents the optimizer from taking huge steps in a poorly conditioned region of the loss landscape early in training.
NaN loss is the most alarming thing you can encounter. Your model outputs become undefined and everything after that point is garbage. This almost always comes down to numerical overflow, which happens when activations or weights grow without bound. The fix is usually one of: adding gradient clipping to cap the maximum gradient norm, reducing the learning rate, adding batch normalization or layer normalization to stabilize activations, or checking for invalid data like infinite or missing values that could trigger NaN propagation through the network. I had a case once where a singleNaN in the input data propagated through the entire first forward pass, and since I wasn't checking my tensors for validity, the model trained on garbage for about 200 epochs before I noticed the loss was NaN. Setting a simple NaN check on the loss at the end of each epoch would have caught that in the first minute.
Custom Loss Functions
Sometimes no built-in loss function fits your problem, and you need to write your own. In TensorFlow and Keras, this is straightforward. You define a Python function that takes y_true and y_pred as tensors and returns a tensor of loss values. The function gets differentiated automatically by the framework's autograd system, so you don't need to compute gradients by hand. The most common reason to write a custom loss is combining multiple objectives into a single training signal. Say you're predicting both a price and a category for a product. You could compute cross-entropy loss for the category and MSE for the price, then add them together with a weighting factor. The key insight is that the two losses will be on different scales. MSE might be in the hundreds while cross-entropy is around 0.5. Without normalization or careful weighting, the larger loss dominates and the optimizer ignores the smaller one entirely. I learned this the hard way on a pricing model where the category loss was consistently being overshadowed. Normalizing both losses to roughly the same scale before summing them fixed the problem immediately. Another legitimate use case is encoding domain knowledge directly into the loss. If you know that misclassifying class A as class B is twice as costly as misclassifying it as class C, you can build an asymmetric loss matrix that penalizes certain errors more heavily. This is common in medical diagnosis and quality control applications where the cost structure is inherently imbalanced. Framework-agnostic implementations are possible too, since the principle is the same regardless of whether you're using PyTorch, TensorFlow, or JAX.

Practical Recommendations
Start with the default loss for your problem type. Binary cross-entropy for binary classification, categorical cross-entropy for multi-class, MSE for regression. Don't experiment with exotic losses until you've established a baseline and confirmed that the standard approach isn't sufficient. Most problems don't need anything beyond the defaults. Always monitor both the training loss and the validation loss. If they diverge significantly, with training loss continuing to decrease while validation loss starts increasing, you're overfitting. This is normal past a certain point. The mitigation strategies are the usual ones: more data, regularization, dropout, early stopping. But note that early stopping based on validation loss is itself a form of loss function management, just at a meta level. If your problem involves severely imbalanced classes, try class weights before reaching for focal loss. Most frameworks support passing a class_weight dictionary to the fit method. This is simpler to implement and debug, and it works well for moderate imbalance. Focal loss is worth the extra complexity when class weights aren't enough, typically when the minority class represents less than 1% of the data.
For sequence-to-sequence and transformer models, label smoothing is a useful technique that acts as a regularizer. Instead of training the model to predict probability 1 for the correct class, you train it to predict something like 0.9, distributing the remaining 0.1 across the other classes. This prevents the model from becoming overconfident and improves generalization, especially on noisy datasets where labels might be incorrect. It's a one-line change in most frameworks and rarely hurts performance. One thing that trips up people constantly is confusing the loss function with the metric. Loss is what the optimizer minimizes. Metrics are what you use to evaluate performance. They don't have to be the same thing, and often shouldn't be. Accuracy is a metric, not a loss function, because it's not differentiable. You can't backpropagate through an accuracy calculation. Cross-entropy is differentiable, which is why it works as a loss. Never try to use accuracy as your training loss and wonder why your model doesn't learn.