Building Lstm For Sentiment Analysis Without Losing Your Mind
I spent about three weeks debugging a sentiment model that kept scoring sarcastic reviews as positive. The words were literally all favorable. "This product is amazing, just like watching paint dry is thrilling." The LSTM parsed every token correctly, assigned high confidence to "amazing" and "thrilling," and produced a result that was confidently wrong. That's not a bug in your code. That's the architecture itself struggling with context windows and pragmatic language. Lstm For Sentiment Analysis remains one of the more accessible entry points into sequence modeling for NLP. It predates transformers but still runs fast enough on modest hardware and is straightforward to implement from scratch if you understand the gating mechanics. Before you copy a tutorial and wonder why your validation loss plateaus at 0.5, here's what actually matters in practice.
What You're Actually Building
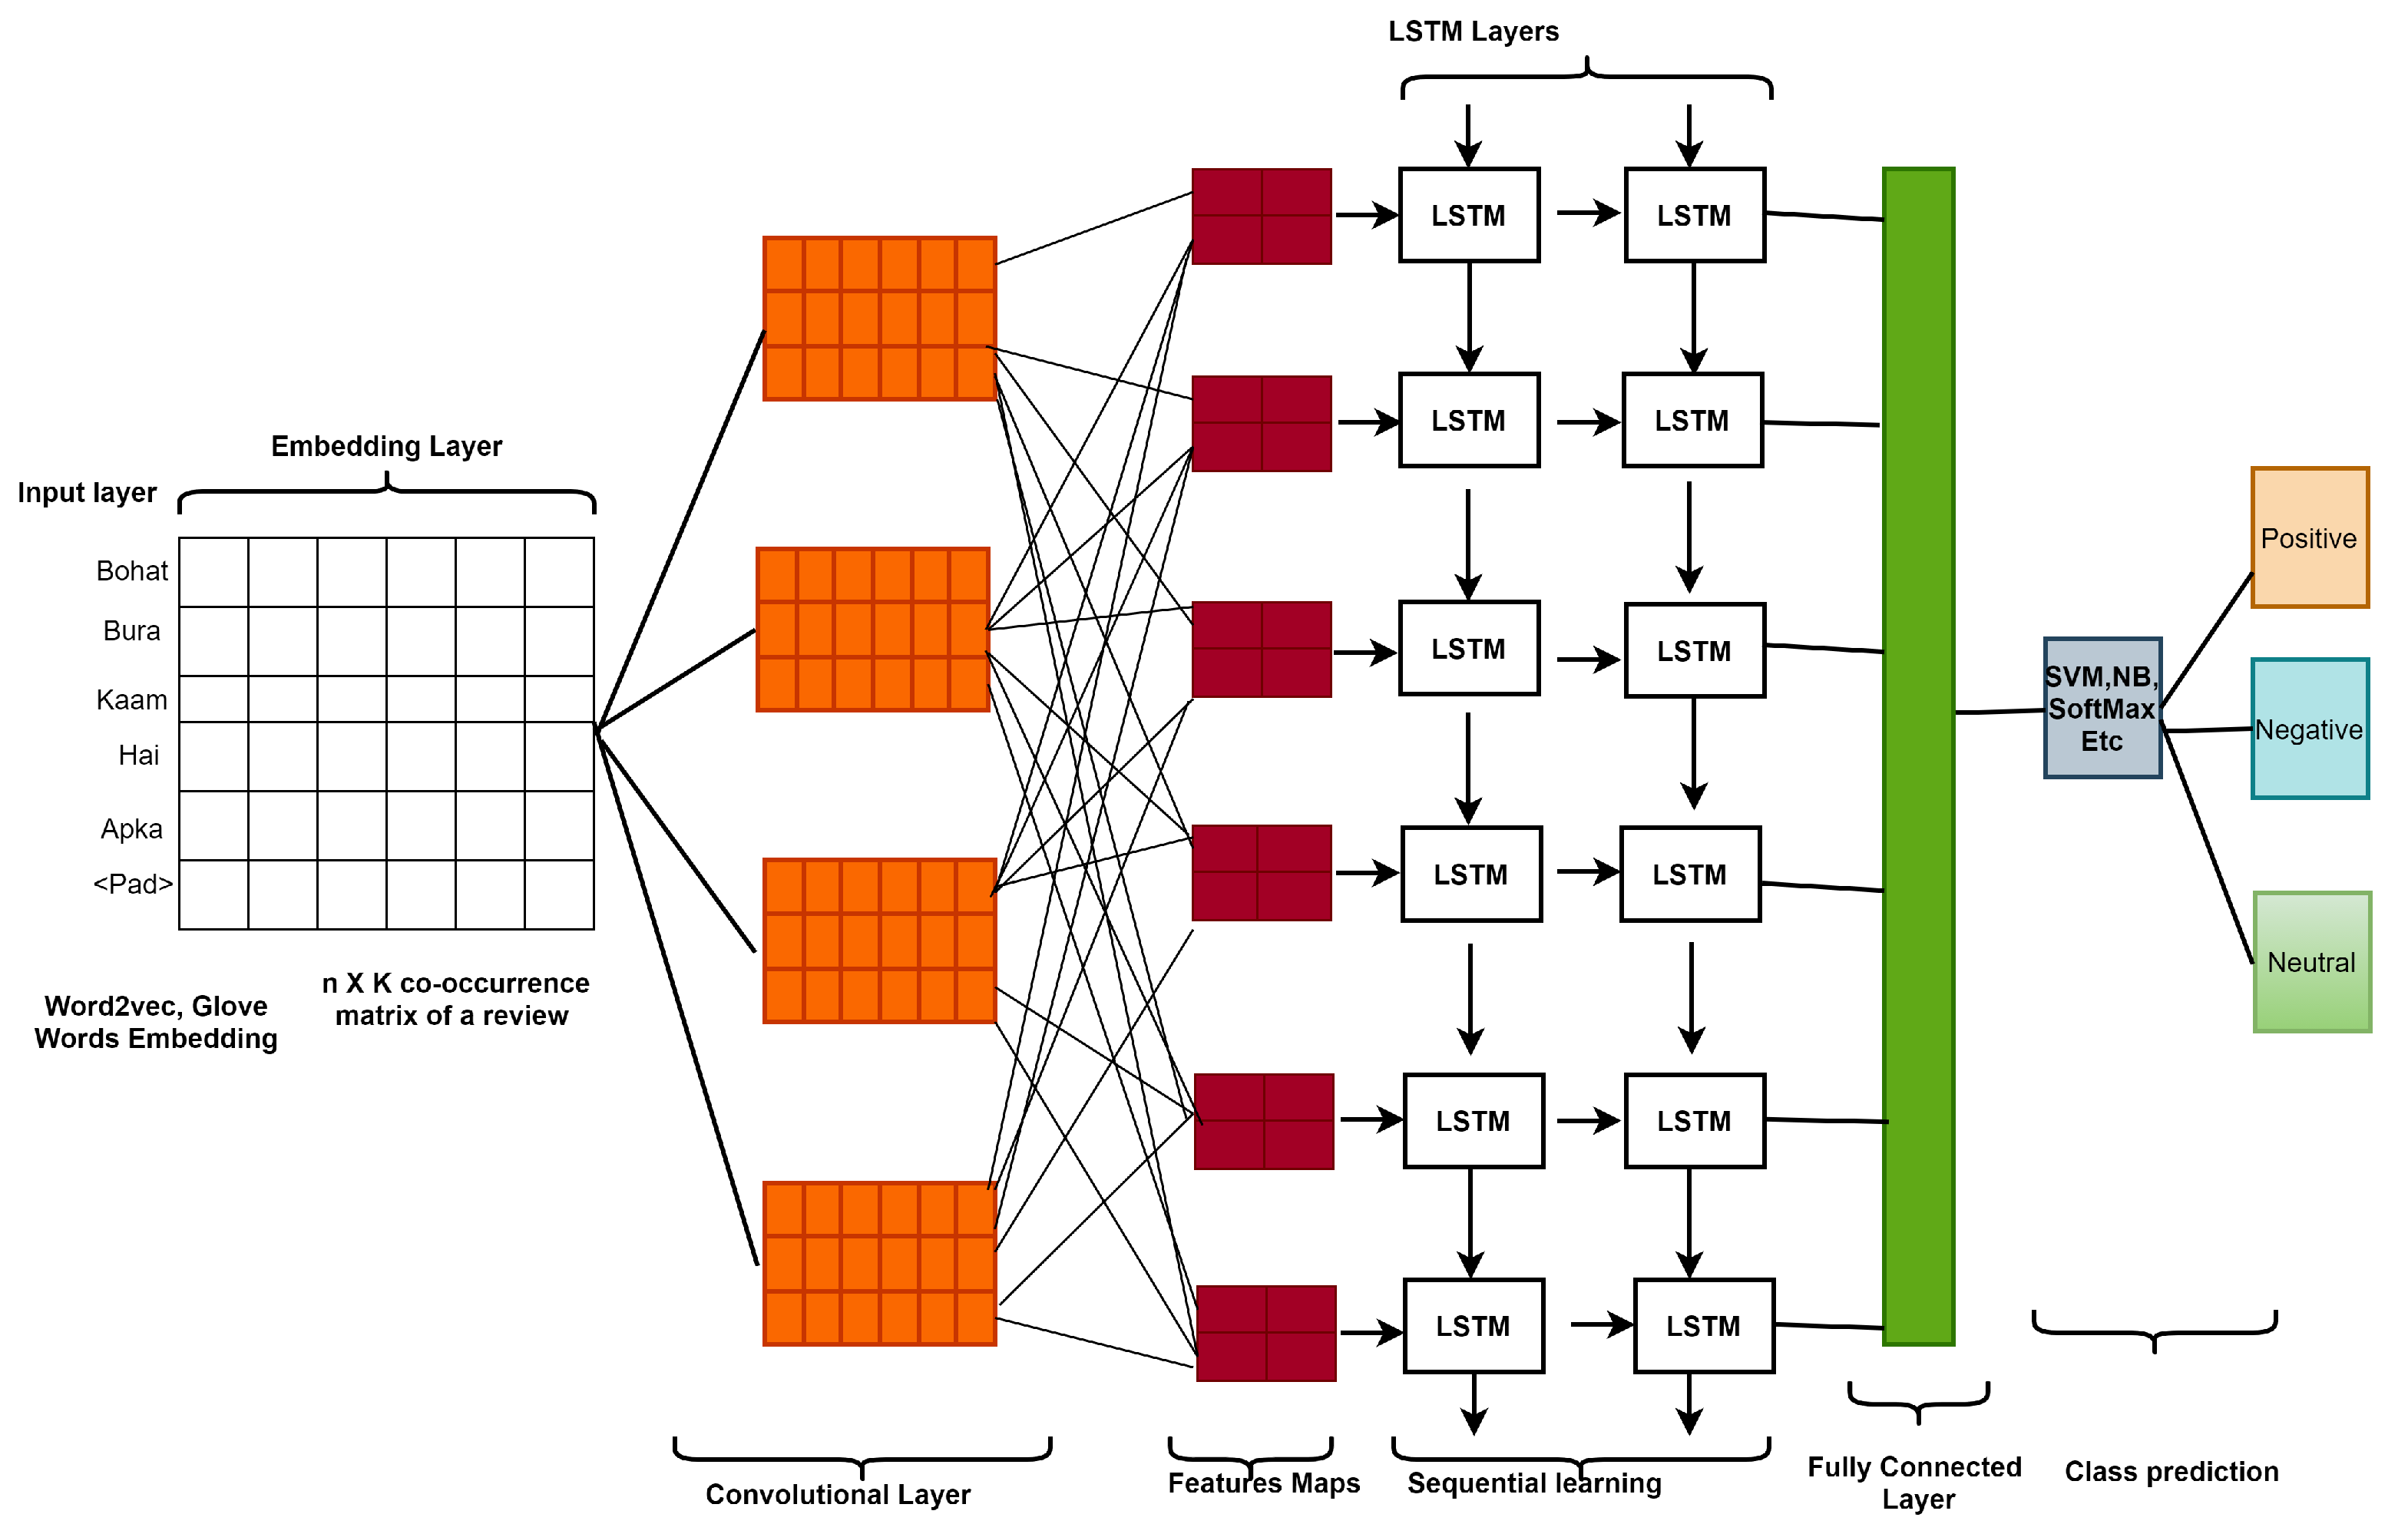
An LSTM processes a sentence one token at a time while maintaining a hidden state that carries information across the sequence. The key component is the cell state, which runs through the entire sequence and gets modified by three gates at each step: the forget gate decides what to discard, the input gate decides what new information to store, and the output gate decides what to pass forward. This is what lets the model remember that "not good" from the beginning of a sentence overrides the positive word "good" near the end. For sentiment specifically, you typically feed an embedding layer into a stack of one or two LSTM layers, then attach a dense output layer with a sigmoid activation for binary classification or softmax for multi-class. Input sequences get padded or truncated to a fixed length, usually between 50 and 200 tokens depending on your data. Most IMDB-scale datasets max out around 200 tokens anyway since reviewers don't write novels in a star rating.
The Pipeline Step by Step
Tokenize your text using a whitespace or subword tokenizer, then map each token to an integer ID. Reserve index zero for padding and index one for unknown tokens. Feed these sequences into an embedding layer that projects each ID into a dense vector space, typically 64 to 256 dimensions. Pass the embeddings through your LSTM layers. If you're using PyTorch, set batch_first=True so your tensor shape is batch_size times sequence_length times embedding_dim rather than the default sequence-first layout that catches everyone off guard on the first try. After the final timestep, take the output from the last timestep and route it through a dropout layer, then a linear layer, then your activation function. For training, binary cross-entropy with logits is the standard loss function when using a sigmoid output. Use Adam with a learning rate around 0.001. Your batch size should be 32 or 64. Train for about 5 to 10 epochs on a dataset like IMDB or SST-2, and you should see validation accuracy settle somewhere between 87 and 91 percent depending on your preprocessing choices. I learned the hard way that removing stopwords before feeding text into an LSTM actually hurts performance. Negation words like "not" and "never" are stopword candidates in many lists, but they are among the most important signals for sentiment classification. Keep them. Strip punctuation instead. That alone pushed my F1 score from 0.82 to 0.87 on a mixed-domain dataset I was working with.
Get the Full Details

Where This Approach Breaks Down
LSTMs process sequences sequentially. They cannot be parallelized across the time dimension the way transformer attention can, which means training is measurably slower than equivalent transformer-based approaches on the same hardware. A comparable bidirectional LSTM on a GPU might take 40 to 60 minutes to train on IMDB, while a small BERT model finishes in roughly 15 to 20 minutes and typically reaches 92 to 94 percent accuracy instead of the 88 to 90 percent ceiling you usually hit with LSTMs. Another failure mode is long-range dependency handling. LSTMs were designed to solve the vanishing gradient problem that plagued plain RNNs, but they still degrade when the relevant context sits beyond roughly 100 to 150 tokens. If your sentiment task requires understanding a contrastive structure where the opinion target appears early and the evaluative language appears at the end of a long paragraph, the model will lose track. This is especially visible in product review datasets where users write detailed context before delivering their verdict. For anything beyond basic positive-negative classification, like fine-grained aspect-based sentiment or multi-label emotion detection, an LSTM alone is insufficient. You'd need to add attention mechanisms or switch to a pre-trained transformer architecture entirely.
Practical Implementation Notes
If you want to implement this yourself rather than import a library solution, the core structure is roughly 60 lines of code in PyTorch. The critical detail most beginners miss is that you should use packed_sequence when your batch contains differently sized sequences. Without it, padding tokens contribute useless gradient signal and slow training without improving accuracy. Packing tells the LSTM to ignore padded positions during computation, which typically cuts training time by about 20 percent on variable-length datasets. For a ready-to-run implementation, Hugging Face's transformers library includes pre-built LSTM-based models in its sequence classification pipeline, though most users default to transformer models regardless. If you specifically need an LSTM for deployment constraints or interpretability reasons, the standard approach is to use PyTorch's torch.nn.LSTM or torch.nn.LSTMCell directly. You can find clean reference implementations in the official PyTorch documentation under the sequence modeling section, and community implementations on GitHub tend to follow similar structures with minor variations in regularization and embedding initialization strategies. The biggest practical advantage of sticking with LSTMs today is model size. A well-tuned LSTM for sentiment analysis typically produces a model file under 10 megabytes when saved with its embedding weights. That fits comfortably on edge devices and embedded systems where loading a 200-megabyte transformer is not feasible. If your deployment target is a mobile app or a low-power inference endpoint, the LSTM remains a legitimate choice despite the accuracy gap.
One more thing worth noting: label smoothing helps here more than you'd expect. Adding a small epsilon value like 0.1 to your cross-entropy loss prevents the model from becoming overconfident on easily classifiable examples, which leaves more representational capacity for the ambiguous cases that actually matter in production. I've seen this technique move F1 scores by 2 to 4 percentage points on imbalanced sentiment datasets without touching the architecture at all.