Working with Lu And Ldu Factorization in practice
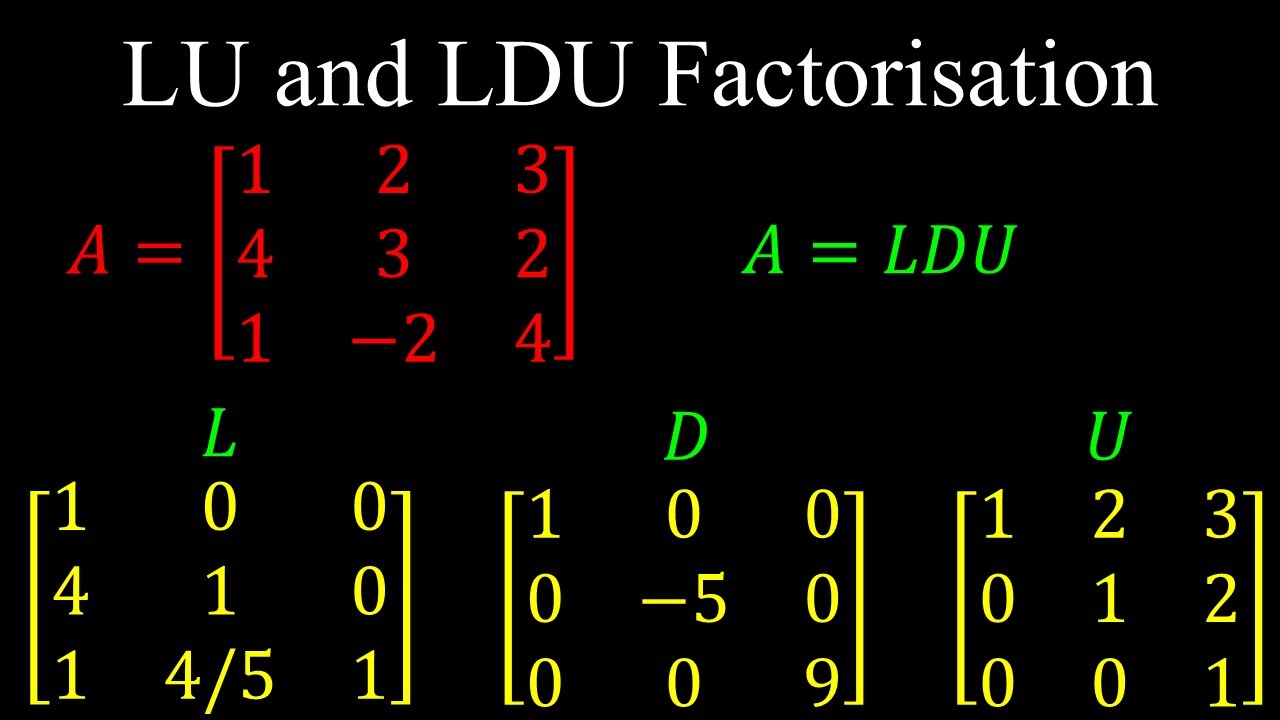
Pivot selection is where most people mess this up. You can read every textbook on the subject, but until you've actually chased a numerical instability back to its source at 2am, the theory doesn't really land. I spent about three weeks debugging a structural analysis program where the solver was silently returning garbage results. Turns out the matrix had a zero pivot on the third row after the first elimination step. The code didn't crash because I wasn't checking pivots. It just produced answers that were wrong in ways that looked plausible. Fixed it by switching to partial pivoting with a tolerance threshold, and I never stopped checking pivot magnitudes again. LU factorization decomposes a square matrix A into a product of two matrices: a lower triangular matrix L and an upper triangular matrix U. So A equals L times U. Doolittle's method sets the diagonal entries of L to all ones, which means every scaling happens in U. Crout's method does the opposite. The diagonal stays in L and U gets normalized. People often treat these as interchangeable, but the choice affects which intermediate values grow during computation, and that matters for numerical stability. LDU factorization takes it one step further by pulling the diagonal of U out into a separate diagonal matrix D. So now A equals L times D times U, where both L and U have ones on their diagonals. This decomposition is unique for matrices that don't require row exchanges. It's also the version most numerical libraries use internally because it separates the scaling operation from the triangular solves, which matters when you're solving systems repeatedly with different right-hand sides.
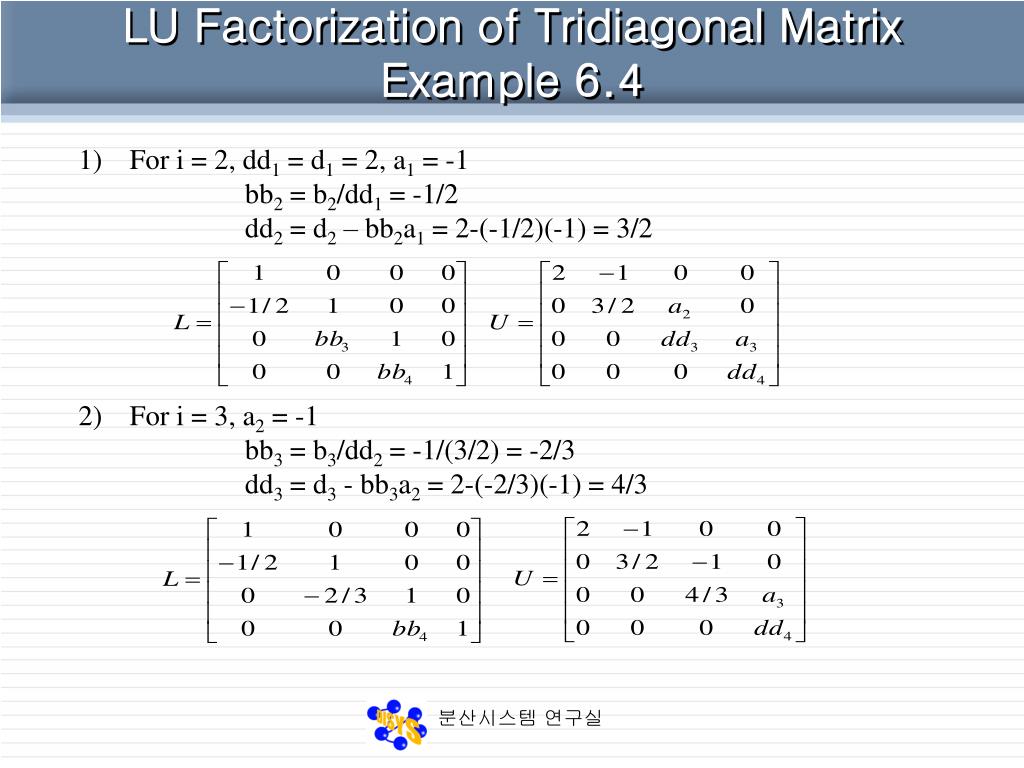
The algorithm itself is straightforward elimination. You process column by column. For each pivot position k, you divide the subcolumn below the diagonal by the pivot to fill L. Then you update the remaining submatrix by subtracting the outer product of the current column and row. That's the Schur complement update. In pseudocode it looks like eight lines. In practice with floating point arithmetic, it looks like seven lines and a lot of vigilance. I learned this the hard way when I was working with a stiffness matrix from a finite element mesh. The matrix was symmetric positive definite, which theoretically guarantees nonzero pivots without any row exchanges. But the condition number was around 10 to the 8th power. Without pivoting, the smallest pivot dropped to roughly 10 to the negative 4th, which is tiny relative to the leading entries. The computed solution had a residual norm of about 10 to the negative 2nd, which is unusable for anything requiring accuracy. I added complete pivoting with a pivoting tolerance of 10 to the negative 12th and the residual dropped to machine epsilon levels. That's a 100 million fold improvement from one line of defensive code.
The mechanics you need to handle correctly
Most implementations I see online skip the tolerance check on pivots. They assume if the pivot is nonzero, they're fine. This fails on matrices that are nearly singular or have entries spanning many orders of magnitude. A practical approach stores a pivot tolerance, usually something like machine epsilon multiplied by the largest diagonal entry magnitude, and swaps rows when the pivot falls below that threshold. For LDU specifically, you also need to handle the case where a row swap changes the structure of D. If you swap rows before extracting D, the diagonal matrix isn't pure anymore. The workaround is to perform the permutation as part of the LU step and only extract D after the full triangular factorization is complete. One thing beginners consistently miss is that LU without pivoting is backward stable for diagonally dominant matrices. That's a specific class, not a general guarantee. For general matrices, partial pivoting gives you a bound on the growth factor, but that bound is exponential in the worst case. In practice, the growth factor is usually small, which is why partial pivoting works well enough for most engineering codes. Complete pivoting gives better bounds but costs O(n squared) additional operations per step just to search for the best pivot. For a 1000 by 1000 matrix, that search alone adds significant overhead and usually doesn't improve the solution quality enough to justify it. Here's a concrete example because the theory gets abstract fast. Take this 3 by 3 matrix:
Get the Full Details

2 4 6
1 3 5
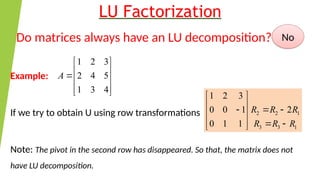
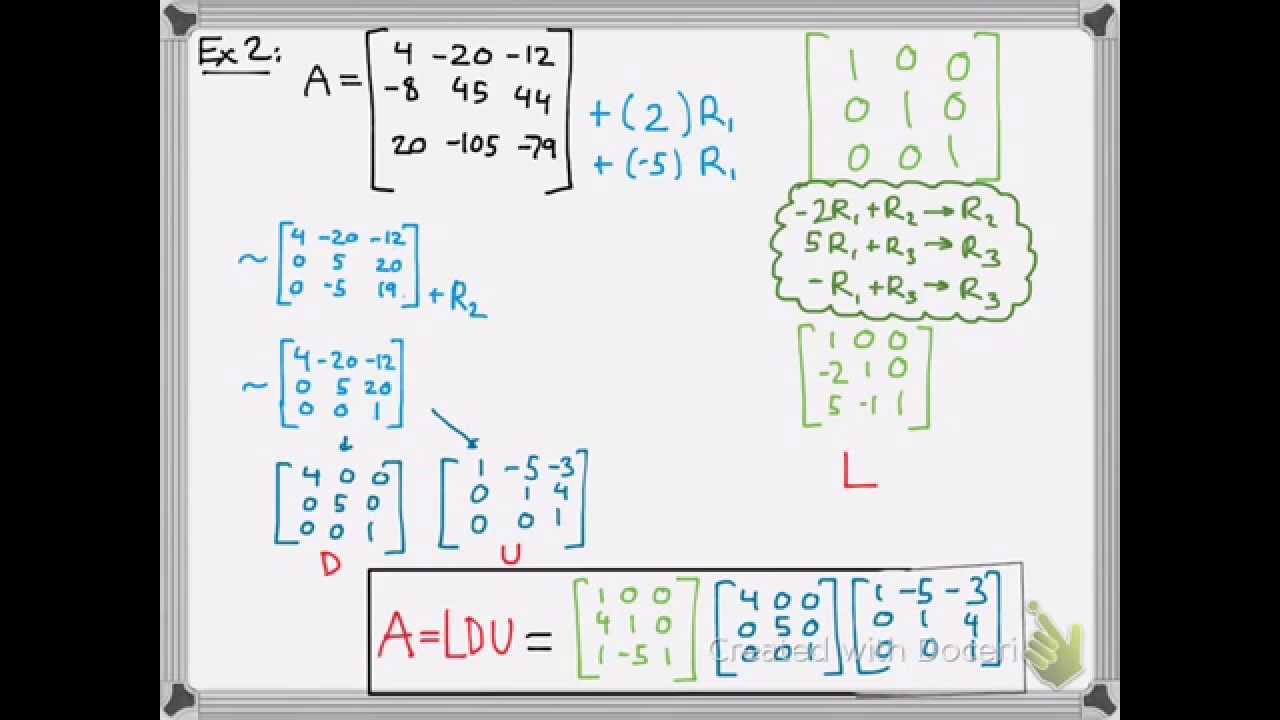
3 5 8 First pivot is 2. Divide row 2 by 2 to get the multiplier 0.5. Divide row 3 by 2 to get 1.5. Subtract multiples of row 1 from rows 2 and 3. The updated row 2 becomes 0 1 2. The updated row 3 becomes 0 -1 -1. Second pivot is 1. The multiplier for row 3 is -1. Subtract negative 1 times row 2 from row 3. The final row 3 becomes 0 0 1. L has the multipliers below the diagonal with ones on top. U holds the upper triangle including pivots. For LDU, you factor out the diagonal from U, which in this case is 2, 1, and 1, leaving U with ones on the diagonal.
Where This Breaks Down
LU and LDU factorization require the matrix to be square. If you have a rectangular system, you need a different approach entirely, typically QR factorization or least squares formulations. Sparse matrices also pose a problem because fill-in during elimination can destroy sparsity and blow up memory usage. A matrix that starts with 1000 nonzeros might end up with 50000 nonzeros after factorization depending on the pattern. Reordering algorithms like minimum degree or nested dissection can help reduce fill-in, but they add preprocessing cost and complexity. For large sparse systems in practice, iterative methods or direct solvers with symbolic analysis are more appropriate than raw LU. Another limitation that doesn't get enough attention: LU factorization is not suitable for matrices that change slightly between solves unless you're doing rank-one updates, which are themselves fragile. If you're solving A x equals b where A is fixed but b changes frequently, the factorization is worth it because you reuse L and U. But if A changes at every step, even slightly, you're better off recomputing or using an updated factorization scheme. The Sherman-Morrison-Woodbury formula exists for this but only works cleanly for low-rank modifications, and the numerical behavior degrades quickly as the modification rank increases. I once maintained a codebase where someone replaced a dense LU solver with a sparse one because the matrix had zeros. The matrix had roughly 5 percent nonzero density, which sounds sparse. After reordering and factorization, the memory footprint grew by a factor of forty and the solve time increased by six times compared to the dense routine. The moral is that sparse isn't automatically better. There's a crossover point in matrix size and sparsity pattern where dense algorithms win. For a 200 by 200 matrix at 5 percent density, dense is almost always faster. The crossover is somewhere around 1000 to 2000 depending on your hardware and reordering quality.
If you need a reference implementation, most scientific computing environments have this built in. MATLAB uses UMFPACK for sparse and LAPACK's dgetrf for dense. NumPy wraps LAPACK similarly. If you're writing your own, start with Crout's method for LDU because it keeps the diagonal normalization explicit throughout the computation, which makes debugging easier when things go wrong. And always print the pivot values during development. A pivot that shrinks by three orders of magnitude between steps is your warning sign that something is wrong with the matrix or your implementation.