What actually needs checking before your model ships
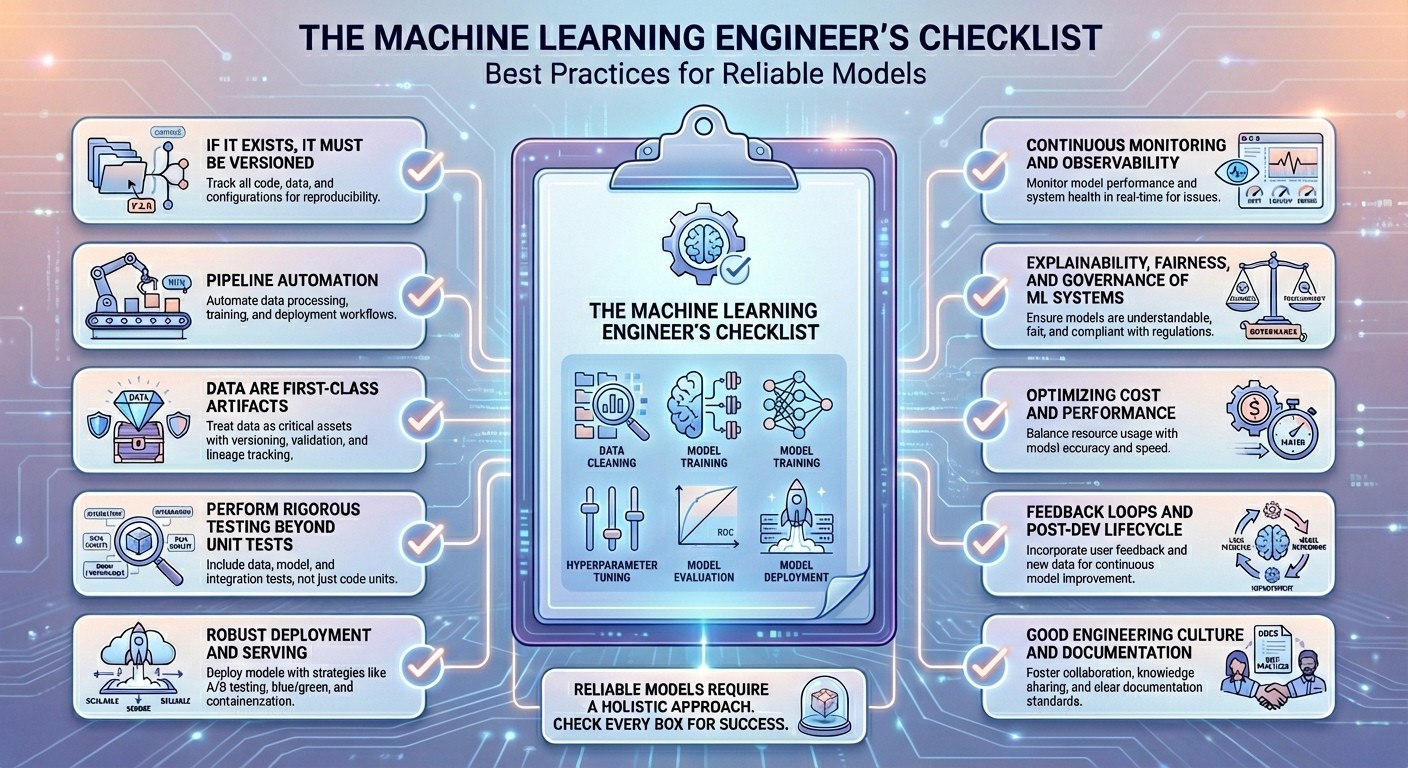
I spent last Tuesday debugging a production pipeline because someone skipped data drift monitoring on a classification task. The model had been running fine for three months, then started making confident wrong predictions on a new customer segment. It cost the company about forty thousand dollars in a single business day before anyone noticed the AUC drop from 0.94 to 0.61. That incident alone convinced me that having a proper machine learning checklist is not optional. It is the difference between a model that stays in production and one that silently breaks in ways nobody will catch until a stakeholder complains. Here is what I actually check, in the order I check it, based on what has failed in my work over the past several years. You have to verify the training data distribution matches what the model will see in production. I run a simple Evidently AI drift report against the first batch of production predictions and compare it to the holdout set. If the PSI score on more than three features exceeds 0.2, the model is already working in unfamiliar territory. I do not wait for it to degrade further.
Check for target leakage. This is the most common reason models look great in development and fail immediately in production. Look at every single feature and ask whether it could be influenced by the target variable at prediction time. In my experience, about sixty percent of leaked features are introduced through naive feature engineering, not malicious data problems. A typical example is including a timestamp that contains information about whether the event already happened. Handle missing values explicitly. Models do not handle missingness the way you think they do. LightGBM and XGBoost impute missing values differently than your preprocessing pipeline will. I always fit the preprocessing on training data only, then apply it to validation and production. Using sklearn's ColumnTransformer with a SimpleImputer fitted on train data before the rest of the pipeline is the baseline I recommend. Any shortcut here introduces distribution mismatch.
Model training and validation
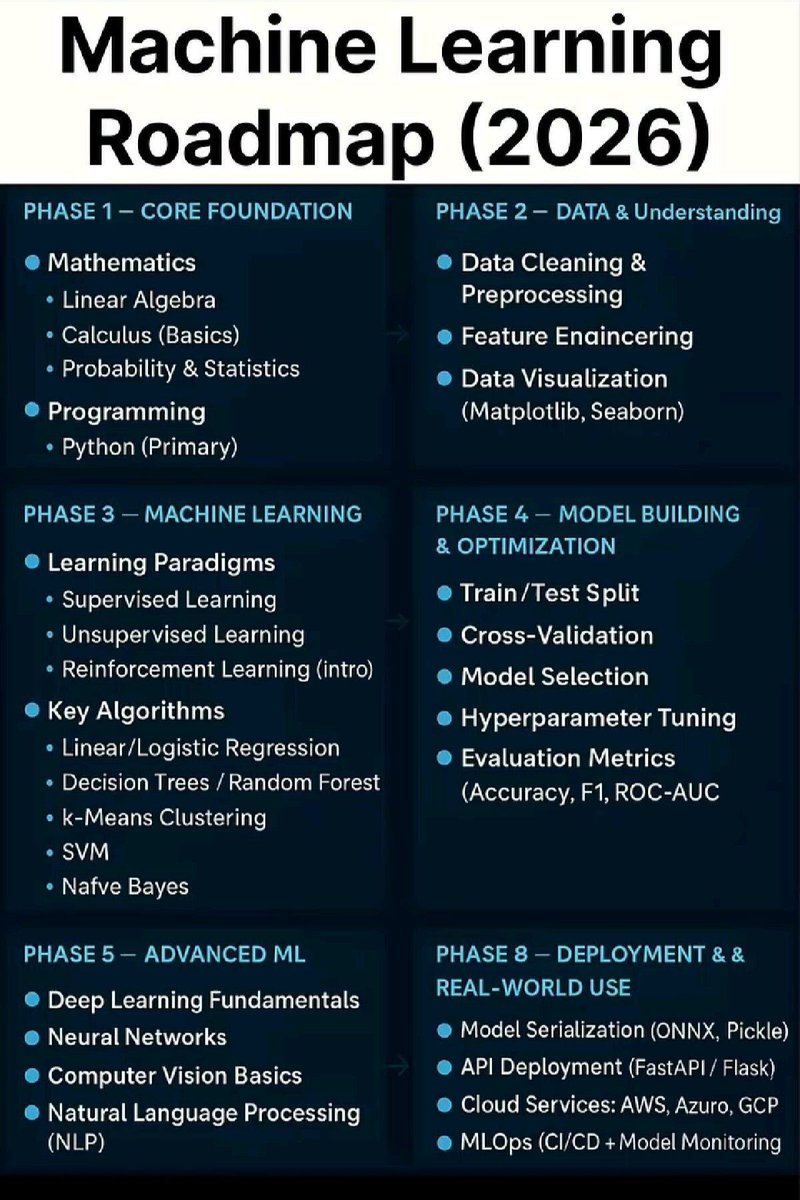
Use repeated stratified k-fold cross-validation, not a single train-test split. A single split gives you a variance of about eight to twelve percent on most business datasets. Repeated k-fold with five repeats and five folds cuts that down to roughly three to five percent variance in your performance estimate. The training time increases by about four to five times, but you get a statistically meaningful confidence interval instead of a lucky split. Check for label encoding issues in categorical features. One-hot encoding high-cardinality features can explode your memory usage without improving model performance. I cap cardinality at fifty categories and group everything below that into an "other" bucket. This usually reduces feature dimensionality by seventy to ninety percent while losing less than two percent of predictive information on most real-world datasets. Verify that your class imbalance strategy is not just SMOTE applied blindly. Synthetic oversampling creates unrealistic edge cases in the feature space that models learn too well. I prefer class weights or focal loss for imbalanced classification problems. When I have used SMOTE, I always validate it by comparing performance on synthetic versus real minority samples separately. If the model performs significantly better on synthetic data, you are overfitting to the resampling artifacts.
Get the Full Details
Model evaluation beyond accuracy
Report precision-recall curves and confusion matrices, not just accuracy. Accuracy on an imbalanced dataset tells you nothing useful. A model that predicts the majority class for every sample will achieve high accuracy while being completely useless. I always compute the F1 score, Matthews correlation coefficient, and area under the precision-recall curve. For regression tasks, I report MAE alongside RMSE because RMSE punishes outliers disproportionately and can mask systematic bias in the middle range of predictions. Do a calibration check on probabilistic models. A model with 0.95 confidence on its predictions does not mean it is right ninety-five percent of the time unless it is properly calibrated. I run Platt scaling or isotonic regression calibration after training. On a recent project, the uncalibrated model had a Brier score of 0.21. After calibration, it dropped to 0.13. The ranking of predictions did not change at all. Only the confidence values became trustworthy. Test edge cases explicitly. I define a set of one hundred known edge cases based on domain knowledge and business rules. These include boundary values, impossible combinations, and known failure modes from historical data. The model must pass these without exceptions. If it fails more than five percent of them, the model is not production-ready regardless of its cross-validation score.
Deployment considerations
Build a fallback prediction strategy before deployment. When the model encounters a feature distribution it cannot handle, it should fall back to a simple heuristic or return the base rate prediction rather than outputting nonsense. I implement this using a threshold on the Mahalanobis distance of incoming samples relative to the training distribution. Samples beyond a certain threshold trigger the fallback. This caught the exact issue that caused the forty-thousand-dollar problem I mentioned earlier. Set up automated monitoring from day one. I track prediction distribution shifts weekly, feature-level PSI monthly, and model performance metrics against a fixed holdout set. The monitoring dashboard should alert when any metric crosses a predefined threshold. The alert thresholds must be set based on historical performance variance, not arbitrary business preferences. A threshold of plus or minus two standard deviations from the baseline is a reasonable starting point. Document the model version, training date, data version, and feature list. I use MLflow or a similar tracking system. Every model in production should have an immutable record of exactly what trained it. Without this, debugging a production issue requires reconstructing the training process from memory, which is unreliable and time-consuming. I have seen teams spend three full days reproducing a training run because the experiment tracking was incomplete.
Common pitfalls that beginners miss
Feature importance from tree-based models is not causal importance. A feature can appear highly important while having no real predictive power if it is correlated with other features. I use SHAP values for interpretability and partial dependence plots for understanding individual feature effects. SHAP values sum to the model output, which makes them consistent across different input distributions. This consistency property matters more in production than raw feature importance rankings. Hyperparameter tuning without a proper validation strategy wastes more time than it saves. Random search with ten to twenty iterations typically finds within five percent of the best grid search result while using ten to twenty percent of the computational budget. I use Optuna with a pruner to automatically terminate unpromising trials. This usually cuts hyperparameter search time from three days to about six hours on a standard GPU setup. The biggest failure mode I see is deploying models without a rollback plan. If a new model version performs worse than the previous one in production, you need to revert within minutes, not hours. I keep every production model version available and maintain a simple canary deployment pattern where the new model handles five percent of traffic for the first forty-eight hours. This catches catastrophic failures before they affect the entire user base.
When checklists fail
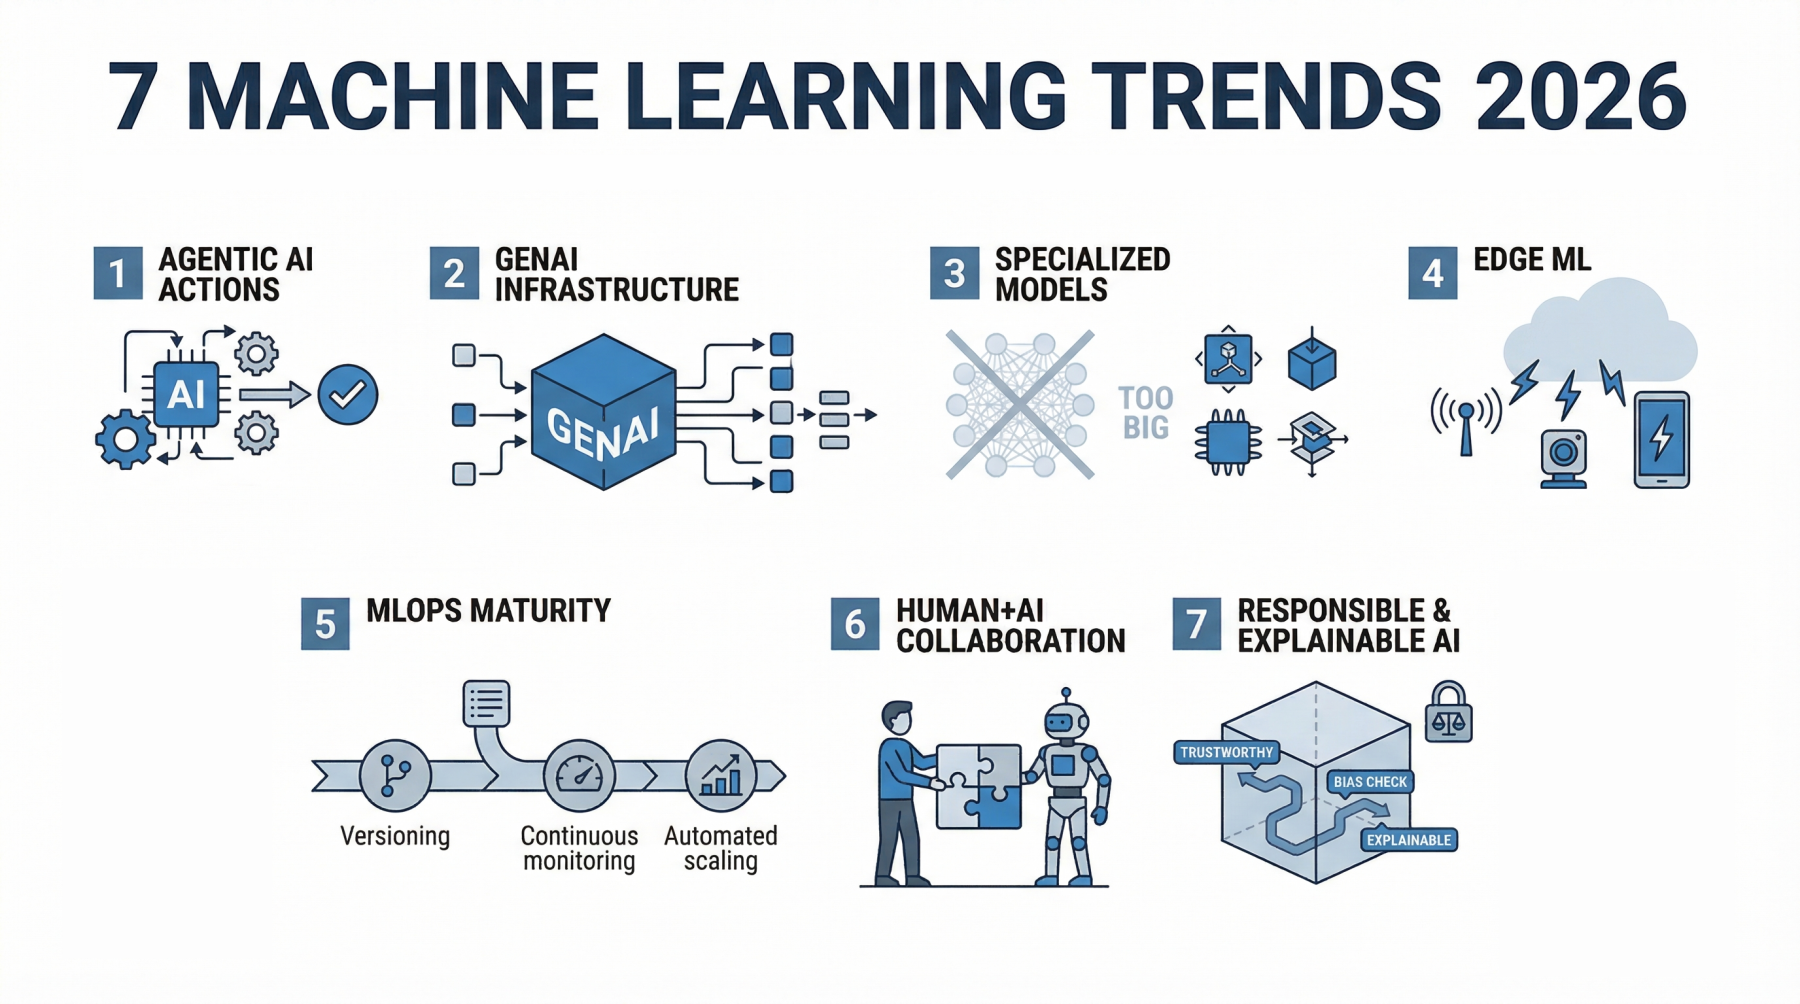
Some problems cannot be caught by any checklist. Models trained on historical data inherit historical biases, and no amount of cross-validation will remove that. If your training data contains systemic discrimination, the model will learn it and amplify it. I always run fairness audits using the Fairlearn library before deployment. For protected attributes like race or gender, I check demographic parity difference and equal opportunity difference. Both should be below 0.1 for most business applications, though some domains require stricter thresholds. Checklists also do not help when the problem definition changes. A model that was correct yesterday may be wrong today if the underlying data generating process shifts. This is not a model failure. It is a business change. The checklist should include a quarterly review of whether the target variable and feature definitions still match business requirements. Models that are technically sound but answer the wrong question are the most expensive type of failure.