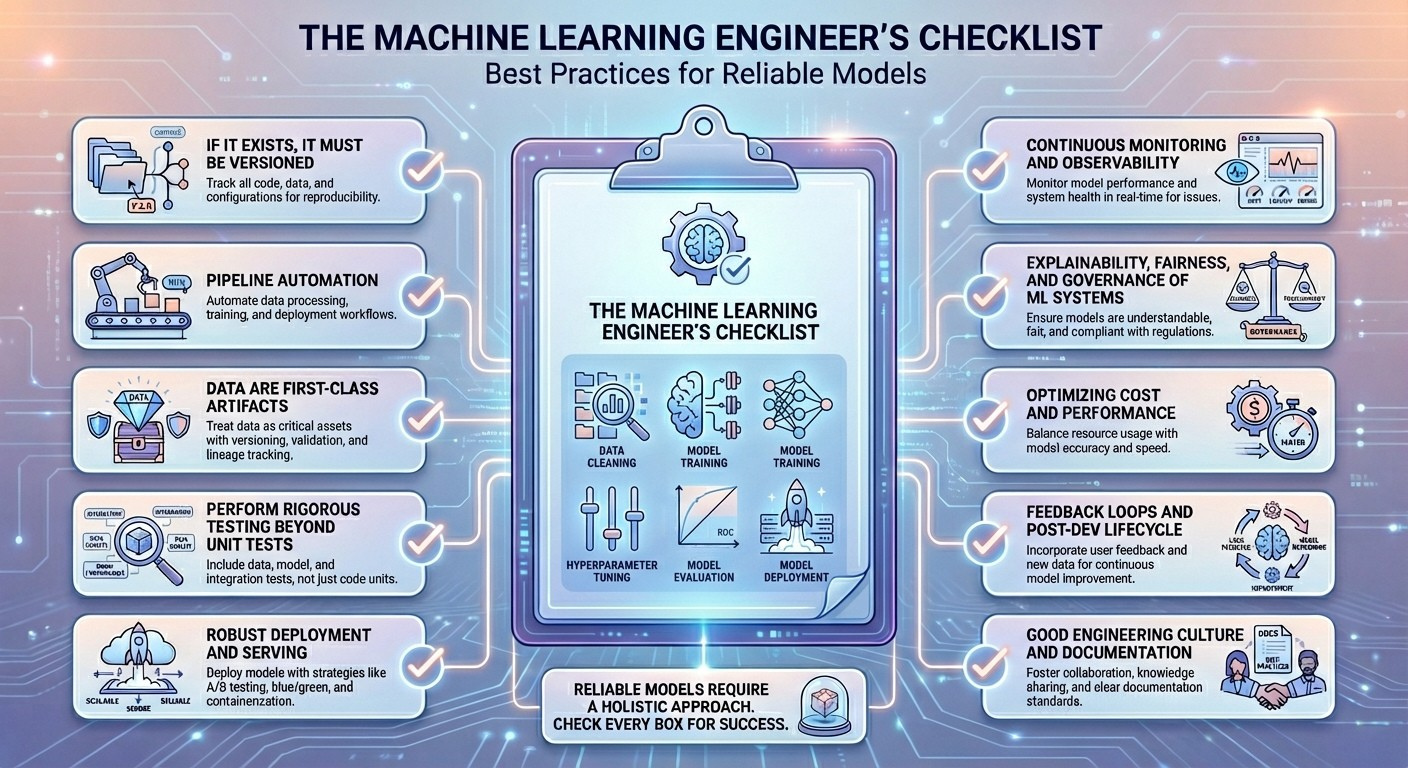
Machine Learning Checklist Best: A Practical Framework That Actually Works
I spent three years building ML pipelines for production systems before I realized most of my time wasn't going toward model training or hyperparameter tuning. It was going toward debugging data issues, reconciling pre-processing drift, and figuring out why the validation metrics looked great while the production system failed every other Thursday. A machine learning checklist best approach helps you catch these problems before they cost you weeks of rework. Most people treat checklists as something for beginners who need hand-holding. That's wrong. Checklists exist because human memory is unreliable under stress. When you're racing to meet a deadline and your model outputs look slightly off, you won't remember to verify the feature store timestamps. Someone else might, but if they aren't in the room, you're relying on luck. The checklist I use isn't tied to any particular framework or tool. It covers the full lifecycle from problem definition through deployment monitoring. I built it by tracking every post-mortem my team had after a production incident and asking what single question could have prevented it. Some items appear on almost every list. Others are specific to edge cases I ran into the hard way.
Problem Definition and Scope
Before writing a single line of code, answer these questions clearly enough that a non-technical stakeholder could repeat them back without distortion: What exact business decision will this model influence? Which metric correlates with success? What happens when the model is wrong? Is the problem well-defined or does it require exploratory analysis first? I once joined a project where the stated goal was "predict customer churn." The team had spent four months building a sophisticated gradient boosting model with an AUC of 0.91. When I asked what "churn" actually meant in their system, they couldn't agree. One department defined it as cancellation. Another counted it as 90 days of inactivity. A third only considered accounts that were billed at least once. The model was optimizing for none of these definitions because nobody had committed to one during scoping.
Write down the ground truth protocol before data collection begins. Specify how labels are generated, who generates them, and what the disagreement threshold is between labelers. If you skip this step, your model will learn from noise and you won't know why until it's too late.
Get the Full Details
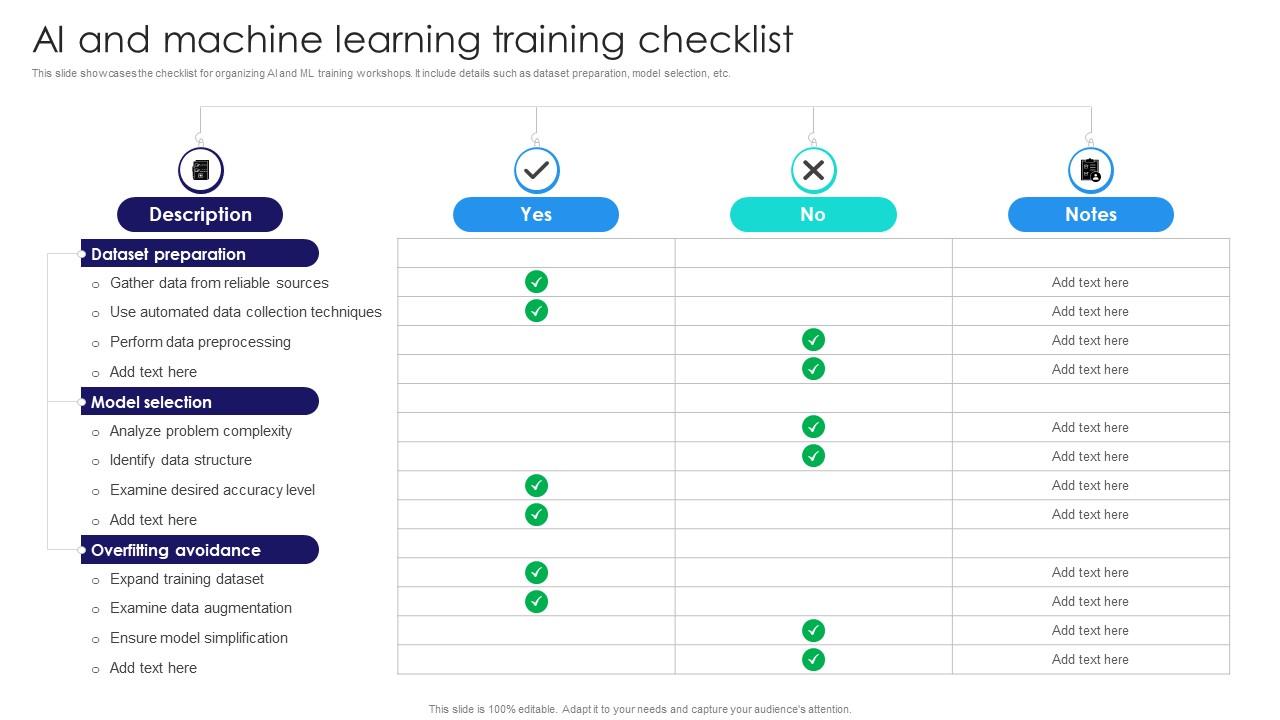
Data Collection and Quality Assessment
Check that your dataset covers the distribution you expect at inference time. This sounds obvious but it fails constantly in production environments. Here's what to verify: Temporal consistency between training and expected serving periods. Geographic or demographic representativeness. Missing value patterns and whether they are random or systematic. Class balance and whether oversampling or class weights are appropriate. Data leakage sources, especially temporal leakage where future information appears in historical features. When I worked on a fraud detection system, our training data contained transaction timestamps up to six months ahead of the prediction point because the data engineering pipeline hadn't properly partitioned the timeline. The model appeared to achieve 99% precision during validation. It dropped to 41% precision in production on day one. The fix wasn't architectural. We simply shuffled the data, recomputed features using only information available at prediction time, and retrained. The model was already correct; the data was lying to us.
Feature Engineering and Selection
Document every feature transformation from raw input to final representation. This documentation should be machine-readable when possible, either through a feature pipeline config or a standardized schema file. Human-readable documentation alone will fall out of sync within weeks. Common pitfalls I see repeatedly: Aggregating features over windows that are too wide, creating look-ahead bias. Transforming features independently in training and serving pipelines without version control. Using statistics computed on the full dataset rather than fold-specific statistics during cross-validation. Creating features that depend on downstream variables which wouldn't be available at prediction time.
Feature importance scores from tree-based models are not causal. They measure predictive contribution within the training distribution, not the actual impact of a feature. Do not drop features solely because their importance score is low. Correlated features can individually appear unimportant while jointly being critical.

Model Development and Validation
Baseline your results before investing in complex architectures. A simple logistic regression or decision stump trained on the same features will establish the floor performance. If your neural network cannot beat it by a meaningful margin, the complexity is not justified. Validation strategy matters more than most teams realize. Time-series data requires temporal splitting. Group-level data requires group-aware K-fold splitting. Simple random K-fold will leak information across folds and produce optimistically biased metrics. Use the appropriate splitting strategy from the start, not after you've already trained and evaluated the model. Keep a model registry. Every experiment that produces a checkpoint should log the training configuration, the validation metrics, the feature set used, and the data split information. Without this traceability, you will never be able to reproduce a working model or understand why a previous version performed better or worse.
Training and Optimization
Monitor loss curves and validation metrics across epochs, not just the final values. Early stopping based on validation loss is standard practice, but define the patience parameter based on actual training behavior rather than a default. Different models converge at different rates. A patience of 10 epochs might be appropriate for one architecture and wasteful for another. Learning rate scheduling generally improves convergence for deep networks. Linear decay, cosine annealing, and reduce-on-plateau are all reasonable choices depending on the optimization landscape. Test at least two scheduling strategies rather than committing to the first one you find documented online. Batch size affects both training speed and generalization. Smaller batches introduce noise that can help escape sharp minima. Larger batches train faster but may converge to flatter solutions that generalize differently. There is no universal optimal batch size. Find it empirically for your specific hardware and dataset combination.
Deployment Considerations
Model serialization format determines what serving infrastructure you can use. ONNX, TensorFlow SavedModel, and TorchScript each have different ecosystem support and hardware acceleration options. Choose the format early and commit to it. Converting between formats after training introduces subtle numerical differences that can affect inference results. API design should include confidence scores alongside predictions. Downstream systems often need to decide whether to trust a prediction or route to a human reviewer. Without calibrated probabilities, the consumer has no basis for that decision. Implement shadow deployments before full rollout. Route live traffic to both the new model and the existing model without affecting user responses. Compare predictions and latency over a representative period. If the new model shows degradation on any segment of traffic, the shadow phase will reveal it before users notice.

Machine Learning Checklist Best: The Consolidated Reference
Here is the consolidated checklist I return to for every project. It evolved from the items above and has been stress-tested across production deployments in finance, healthcare, and e-commerce. Problem definition complete with success metric and failure consequences documented. Ground truth protocol specified including labeling criteria and inter-annotator agreement threshold.
Dataset distribution verified against expected serving distribution. Temporal leakage audit completed with source documentation. Feature transformations version-controlled and independently auditable.
Validation split strategy appropriate for data structure. Baseline model trained and documented. Experiment tracking configured with full configuration history.
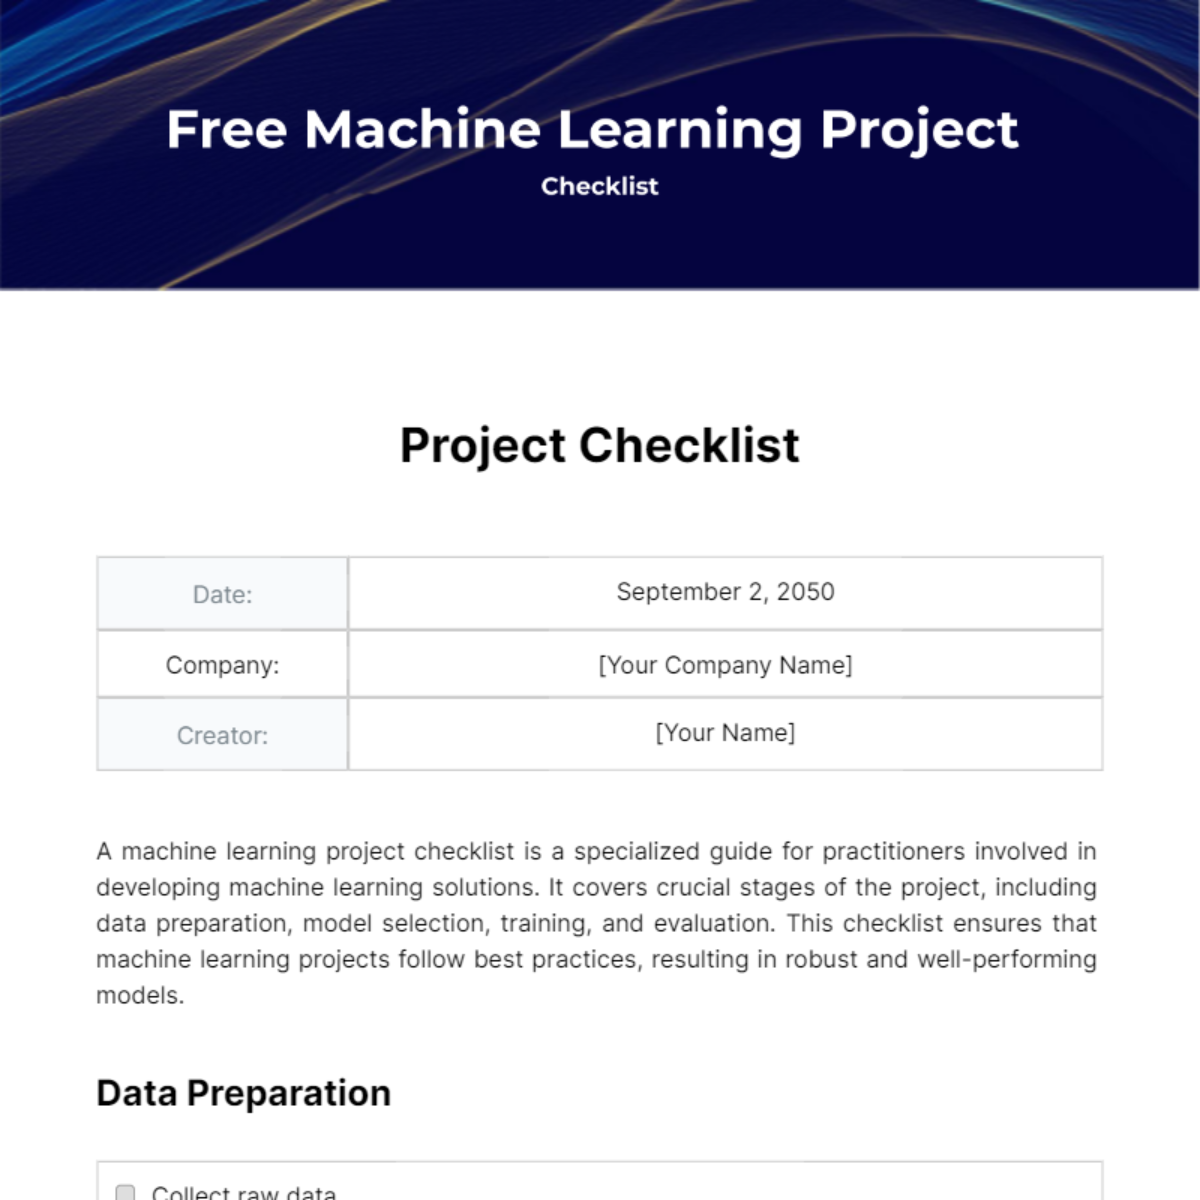
Model serialization format selected and compatible with target serving infrastructure. Shadow deployment plan documented before production cutover. Monitoring schema defined including prediction drift detection and feedback collection.
This checklist is not exhaustive. Certain domains will require additional items. Healthcare deployments need HIPAA compliance verification. Financial models need model risk management documentation. But the core structure applies universally because the failure modes are consistent across domains.
Where Checklists Fail and What to Use Instead
A checklist has a fundamental limitation: it only catches problems it already knows about. Novel failure modes will not appear on any existing list. When you encounter a problem that your checklist did not flag, the solution is not to add a new item. The solution is to understand the underlying principle that the item was trying to enforce and apply that principle to the new situation. For example, the item about temporal leakage exists because of the underlying principle that information from the future cannot be available at prediction time. Any implementation of that principle will prevent the class of errors the checklist item was designed to catch. New types of leakage that haven't been discovered yet will still violate the same principle. If you find yourself adding items to a checklist because similar problems keep occurring, consolidate those items back into their underlying principle and rewrite the checklist around fewer, higher-level checks. A checklist with fifty items gets ignored. A checklist with twelve principles gets followed.
The best machine learning checklist best you can build is not a list of tasks. It is a structured way of thinking about where systems break and why. The tasks are just the surface expression of that thinking.
