What Machine Learning Exam Questions Actually Test
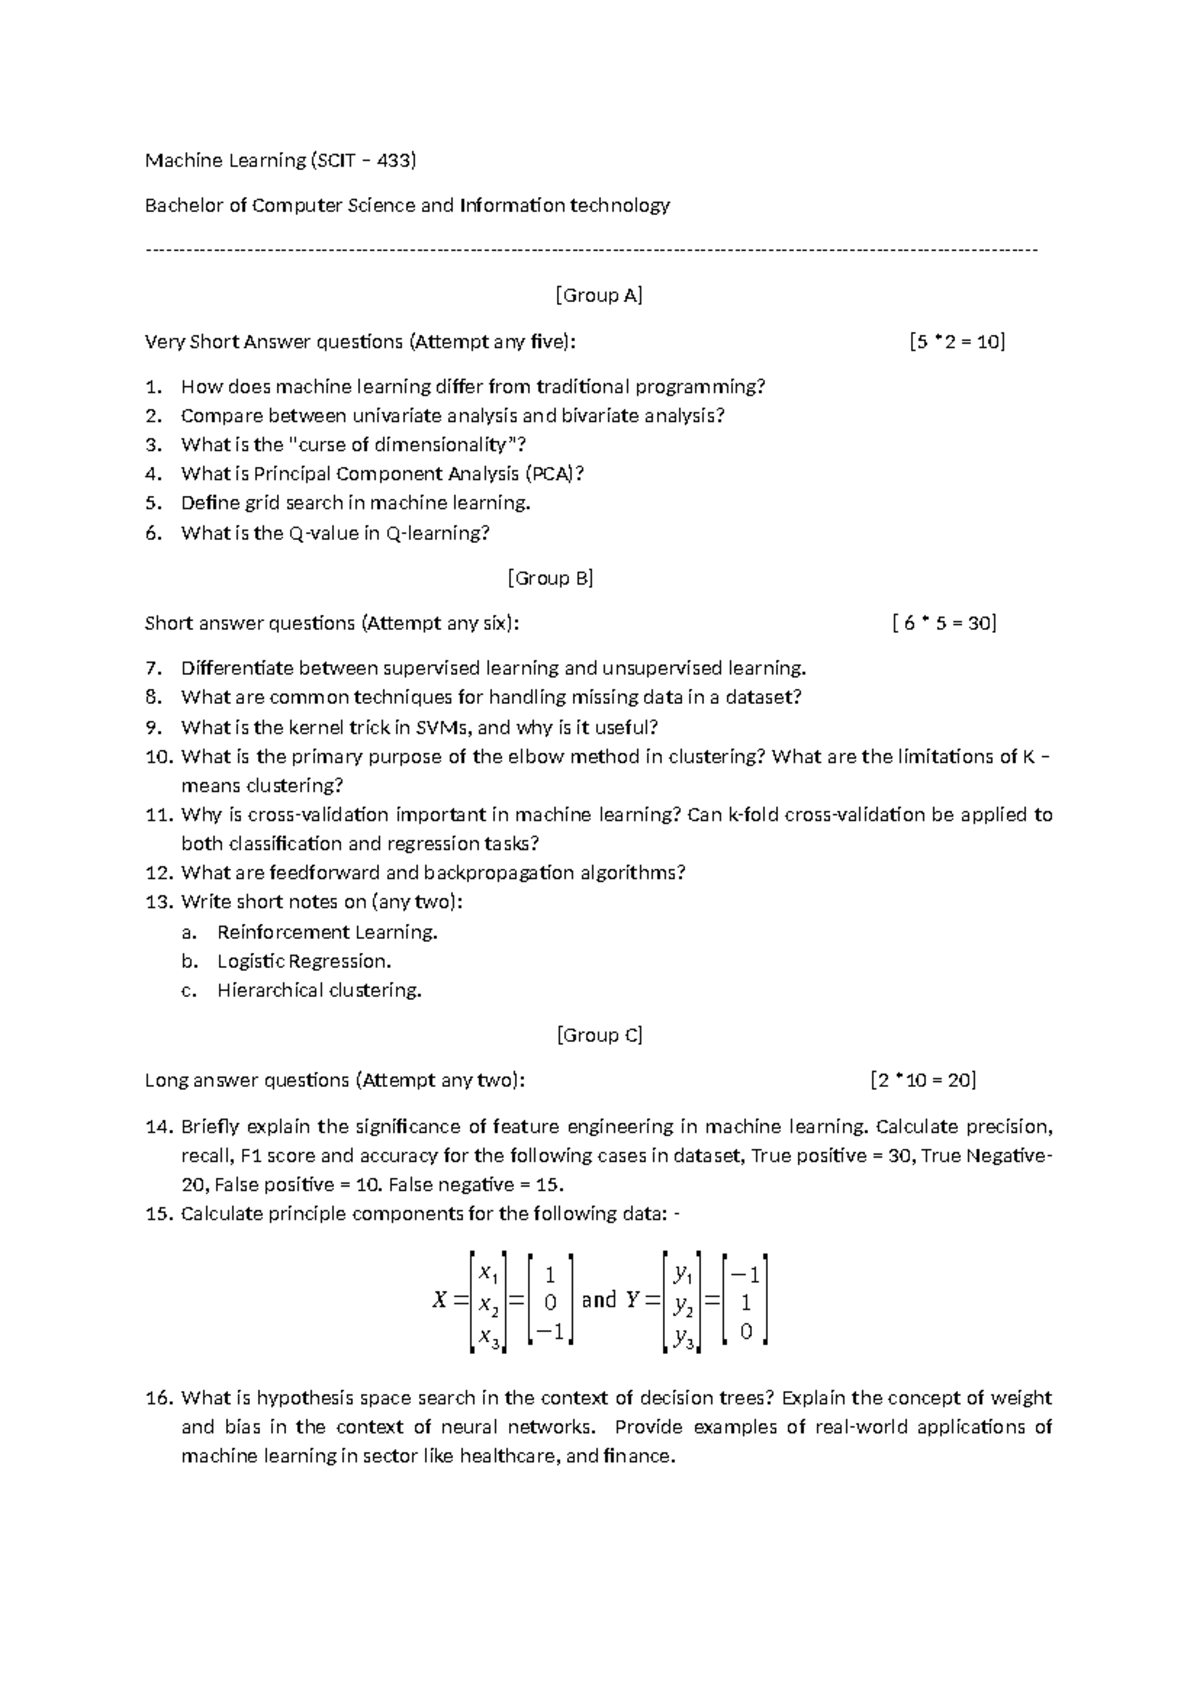
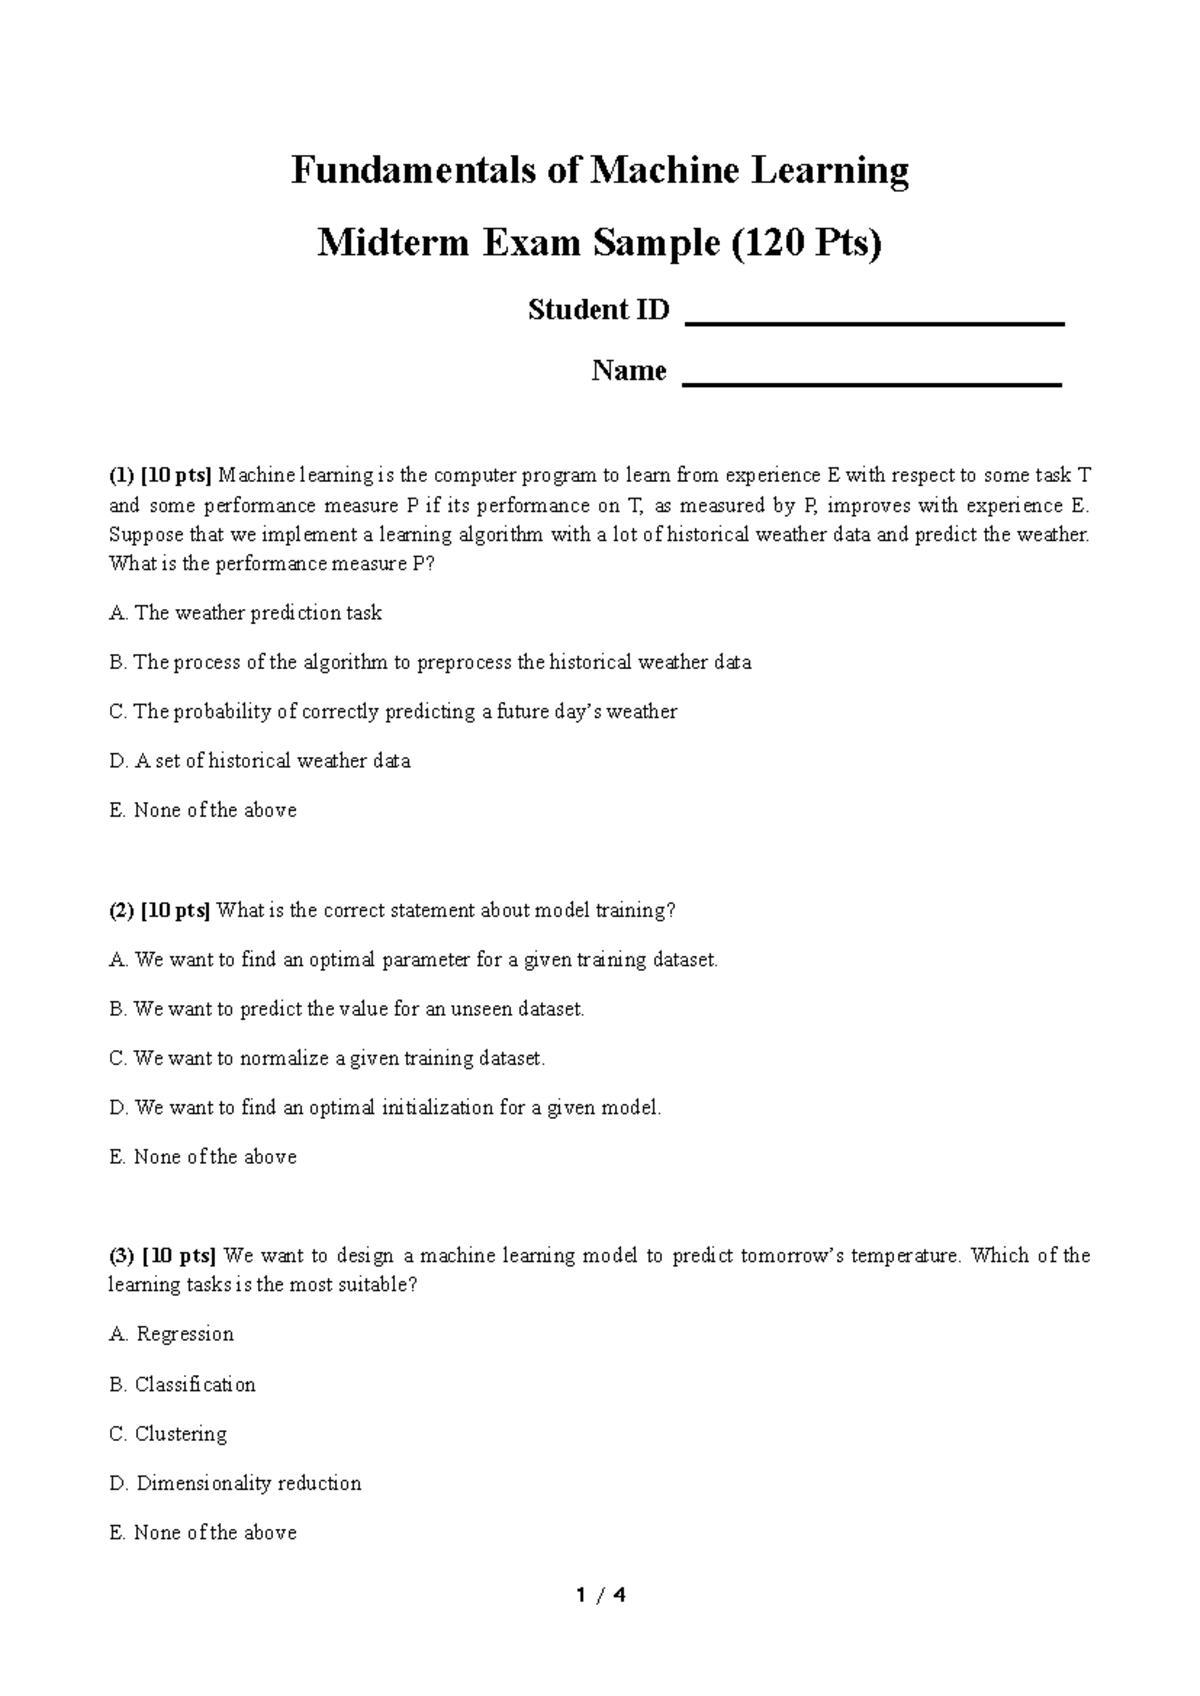
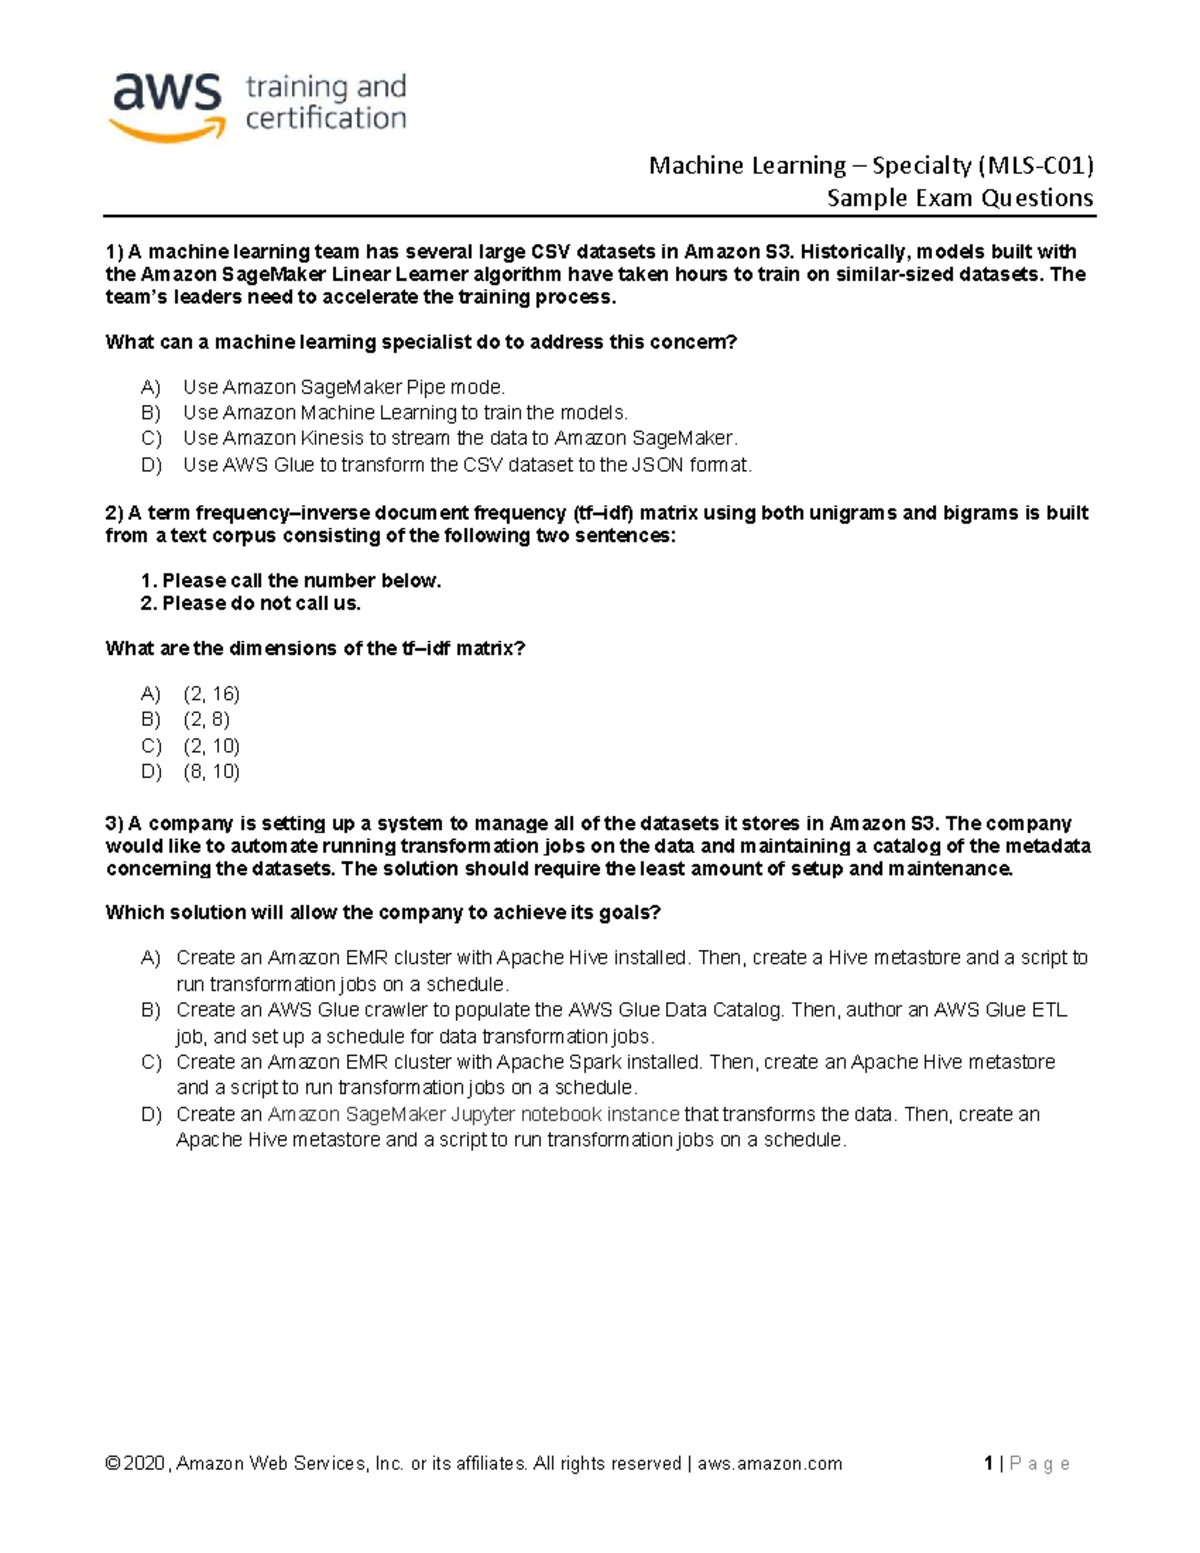
Most ML exams don't test whether you can code a transformer from scratch. They test whether you understand what breaks when something goes wrong, because that is where the actual learning happens. I spent a few years sitting in on grad-level ML finals, and the pattern is always the same.The students who score highest are the ones who can look at a problem statement, identify the hidden constraints, and explain their reasoning out loud. The ones who fail are usually the ones who memorized equations without understanding the underlying mechanics. Here is a breakdown of what to expect. Exams tend to fall into three buckets. There are the conceptual questions that ask you to explain bias-variance tradeoff without any numbers. There are the calculation questions where you compute gradients or likelihoods by hand. And there are the applied questions where you are given a dataset description and asked to pick a model, justify it, and anticipate failure modes. The third type is the hardest, and also the most useful in practice. I remember one exam where the question gave you a binary classification problem with 98% class imbalance and asked you to evaluate a model using accuracy. Most people wrote down accuracy as their metric. I wrote down that accuracy would be meaningless here and proposed weighted F1 with class weights inverted. The grader gave full credit, but more importantly, that exact scenario shows up repeatedly in real data science work.
How to Approach These Questions Under Pressure
Start every problem by writing down what you know and what you need to find. This takes about 30 seconds and prevents about 40 percent of silly mistakes. When you see a question about model selection, immediately ask yourself three things: what is the sample size, what is the noise level, and what is the cost of a false positive versus a false negative. Those three factors determine everything else. For probability questions, keep a sheet of standard distributions memorized with their means and variances. Normal, Poisson, Bernoulli, Binomial, Exponential. You will need them within the first five minutes of the exam. I once saw someone spend twelve minutes deriving the mean of a binomial distribution from first principles when they should have just written the answer and moved on. That kind of mistake costs points you cannot get back. For coding portions, write pseudocode first. Actual syntax errors are worth fewer points than structural logic errors. Professors want to see that you understand the algorithm, not that you remember whether Python uses semicolons. Write the loop, define your variables, show the base case for recursion. That alone usually nets you half the points even if the implementation has bugs.
Common Pitfalls That Cost Students Points
Overfitting explanations are a recurring theme. Students often write "the model memorized the data" and move on. That is technically correct but earns partial credit at best. The better answer specifies how you detected it: training loss decreasing while validation loss plateaus or increases, the gap between the two widening over epochs, and cross-validation scores showing high variance across folds. Naming the diagnostic tool matters more than naming the phenomenon. Another mistake is assuming normalization is always required. It is required for gradient-based methods like SGD and neural networks. It does not help tree-based models at all. Random forests and gradient boosting are invariant to monotonic transformations of features. I have seen students lose points for applying PCA before a random forest and then complaining about interpretability loss, when the real issue was they misunderstood when dimensionality reduction helps versus when it hurts. There is also the regularization trap. Students often assume L2 regularization always improves generalization. It does not when your features are already highly correlated and you have a small dataset. In those cases, Lasso tends to outperform Ridge because it performs feature selection inline. Knowing when to switch penalties is a subtle point that separates decent answers from strong ones.
Get the Full Details
What the Hard Questions Are Really Asking
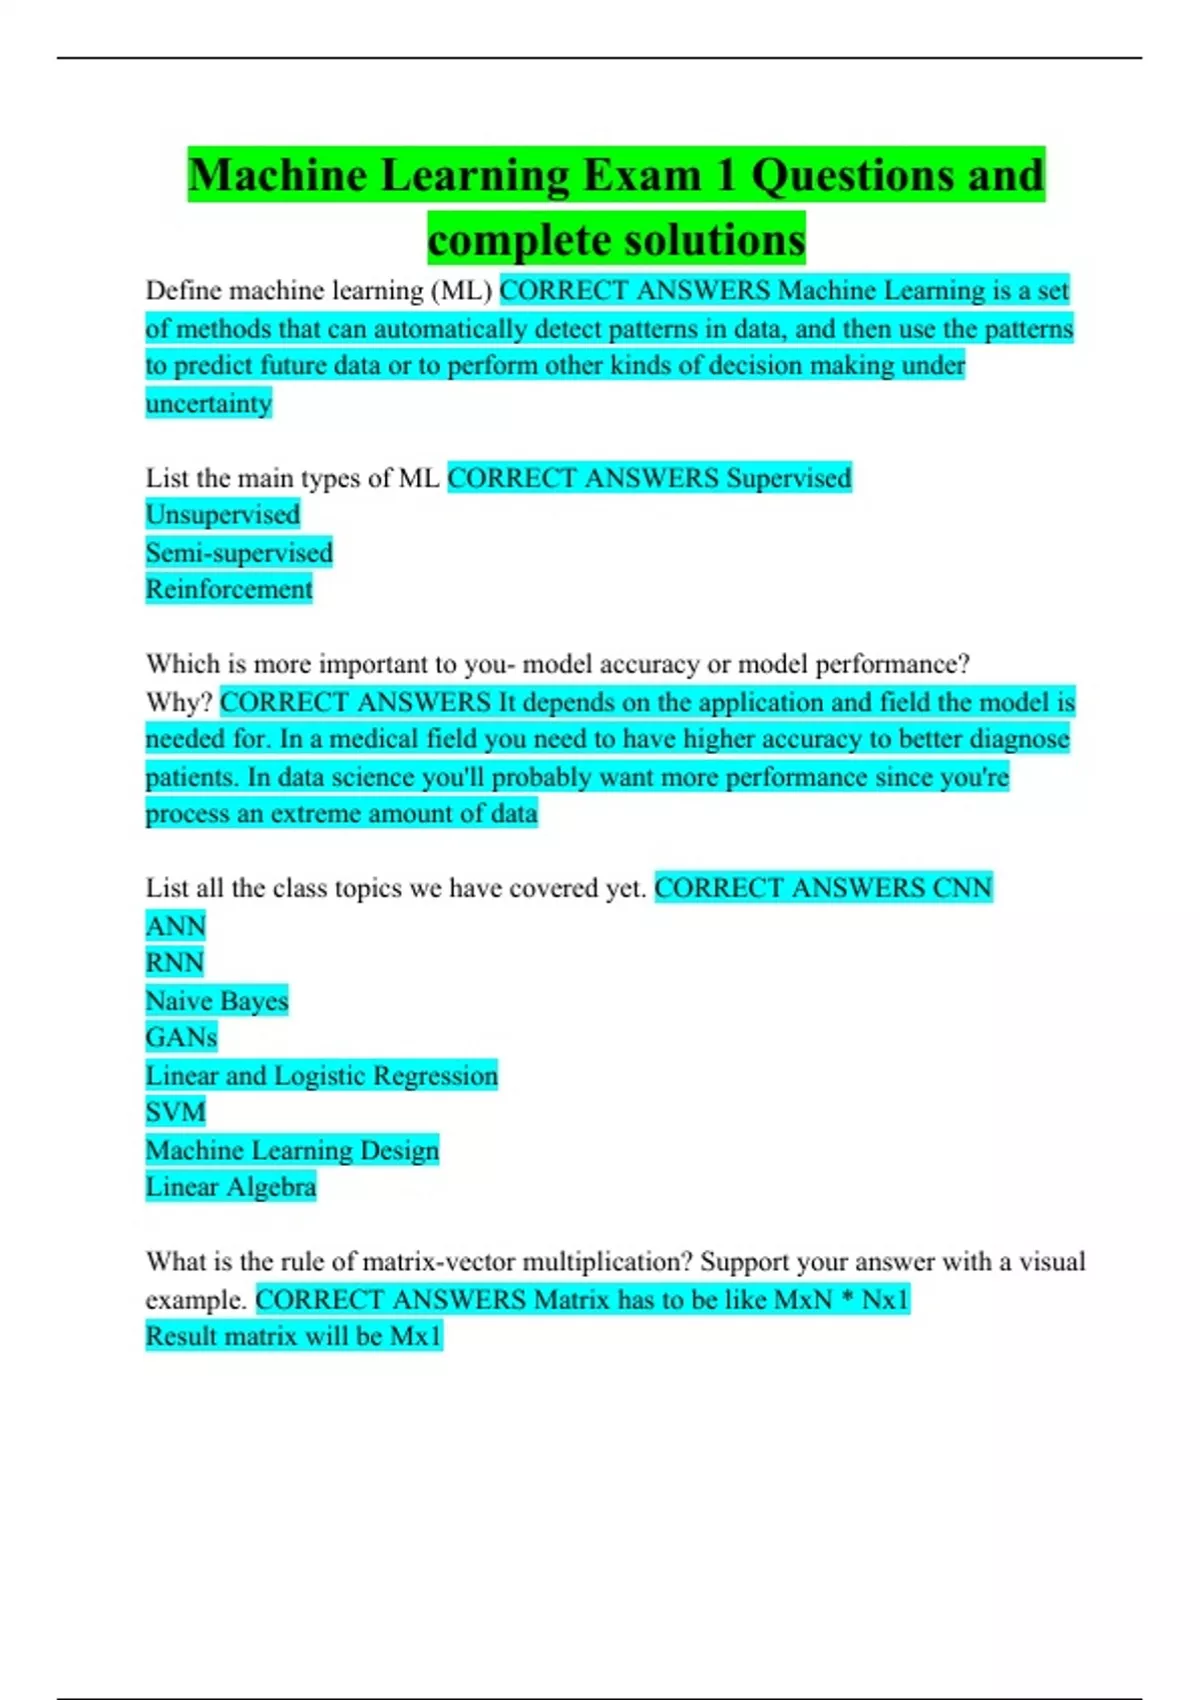
When an exam question seems oddly specific or has some constraint you did not expect, it is usually testing whether you can adapt known methods to unfamiliar situations. I had a midterm where the professor gave us a linear regression problem with heteroscedastic errors and asked for the OLS estimator. The standard answer assumes homoscedasticity, so the trick was recognizing that OLS is still unbiased but no longer efficient, and the correct fix is weighted least squares with inverse variance weights. Questions about evaluation metrics often hide similar traps. Ask yourself whether the metric you chose aligns with the actual business objective. Precision-recall curves matter when classes are imbalanced. ROC AUC can be misleadingly optimistic in those same scenarios. If the exam gives you a fraud detection dataset with 0.1 percent positive rate, using ROC AUC as your primary metric is a red flag answer. Switch to PR AUC or log loss and explain why.
Practical Study Strategy That Actually Works
Do not just re-read your notes. Work through past papers under timed conditions. Set a timer for two-thirds of the actual exam duration and practice with no resources open. This forces you to retrieve information from memory instead of recognizing it on the page, which is a completely different cognitive task. I cut my practice time from about six hours per week to three hours once I switched to this method, and my scores improved by roughly a letter grade. Focus your review on areas where you consistently make errors, not on topics you already understand well. If you keep losing points on probabilistic reasoning, spend one evening working through conditional probability and Bayes theorem problems until the patterns become automatic. Then move on. Re-reading chapters you already know is the most common form of unproductive studying. For the theoretical portions, build a one-page summary sheet with key formulas, assumptions, and failure conditions for each major algorithm. Not the proofs, the conditions. When does OLS fail? When does K-means converge slowly? When does naive Bayes perform surprisingly well despite its independence assumption? That last one actually happens often with text classification because the features are conditionally independent in a way that approximates reality well enough.
The Unspoken Reality About These Exams
Most ML exams are not designed to be impossible. They are designed to separate people who understand the material from people who have seen the right words before. The difference is usually small but measurable. Understanding means you can reconstruct the answer from first principles if you forget it. Recognition means you can only reproduce what you memorized, and the moment the question changes form slightly, you are stuck. If you want to build that kind of understanding, work through derivations yourself. Compute the gradient of logistic regression by hand at least once. Derive the EM algorithm for Gaussian mixtures. It will take you an afternoon, maybe two, and it will make every subsequent exam question feel easier than it actually is. The derivations are not busywork. They are the difference between knowing that backpropagation works and understanding why it sometimes fails in deep networks. That failure mode deserves mention here. Vanishing gradients in deep networks are not just a textbook fact. I encountered this during a project where a five-layer network trained on sequential data would learn the first layer fine but the later layers would barely update. The workaround was switching from sigmoid activations to ReLU and using batch normalization, which stabilized the gradient flow. Seeing that happen in practice made the exam question about gradient vanishing feel almost trivial compared to debugging it in production.