Getting Started With ML Without Wasting Six Months
You do not need a computer science degree to start using machine learning. You need a problem you actually care about solving, a laptop that will not catch fire when you ask it to do something slightly ambitious, and about three weeks of your life to learn the basics. That is it. The rest is noise. I have watched people spend four months reading textbooks about backpropagation before they ever train a model that does something useful. It is a waste of time. You learn the math when you need it. You do not learn it ahead of time like it is some prerequisite for being allowed to have opinions about neural networks.
Machine Learning For Beginners Simple
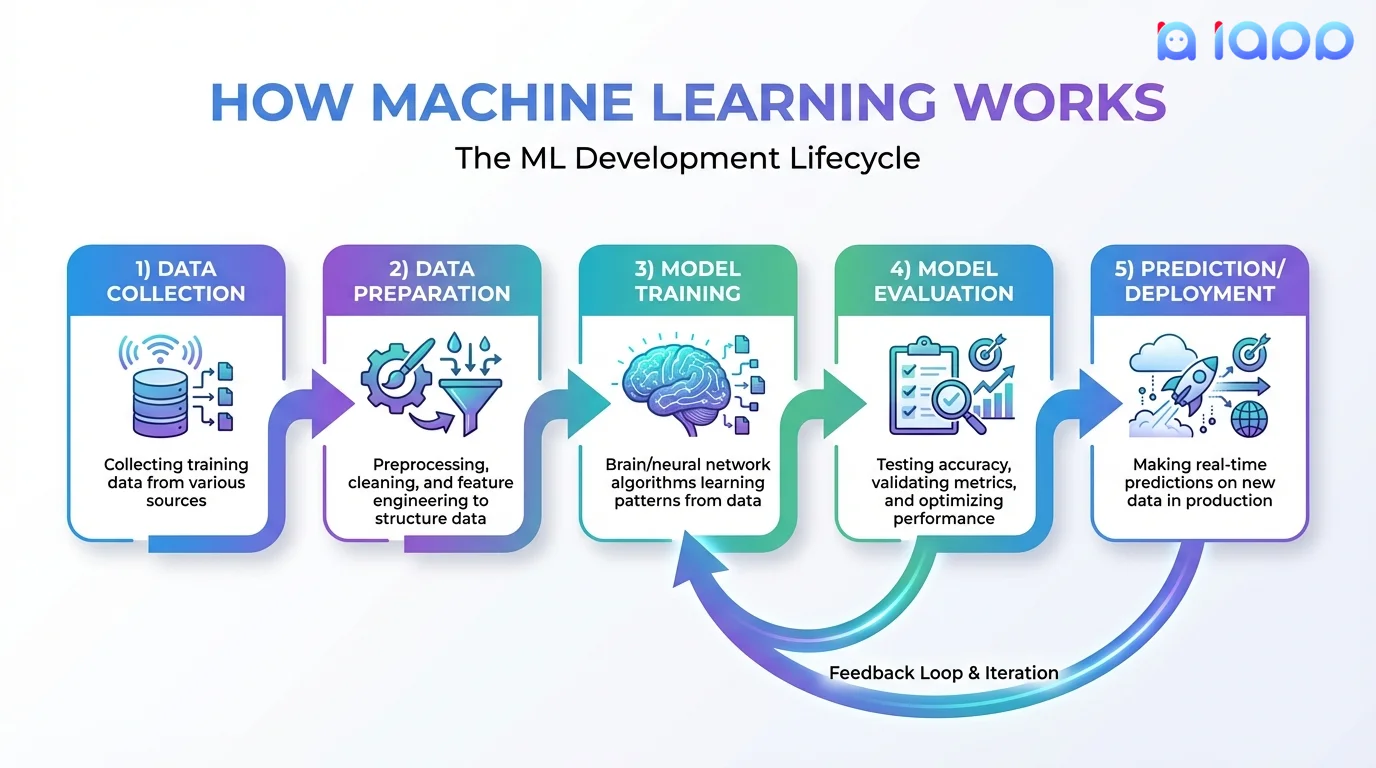
Start with scikit-learn. It is the default starting point for most practical work, and it has been the default for over a decade because it works. You install it with pip, you load some data, you pick a model, you call fit, and then you call predict. That is the entire loop. Everything else you read about is refinement. The most common mistake beginners make is trying to build something complex before they understand why their simple version is failing. I had a client once who spent three weeks tuning a random forest on a dataset with 800 features and a hundred rows of data. The model achieved 99% accuracy on the training set and 52% on the test set. Classic overfitting, but he could not see it because he was focused on accuracy alone. Switching to cross-validation and looking at the precision-recall curve showed the problem immediately. Feature selection using recursive feature elimination brought test accuracy up to 81%. That was the whole thing. Five lines of additional code. Data preparation is where most projects die. You will spend roughly 60 to 70 percent of your time cleaning and organizing data before you even touch a model. This is not a suggestion. It is what happens. If your data has missing values, you need to decide whether to impute them, drop the rows, or use a model that handles them natively. If your categories are inconsistent — say "NY", "n.y.", and "New York" all appearing in the same column — your model will treat them as entirely different things. I wrote a quick deduplication script using fuzzy string matching once that caught about forty distinct variants of city names in what I thought was a clean dataset. Forty variants for one column. It took me two hours to find and fix. Would have taken me six months to debug the downstream effects.
Feature engineering matters more than model selection for small datasets. On a dataset with fewer than ten thousand rows, a well-chosen logistic regression will outperform a randomly configured neural network every single time. Neural networks need data. Lots of it. If you have a small dataset and you jump straight to deep learning, you are not being sophisticated. You are just fighting your own constraints. Here is something most beginners miss: normalization and standardization are not optional steps you skip to save time. If you feed raw unscaled features into a model like support vector machines or gradient boosting, the features with larger ranges will dominate the learning process purely because of their scale, not because they are more informative. StandardScaler in scikit-learn takes about thirty seconds to run on a typical dataset and can improve performance by ten to twenty percentage points on certain algorithms. It is one of the highest-return operations you will do. When you are ready to move beyond tabular data, start with image classification using a pre-trained model rather than building a CNN from scratch. Transfer learning lets you take a model that was already trained on millions of images — ResNet, EfficientNet, whatever is current — and retrain just the final layers on your own small dataset. I used this approach to build a model that classified types of industrial defects from photos. The original model was trained on ImageNet with over a million images. My dataset had about eight hundred labeled images. We fine-tuned EfficientNet-B0 and got to around 94% accuracy after two days of work. Training that same architecture from scratch on eight hundred images would have produced garbage. Period.
Get the Full Details

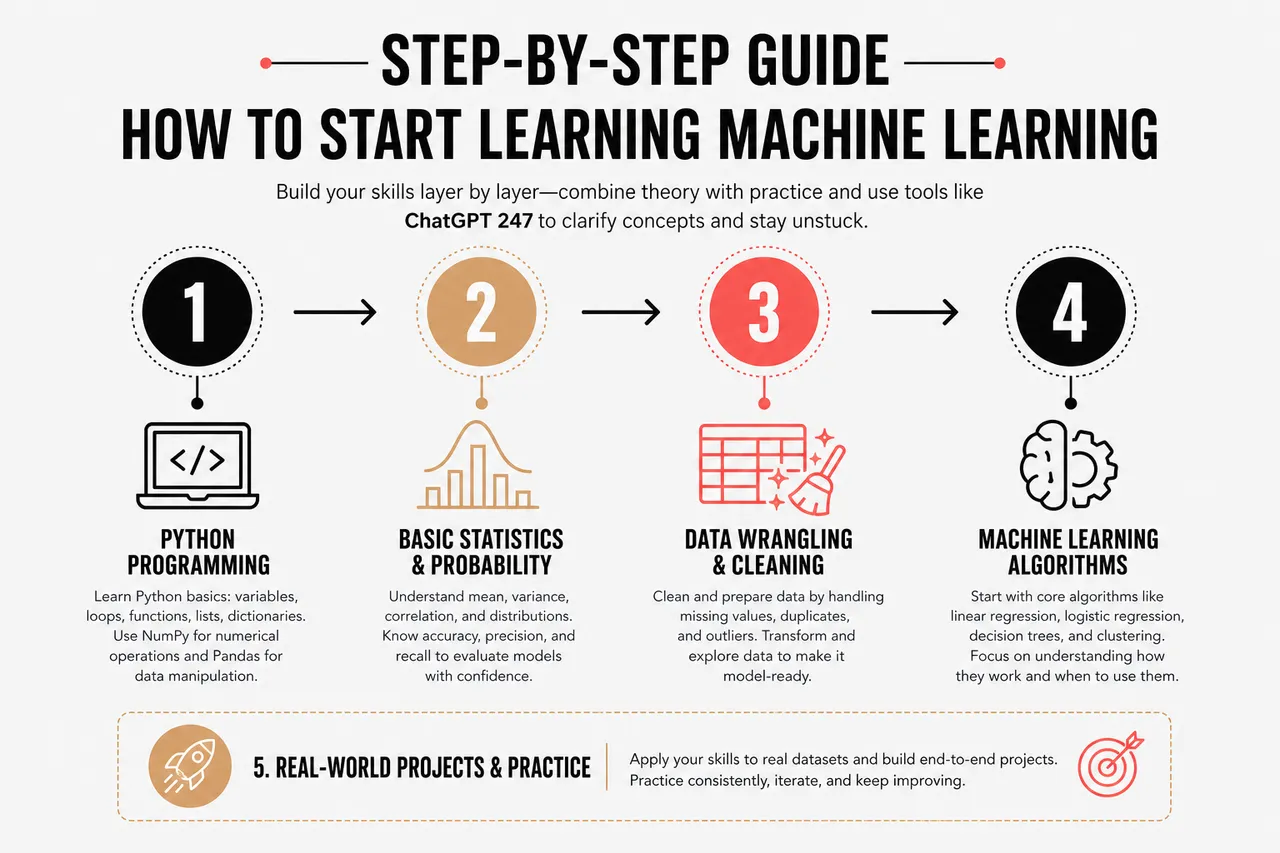
The biggest bottleneck for beginners is not understanding the algorithms. It is knowing when a model is lying to you. A model can look great on your validation set and completely fall apart in production. This happens because your data is not representative of the real world. Maybe your training data only contains images taken during the day, and your production data includes nighttime photos. The model never saw the nighttime variation, so it fails when it encounters it. Always validate with data that looks as much like your real deployment data as possible. Train on daytime photos. Test on nighttime photos if that is what you will actually deploy on. For those just starting out, I recommend this path: get comfortable loading and exploring data with pandas, learn the basic scikit-learn models (logistic regression, random forest, gradient boosting, KNN), understand what train-test split and cross-validation actually do, and then specialize based on what kind of problem you keep running into. Do not try to learn everything at once. Pick one type of data — tabular, text, or images — and go deep on that before branching out. There are also free resources that are genuinely useful. The scikit-learn documentation has some of the clearest examples in all of software. Kaggle has starter notebooks for nearly every common problem type. You do not need a paid course. You need to open a notebook and break things until you understand why they broke.
If you run into problems, stack overflow and the official documentation will solve most of them. Community forums like the scikit-learn mailing list and the r/machinelearning subreddit are also decent, though the quality varies. I have found that asking specific questions with code and error traces gets you answers in hours. Asking vague questions like "how do I learn ML" gets you lectures from strangers who think they know better than you. The field moves fast. New architectures and techniques appear constantly. For beginners, this is actually helpful because it means the barrier to entry keeps dropping. Tools like Hugging Face Transformers have made NLP accessible without writing a single line of custom training code. You can load a pre-trained model, pass in your text, and get results in under ten lines. The tradeoff is that you are relying on someone else's work, which is fine until it is not. When your model starts making strange predictions on edge cases, you will need to understand what is happening under the hood. That is when you go back and learn the fundamentals. One more thing that will save you frustration: set up a proper experiment tracking system early. Even if it is just a spreadsheet where you log the model, the hyperparameters, the dataset version, and the results, you will thank yourself later. I have lost count of how many times I came back to a project after a month and had no idea which configuration produced the best result. Version control your data and your code. Use something like DVC for data versioning if your datasets are large. It adds a small overhead upfront and prevents enormous headaches later.