Why the usual textbooks get credit risk wrong
Most people learning to build risk models start with the textbook approach: grab a Kaggle dataset, train a logistic regression, celebrate when AUC hits 0.75. That is not how it works in production. The gap between a notebook that runs and a model that actually gets used to set capital reserves is where people burn through six months and five performance reviews. I spent three years building credit risk scorecards and fraud detection systems for a mid-tier lender. We had a model that scored well out of sample but failed catastrophically on a very specific edge case. The problem was not the algorithm. It was that we were using customer income as a raw feature without accounting for the fact that gig economy workers reported highly variable monthly earnings. The model penalized these applicants because the training data had smooth, predictable income patterns from traditional employees. We had to build a volatility adjustment factor based on standard deviation of their last twelve months of deposits. Without it, we were rejecting perfectly creditworthy people while accepting stable borrowers who happened to have smoother paycheck patterns.
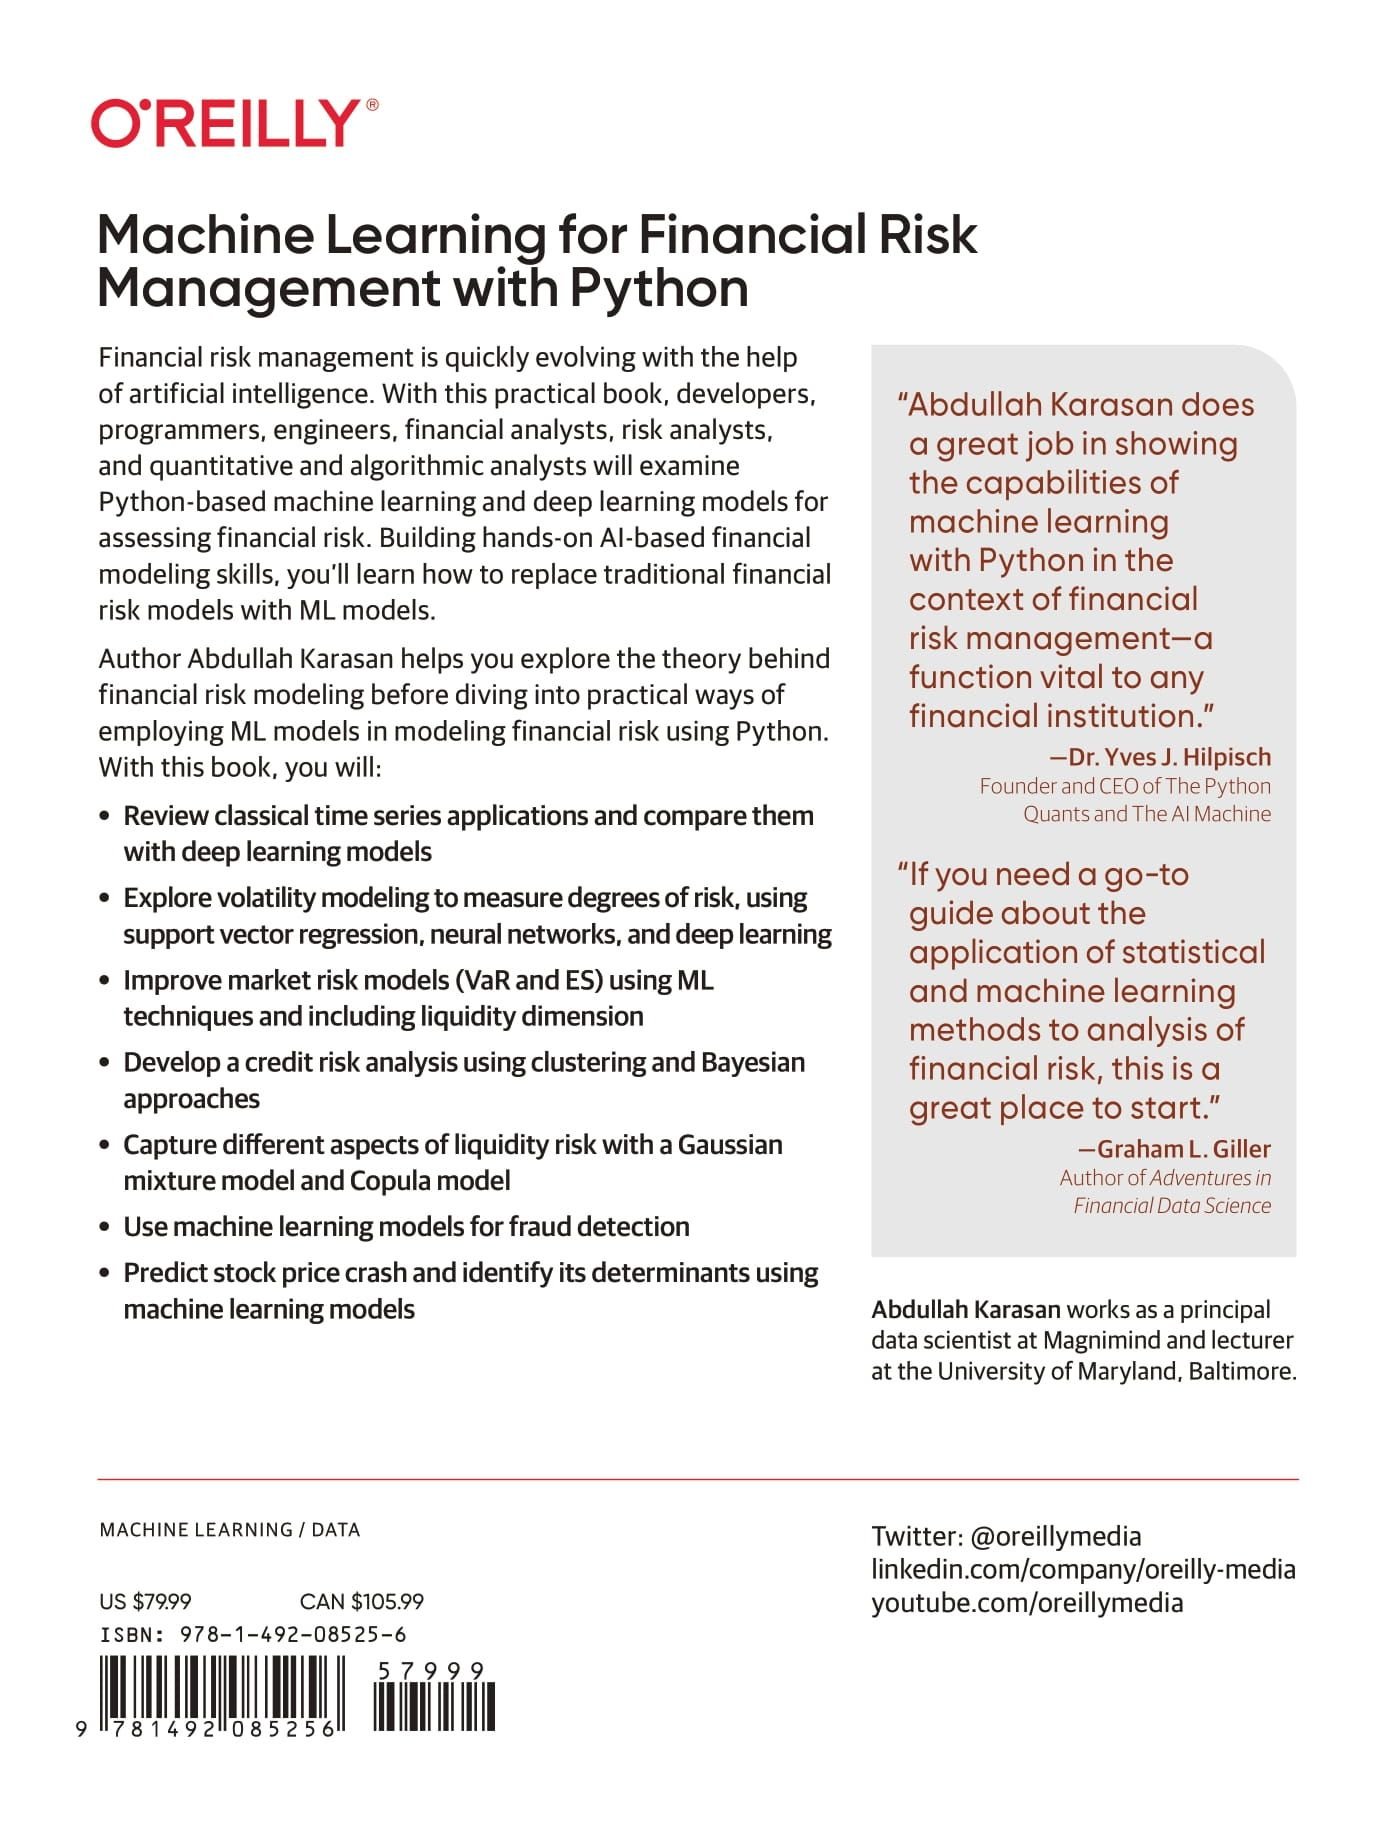
Machine Learning For Financial Risk Management With Python
The practical workflow looks like this. You start by ingesting raw transaction and demographic data into a pandas DataFrame. Then you clean it, handle missing values, and create engineered features that capture the actual behavior you care about. Payment velocity matters more than raw balance. Debt-to-income ratio over the trailing six months is usually better than the current snapshot because it smooths out temporary spikes. You encode categorical variables carefully because one-hot encoding high-cardinality fields like merchant categories can blow up your memory footprint and introduce collinearity. I recommend using scikit-learn for the modeling pipeline. XGBoost or LightGBM are standard choices for tabular risk data because they handle nonlinear relationships and interaction effects better than logistic regression without requiring extensive feature engineering. But here is the thing most tutorials do not tell you. You should not tune hyperparameters with grid search. Random search with early stopping typically finds a comparable model in a fraction of the time. I usually run fifty random samples from a reasonable distribution and pick the top three by validation score. When you move to validation, do not use a simple random split. Financial data has temporal structure. You need to use time-based cross-validation where the training window always precedes the validation window. If you mix future data into your training set, you get inflated performance metrics that collapse the moment the model touches production. We learned this the hard way when our initial backtest showed a Gini coefficient of 0.42 and the live model delivered 0.28 within two quarters.
Feature importance alone is not enough for risk models. Regulators and internal audit teams want to understand why the model rejects an applicant. You should use SHAP values to generate per-predictor explanations. This gives you both global interpretability and local justification. The tradeoff is that SHAP computation can be slow on large datasets. We found that calculating exact SHAP values for our 500,000-row dataset took about four hours. Switching to TreeSHAP for LightGBM reduced that to roughly twelve minutes. Worth the switch. Model monitoring is where most implementations fail. A model that performs well on historical data will drift as consumer behavior changes. You should track PSI, or Population Stability Index, on a monthly basis across your key features. A PSI above 0.1 indicates meaningful shift and above 0.25 means you should retrain. We also track stability of the score distribution because a model that maintains the same discrimination but shifts its calibration is still usable. The opposite is a model that drifts in AUC while keeping the same mean score, which is much harder to detect. Here is a counter-intuitive point. Sometimes simpler models outperform complex ones in risk management. A well-specified logistic regression with monotonic constraints often passes regulatory scrutiny better than a black box ensemble because you can prove the directionality of each feature. If a regulator asks why increasing debt-to-income ratio increases predicted default probability, a logistic model gives you a clear coefficient. A gradient boosting machine gives you SHAP summaries that are harder to defend in a formal audit. I usually build both and compare them. The logistic regression serves as the documented baseline, while the ensemble improves accuracy by about two to four percentage points in AUC.
Get the Full Details
Another common pitfall is survivorship bias in your training data. If you only train on accepted applicants, you have no information about why rejected applicants would have defaulted or not. This is particularly damaging for threshold tuning because your model never sees the cases that sit near the rejection boundary. The workaround is to use incomplete classification methods or approximate the population of rejected applicants using propensity scoring. It adds complexity but reduces selection bias significantly. Deployment requires more than just saving the model object. You need versioned pipelines, feature store integration, and automated retraining triggers. I usually containerize the scoring logic with FastAPI for low-latency inference and use Airflow or Prefect for orchestration. The model artifacts go into S3 with metadata about training date, feature set version, and validation metrics. Without this discipline, you end up with five different model versions running in production and no way to know which one the system actually used last Tuesday. The Python ecosystem has good tools but no single framework handles everything. Here is what a typical stack looks like. Pandas and NumPy for data manipulation, Polars if you need faster processing on large datasets. Scikit-learn for preprocessing and simpler models. LightGBM or XGBoost for the main classifier. SHAP for interpretability. MLflow for experiment tracking and model registry. Great Expectations for data quality validation before training. Each of these tools has a learning curve but the combination is now standard across most financial institutions.
If you are starting from scratch, begin with a small dataset and a logistic regression to establish a baseline. Get the feature engineering pipeline working cleanly before adding complexity. Most failures happen at the data quality stage, not the modeling stage. A single badly encoded feature can destroy model performance more effectively than any suboptimal algorithm choice. Spend most of your time on data validation and feature definition. That is where the actual work happens.
What to watch out for
Data leakage is the silent killer. If your engineering pipeline includes any operation that uses future information, such as rolling statistics that look ahead or target encoding computed on the full dataset, your model will appear to perform excellently in testing and fail in production. Always compute encodings and transformations inside cross-validation folds to prevent this. Coverage bias matters too. If your training data represents only a narrow segment of applicants, the model will perform poorly on demographics that were underrepresented. We found that our initial model had significantly worse calibration for first-time borrowers compared to repeat customers. The fix was to oversample the minority group during training and adjust the decision threshold separately for each segment. Computational cost increases non-linearly as you add features. A model with fifty features might train in minutes, but one with two thousand engineered features can take hours on the same hardware. Feature selection is not optional at scale. Use mutual information scores or recursive feature elimination to trim the set before final training. We typically end up with around eighty to one hundred features for our production models after this step.
There is no universal solution. If your institution has strict interpretability requirements, lean toward simpler models with strong documentation. If accuracy is the primary constraint and you have the infrastructure to support it, ensemble methods with SHAP explanations work well. The best approach depends on your regulatory environment, team expertise, and computational resources. Choose deliberately rather than following the trend.