Why ML Fails Most Chemistry Projects Before They Start
Most people try to throw a random forest at a molecular property dataset and wonder why their r-squared looks like garbage. The issue is rarely the algorithm. It is the way the data was prepared, how the features were engineered, and whether anyone bothered to think about what the model is actually being asked to predict. I spent three years building models for reaction yield prediction, solubility, and toxicity screening across several labs. The first six months were basically just me deleting code and going back to square one after realizing every initial success was overfit to noise. That pain taught me more than any tutorial ever did.Machine Learning In Chemistry: What It Actually Means
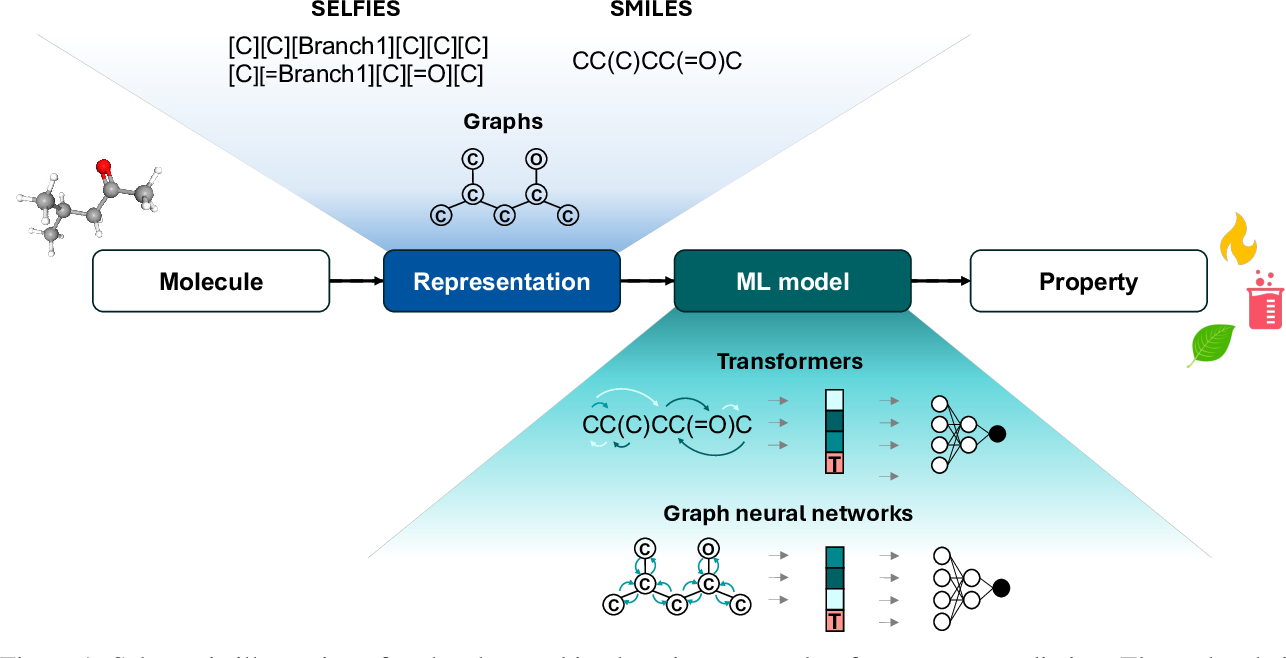
Machine Learning In Chemistry is not magic. It is pattern recognition applied to numerical representations of molecules, reactions, or experimental conditions. You take chemical structures, convert them into something a computer can process, train a model to find relationships between those representations and some target property, and then hope it generalizes to new data. The whole pipeline breaks if any single piece is wrong. And in chemistry, that happens constantly. Molecules are complex. Small errors in SMILES strings, tautomers, or protonation states can destroy your entire dataset before training even begins.
Feature Representation Matters More Than Your Algorithm
Beginners obsess over choosing between XGBoost, neural networks, and Gaussian processes. Veterans spend their time making sure the molecular descriptors are correct. There are two main ways to represent molecules. The first is using handcrafted descriptors: molecular weight, logP, topological polar surface area, E-state indices, and dozens of others. RDKit can generate over a hundred of these in seconds. The second approach uses learned fingerprints or graph neural networks, where the model figures out which structural features matter without you telling it explicitly. SchNet, DimeNet++, and EGNN fall into this category. Handcrafted descriptors work well when you have limited data and need interpretability. Graph neural networks tend to outperform them when you have thousands or millions of labeled examples, but they require significantly more computational resources and careful hyperparameter tuning.
I ran into a specific problem early on where my GNN was consistently predicting nearly identical values for entirely different molecules. The training loss was going down fine, but predictions on the test set were useless. The issue turned out to be that my graph construction was dropping hydrogen atoms by default, and my target property depended heavily on hydrogen bonding patterns. Adding explicit hydrogens and rebuilding the graph solved it immediately. The model went from an r-squared of 0.12 to 0.78 on the same dataset. That one detail cost me two weeks of debugging before I figured it out.
Get the Full Details

Data Quality Is the Bottleneck Nobody Talks About
Chemistry datasets are notoriously messy. You will find duplicate entries with slightly different names, measurements taken under inconsistent conditions, and whole columns filled with NaN values that someone just decided to leave in. A single mislabeled entry in a toxicity dataset can shift your model's predictions enough to mislead an entire research direction. Before training anything, clean your data. Check for duplicates using canonical SMILES. Verify that molecular formulas match the structures. Look for outliers using simple statistical methods or visualization. Filter out entries where the experimental conditions are ambiguous or incomplete. This step usually takes longer than the actual model training. I budget one week of cleaning for every one week of modeling. Sometimes more.
Validation Strategies Specific to Chemistry
Random k-fold cross-validation is the default in most machine learning courses, but it is almost always wrong for chemistry problems. Molecules that look similar in descriptor space are often chemically similar, and splitting them randomly between train and test sets gives you artificially inflated performance numbers. Your model is essentially memorizing rather than learning. Instead, use scaffold-based splitting. Group molecules by Bemis-Murcko scaffolds and ensure that entire scaffolds appear in either the training set or the test set, never both. This forces your model to generalize to new chemical structures rather than interpolating within familiar ones. The performance numbers will drop, sometimes dramatically, but they will be honest. Another approach is temporal splitting, useful when you have access to time-stamped data. Train on older publications and test on newer ones. This simulates the real-world scenario where you want your model to predict properties of newly synthesized compounds.
When ML Works and When It Does Not
Prediction tasks that stay within the chemical space of your training data tend to work reasonably well. If your training set covers compounds with molecular weights between 200 and 500 Da, logP values from -2 to 6, and common functional groups, predictions for similar molecules are usually trustworthy. Extrapolation is where things fall apart. Ask your model to predict the solubility of a organometallic compound when your training data only contains organic small molecules, and it will give you a number. That number will be wrong, and you will not know how wrong without experimental validation. The model has no mechanism to say "I have no idea" in a reliable way. Uncertainty quantification methods like ensembles, Monte Carlo dropout, or conformal prediction can help flag low-confidence predictions, but they are not foolproof. I still validate questionable predictions experimentally whenever possible.
Practical Tools and Getting Started
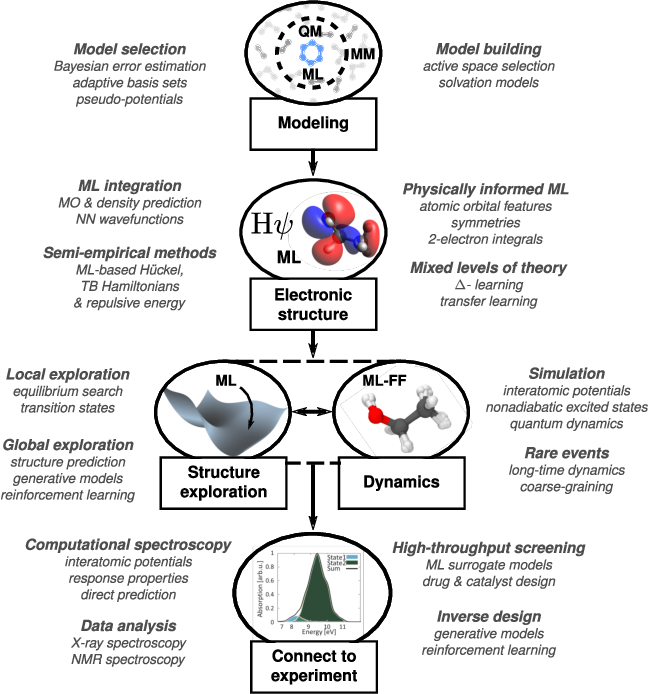
If you are new to this, start simple. Use RDKit for molecular preprocessing and descriptor calculation. Scikit-learn has everything you need for baseline models. For graph neural networks, try PyTorch Geometric or DeepChem, which are built specifically for molecular data. Don't skip the baseline. Train a simple model using basic descriptors before reaching for a deep learning architecture. You would be surprised how often a random forest with Morgan fingerprints outperforms a complex GNN on small datasets, and you will learn things about your data along the way that a black box model will hide from you. Also, keep your pipelines modular. Write functions for data loading, cleaning, descriptor calculation, splitting, training, and evaluation. Chemistry projects tend to grow messy fast, and refactoring a tangled script after three months is miserable.
The Reality of Doing Machine Learning In Chemistry Day to Day
The work is mostly data wrangling, debugging strange failures, and convincing yourself that a 0.03 improvement in r-squared is actually meaningful. The exciting parts exist, but they are rare. Most of the value comes from knowing when not to trust the model and when to go back to the drawing board. Chemistry is hard. Molecules do not obey simple mathematical relationships the way tabular data sometimes does. But the field has moved far beyond hand-curated qualitative rules, and the models that work are the ones built by people who respect both the chemistry and the data.