Why Your ML Pipeline Logs Matter More Than Your Model Architecture
I've been spending a lot of time recently dealing with production ML systems that keep failing in ways that don't show up in any dashboard. You train a model, it looks fine on validation, then suddenly it starts producing garbage predictions at 2 AM and nobody knows why until someone notices the error rate has spiked. The answer is usually buried somewhere in the logs, but finding it requires actual effort. It's the process of collecting, structuring, and examining the output data that your ML system generates during training, inference, and monitoring. Not the kind of logs you write yourself with print statements, but the structured telemetry that exists around model performance—loss curves, latency distributions, feature drift metrics, pipeline step durations, GPU utilization snapshots, and error traces. Anyone who's debugged a production model at 11 PM knows that the standard monitoring tools only tell you half the story. You need to connect the dots between what happened in the training data, what the model actually predicted, and what the infrastructure was doing at the same time. That connection lives in the logs. Most people treat logs as a last resort when everything else has failed. That's backwards.
The Tooling Stack I Actually Use
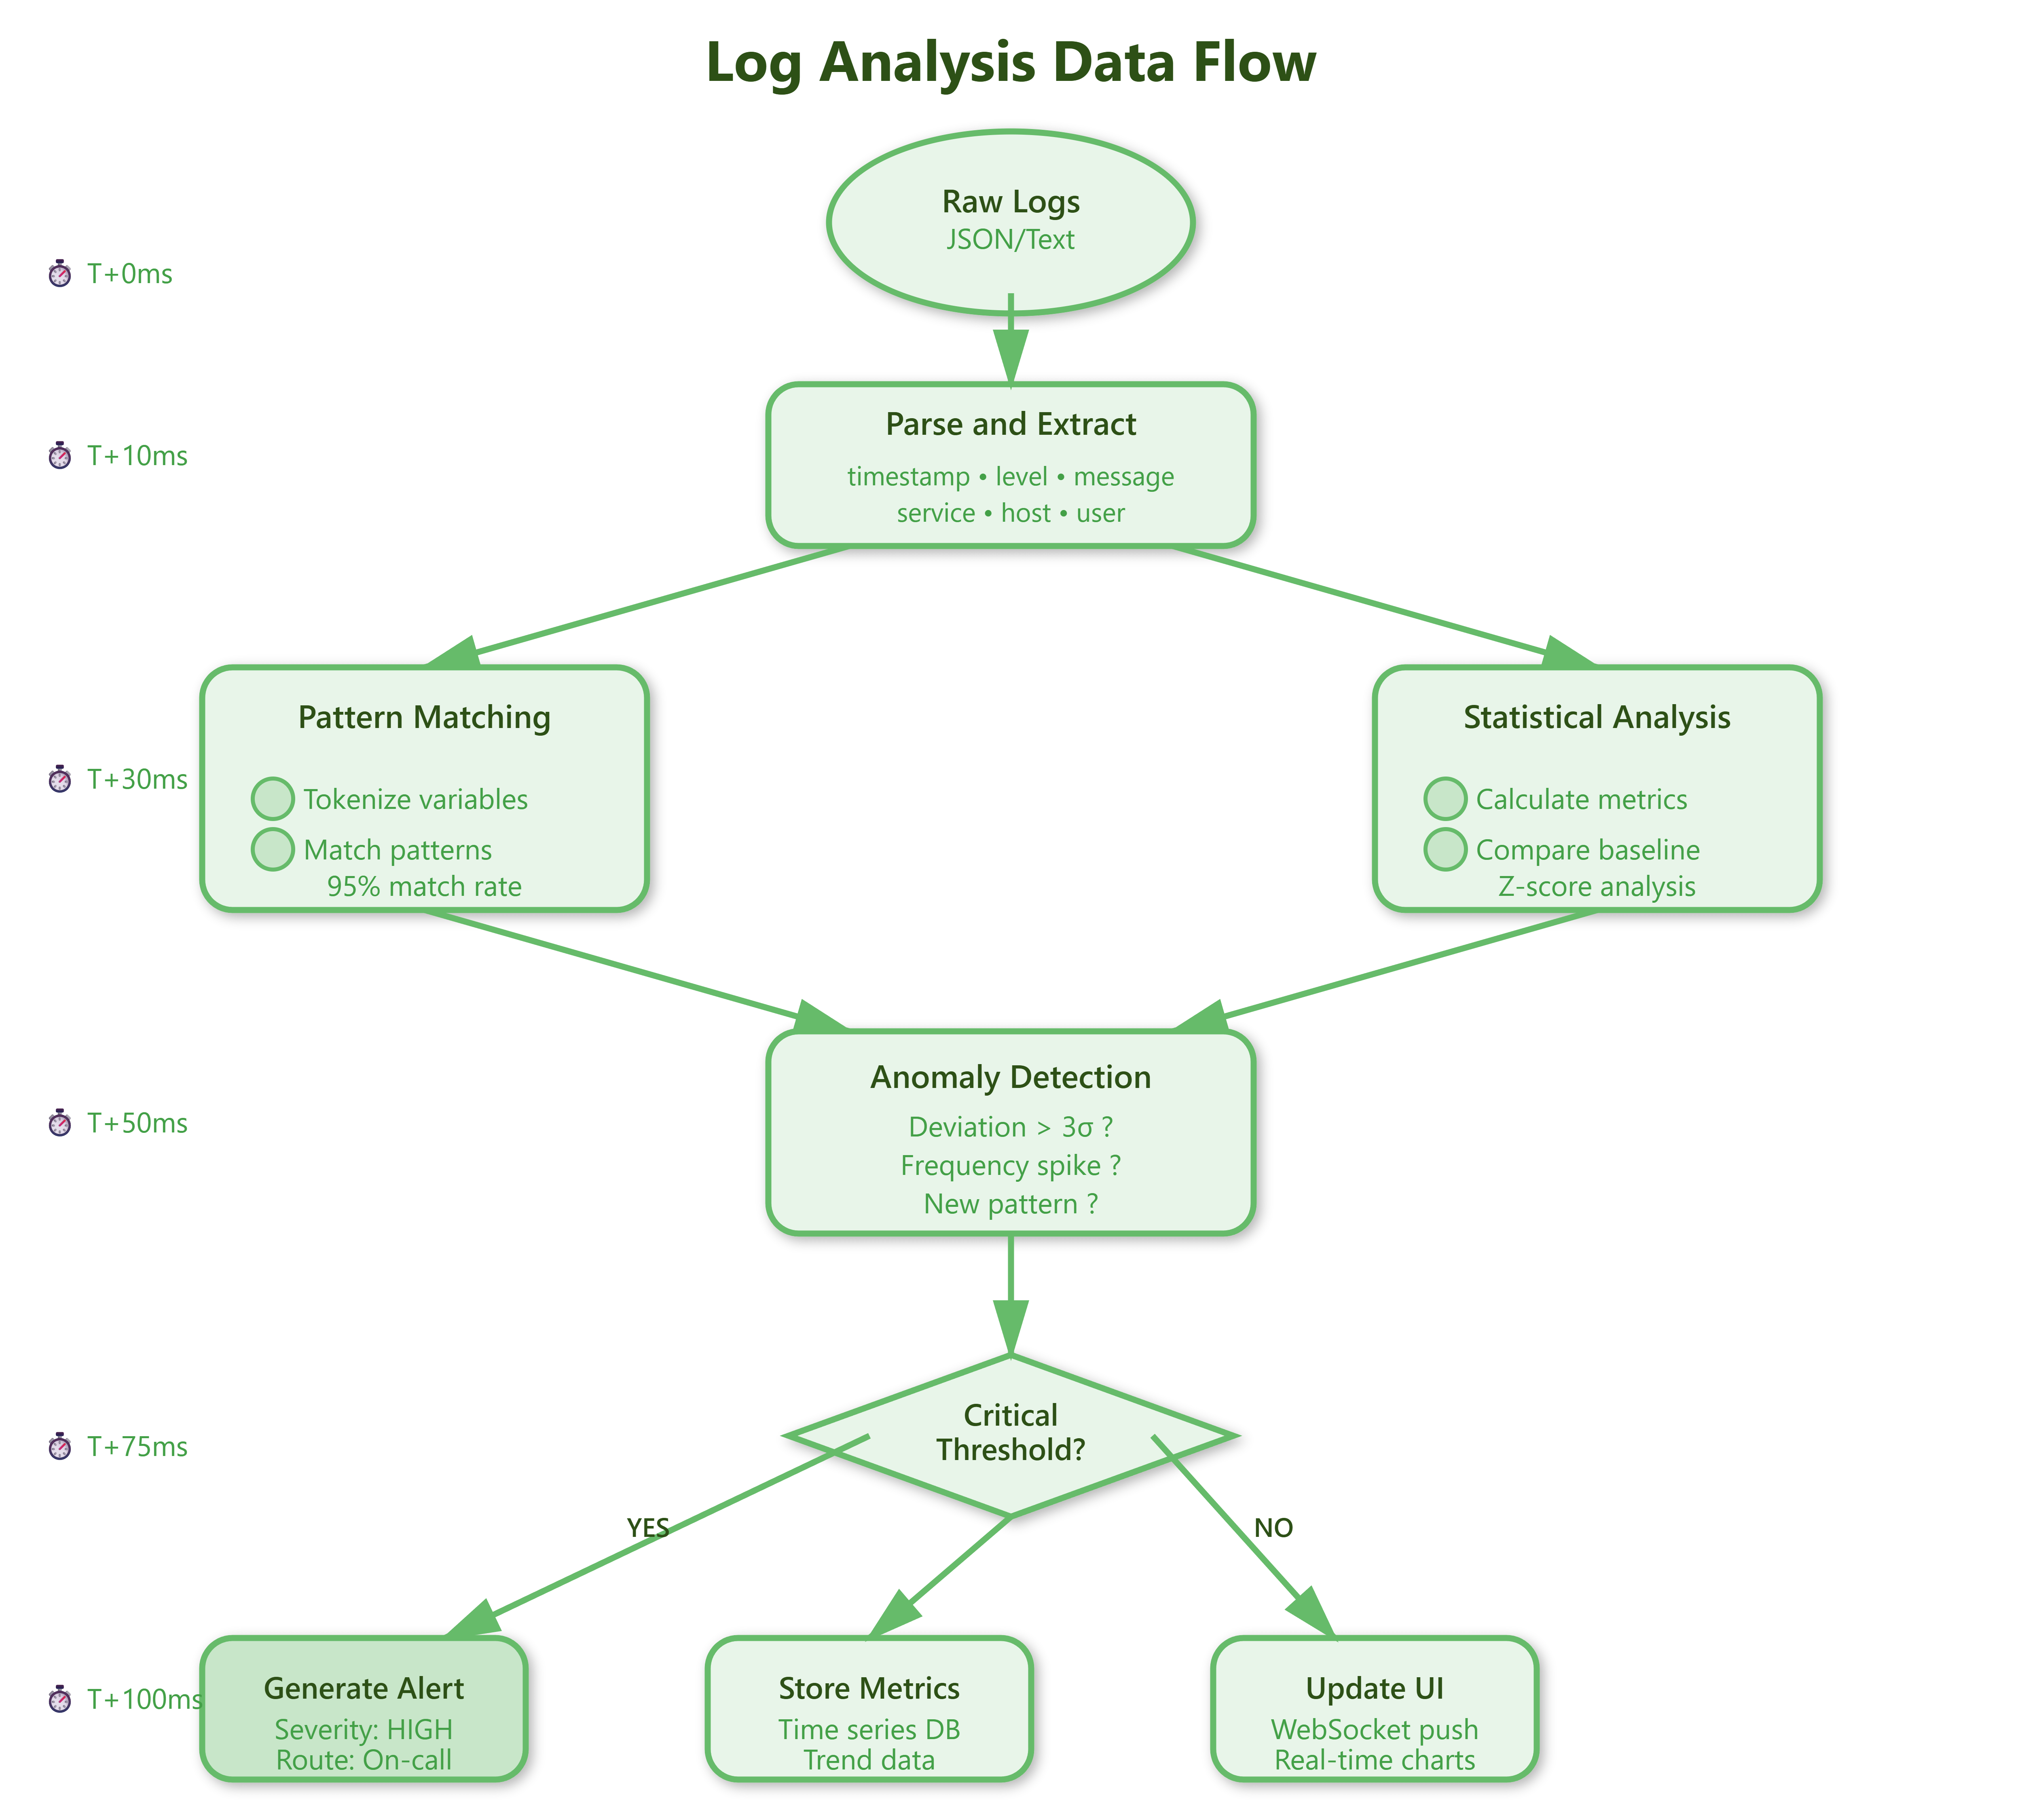
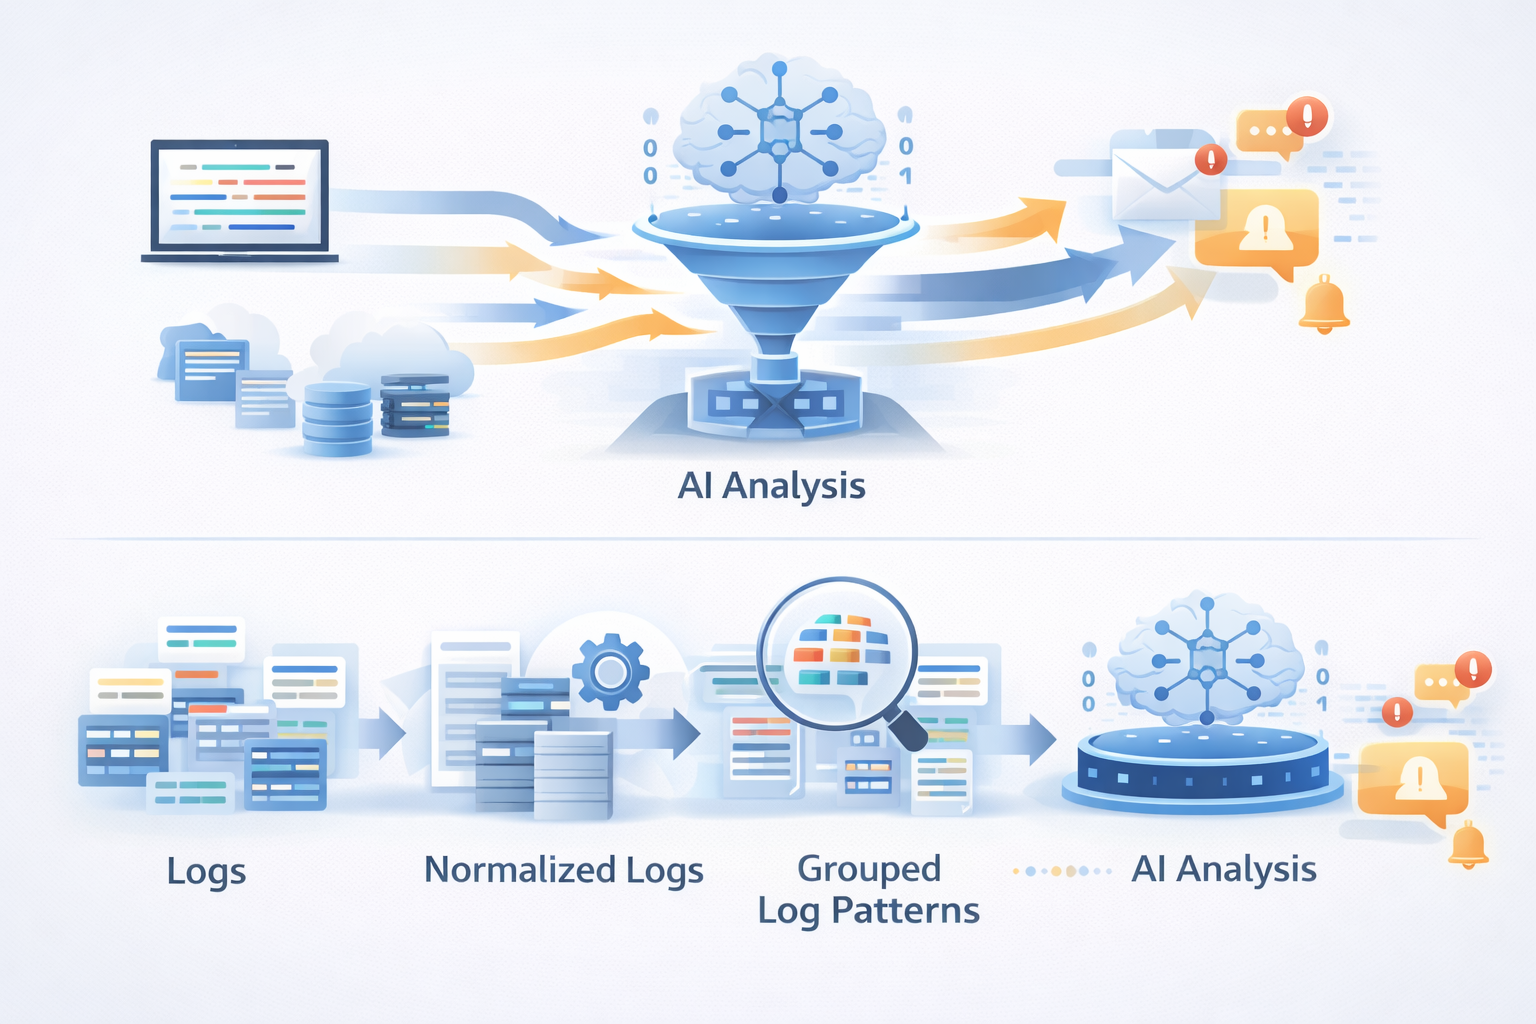
For log collection, I stick with open-source options. Fluent Bit or Filebeat for shipper agents that sit on the infrastructure and forward log events. On the storage side, Elasticsearch with Kibana works fine for smaller deployments, but I moved to Loki because it indexes metadata instead of the full text, which keeps costs down significantly. Prometheus for metrics, and I pair it with Grafana for visualization. For the actual analysis layer, I run custom Python scripts using pandas and a lightweight anomaly detection library like PyOD, plus some SQL queries against the log data warehouse. If you're on AWS, CloudWatch Logs with Lambda-based analyzers is decent but expensive at scale. GCP's Vertex AI has built-in model monitoring that handles a lot of the routine work, but you lose flexibility. The approach I've settled on involves a dedicated log ingestion pipeline that writes everything to a time-series database, then runs periodic analysis jobs that flag deviations from historical baselines. Here's the thing most guides won't tell you: the format of your logs matters more than the tool you choose. Structured JSON logs with consistent field names save you hours during an incident. I've seen teams waste two days just trying to parse unstructured log output from a pipeline that wasn't designed with observability in mind. Every log entry should have at minimum a timestamp, an event type, a correlation ID, and the relevant numerical values. Anything less and you're going to regret it later.
A Real Problem I Faced
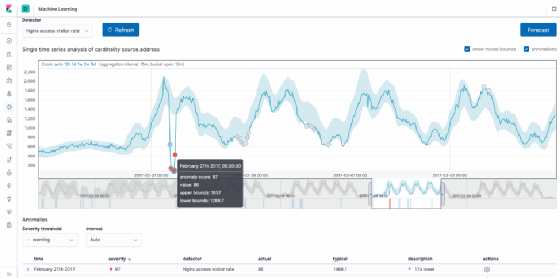
Last year I was running a recommendation model for an e-commerce platform. The model would periodically start making slightly worse predictions—nothing dramatic, maybe a 3% drop in click-through rate over several days. Nobody could find the cause because the standard alerts only triggered on hard failures, not gradual degradation. The infrastructure was healthy, the data pipeline was running, there were no errors in any log. I ended up writing a custom analyzer that compared the distribution of input features between consecutive training batches against the previous month's baseline using Jensen-Shannon divergence. The log analysis revealed that a downstream data source had started including a new product category that the model had never seen during training. The model wasn't breaking—it was just being asked to make predictions in a space it had zero coverage for. The anomaly showed up clearly in the log-derived feature drift metrics before it ever impacted the business metric. Once I identified it, I retrained the model with the new category included and the CTR recovered within a day. Without the log analysis layer, this would have taken weeks of manual investigation.
Get the Full Details
Counter-Intuitive Things I've Learned
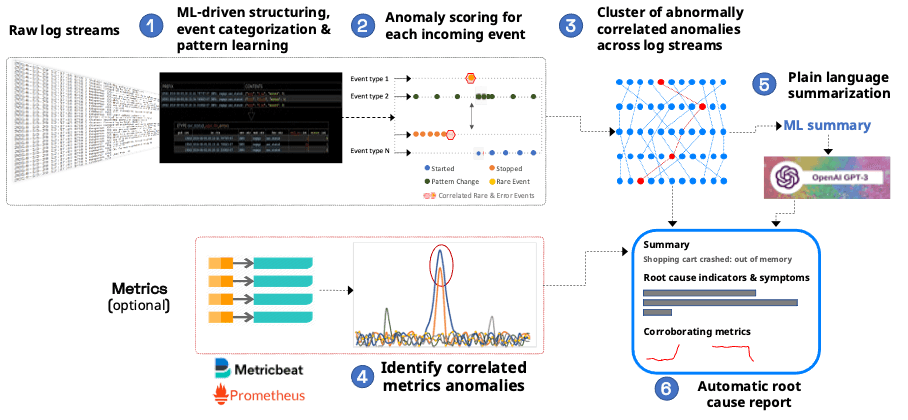
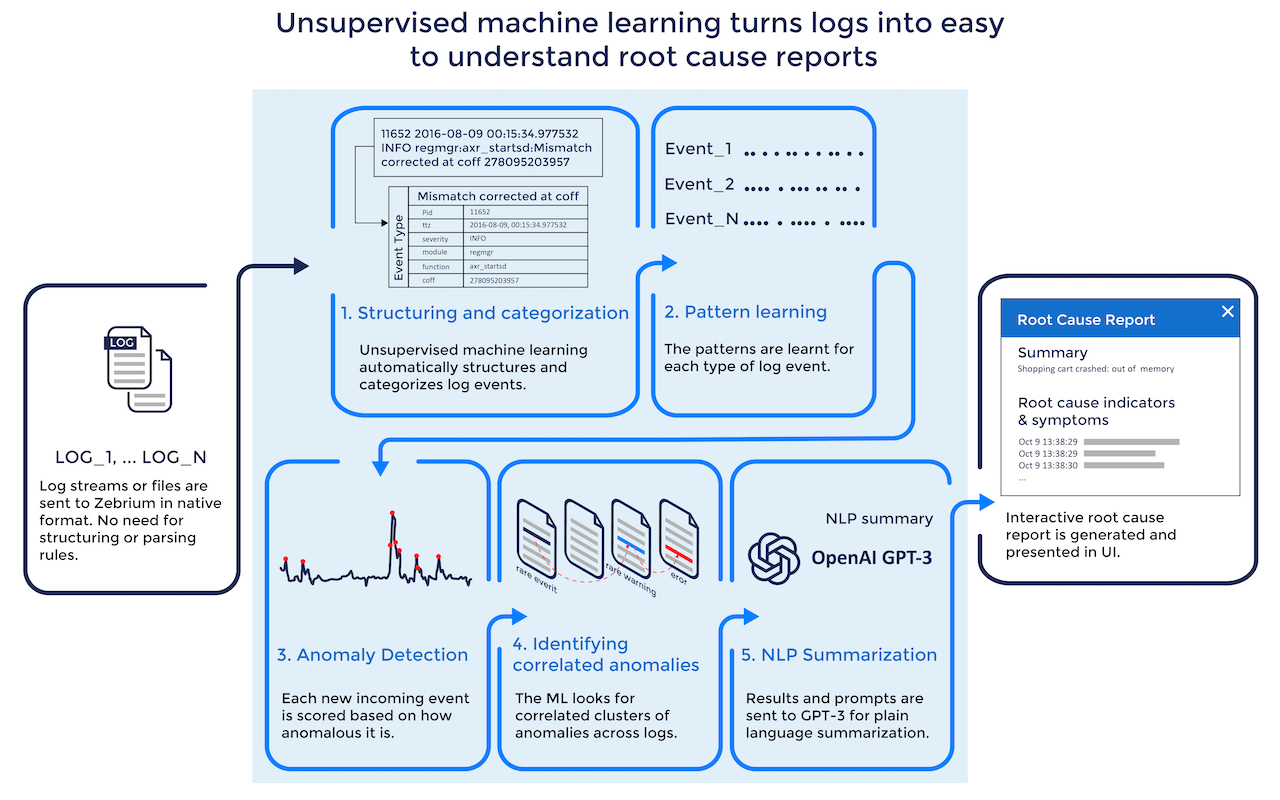
First, more logging is usually worse, not better. Every extra log entry increases storage costs, slows down your pipeline, and creates noise that drowns out actual signals. I've seen teams log every single prediction, every intermediate computation step, and every variable state. This makes it nearly impossible to find the relevant signal during an incident. Log at the event level—model invocations, training checkpoints, pipeline transitions, error conditions—not at the granular operation level. You can always recompute the fine details if needed; you can't recover logs you didn't capture. Second, the hardest patterns to detect aren't the ones that look wrong—they're the ones that look right but are actually wrong. A model can have perfect validation accuracy while its inference path is silently consuming stale data because a cache invalidation failed. The logs from the model itself will look healthy. You need to cross-reference the model's own telemetry with the infrastructure and data pipeline logs to catch these cases. This is where Machine Learning Log Analysis becomes genuinely useful rather than just a monitoring exercise.
Common Pitfalls and Where This Approach Fails
Log sampling is a real problem. Many production systems sample logs to reduce volume, which means rare failure modes get lost entirely. If you're sampling at 10%, you're going to miss errors that happen once per thousand requests. Always know your sampling rate and design your detection logic accordingly, or disable sampling for critical paths. Time synchronization across distributed systems is another issue I encounter constantly. If your model training job, inference service, and data pipeline are on different machines with slightly different clocks, correlating events becomes unreliable. NTP drift of even a few hundred milliseconds can throw off your analysis. Use a centralized time source and log the timezone explicitly. This sounds basic but I've spent entire afternoons debugging what turned out to be a clock skew problem. The biggest limitation of log-based analysis is that it can only tell you about things that were logged. If you didn't capture the right information, no amount of analysis will recover it. I've had to rebuild entire logging strategies from scratch because the original setup didn't include correlation IDs or sufficient context in error messages. Plan your logging schema before you deploy, not after.
Log volume also scales poorly. A single training run with high-frequency logging can generate terabytes of data in hours. Retention policies matter enormously here. I typically keep raw logs for about two weeks, aggregate them into summary statistics for a month, and then move to compressed cold storage. The cost of storing everything indefinitely is unsustainable for most teams, but you'll always want to go back to the raw data when something weird happens.
Getting Started Without Overcomplicating It
Start simple. Make sure your application logs are structured JSON. Add correlation IDs that flow through your entire pipeline. Set up a basic log aggregator. Write one script that queries your logs for error patterns and trains a simple statistical model to flag anomalies in key metrics. Don't try to build a full observability platform on day one. The goal is to be able to answer the question "what happened last Tuesday when the model started performing poorly" without spending three hours searching through files. The infrastructure for this isn't free, but it's manageable. For a small team, setting up Loki with Grafana and a few custom log parsing rules will cost you maybe a couple hundred dollars a month in hosting. The alternative is losing a day of engineering time every time something goes wrong in production, which is a much more expensive proposition when you factor in the business impact of undetected model degradation. The core insight is that log analysis for ML isn't fundamentally different from log analysis for any other system. It's about collecting the right data, structuring it consistently, and building queries that surface the patterns you care about. The ML-specific part is knowing which signals matter—feature drift, prediction distributions, training loss convergence—and making sure they're actually being logged in a way that lets you track them over time.
Most teams skip this because it feels like infrastructure work, not model work. But the models are running on infrastructure, consuming data from pipelines, and producing outputs that interact with users. All of that interaction leaves traces. The traces are in the logs. Learning to read them will save you more debugging time than any amount of hyperparameter tuning.