Getting ML-Based NTA Working Without Losing Your Mind
Most people try to slap a pre-trained model onto raw packet captures and wonder why it produces garbage. It doesn't work that way. The pipeline matters more than the model you pick. I spent about six months untangling a deployment where an organization had a perfectly decent XGBoost classifier and completely broken results. The issue wasn't the model at all. It was how they were extracting features from NetFlow data. Once I stopped treating packet headers as standalone values and started deriving flow statistics over sliding windows, the F1 score jumped from 0.41 to 0.83. I won't walk you through training a neural net here because that part is trivially well-documented. What nobody talks about is the data preparation, which eats roughly 70 to 80 percent of the total time. Let me get into the actual workflow and the parts that trip people up.
Understanding Machine Learning Network Traffic Analysis
This isn't magic. It's just supervised or unsupervised learning applied to network telemetry data. You take captured traffic, extract features like packet size distributions, inter-arrival times, protocol flags, flow duration, and byte ratios, then feed those into a model. The model learns what normal looks like and flags deviations. That's the entire concept distilled down. What happens in practice is messier. You're working with pcap files, NetFlow v9, sFlow, or whatever telemetry your environment generates. You need a labeled dataset. That's the hard part. Most organizations don't have labeled attack data sitting around because if they did, they wouldn't need the tool in the first place. So you end up using unlabeled traffic, running clustering algorithms, and manually validating the outliers. Or you buy a dataset like UNSW-NB15 or the CICIDS2017 set and fine-tune on top of that, which works okay for baseline training but fails when your actual network behaves differently than the dataset's capture conditions.
The Actual Feature Extraction Pipeline
Here's what you actually need to do, step by step. Step one: Capture or pull your traffic data. Zeek logs are usually the best starting point if you want structured, parseable output. If you're using raw pcap, you'll need something like Scapy or tshark to extract fields. I use tshark because it's faster and can export directly to CSV. Setting it up takes about ten minutes. A basic command looks like this: tshark -r capture.pcap -T csv -Y "tcp or udp" -E header=y -E separator=, -E quote=d -R "frame.time_epoch,tcp.srcport,tcp.dstport,tcp.len,tcp.flags,udp.len,ip.src,ip.dst" -w output.csv
Get the Full Details
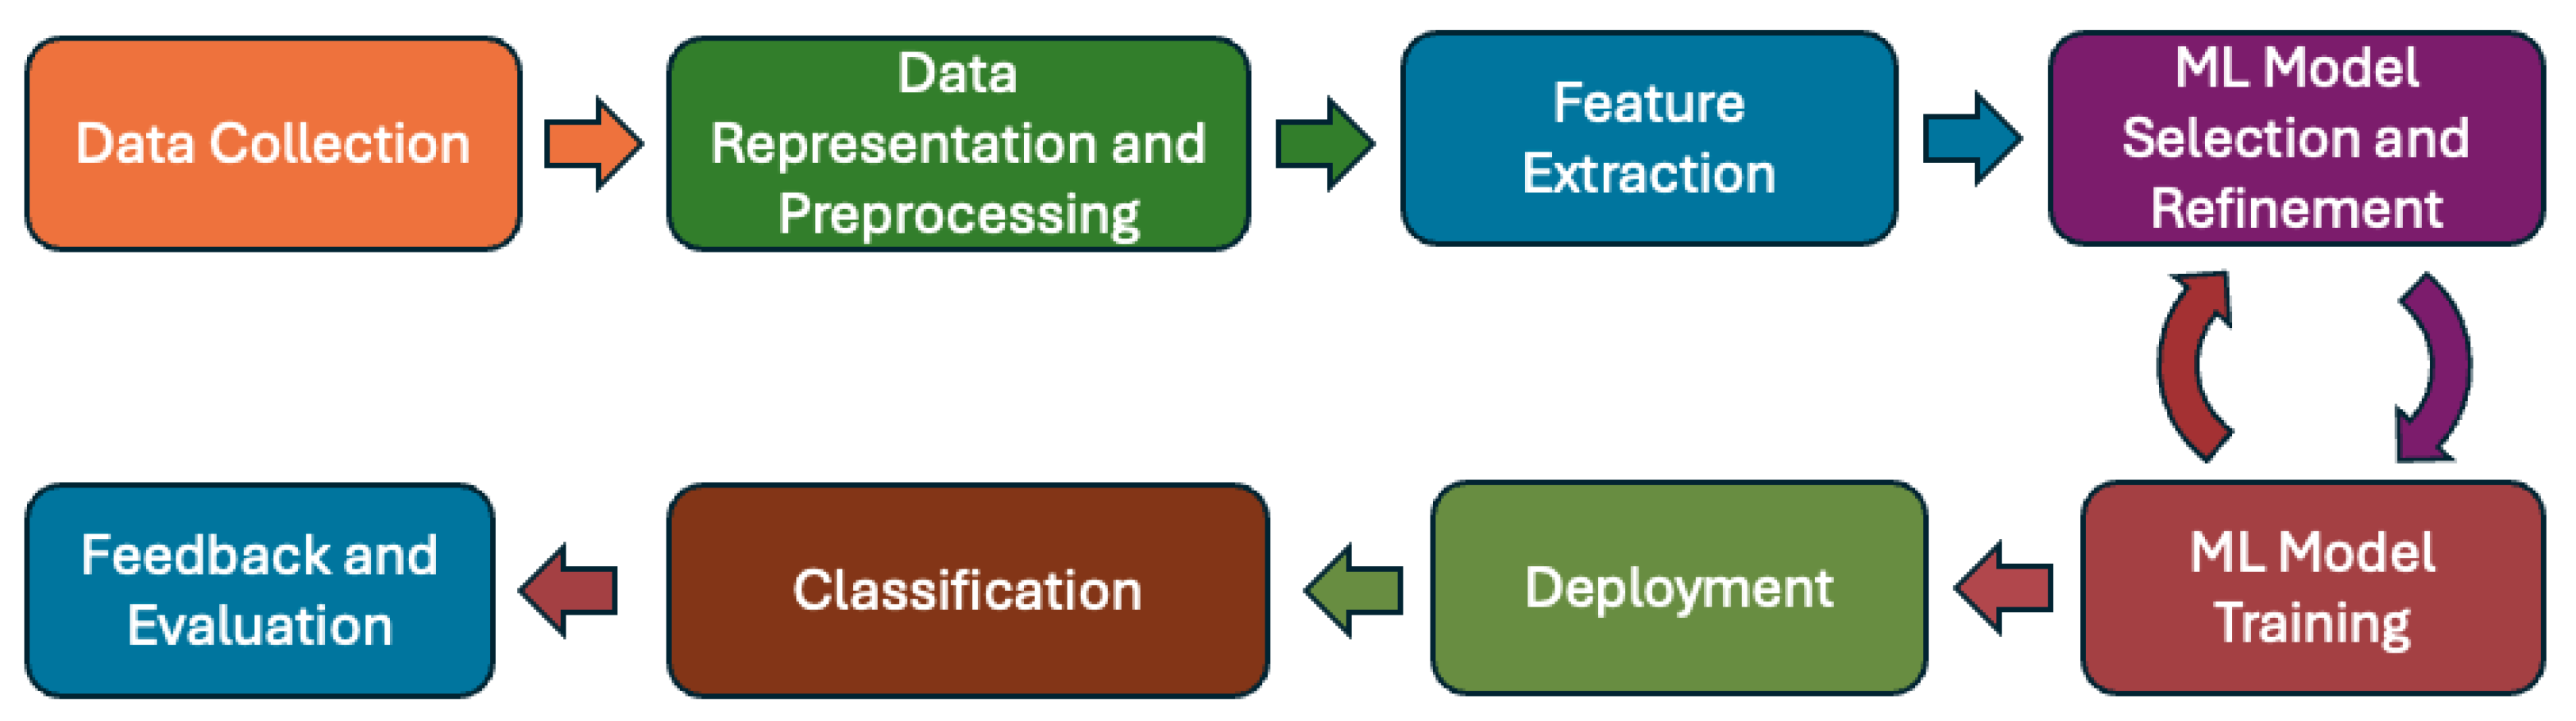
That gives you a flat CSV you can load into pandas. From there, you need to group by flow. A flow is typically defined by the tuple: source IP, destination IP, source port, destination port, and protocol. Packets belonging to the same flow get aggregated into one row per flow. Each row gets features like total bytes, total packets, mean packet size, standard deviation of packet sizes, flow duration, packet rate, and flag statistics. Step two: Label your data. If you have ground truth from an IDS or SIEM correlation, use it. If you don't, consider using a autoencoder to learn the normal distribution and flag high reconstruction error samples as potential anomalies. Then manually review a batch of those flagged samples to validate whether they're actually malicious or just unusual but benign traffic. Step three: Feature engineering. This is where most people quit. Raw features like total bytes are useless on their own. You need engineered features: the ratio of incoming to outgoing bytes, the number of unique destination ports per source IP per minute, whether a connection established but transferred zero bytes (often a scan), the ratio of SYN flags to total packets in a flow (high SYN-to-packet ratio is a classic port scan signal). These engineered features are what make the difference between a model that scores well on a benchmark and one that actually catches things in production.
Step four: Model selection. Start simple. Isolation Forest and Random Forest both work surprisingly well for network anomaly detection. I've used both extensively. Isolation Forest is faster at inference and requires less tuning. Random Forest tends to have slightly better precision but runs slower. For production environments where you're processing thousands of flows per second, Isolation Forest is the more practical choice. If you need higher recall and can afford the compute, Gradient Boosting with careful feature selection beats both.
Something Nobody Warns You About: Seasonality and Drift
Your model will degrade. Not slowly. Pretty fast. I had a deployment where the model was performing well for about three weeks, then the false positive rate doubled overnight. The network had changed. A new department migrated to a different cloud provider, and the traffic patterns shifted. The model had learned what normal looked like from the previous month and suddenly flagged routine cloud sync traffic as anomalous. It wasn't wrong technically. The traffic was anomalous relative to the training period. It was just not anomalous in a malicious sense. The workaround was implementing a sliding retraining window. Instead of training on a static historical dataset, I retrained the model weekly on the most recent two weeks of traffic, excluding any samples the security team had marked as false positives. This kept the normal baseline current and dropped the false positive rate back down to acceptable levels within a day of each retrain cycle. The whole retraining process takes about 15 to 20 minutes on a single GPU, depending on dataset size. Another issue that comes up constantly is class imbalance. Malicious traffic is usually less than one percent of total traffic. If you train a classifier without addressing this, it will learn to predict everything as normal and achieve 99 percent accuracy while detecting exactly zero attacks. You need to use techniques like SMOTE oversampling, class weight adjustment, or simply train on a balanced subset and calibrate the decision threshold afterward. I usually go with class weights because SMOTE can introduce synthetic samples that don't reflect real network behavior.

A Tool I Actually Use
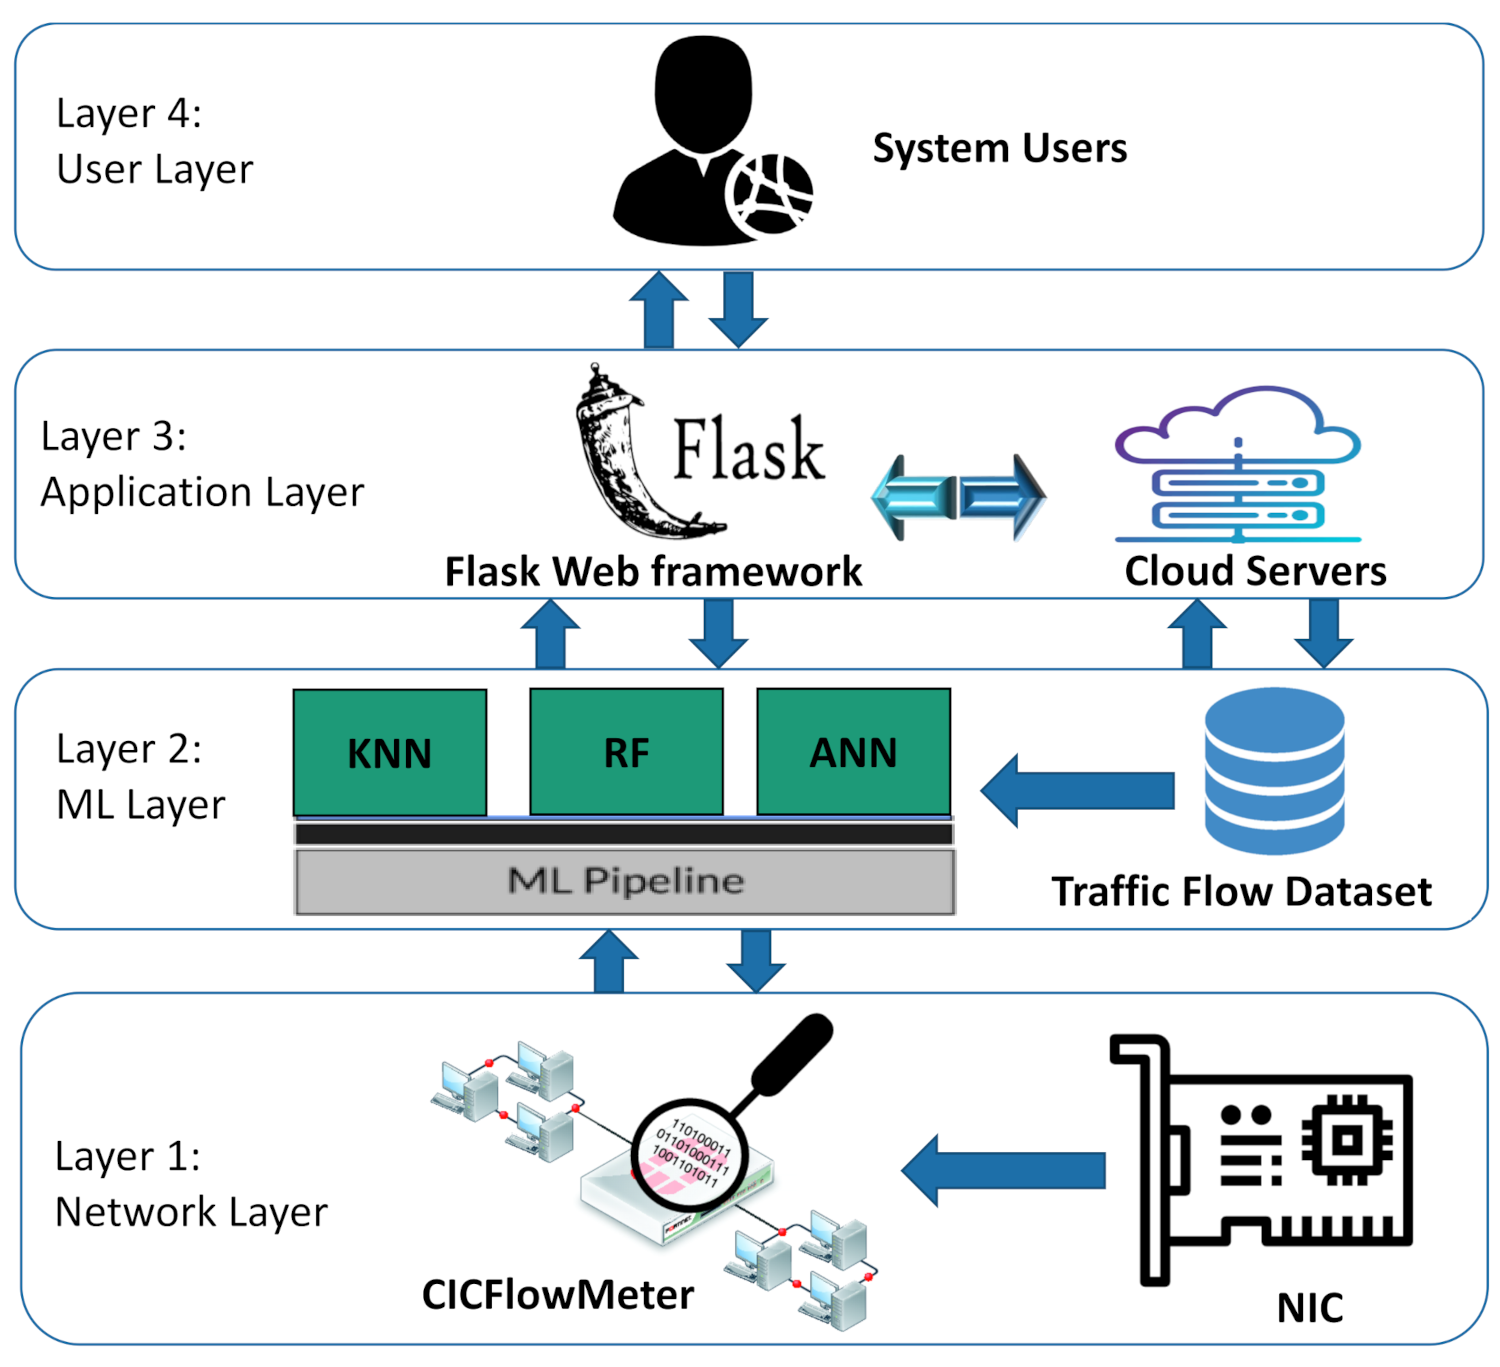
For people who want to get started quickly rather than build everything from scratch, there's ML-NTA. It's a GitHub repo that provides a full pipeline for network traffic analysis using machine learning. It handles feature extraction, basic labeling, model training with both Isolation Forest and Random Forest, and evaluation metrics. It won't solve every problem you have, but it gets you past the initial wall where most people get stuck. Download it and follow the README. The setup takes about 30 minutes if you have Python and pip installed. If you're working with live traffic rather than captured files, you'll want to integrate this with a stream processing tool like Apache Kafka or even a simple Python script reading from a port mirror. The real-time aspect adds complexity because you need to handle out-of-order packets and incomplete flows. A flow isn't complete until you see the FIN or RST flag, or until a timeout period (usually 60 seconds) expires. During that timeout window, your features are incomplete and your model's predictions are unreliable. I solved this by implementing a dual-pass system: the first pass runs predictions on partial flows using whatever features are available, and the second pass re-evaluates once the flow completes. The second pass corrects most of the early misclassifications.
When It Doesn't Work
Be honest about the limitations. ML-based network traffic analysis fails badly against encrypted traffic where payload-based features disappear. It struggles with low-and-slow attacks that spread malicious activity across weeks or months to avoid threshold-based detection. It also produces a lot of noise. Expect 5 to 15 percent of your flagged traffic to be false positives, even with a well-tuned model. You need a person or an automated triage workflow reviewing those alerts, otherwise the SOC will tune the model's sensitivity down until it catches nothing. For encrypted traffic specifically, you might look into TLS fingerprinting features instead. Things like JA3 hashes, certificate details, and handshake timing can be extracted without decrypting anything and they provide useful signals for identifying known malicious tools. Combining TLS features with flow-level features gives you better coverage than either approach alone. The bottom line is that this approach works well as part of a layered detection strategy. It's not a replacement for signature-based detection or behavioral rules. It's a tool for finding things you didn't already know how to look for. Used properly, it catches things that would otherwise slip through. Used blindly, it produces alerts that nobody acts on and gradually gets ignored. The difference is in how much attention you put into the data and the features.