Getting Started With Machine Learning Project Planning
Most people jump straight into coding when they start a machine learning project. They install libraries, grab a dataset, and begin training models without thinking about the overall structure. This approach usually leads to wasted time and confusing code later. A proper planning phase helps you avoid these problems before they happen. This is a systematic approach to organizing your machine learning workflow from the beginning. It covers dataset management, experiment tracking, model versioning, and deployment planning. The core idea is simple: document your decisions and reproduce them consistently. Without this structure, you will lose track of which parameters produced which results. I worked on a project last year where we trained over 200 variants of a recommendation model. We had no systematic way to track experiments. Two engineers independently modified the same configuration file and both claimed their results were better. It took us three days to realize they were testing completely different things. After that, I started using a structured planning method for every project.
The Practical Workflow
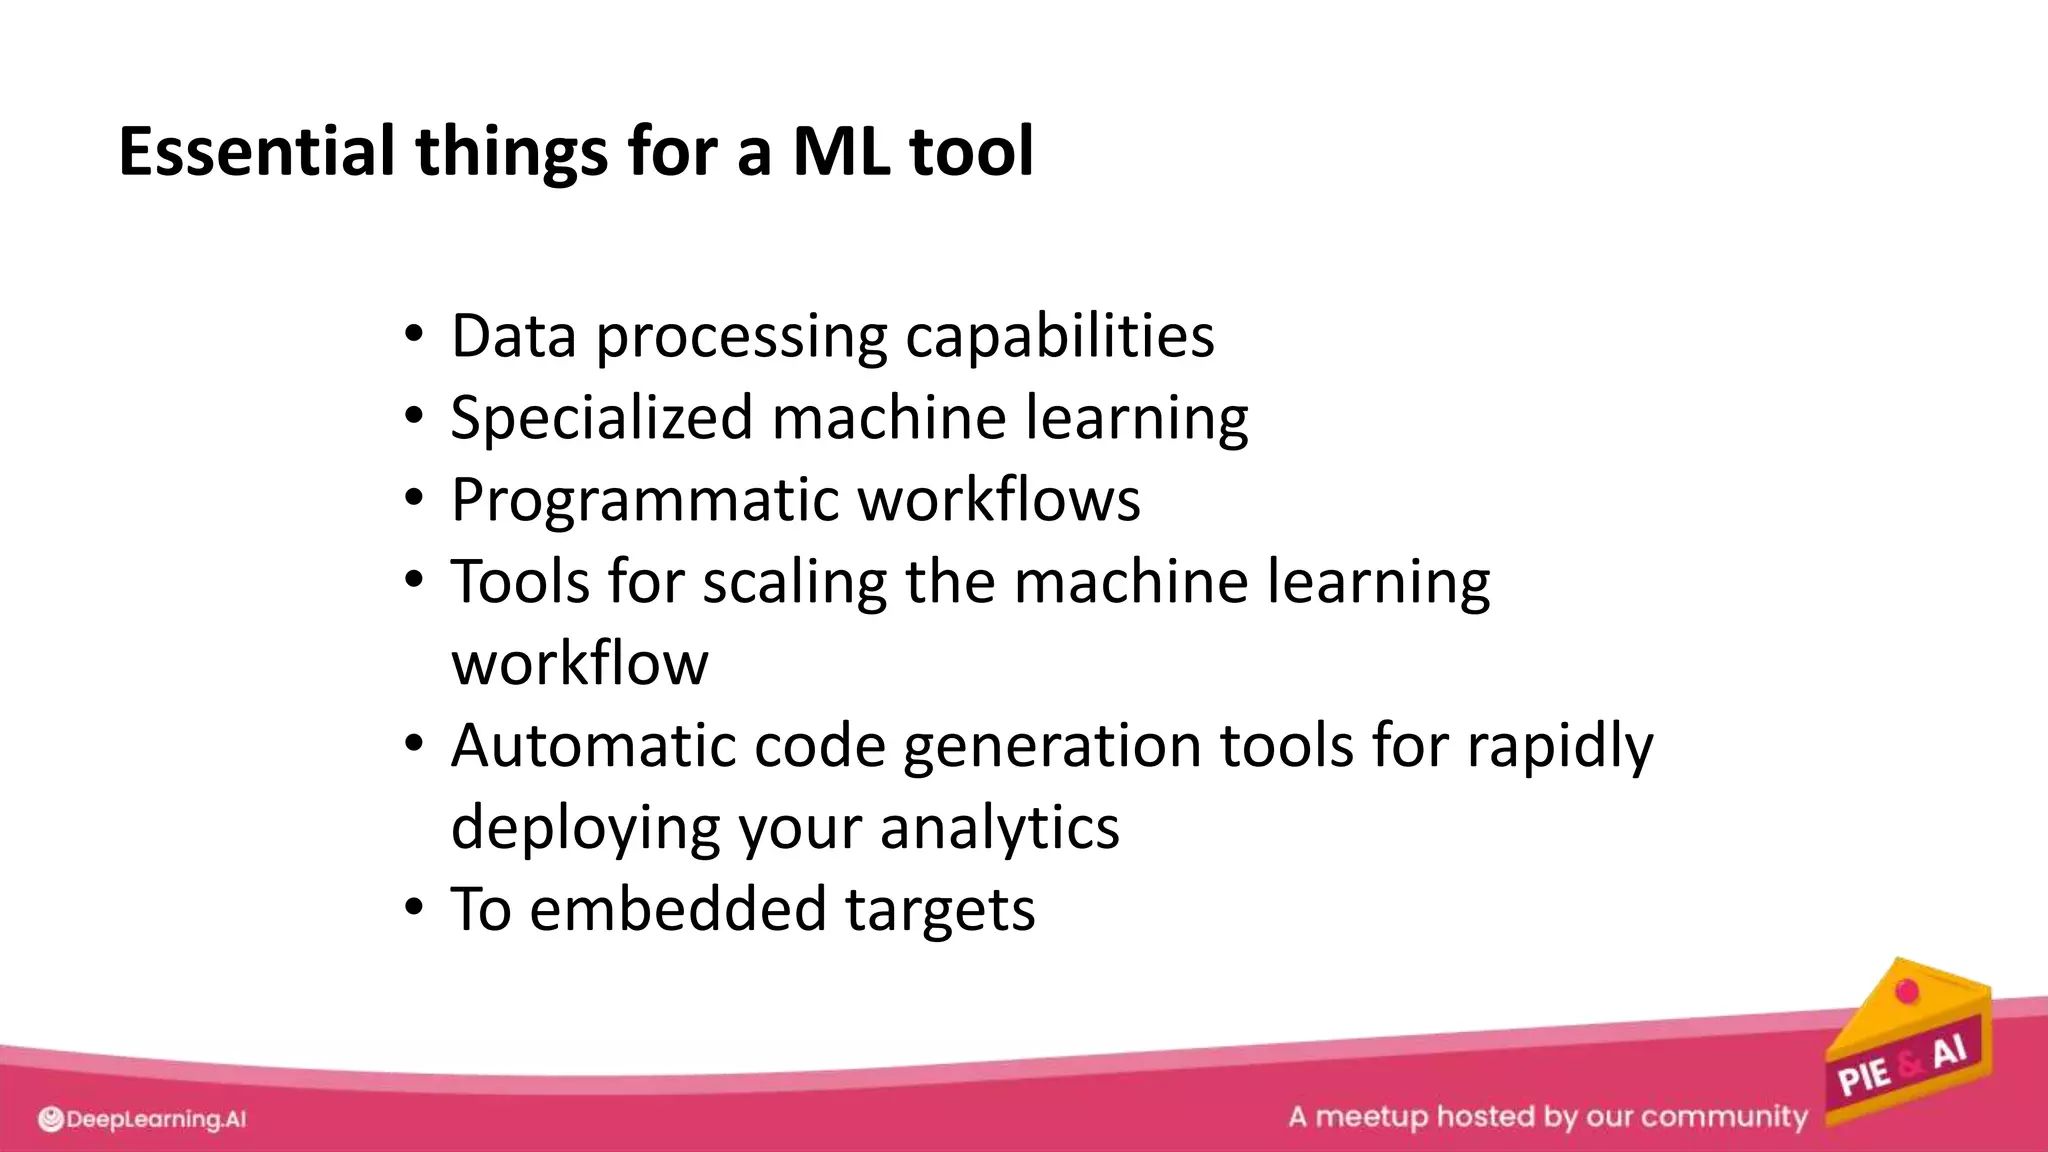
Start with your data pipeline before writing any model code. Create a clear folder structure that separates raw data, processed data, feature definitions, and model artifacts. I use this layout on almost every project: data/raw for untouched source files, data/processed for cleaned and transformed data, features/ for any transformation logic, and models/ for trained artifacts with timestamps. Document your feature engineering decisions in a simple YAML or JSON file. Include the input sources, transformation steps, and expected output shapes. This documentation becomes your single source of truth when someone asks why a particular feature looks a certain way. Without it, you will spend hours reverse-engineering decisions you made months ago. Experiment tracking is where most projects fail. Use a tool like MLflow or Weights & Biases, but configure it properly from day one. Record hyperparameters, data splits, metrics, and model artifacts for every run. I learned this the hard way when a model performed well in development but failed in production due to a data leakage issue that nobody could reproduce. Proper logging would have caught this immediately.
Common Pitfalls and Solutions
Overfitting to your validation set is a real problem when you run too many experiments without a holdout test set. I once saw a team achieve 97 percent accuracy on their validation data but only 64 percent in production. They had tested hundreds of configurations against the same validation set and unknowingly optimized for it. The solution is simple: keep a completely untouched test set until the final evaluation. Data drift is another issue that planning helps catch early. Monitor your feature distributions regularly and flag significant changes. I use a simple statistical test comparing current distributions to the training baseline. When the p-value drops below 0.01, I investigate whether the change is legitimate or indicates a pipeline problem. This warning system has saved me from deploying models trained on outdated data patterns. Version control for data is often ignored but critical for reproducibility. Use DVC or similar tools to track data changes alongside code. When a colleague reported different results from the same notebook, we discovered they were using a slightly different version of the dataset. The fix was implementing data versioning from the start of the next project.
Get the Full Details
Deployment Considerations
Planning for deployment before training begins saves significant rework. Define your serving requirements upfront: expected latency, throughput, and update frequency. These constraints influence your model architecture choices more than you might expect. A model requiring sub-100-millisecond responses needs different optimization than one processing batch requests asynchronously. Containerize your training and serving environments consistently. I use Docker with pinned dependency versions to ensure reproducibility. The exact same code should produce identical results whether running on a developer laptop or production server. Inconsistent environments have caused more production incidents than I can count. Monitor your deployed models for performance degradation. Set up alerts for prediction drift and error rate spikes. I configure automated daily evaluations comparing current performance to baseline metrics. When accuracy drops below a threshold, the system notifies the team for investigation. This proactive monitoring catches issues before users notice problems.
Resources and Tools
MLflow provides open-source experiment tracking with model registry features. The basic setup takes about 30 minutes and supports most major frameworks. You can host it yourself or use the managed version for larger teams. The tool integrates well with existing CI/CD pipelines and supports Python, R, and Java projects. DVC handles data versioning and pipeline orchestration effectively. It works as a Git extension and tracks data changes without storing large files in repositories. The learning curve is moderate but the payoff in reproducibility is substantial. Projects with complex data dependencies benefit most from this approach. For production monitoring, Prometheus with Grafana provides flexible metrics collection and visualization. I configure custom exporters for model-specific metrics like prediction latency and confidence distributions. The combination of standard infrastructure metrics with model-specific measurements gives complete visibility into system health.
Weights & Biases offers a managed alternative with strong collaboration features. The free tier supports individual researchers while paid plans provide team management capabilities. Projects requiring frequent experiment comparison across multiple team members benefit from the centralized dashboard. FastAPI provides a modern framework for building model serving APIs. The automatic documentation generation and async support make it suitable for production deployments. I typically containerize FastAPI services with Gunicorn for production and uvicorn for development. The framework handles request validation and response serialization efficiently.

When Planning Fails
No planning method works perfectly for exploratory research projects where requirements change frequently. If you are experimenting with novel architectures or researching new approaches, rigid planning can slow down iteration. In these cases, use lightweight documentation: simple notebooks with clear sections and versioned checkpoints. The goal is balance between structure and flexibility. Small teams with limited data may not benefit from enterprise-grade tooling. The overhead of configuring MLflow, DVC, and monitoring systems can exceed the value gained from perfect reproducibility. Start with simple file-based tracking and graduate to specialized tools as projects grow. The planning should serve your workflow, not constrain it. Sometimes the best approach is minimal planning with frequent review. I conduct weekly check-ins with my team to assess whether our planning artifacts remain accurate and useful. Outdated documentation is worse than no documentation because it creates false confidence. Regular maintenance keeps the planning process relevant and valuable.