So You're Looking for Machine Learning Printable Best
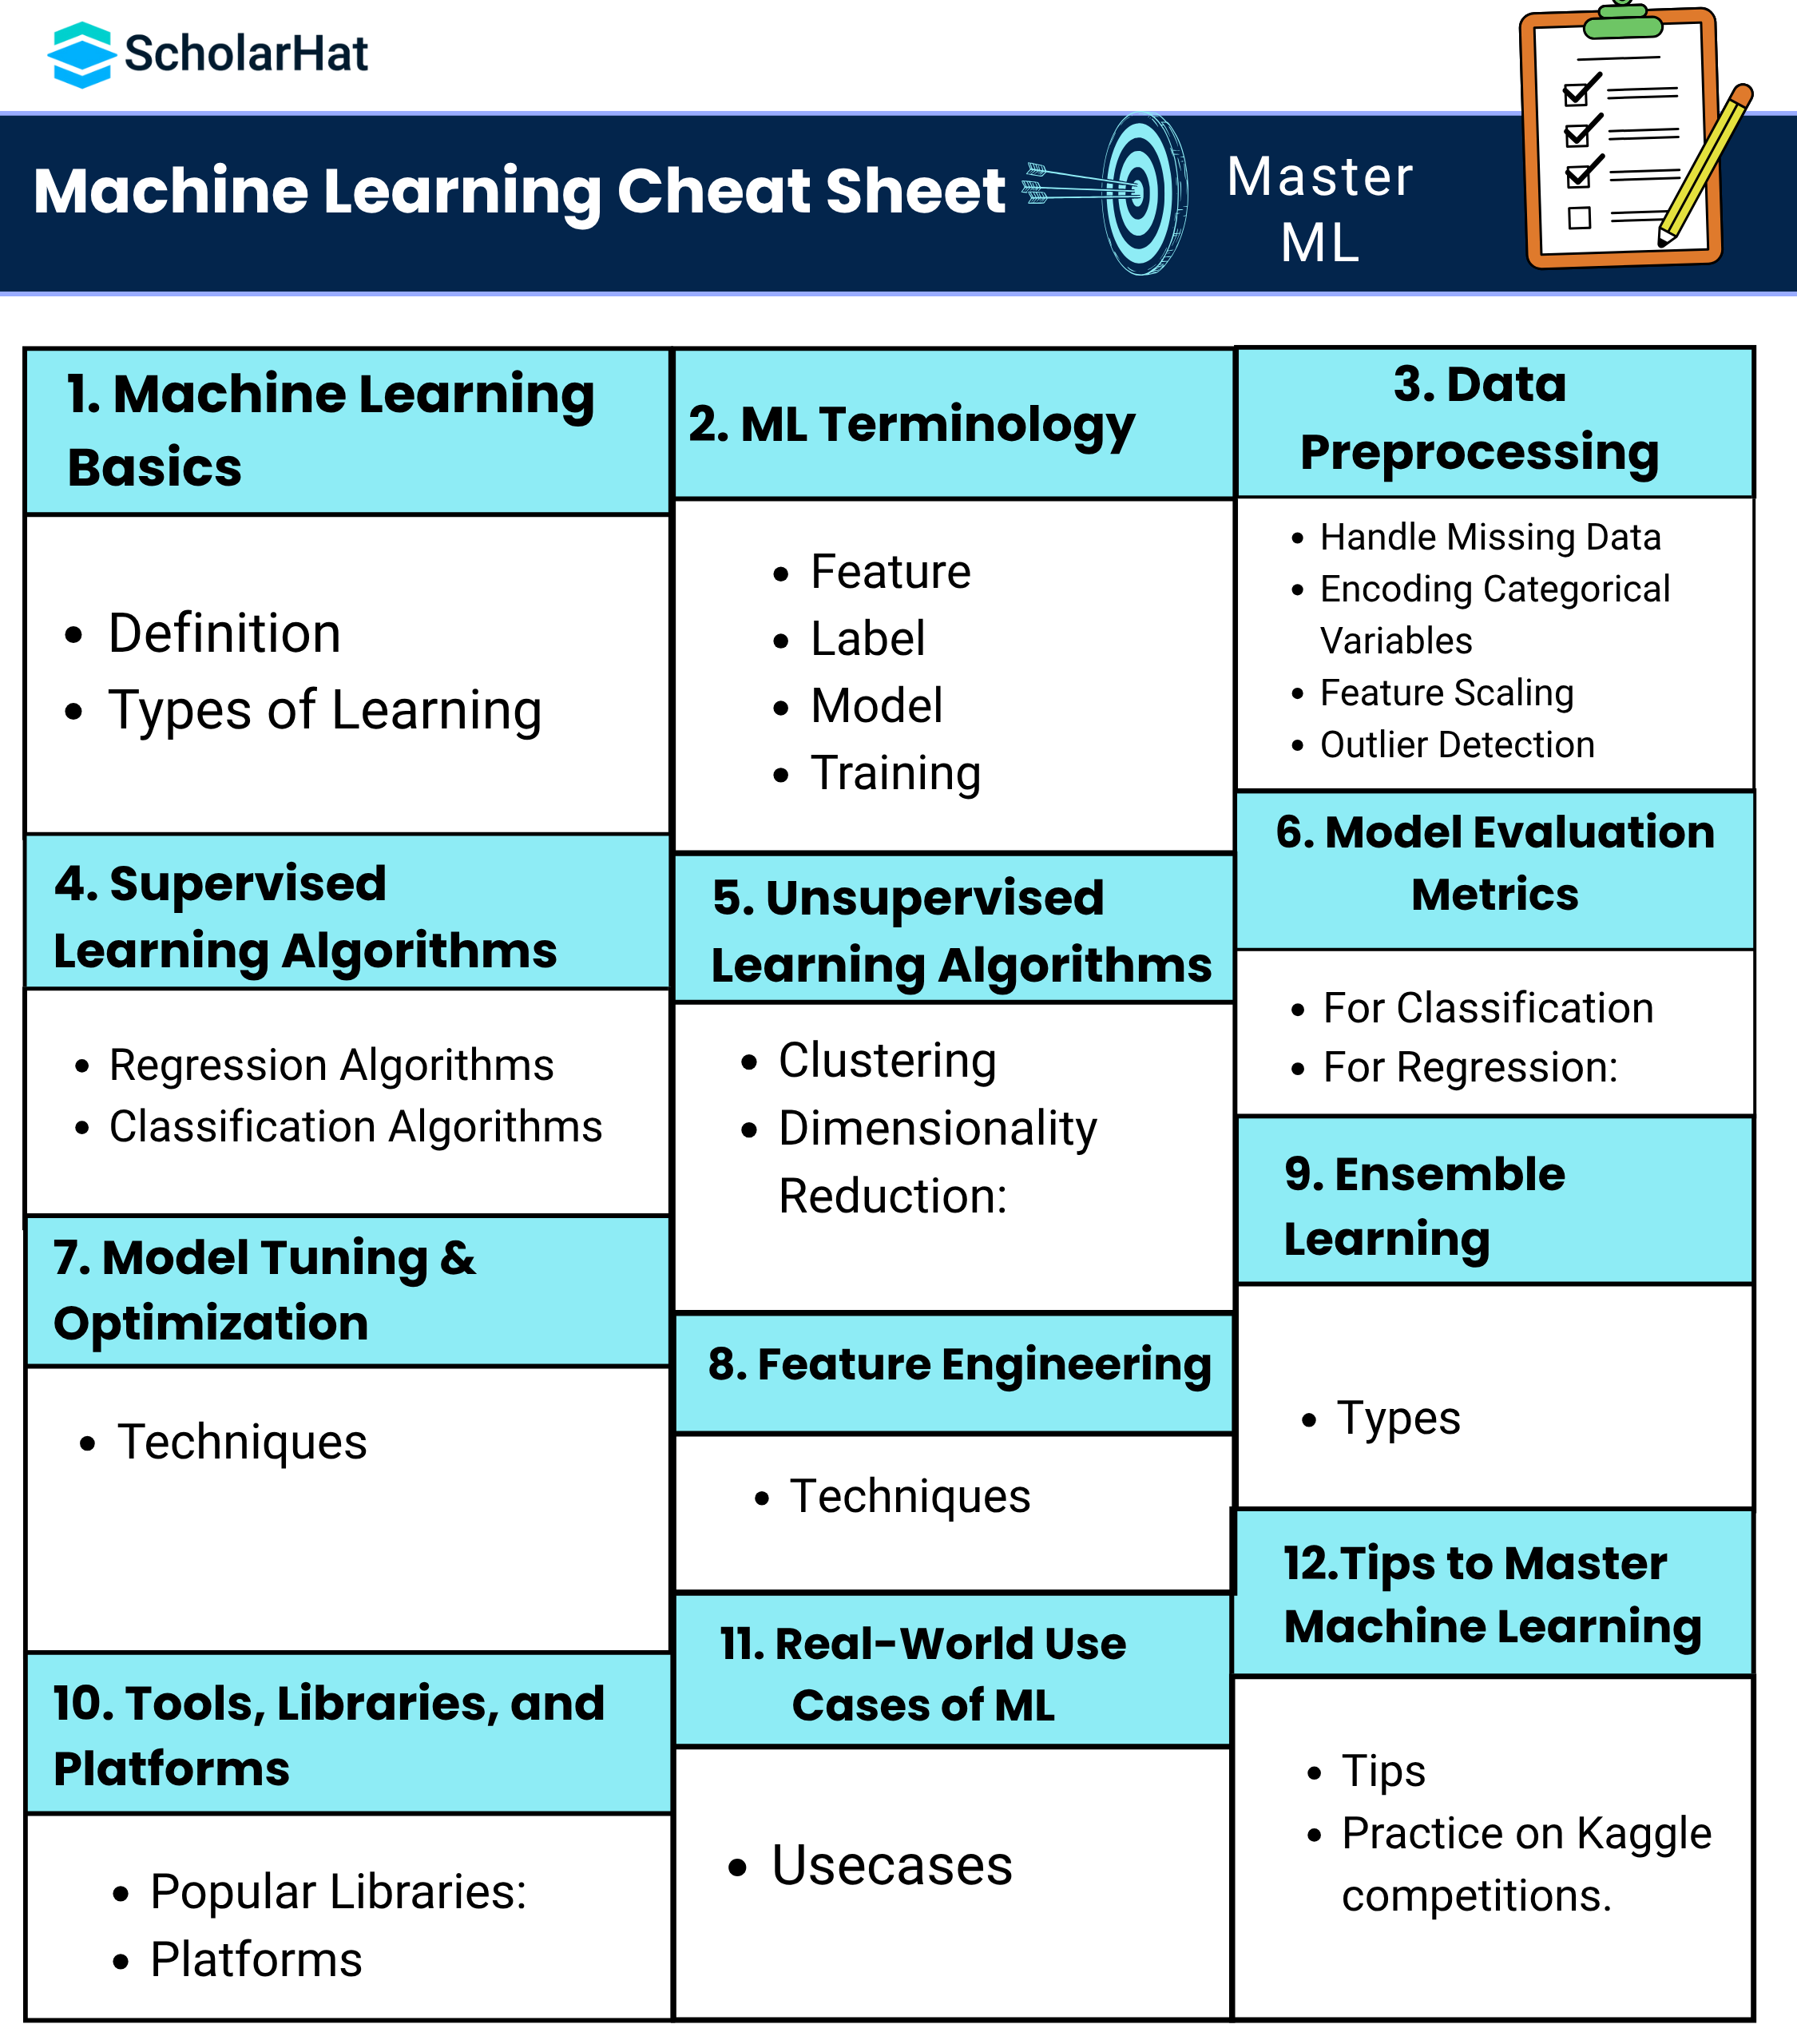
I found myself going back to this resource repeatedly when setting up quick model evaluation sheets for my team. What I appreciate about it isn't anything groundbreaking — it's just well-organized. The layout covers the usual suspects: confusion matrix templates, ROC curve plotting guides, feature importance checklists, and a decent section on handling imbalanced datasets that most people overlook until their F1 scores look nothing like their accuracy numbers. Here's how I actually use it. When I'm starting a new project, I print out the evaluation framework page first and pin it next to my monitor. That one sheet alone saves me from forgetting to track precision-recall tradeoffs on classification tasks, which happens way more often than I care to admit. The downloadable version is clean — no ads, no popups, just a straightforward PDF that loads fast and prints without cutting off the rightmost columns. My go-to section has always been the class imbalance troubleshooting flowchart. I spent about three weeks debugging a model that looked perfect on validation but collapsed on production data. Turns out I'd been optimizing for the wrong metric the entire time because I never actually mapped out which threshold mattered for my specific use case. That flowchart helped me walk through the decision process step by step. I wish I'd seen it before I wasted those three weeks, but better late than never.
What's Actually Good About This Resource
The confusion matrix breakdown is genuinely better than most of what you'll find floating around. A lot of tutorials gloss over the difference between macro and weighted averaging when reporting metrics. This one explains it plainly and shows you exactly when each approach makes sense. For multi-class problems, the weighted average is usually what you actually want, but people default to macro averages because they're easier to explain in a meeting. That disconnect costs real projects. Another thing worth noting: the probability calibration section. Most people never think about whether their model's output probabilities are actually calibrated until something breaks downstream. Brier score calculation and reliability diagrams are covered with enough detail to get started without overwhelming you. I've used this when building models that feed into risk scoring pipelines where miscalibrated probabilities directly affect business decisions. The guidance on isotonic regression versus Platt scaling is concise but accurate.
What's Missing or Could Be Better
Let me be straight about the limitations. There's almost nothing on time series or sequential data. If your problem involves temporal dependencies, you're on your own beyond what standard cross-validation templates can offer. The k-fold stratification advice doesn't extend well to time-based splits, and that gap matters more than you'd think until you're accidentally leaking future information into your training set. The hyperparameter optimization section is superficial. It mentions grid search and random search but skips over Bayesian optimization entirely, which is pretty standard now. For anyone running experiments with more than a handful of parameters, that omission is a real bottleneck. I ended up supplementing this with Optuna documentation and writing custom sweeps rather than relying on what's covered here. There's also no discussion of reproducibility practices beyond "set your random seed." That's adequate for a quick reference but completely insufficient if you're working in a team environment where someone else needs to reproduce your results months later. Track everything, use experiment management tools, and don't rely on a printable PDF to keep your workflow consistent.
Get the Full Details

How to Actually Use This Without Wasting Time
Print it once. Don't print it every time. I see people bookmarking these resources and then never touching them again because they treat finding the document as the end of the process. Download the PDF, print the sections relevant to your current project, and reference it directly while you work. The value is in the act of looking at it during the actual implementation, not in having it saved somewhere. Pair it with a notebook or spreadsheet where you log your experiments. The templates in this resource are designed to be filled out, not admired. I keep a running log with columns for dataset split strategy, metric choices, and whatever preprocessing steps I applied. When I come back to a project six months later, that log is worth more than any printable guide. Also, don't treat the examples as gospel. The toy datasets they use for demonstrations are fine for learning the concepts, but your real data will behave differently. I ran one of their classification examples through my own pipeline and got slightly different results because of how the train-test split handled the class distribution. Minor discrepancy, but it reminded me that these are illustrations, not benchmarks to match exactly.
Download
The official page is ML-Printable-Best Resources. It's free, no registration required. I'd recommend filtering by your specific use case before diving in — the full document is around 40 pages, and trying to absorb everything at once just slows you down. Pick the sections that match your immediate problem and come back for the rest later. If you're just starting out with ML and want something tangible to work from, this is decent. It won't make you an expert overnight, and it doesn't cover everything you'll eventually need, but it's cleaner than most of what's available and the explanations don't talk down to you. That's more than I can say for a lot of what's online.