Learning ML Without Burning Out
I keep seeing people ask about structured ways to actually get functional with machine learning without reading fifteen books and then quitting. There isn't one official curriculum. What exists are people sharing their own monthly pacing. I call the approach Machine Learning Step By Step Monthly because that's what it actually is. The idea is simple. You commit to one focused month where you learn a single slice of the workflow end-to-end. Not theory for theory's sake. A complete loop from data to deployment, even if the loop is small and ugly. Most advice skips straight to model training and leaves people confused about why their scripts crash on real data. That's the wrong starting point.
Machine Learning Step By Step Monthly
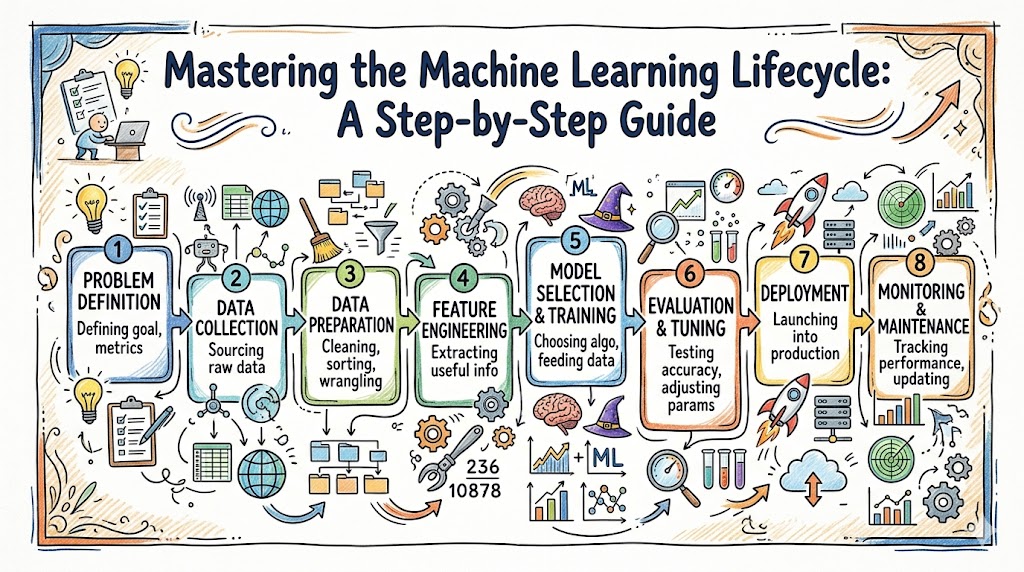
Here is how it works in practice. You pick a month. You define a narrow problem. You build the pipeline, break it, fix it, and ship something that isn't a notebook full of prints. The month becomes a container. It forces prioritization. Start with data, not models. I see the same mistake constantly. People download a cleaned dataset, run a quick baseline, and call it a project. Real data doesn't land cleanly. You will spend the first two weeks just mapping where columns come from, why dates shift across sources, and who decides what "missing" means. Write that down. Keep a log. It saves you months later when someone asks how you got a number. Build a dumb baseline first. Mean imputation, constant prediction, or a simple heuristic. Measure it. Then add complexity only when the baseline fails on the metric that matters. If your business cares about false negatives more than accuracy, stop optimizing AUC. Track the cost you actually pay. This habit cuts evaluation time from hours to minutes because you stop chasing vanity scores.
The third week is where most plans collapse. Model selection comes late, but feature engineering, validation design, and error analysis should happen early. Split your data by time, not randomly, if your problem has any temporal component. Random splits look good in tutorials and lie in production. I had a project where a great cross-validation score dropped to near-random once we deployed, because the validation set contained future info leaked through grouping. The fix was event-based splitting and a holdout period that matched the shipping cadence. Ship something small by the fourth week. A script that reads input, predicts, logs output, and fails loudly. Add monitoring if you can. If you cannot, add a simple log file with timestamps and a threshold check. Production readiness is not a metaphor. It means you can restart the pipeline without rewriting code and you know when it breaks. I recommend repeating this cycle monthly. Each month adds one layer. Month one ends-to-end on a tiny dataset. Month two adds proper validation. Month three adds deployment. Month four adds monitoring and rollback. You do not need a perfect plan. You need a completed loop you can examine and improve.
Get the Full Details

Common pitfalls are predictable. Overfitting to a single notebook. Chasing SOTA without a clear metric. Ignoring feature drift. Assuming preprocessing is reversible. Treating data cleaning as a one-time task. These are not secret knowledge. They are just easy to forget when you are excited about a new model. Another nuance people miss is that hyperparameter tuning often pays off less than fixing data quality. I spent two days on a grid search once and gained nothing. Then I spent an afternoon fixing duplicate records and the score improved noticeably. Compute budget is finite. Spend it where the bottleneck actually is. If this monthly structure does not fit your schedule, consider a quarterly cadence with a weekly micro-commitment. Or skip it entirely and focus on a single problem until it breaks in a way that teaches you something new. The method is a scaffold, not a rule.
For a download package or starter template, look for a repository that includes a sample dataset, a baseline script, a validation splitter, and a simple logging setup. If you find one, adapt it to your domain. Do not copy it blindly. That is the practical version of Machine Learning Step By Step Monthly. It is not glamorous. It is just a way to stop drifting and start shipping.