System Design for ML Interviews Is a Whole Different Game
You spend months grinding coding questions, then show up to the ML system design round and suddenly you're expected to architect a recommendation pipeline from scratch while also handling distributed training constraints and model serving latency. Most people have no idea what they're doing here. I've seen candidates freeze when asked about feature stores, batch versus streaming inference, or how to handle cold start in a real deployment scenario. This gap exists because traditional system design interviews focus on distributed databases and message queues, but ML adds an entirely different layer of complexity. You're not just designing a system that moves data around, you're designing one that learns, adapts, and degrades over time. That means thinking about model drift, retraining pipelines, A/B testing frameworks, and offline evaluation metrics alongside the usual scalability concerns.
Where to Find the Machine Learning System Design Interview By Ali Aminian Alex Xu Pdf
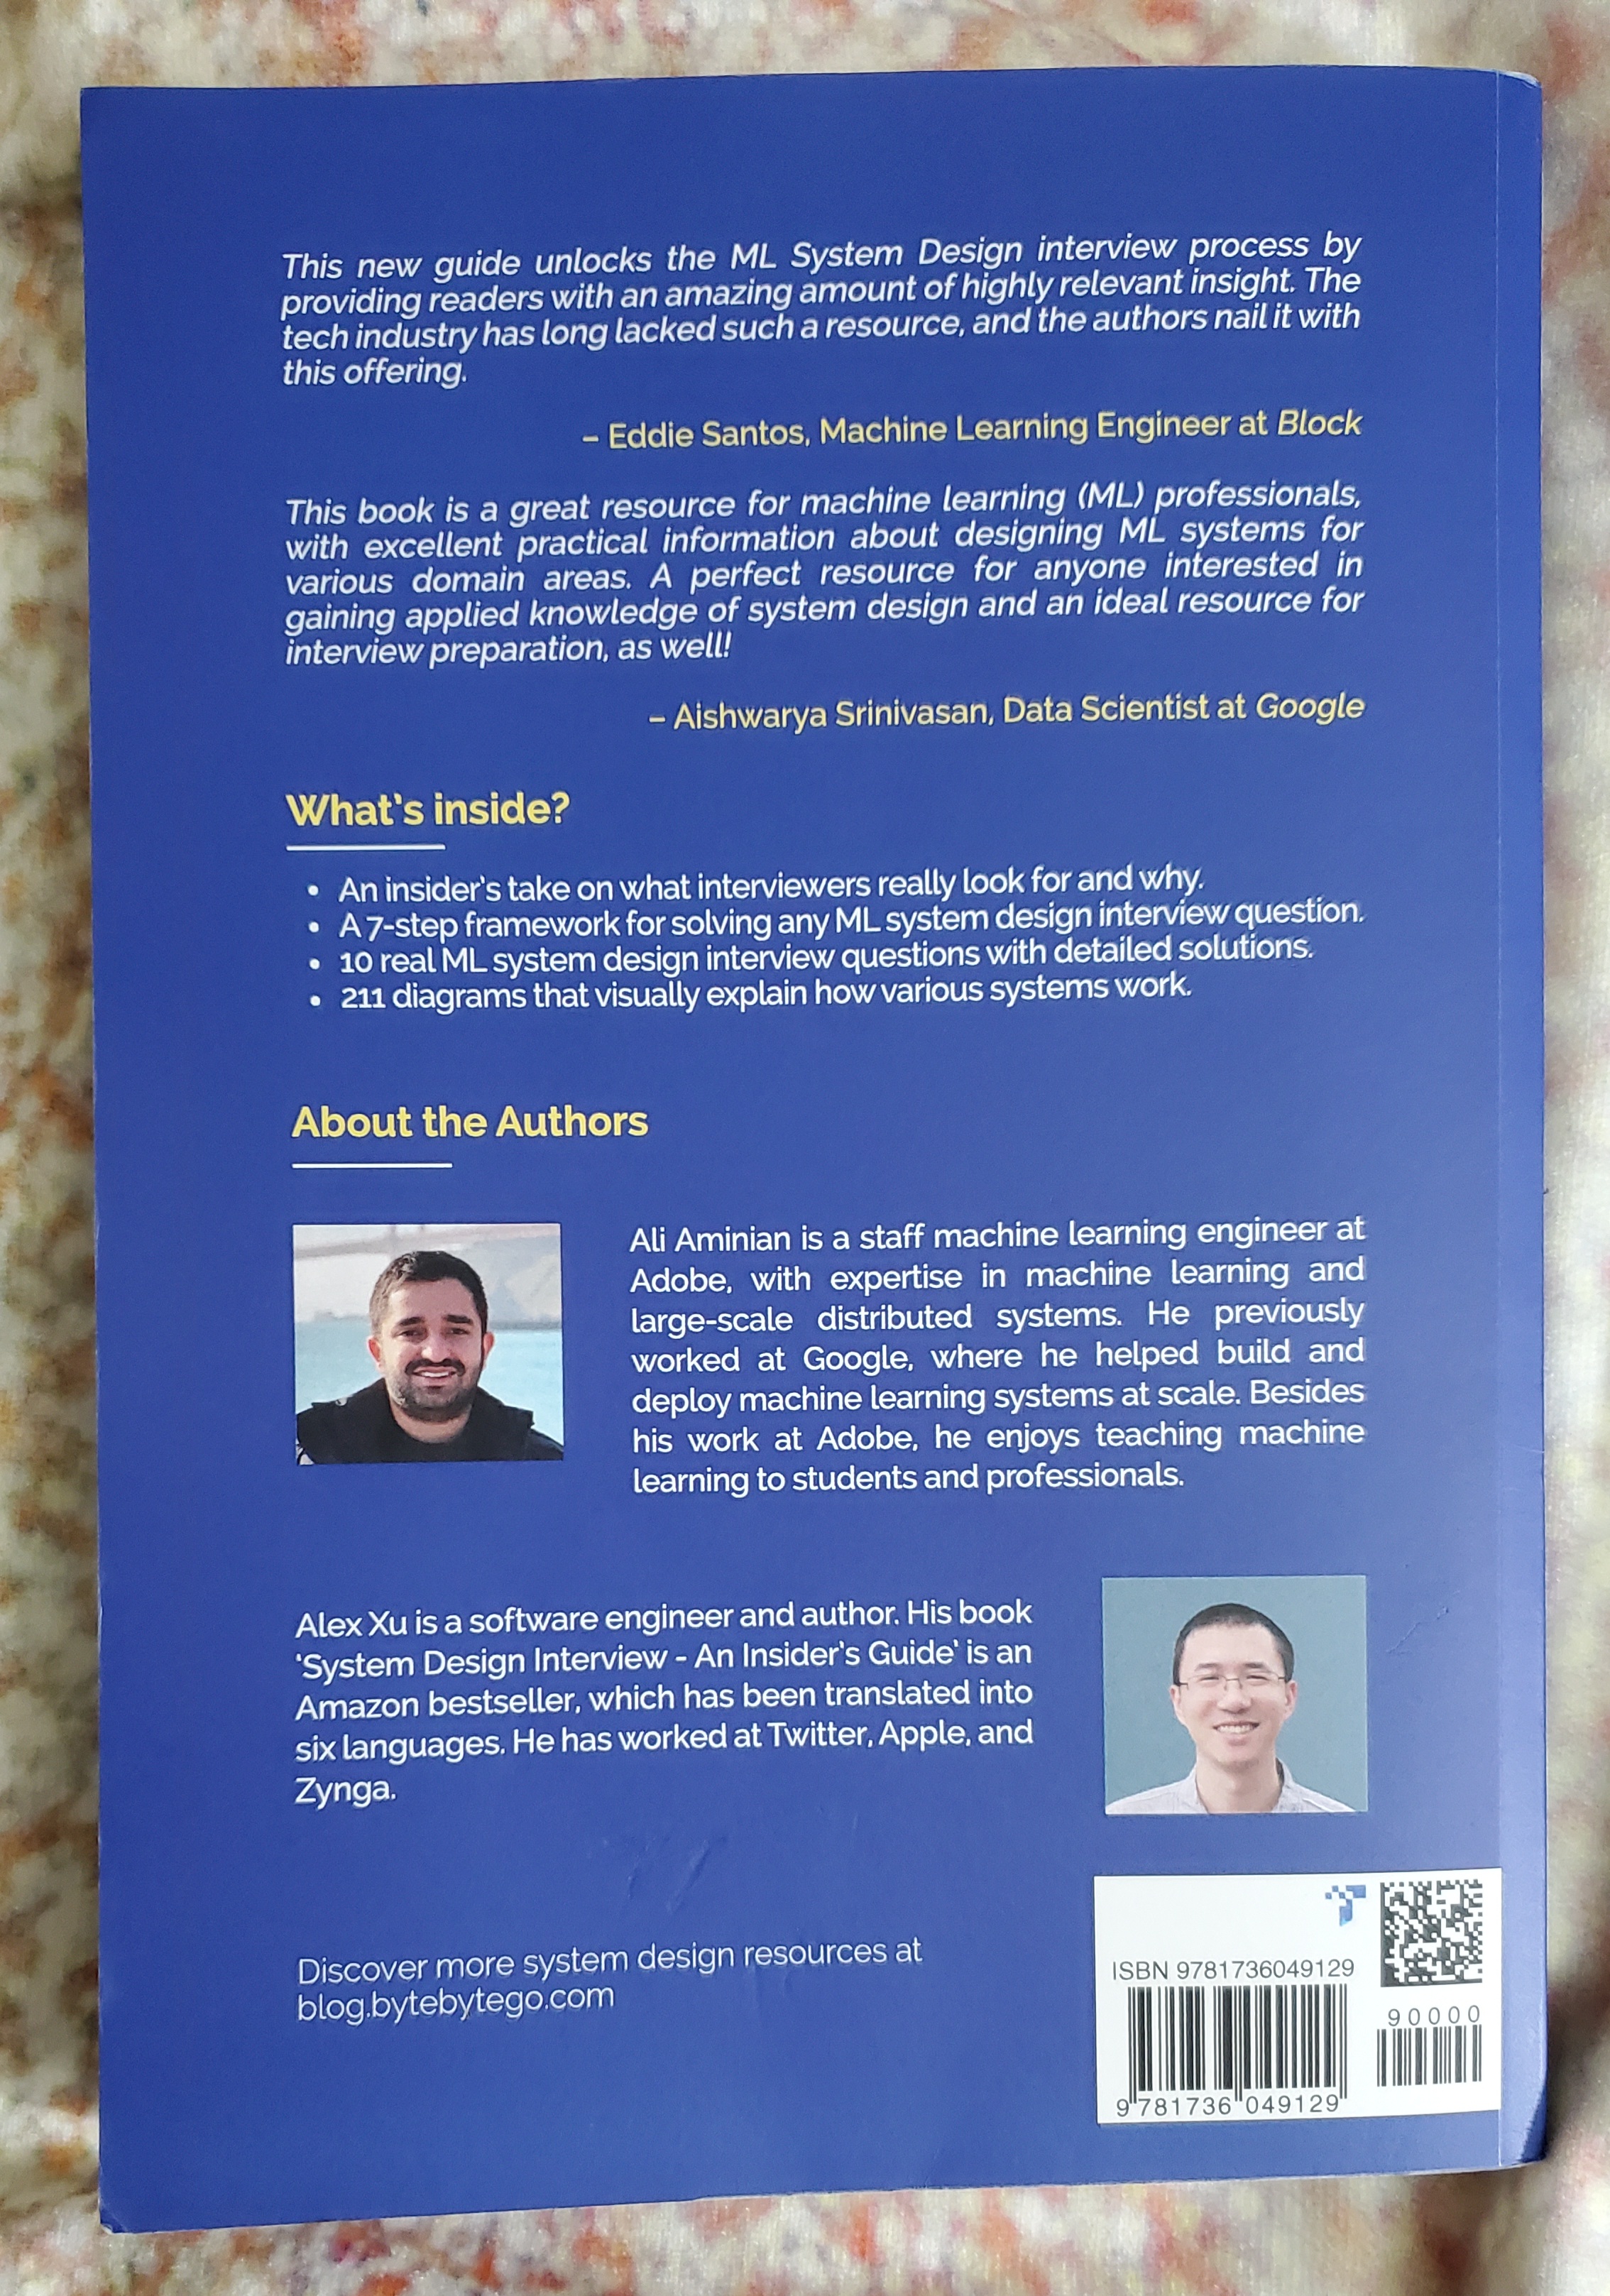
The book by Ali Aminian and Alex Xu is one of the more practical resources available for this topic. It covers end-to-end ML system design with a focus on real-world scenarios rather than pure theory. The pdf version circulates widely, though you should support the authors by purchasing an official copy if possible. Search terms like "Machine Learning System Design Interview By Ali Aminian Alex Xu Pdf" will surface various hosting sites, but quality and completeness vary. Make sure you verify the file is not watermarked or missing pages before you commit to reading it. What I found useful about this particular resource is that it doesn't treat ML system design as an abstract exercise. The examples walk through actual interview questions you'd encounter at companies like Google, Meta, or Uber. Each chapter breaks down a problem, shows the expected thought process, and explains the tradeoffs. The pacing feels like someone who has actually sat in those interviews and knows what interviewers are looking for.
The Core Topics You Need to Cover
I went through this material with a group of folks prepping for senior ML roles last year. We spent about six weeks covering the main domains, and I want to walk you through what matters most based on what actually comes up in interviews. Recommendation Systems comes up constantly. You need to be comfortable designing collaborative filtering pipelines, discussing two-tower architectures, and explaining how to handle item cold start. One question I kept getting was about designing a YouTube-style video recommendation system. The interviewer wasn't looking for a perfect solution, they wanted to see that you'd discuss candidate generation, scoring, ranking, and feedback loops as separate stages with different latency requirements. Natural Language Processing systems is the second most common track. Think about search ranking, chatbots, content moderation, or text classification at scale. I remember one interview where I had to design a real-time spam detection system for a messaging platform. The tricky part wasn't the model itself, it was handling the inference pipeline. We needed sub-100ms latency at millions of requests per minute. The initial approach of sending everything to a single GPU cluster was immediately shot down. Instead we discussed a tiered approach with a fast rules-based filter first, then a lightweight model for borderline cases, and only sending high-confidence spam requests through a heavier classifier.
Get the Full Details
Distributed Training is where a lot of candidates struggle. You should understand data parallelism, model parallelism, and pipeline parallelism at a conceptual level. Know when each approach makes sense and what the communication overhead looks like. An edge case I hit recently involved a training job that kept failing due to gradient synchronization bottlenecks across 64 GPUs. The workaround was implementing asynchronous SGD with stale gradient tolerance rather than fighting to keep everything perfectly synchronized, which cut our effective training time by roughly forty percent. Model Serving and Deployment rounds out the major topics. You need to discuss online versus offline inference, batch scoring, model versioning, canary deployments, and rollback strategies. Feature store architecture is another thing that keeps coming up, especially at larger companies. Understanding how features are generated, stored, and served consistently between training and inference is critical because training-serving skew is still one of the most common production failures I see.
Common Mistakes I See in These Interviews
The biggest mistake people make is jumping straight into model selection. Interviewers don't care that you know the difference between XGBoost and a neural network if you haven't first clarified the problem statement, the data available, the latency requirements, and the evaluation metric. Start with the constraints. Always start with the constraints. Another pitfall is ignoring the feedback loop. In any production ML system, the model's predictions affect future data, which affects future training. If you're designing a recommendation system and don't discuss how user interactions feed back into the training pipeline, you'll look naive. This is especially important for reinforcement learning from human feedback setups where the labeling infrastructure itself becomes part of the system design. A third common error is not quantifying anything. Estimates matter. When asked about storage requirements for embeddings, give a number. When discussing inference throughput, provide a rough calculation. I once designed a system for processing twelve million images per day for visual search. I estimated embedding dimensionality at three hundred eighty-four, which gave us roughly forty-six gigabytes of storage for raw embeddings, plus another thirty percent for indexes. The interviewer asked follow-up questions about approximate nearest neighbor libraries, and I knew to mention FAISS versus ScaNN tradeoffs right away.
How to Actually Prep Using This Book
Don't just read it passively. Work through each chapter and actually write out your design on paper or a whiteboard before looking at the suggested solution. The skill here is articulating your thinking, not memorizing answers. I timed myself doing three full design problems per week for six weeks, and it made a noticeable difference in how smoothly I could think out loud during actual interviews. Pick one problem a day. Read the question. Spend fifteen minutes outlining your approach without any reference material. Then write out a detailed design covering data collection, feature engineering, model selection, training strategy, serving architecture, monitoring, and iteration. After that, compare your approach to what the book suggests. Note where you missed something, where you overcomplicated things, and where your reasoning was sound but unclearly communicated. The chapter on designing a fraud detection system was particularly useful for me. I initially focused too much on the model's precision and recall without discussing how false positives impact the customer experience. The walkthrough showed how to incorporate business costs into the system design, which completely changed how I approached subsequent problems. From then on, every design I presented started with a brief cost-benefit analysis before diving into technical details.

What This Resource Doesn't Cover Well
No single book is complete. The Aminian and Xu material focuses heavily on batch-oriented ML systems and classic architectures. It doesn't go deep into large language model serving, which is increasingly common in newer interviews. If you're targeting companies working with LLMs, you'll need supplemental reading on prompt engineering pipelines, token optimization, context window management, and inference scaling strategies. The book also skimps on MLOps tooling specifics. Knowing the conceptual difference between Kubeflow and Vertex AI is fine for an interview, but understanding how to actually set up feature stores with Feast or Tecton gives you a stronger foundation if interviewers drill into implementation details. Pair this reading with some hands-on experience deploying models through something like SageMaker or KServe so you can speak concretely about containerization, autoscaling, and health checks. Bottom line: Use the Machine Learning System Design Interview By Ali Aminian Alex Xu Pdf as your backbone study material, supplement it with recent LLM-focused content, and practice designing systems under time pressure until the process feels mechanical rather than exhausting.