
Let's talk about how ML actually moves from "we trained a model" to "the model is doing something useful."
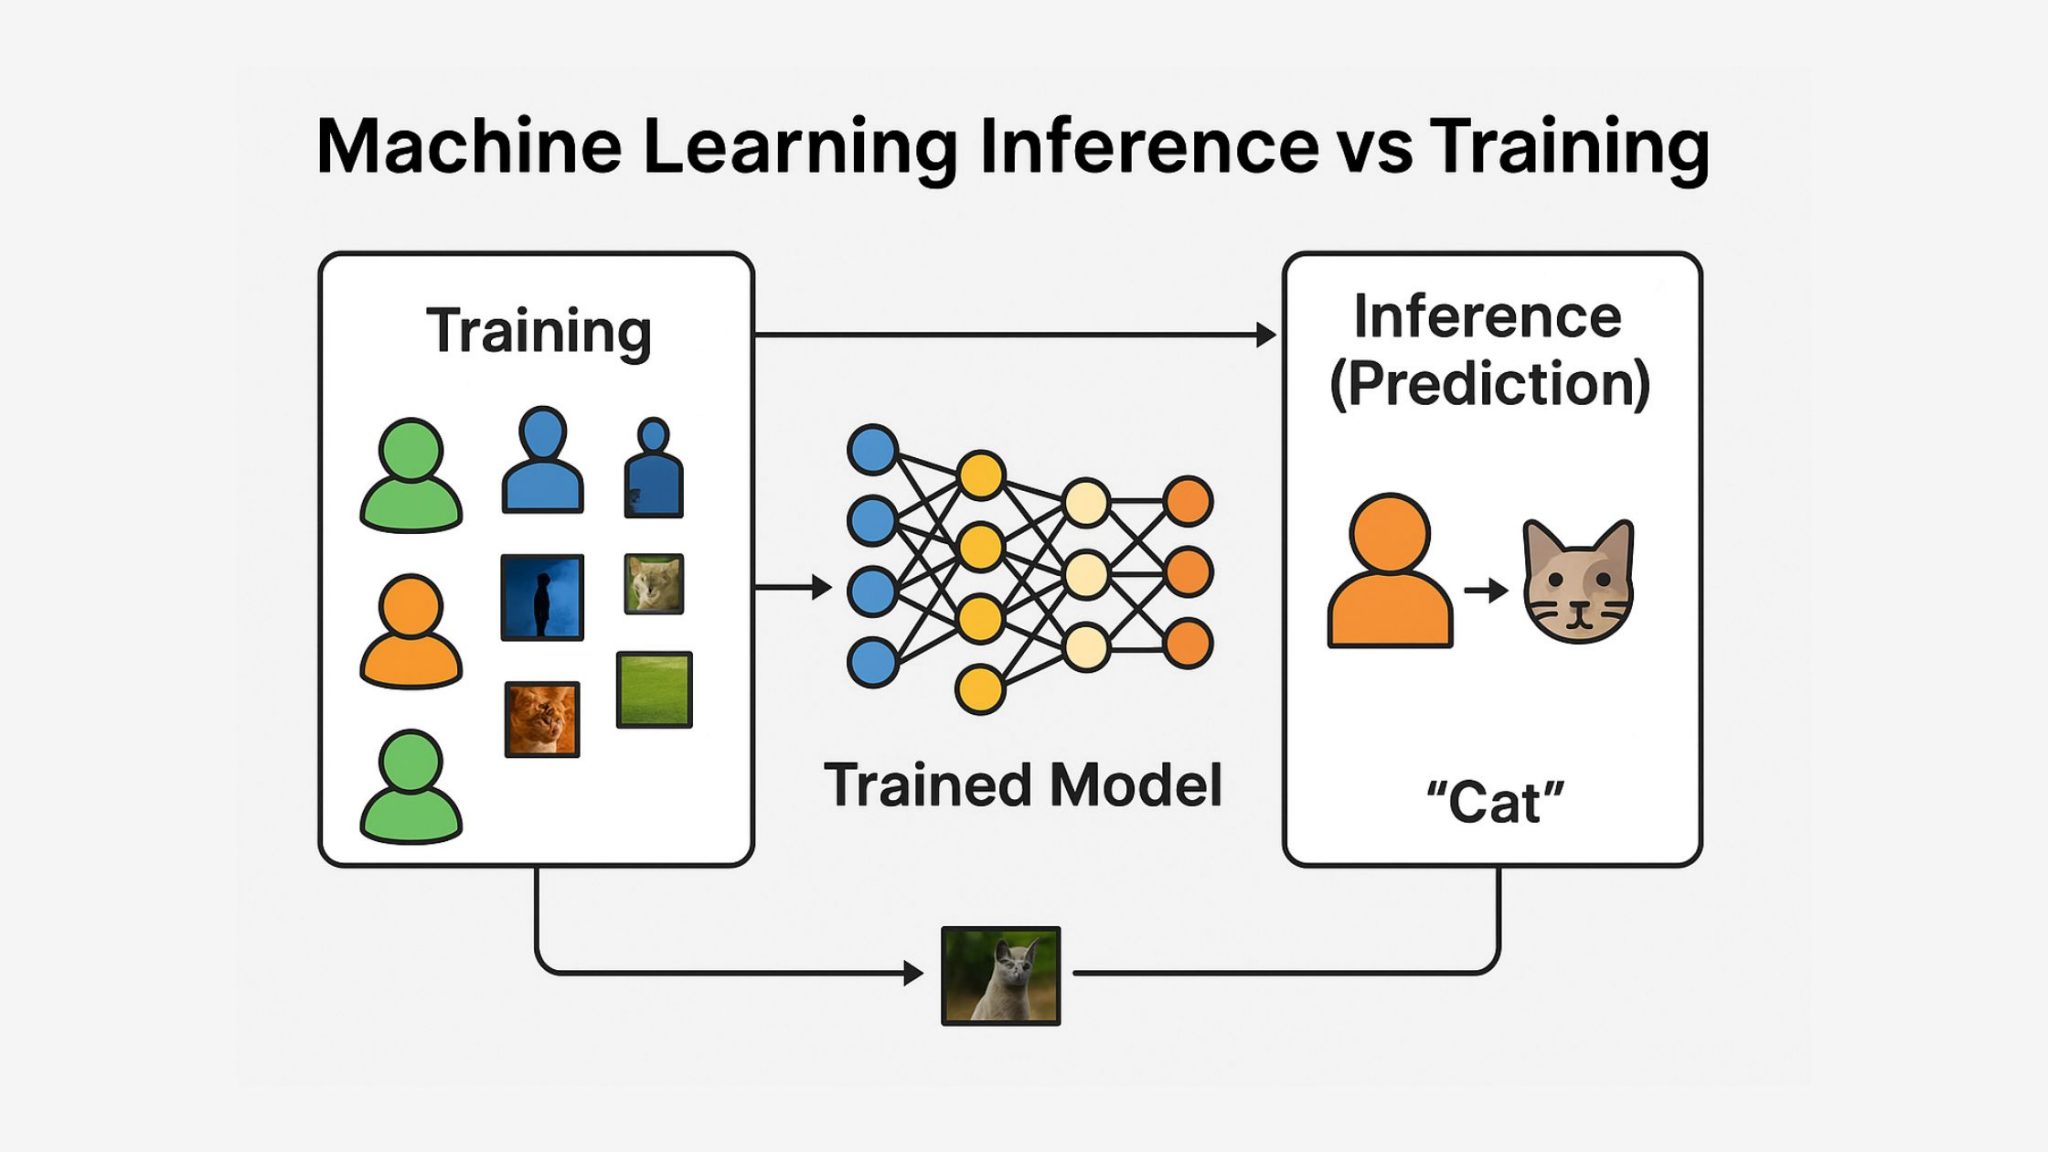
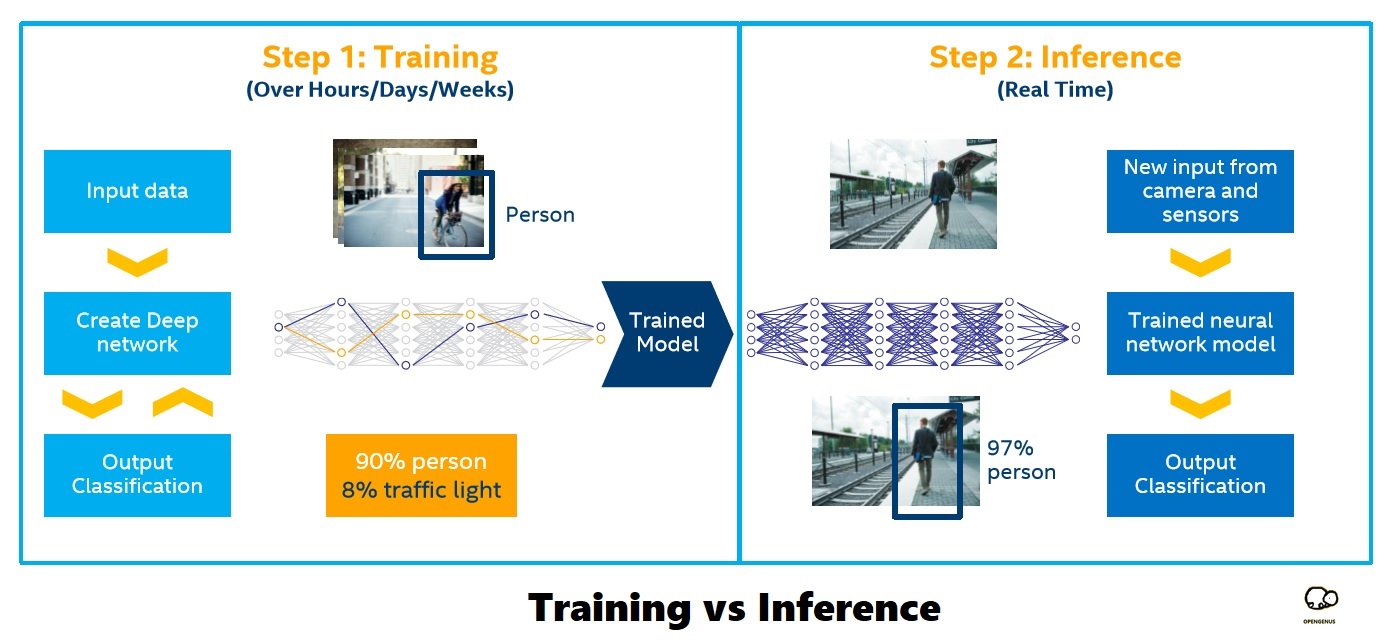
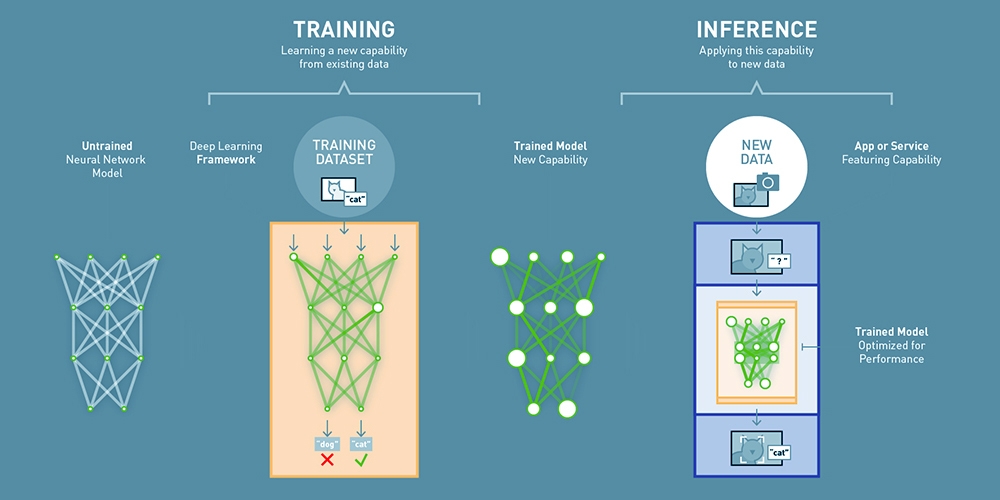
Training and inference are two completely different phases of the machine learning lifecycle, and treating them as interchangeable is one of the most common mistakes I see. Training is where you feed labeled data through a model, compute loss, propagate gradients backward, and update weights. Inference is where you take a fully trained model and run new data through it to produce predictions. That's the textbook version. The real version involves way more infrastructure decisions, memory trade-offs, and places where things quietly break. During training, you're juggling multiple GPUs or TPUs, mixed precision, gradient accumulation, checkpointing, and data pipelines that never seem to keep up with the compute. A typical modern training run might involve tens or hundreds of GPU hours, petabytes of data flowing through custom dataloaders, and loss curves that look nothing like what the papers showed. You're spending money on cloud compute or maintaining an on-prem cluster. The goal is to minimize loss on a validation set while hoping the model doesn't overfit or diverge.
Machine Learning Training Vs Inference: What Actually Changes
Inference strips almost all of that away. No backward pass, no gradient computation, no optimizer state, no checkpointing. You're doing a forward pass through frozen weights and getting outputs. The computational cost drops by orders of magnitude. A model that took 48 hours to train on eight A100s might produce a single prediction in under 50 milliseconds on a single GPU—or even a CPU, depending on the model size. But the simplicity of inference is deceptive. The infrastructure around it is where people get burned. Serving a model isn't just loading weights and calling .predict(). You need request batching, model warmup, memory management, latency optimization, and often some form of quantization or pruning to make it feasible to run at scale. A raw PyTorch model checkpoint is not a production-ready inference engine. It's not even close.
The Training Pipeline in Practice
Here's what a real training workflow looks like, minus the marketing fluff. You start with data cleaning and preprocessing, which eats up more time than anything else. Then you set up your training loop with a dataloader, a model, an optimizer, a loss function, and a schedule for the learning rate. You watch the loss go down. It sometimes goes up. You check for overfitting. You adjust. You checkpoint periodically because hardware fails and experiments die. Mixed precision training (FP16 or BF16) is standard now. It cuts memory usage roughly in half and speeds things up on modern GPUs, but it introduces numerical stability issues that don't show up in FP32. Your loss might suddenly become NaN and you'll spend two days figuring out whether it's the learning rate, the gradient clipping, or a bad batch of data. Gradient checkpointing trades compute for memory by recomputing activations during the backward pass instead of storing them. Useful when you're pushing the limits of GPU memory. Costs about 20-30% more training time. I once spent an entire week debugging a training run where the model was converging normally on a single GPU but diverging across eight GPUs in a distributed setup. Turned out to be a data parallelism issue—the random seed wasn't being set consistently across processes, so each GPU was seeing a different data order, which interacted badly with the batch normalization layers. The fix was straightforward: set a fixed seed per worker and use a deterministic data loader. But identifying it took forever because the symptoms looked like a learning rate problem.
Get the Full Details
The Inference Side: Where Things Get Complicated
After training finishes, you have a model checkpoint. Usually a collection of weight tensors saved in formats like PT, SAFETENSORS, or ONNX. That checkpoint lives on a disk somewhere. It doesn't do anything until you build an inference pipeline around it. The first decision is how to serve the model. Are you running it on a GPU server, a CPU fleet, edge devices, or in a browser? Each choice comes with different constraints. GPU inference gives you speed but costs money. CPU inference is cheaper but slower. Mobile and edge require quantization to INT8 or even lower precision because those devices don't have the memory bandwidth for full precision weights. Quantization is where training and inference start to meaningfully diverge. A model trained in FP16 can often be quantized to INT8 for inference with minimal accuracy loss. That's called post-training quantization. But for some architectures, especially transformers and large language models, PTQ isn't enough. You need quantization-aware training, which means going back into the training loop and simulating quantization noise during training so the model learns to be robust to it. This usually costs another few days of training time and can reduce final accuracy if not done carefully.
I had a project where we trained a computer vision model for defect detection and got 97% accuracy in training. After quantizing to INT8 for deployment on edge hardware, accuracy dropped to 89%. The model had learned features that were sensitive to small weight perturbations. The workaround was to retrain with quantization-aware training for two additional epochs, which brought accuracy back to 96%. It's a reminder that quantization isn't a free lunch—it's a trade that requires its own tuning process.
Throughput, Latency, and Batching
When you're serving inference at scale, two metrics matter: latency and throughput. Latency is how long a single request takes. Throughput is how many requests you can handle per second. They often pull in opposite directions. Larger batch sizes improve throughput but increase latency per request. Smaller batches reduce latency but waste GPU compute on underutilized cores. The sweet spot depends entirely on your use case. A chatbot needs low latency—you can't have users waiting three seconds for a response. A batch processing job that analyzes documents overnight cares about throughput, not latency. You might batch 64 or 128 requests together and process them in parallel, sacrificing individual request speed for overall efficiency. Model compilation tools like TensorRT, OpenVINO, and TorchInductor can optimize inference by fusing operations, eliminating redundant computations, and choosing better memory layouts. These can cut inference latency by 30-60% on the same hardware. But they require converting your model to their format, which sometimes breaks functionality if your model uses custom layers or dynamic control flow that the compiler doesn't support.
The Hidden Gap Between Training and Inference Data
This is the part nobody warns you about. Your training data and your inference data are rarely processed identically, and that mismatch causes silent failures. A normalization statistic computed on the training set might not match the distribution of your production data. A tokenizer trained on one corpus might handle edge-case inputs poorly. An image preprocessing pipeline that resizes and crops during training might behave differently when fed raw production images. I once deployed a model where the training pipeline used aggressive data augmentation—random cropping, color jitter, rotation. The inference pipeline didn't use any of that because it wasn't needed. The model performed great during validation but poorly in production because it had learned to rely on augmented features that weren't present in real-world inputs. The fix was to add a minimal set of inference-time transformations that matched the statistical properties of the training augmentations, essentially doing a lightweight version of the same preprocessing during prediction. Data drift compounds this problem. Production data changes over time. Customer behavior shifts. New product categories appear. A model trained on last year's data might slowly become less accurate as the underlying distribution evolves. Monitoring for drift isn't optional—it's required. You need to track input distributions, prediction confidence, and downstream metrics continuously. When drift exceeds a threshold, you retrain.
Memory and Compute Requirements Compared
Training requires significantly more resources than inference. A transformer model trained with 7 billion parameters might need 28GB of GPU memory just for the weights in FP32. Add optimizer states (Adam maintains first and second moment estimates, doubling memory), gradients (another full weight copy), and activation memory for the forward pass, and you're looking at 100GB+ for a single training step. That's why distributed training across multiple GPUs is nearly mandatory for large models. Inference for the same model in FP16 needs about 14GB. In INT8 quantization, roughly 7GB. The reduction is dramatic because you eliminate optimizer states, gradients, and activation memory entirely. You're only storing the weights and computing a forward pass. There's a middle ground called progressive serving, where you load a lower-precision version of the model for most requests and only load the full-precision version when the model is uncertain or when requests come from high-priority users. This saves money on inference infrastructure without noticeably degrading quality for the average user. It's more common in production systems than you'd expect.
Deployment Patterns
The way you deploy inference depends on your traffic patterns. For steady, predictable traffic, you can run a dedicated serving instance and keep it warm. For spiky or unpredictable traffic, autoscaling is necessary but introduces cold-start latency—the time it takes to load a model into memory when a new instance boots. Cold starts can range from 30 seconds for small models to several minutes for large ones. Serverless inference platforms like AWS Lambda with GPU support or Modal abstract away the infrastructure but introduce their own constraints. Maximum execution time, memory limits, and cold-start penalties mean you can't just drop a massive model into a serverless function and expect it to work well. You need to size your model and your environment carefully. For real-time applications, you often need to cache predictions or use request batching to smooth out traffic spikes. A model that can handle 100 requests per second might collapse under 200 if each request requires a full model forward pass. Batching five requests into a single forward pass reduces the per-request overhead and keeps latency acceptable.
Monitoring After Deployment
Training has clear stopping criteria: validation loss plateaus, you hit a target accuracy, or you've run out of compute budget. Inference has no natural endpoint. The model keeps running, producing predictions, and the quality can degrade in ways that aren't immediately obvious. A model that was 95% accurate at deployment might drift to 82% over six months without anyone noticing if you're not monitoring it. You need to track prediction distributions, not just accuracy. Accuracy requires labels, and labels are expensive to collect in production. Prediction distributions are free—they're just the model's outputs. If the distribution shifts significantly from what you saw during validation, that's a signal that something is wrong, even if you haven't received any labeled feedback yet. Retraining pipelines should be automated. Manual retraining is unreliable—people forget, environments change, and the model degrades silently. Set up a pipeline that triggers retraining when drift is detected, validates the new model against the old one, and can be rolled back if the new model performs worse. This is standard MLOps practice, but it's also where most teams fall short.
Cost Considerations
Training costs are front-loaded. You pay for compute upfront, usually in a concentrated burst over hours or days. Inference costs are ongoing. A model that costs $500 to train might cost $2,000 per month to serve at scale, depending on traffic volume and infrastructure choices. For high-traffic applications, inference costs can exceed training costs by an order of magnitude over the model's lifetime. Optimizing inference cost is usually about reducing compute per request. Quantization helps. Model distillation—training a smaller model to mimic a larger one—helps. Pruning unnecessary weights helps. Architectural choices during training matter for inference cost because a model with more parameters or a deeper architecture will always cost more to serve, regardless of optimization. There's also the human cost. Training requires ML engineers who understand distributed systems, numerics, and optimization. Inference requires engineering skills that overlap with traditional software deployment—load balancing, caching, CI/CD, monitoring. The skill sets are related but distinct, and teams that treat inference as an afterthought often find themselves struggling with operational issues that could have been designed around from the start.
What Most People Get Wrong
The biggest misconception is that training and inference are symmetric. They're not. Training is about discovering a good set of weights. Inference is about deploying those weights efficiently and reliably. The skills, tools, and infrastructure for each phase are quite different. A model that trains well doesn't necessarily serve well, and a model that serves efficiently might have been trained poorly. Another misconception is that inference is simple because it's "just forward propagation." The simplicity of the computation hides the complexity of the surrounding system: loading, preprocessing, batching, compiling, serving, monitoring, scaling, updating. Each of these pieces can fail independently, and they fail in production in ways that are much harder to diagnose than training failures. The models that perform best in practice aren't necessarily the largest or most accurate on paper. They're the ones where the training and inference pipelines are designed together, where deployment constraints influenced the architecture choice, and where monitoring catches problems before users do. That integration between training and inference is what separates a prototype from a product.

Practical Steps to Bridge the Gap
If you're building a system that moves from training to inference, here's what actually works. Export your model to an intermediate format like ONNX during training, not after. Validate the ONNX model against your original framework to ensure numerical parity. Run quantization benchmarks on the exported model before committing to a precision. Set up a minimal inference server early in the development process, even if it's just a local test, so you understand the latency and memory characteristics of your model in a serving context. Monitor your training data pipeline for the same kinds of drift you'll see in production, because the training data is your proxy for what the model should see at inference time. And when the model does fail in production—and it will—have a rollback plan that lets you revert to the previous version within minutes, not hours. Training gives you the model. Inference makes it useful. Both phases matter. Neither is complete without the other.

