Why Most People Waste Months on Outdated Tutorials
The machine learning landscape shifts hard every single year. A tutorial you followed in early 2023 might have already been completely wrong by mid-2024. Models changed, libraries restructured, best practices flipped overnight. That is the basic reality nobody wants to hear. I spent about eighteen months building production systems before I accepted that following someone else's guide without a critical filter was the single biggest bottleneck in my workflow. You can download a fresh Machine Learning Tutorial Yearly that actually accounts for these changes, but you still have to know what questions to ask before you trust any of it.
Machine Learning Tutorial Yearly
This is a yearly updated resource framework rather than a single product. You will find collections of guides, notebooks, and walkthroughs that are supposed to reflect the current state of the field. The problem is that even the ones claiming to be current often lag six to nine months behind real practice. PyTorch released new tensor capabilities. TensorFlow deprecated entire API surfaces. Hugging Face changed their model loading conventions twice in a single year. If your tutorial was written before those events, you are already behind. Here is what I actually do before I start following any tutorial path. I check the publication date first. Then I cross-reference the library versions mentioned in the code against what is currently pinned in the latest stable releases. Most tutorials list tf.version 2.14 while the current stable is past 2.17. The code breaks immediately if you follow it blindly. I fix this by creating a separate conda environment and explicitly installing the versions the tutorial originally used. It takes maybe twenty minutes and saves you from three hours of debugging errors that are nothing more than API drift. I ran into a particularly ugly case last fall when a popular tutorial claimed to show a proper fine-tuning workflow for a vision transformer. The code used torch.compile with a specific profiler configuration that silently produced incorrect gradients on certain GPU architectures. The tutorial author never noticed because they were running on a different hardware setup. I caught it when validation loss started increasing during fine-tuning instead of decreasing. The workaround was straightforward: I disabled torch.compile, switched to standard eager execution for the training loop, and verified the gradient flow by printing the norm of the gradients at each layer. Something that should take an hour of debugging cost me a full afternoon because the tutorial was technically recent but practically broken.
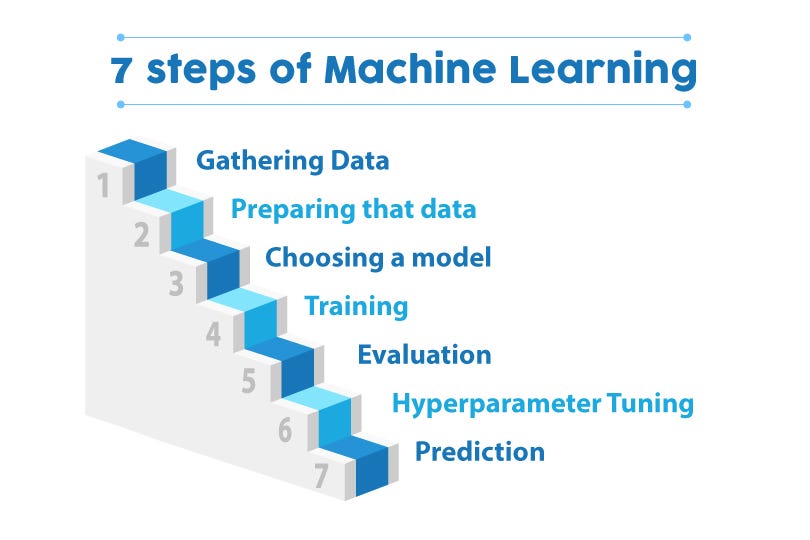
The bigger issue nobody talks about is that most tutorials teach you the happy path. They show you loading a dataset, training a model, and achieving decent accuracy on a held-out test set. They never explain what happens when your labels are noisy, your training distribution does not match your inference distribution, or your model simply overfits because you did not validate early enough. I recommend building a deliberately broken version of whatever project the tutorial describes before you consider yourself competent. Corrupt ten percent of your training labels randomly. Split your data by time rather than randomly. Introduce a class imbalance that makes the model trivially accurate by just predicting the majority class. These exercises teach you more than a perfect five-step walkthrough ever will. Another counter-intuitive thing I learned the hard way: writing your own small implementations from scratch is often more educational than following a polished tutorial. When you build a simple neural network from numpy or a basic attention mechanism without any library shortcuts, you understand the mechanics well enough to spot when a tutorial is glossing over important details. I found this out when a tutorial casually skipped the learning rate warmup step for a transformer model and blamed poor performance on insufficient epochs. The model needed warmup, not more training. A pure tutorial follower would likely never have caught that. Not everything in these yearly resources is trustworthy. Some sites recycle old content under new dates without actually updating the material. The model cards they reference might point to archived repositories. The performance numbers they claim are impossible to reproduce on modern hardware. I have seen tutorials advertising ninety-five percent accuracy on datasets where the current SOTA is around eighty-eight percent using entirely different evaluation protocols. Always verify claims independently.
Get the Full Details
When I evaluate whether a Machine Learning Tutorial Yearly collection is worth my time, I look for three things. First, whether the author includes a known issues section that acknowledges what might break. Second, whether the code is available in a public repository with open issues where you can see real problems being discussed. Third, whether the tutorial includes any discussion of failure modes or limitations rather than just presenting a success story. Most resources fail on all three counts. A practical recommendation that usually works better than following a tutorial linearly: pick a small project you actually care about and use tutorials as reference material rather than as step-by-step instructions. When you hit a specific problem, look up the tutorial section relevant to that problem. This approach forces you to engage with the material actively instead of passively copying code that you do not fully understand. You will learn slower in some sense because you cannot rush through, but the knowledge sticks and you become better at troubleshooting independently. The field moves too fast for any single tutorial to remain correct for long. The best approach is to treat yearly tutorial collections as starting points and maps rather than authoritative guides. You need to verify versions, test edge cases, and build your own broken experiments. The tutorials will save you initial setup time but they will not replace the judgment you develop through hands-on work with real problems.