What Macro Level Of Analysis Actually Means
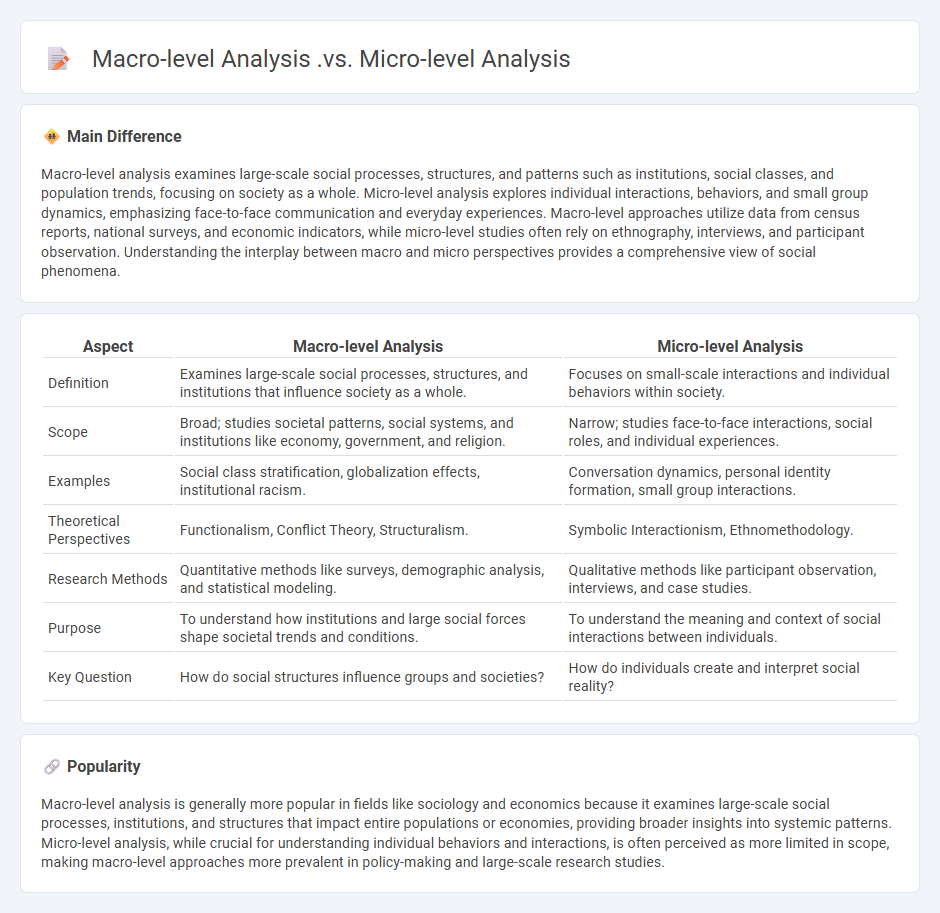
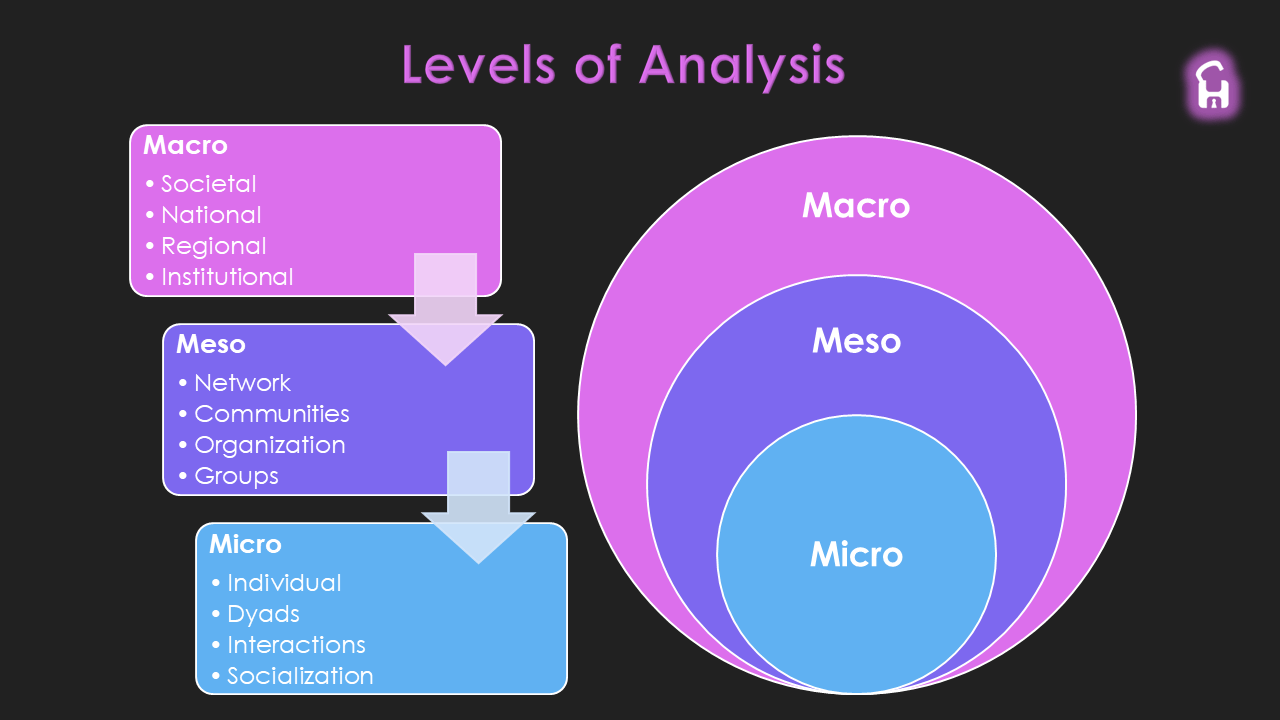
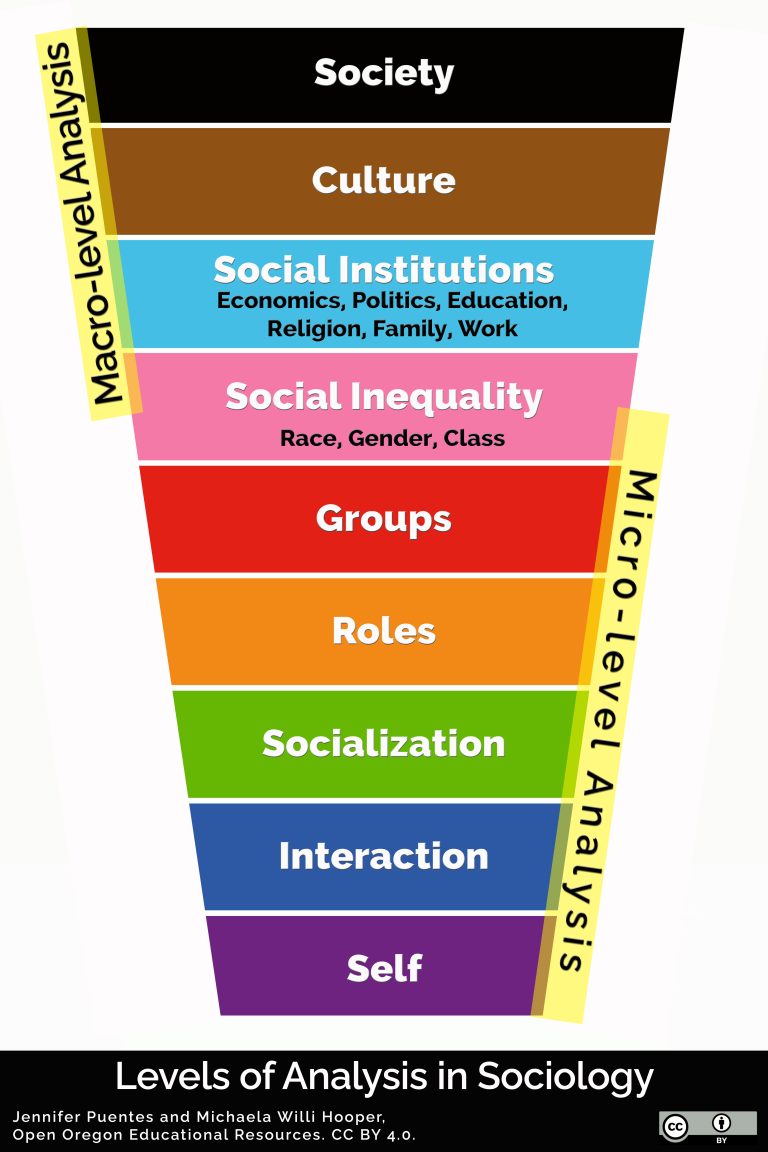
I keep seeing people conflate macro analysis with just looking at big numbers. That is not the same thing. Macro Level Of Analysis means you are intentionally stepping back from individual cases to see patterns across entire populations, organizations, or systems. You stop asking what happened to one person or one company and start asking what is happening to groups, sectors, or nations. This matters because some questions cannot be answered at the individual level. They only become visible when you zoom out. Most beginners jump straight into statistical software and run regression models on whatever dataset they can find. This usually produces noise rather than insight. The better path is to start with your research question, then work backward to what kind of data can answer it. I once spent three weeks building a model to explain regional economic growth and discovered too late that my independent variables were coded at the national level while my outcomes were measured at the city level. Ecological fallacy walked right in through the front door. I had to scrap the whole thing and rebuild with properly aggregated data. That cost me roughly forty hours and taught me to verify unit-of-analysis alignment before writing a single line of code. Macro Level Of Analysis requires you to think about scale explicitly. Are you studying countries? Industries? Generations? The unit you choose determines your data sources, your methods, and your validity threats. Pick it early. Write it down. Revisit it constantly.
How to Actually Do It
Start by mapping the system you want to study. Draw out the relevant actors, institutions, and feedback loops. Do not skip this step because it is the only way you will notice which variables matter at the aggregate level. Individual-level correlations often disappear or reverse when you look at the macro picture. That is called a cross-level paradox and it happens more often than most researchers admit. Once your system map is roughed out, identify the appropriate aggregate measure for each construct. Population-level vaccination rates, GDP growth, crime statistics, industry concentration indices, public opinion aggregates. These measures exist in datasets like the World Bank Open Data, OECD Statistics, UN databases, or national census bureaus. The problem is never finding them. The problem is ensuring the geographic boundaries, time periods, and definitions actually match what you need. A "manufacturing employment" figure from one country may count different workers than the same label in another country. You need consistency or you need to document your adjustments carefully. After data assembly, run descriptive analysis at the aggregate level before anything fancy. Look at distributions. Check for outliers. Compute basic correlations. If your data looks broken at this stage, complex modeling will not fix it. It will just produce more confidently wrong answers. Most people miss this and move straight to multilevel modeling or time-series analysis without checking whether their aggregate measures are even reliable.
Techniques That Work
Ecological regression is the most common approach. You correlate variables measured at the group level to test hypotheses about aggregate relationships. It works well for political science, epidemiology, and economics. But it carries a well-known limitation: you cannot infer individual-level behavior from group-level patterns. If a district with higher average income votes for a particular party more often, that does not mean wealthy individuals within that district are voting for that party. The reverse is also true. Individual voter records might show the opposite pattern entirely. This is the ecological inference problem and it is why people sometimes call it the ecological fallacy. Multilevel modeling, or hierarchical linear modeling, addresses this by nesting individuals within groups simultaneously. You can estimate both within-group and between-group effects in one framework. The downside is that it requires data at both levels. Not every project has access to individual-level observations alongside aggregate data. When you do have it, multilevel models are worth the extra setup time. They typically take two to three times longer to specify and validate than simple ecological regression, but they give you results you can actually interpret without falling into ecological inference traps. Time-series analysis at the macro level is another option. It works for countries, regions, or industries observed over many time periods. Granger causality tests, panel data models, and vector autoregressions are standard tools here. Panel data is particularly useful because it lets you control for unobserved heterogeneity across units. Fixed effects models absorb time-invariant characteristics that differ between units. Random effects models assume those characteristics are uncorrelated with your predictors. The Hausman test tells you which assumption is more reasonable for your dataset. Skip the test and pick randomly. Your coefficients will shift depending on which you chose and you will not know which is correct.
Get the Full Details
Things That Break Macro Level Of Analysis
Modifiable areal unit problem, or MAUP, is probably the single most destructive issue in macro research. Your results change depending on how you draw boundaries or aggregate data. Switch from counties to zip codes to census tracts and your correlations can flip direction. I worked on a housing affordability study where the significance of income-to-price ratios disappeared entirely when I moved from municipal boundaries to school district boundaries. The underlying data was identical. The aggregation was different. MAUP is not a minor inconvenience. It is a structural threat that can invalidate findings without warning. Another common failure mode is ignoring spatial autocorrelation. Nearby units tend to be more similar than distant units regardless of any causal mechanism you are testing. Standard regression assumes independence between observations. Macro data violates this assumption constantly. Neighborhoods affect neighboring neighborhoods. States affect neighboring states. Countries share shocks through trade and migration. If you do not account for spatial dependence using methods like spatial lag models or spatial error models, your standard errors will be understated and your significance tests will be too optimistic. You will find relationships that do not exist or miss relationships that do. Spatial econometrics tools in R packages like spatstat and plm or Stata commands like spreg and xsmle handle this, but they require understanding spatial weight matrices and choosing an appropriate specification. There is no automated default that is correct for every dataset.
When Macro Level Of Analysis Fails Completely
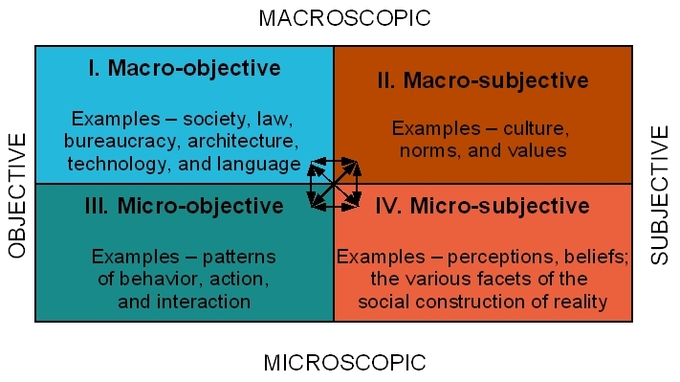
Sometimes the macro approach simply cannot answer your question. If you need to understand individual decision-making, individual-level methods are necessary. Macro analysis can tell you that higher education spending correlates with higher civic participation across countries. It cannot tell you whether educated individuals are the ones participating or whether educated individuals are being mobilized by specific institutional arrangements. For that, you need micro data and ideally an experimental or quasi-experimental design. Another scenario where macro analysis breaks down is when sample sizes are too small. Cross-national studies often end up with fewer than fifty units. That is barely enough for models with multiple predictors. Small N does not mean you should abandon macro analysis entirely. It means you need to simplify your models, use Bayesian approaches with informative priors, or focus on qualitative comparative methods like QCA. Mixed methods combining macro quantitative analysis with targeted case studies often produce the most defensible results when N is constrained.
Practical Workflow
Here is what a realistic workflow looks like after you have already learned these lessons the hard way. Define your unit of analysis and verify consistency across all data sources. Map spatial and temporal boundaries explicitly. Aggregate individual-level data only if you have the raw data available and you need it. Prefer existing aggregate datasets when possible because they are usually cleaned and standardized. Run descriptive statistics and check for MAUP by rerunning key models with alternative aggregation schemes. Test for spatial autocorrelation using Moran's I or Lagrange multiplier tests before modeling. Choose your estimation strategy based on data structure, not convenience. Report your unit of analysis, your aggregation method, and your spatial specification in the methods section. Every time. Readers and reviewers need to know what boundaries your results depend on. The macro level is useful when your question is about patterns across groups, systems, or populations. It is the wrong tool when your question is about mechanisms inside individuals. Knowing which is which and accepting that limitation is probably the most practical skill in this area. Everything else follows from that distinction.