
What You Actually Need to Know Before Walking Into a Mainframe Interview
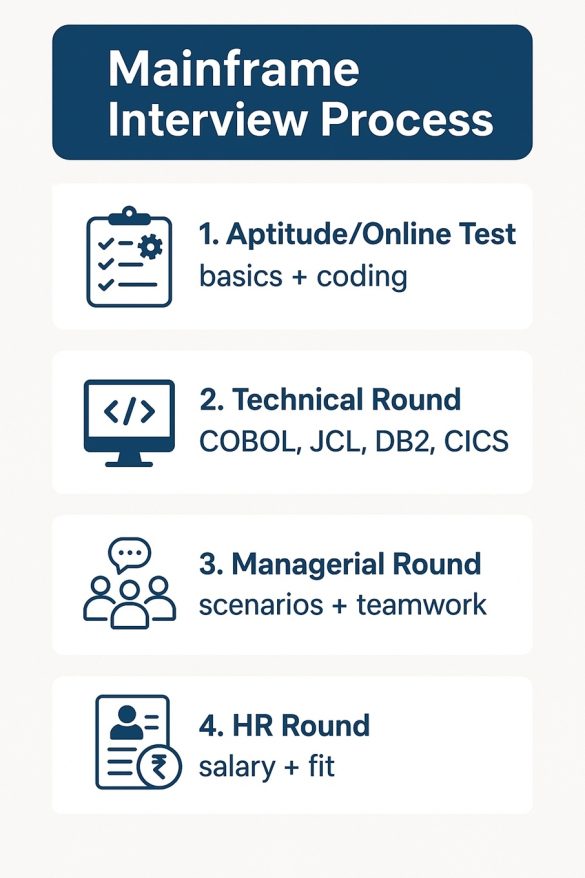
Most people walk into a mainframe interview with their Google Fu maxed out, having memorized three JCL snippets and a COBOL loop or two. It doesn't matter. I've sat on panels at three different companies and watched candidates recite perfect definitions for everything from SORT card syntax to VSAM KSDS structures, then immediately fail when asked to walk through a production problem. The question isn't whether you know the terms. The question is whether you've actually touched a machine that's been running since 1983 and kept it alive through a Friday night. Here are the questions I find myself asking, and more importantly, what I'm listening for in the answer. Walk me through how you'd troubleshoot a job that keeps abending with S0C4.
This is the bread and butter question. A Soc4 is a protection exception — someone tried to access memory they shouldn't have. The candidate should immediately mention checking the abend trace, looking at the register values, and specifically referencing the PC (program counter) value that points to the exact instruction that faulted. I've seen too many people jump straight to "maybe it's a null pointer" like we're debugging Java. On the mainframe, a null reference looks very different. I had a candidate once tell me to "add a null check before the READ" on a COBOL program that was pulling from a VSAM file. The file wasn't even the problem — it was a misaligned REDEFINES clause two paragraphs down. Point is, the answer isn't the first thing you think of. The answer is the systematic process of narrowing it down. Explain the difference between a PDS and a PDSE, and when you'd need one over the other. This sounds basic, which is exactly why people mess it up. A PDS is the traditional partitioned dataset — it has an index block and a directory block, and once it hits roughly 16,383 members, you start seeing performance degradation because the directory can't expand efficiently. A PDSE, introduced in z/OS 1.6, removes that ceiling and handles concurrent access better because it uses a different internal structure. The counter-intuitive part most people miss is that migrating from PDS to PDSE isn't just a ddname change. You need to validate your JCL because some older utilities don't handle PDSEs correctly, and if you're using IKJEFT01 or IKJBAT for interactive work, there are known compatibility quirks with certain ISPF panels.
You have a COBOL program that's processing a sequential file at 3 AM and it's running four times slower than it did last month. Where do you look first? Slow answers here are the real tell. First, I'd want to hear about the SORT output — were there recent changes to the sort areas or the sort work datasets? Second, I'd want to know if anyone updated the program's load module without going through the normal promotion path, which means it could be pulling in a mismatched copybook or linkage section. Third, check the system logs. I dealt with an issue like this at a previous employer where a COBOL batch job had gone from completing in 12 minutes to running for over an hour. We traced it to a changed LPAR configuration — someone had altered the CPU weighting on the system during a maintenance window and never reverted it. The job itself hadn't changed at all. Describe how you'd migrate data from a VSAM KSDS to a DB2 table, including the concerns you'd have.
Get the Full Details
A proper answer here involves more than just firing off an IDMS-style export and calling it done. I want to hear about key ordering. VSAM stores records in key sequence, and if the DB2 table doesn't have a matching index strategy, you're going to create a performance nightmare on the receiving end. I want to hear about REUSE versus TRUNCATE behavior in the LOAD utility. I want to know if they considered the ESDS or RRDS variants and whether the source data might have deleted keys that would cause issues with DELETE processing on the target. The actual mechanics — using DFSORT with the OUTREC verb to reshape records, or leveraging the DB2 INGEST command for bulk loads — that's the easy part. The part that shows experience is the data integrity checks. What is RACF doing when it intercepts a job that's trying to access a protected dataset? RACF operates at the security layer between the operating system and the resource request. When a job tries to open a dataset, RACF checks the user's authority against the dataset class definition — typically the DSN class. It evaluates the access level requested: READ, UPDATE, or CONTROL. If the user doesn't have the required permission, RACF returns an authorization failure and the system abends or the job steps with an appropriate message. The nuance people miss is that RACF also processes resource profiles with wildcards and overrides, and a user might appear to have no explicit authority but still gain access through a group profile or an alternate RACF id. I once spent two days tracking down why a particular operator could run a job that another operator with seemingly identical privileges could not. It turned out to be an alternate id situation buried in a class override.
Tell me about a time you had to optimize a COBOL program's performance and what you actually changed. This is where most candidates drift into vague territory. I want specifics. Did you restructure nested loops? Did you replace a sequential file access with indexed access? Did you find a redundant DISPLAY statement in a loop that was executing millions of times? I had a program that was processing claim files and taking nearly 40 minutes because every single record had an unconditional INSPECT statement running through the entire string to normalize case. The fix was to add a BEFORE WHEN clause that checked a flag byte first, which eliminated the INSPECT for roughly 70% of the records. That cut runtime from 40 minutes to about 11. How do you read and interpret a System Dump, and what's the first register you check?
On the mainframe, you're typically looking at an SLIP trace or a system dump generated by the operator or the SMF capture process. The first register matters depending on the abend code. For a Soc4, Register 1 typically holds the address that caused the fault. Register 15 contains the return code. Register 13 points to the save area chain, which lets you walk back through the called programs. The dump itself is printed in hex and ascii format, and you're looking for the instruction address in the PC field of the dump to identify which program statement failed. Most beginners try to read the dump linearly from top to bottom, which is useless. You go to the PCB and CSB sections first to understand the context of the failure, then trace back through the linkage stack. Explain how IPL works and what happens during a controlled restart. IPL, or Initial Program Load, is how you bring a z/OS system up from a cold state. It loads the bootloader from the control unit, which then loads the bootstrap program, which initializes the hardware and loads the operating system kernel. A controlled restart differs from a cold start in that the system preserves certain processor states and memory contents — particularly the CHPIDs and the I/O configuration. The JES2 or JES3 spooling systems are restored, and queued jobs are replayed rather than re-queued from scratch. What people don't always grasp is that a controlled restart assumes the hardware didn't change. If you swapped a disk controller or added a new CSS address, a controlled restart will fail and you need a full IPL instead. I've seen this happen after a hardware maintenance window where the engineers forgot to document a CSS renumbering.
What's the difference between BCD and ZONED format, and why does it still matter in 2024? BCD, or binary coded decimal, packs two decimal digits into a single byte using four bits each. ZONED decimal uses a full byte for each digit, with the high-order four bits being the zone — typically x'F' for unsigned numbers or x'D' for negative. This matters because legacy data moving between systems often carries implicit format assumptions. A program written to expect ZONED format will produce garbage if it receives BCD data, and the garbage doesn't look obviously wrong until it gets downstream. The classic example is a date field stored as packed decimal where a newer program reads it as zoned and interprets the zone bits as part of the digit values. You end up with dates like F0F1F2F3F4F5 instead of 202405, and the database load fails silently on the format validation. How would you set up a test environment for a COBOL-VSAM application without disrupting production?
The standard approach is to allocate separate VSAM clusters for the test environment and use JCL conditional processing or symbol substitution to point the program at the correct dataset. You'd use IDCAMS to define the test cluster with the same attributes as production but on a different volume serial. For the COBOL program itself, you'd compile and link-edit it under a test jobstream that references the test cluster. The critical piece most people overlook is the SMF reporting — if your test jobs write to the same SMF classes as production without proper tagging, you'll corrupt your capacity planning data. I've seen a test run generate enough SMF records to trigger an automated alert about production capacity being exceeded. What are the common pitfalls when working with COBOL REDEFINES, and how do you debug a bad one? A REDEFINES clause lets you define the same storage area under multiple names with different data structures. The pitfall is that COBOL doesn't validate the alignment between the original and the redefined fields at compile time. If the byte counts don't match exactly, or if you're redefining a numeric field with a display structure, the compiler won't stop you. It will just produce a program that runs and gives you wrong answers. Debugging involves tracing through the program with a debugger like Abend-Aider or the IBM Debug Tool, watching the actual bytes in memory as the program executes. I've fixed a bug this way where a REDEFINES was mapping a 10-byte numeric field onto a 12-byte alphanumeric field, causing it to spill into adjacent storage and corrupt a counter variable. The program produced incorrect results for exactly three out of every hundred transactions.
Explain what a Sysplex is and when you'd actually need one. A Sysplex is a cluster of two or more z/OS systems that work together as a single logical unit, connected by coupling facilities and a shared data space. The coupling facility handles lock management, cache coherency, and queuing across all the systems in the group. You need a Sysplex when your business requires uninterrupted processing — for example, a bank that can't afford to stop transaction processing during a system failure. With CF-based workload management and cross-system coupling, you can fail over a workload from one system to another transparently. The downsides are real though. A Sysplex requires significant upfront investment in coupling facility hardware, specialized staffing, and careful workload balancing configuration. For smaller shops, a single well-tuned z/OS system with proper redundancy often delivers more available uptime than a poorly configured Sysplex. How do you handle a production job that's stuck in the JES2 queue and blocking other critical work?

First step is identifying why it's stuck. Is it waiting on a resource — a dataset, a printer, a terminal session? Check the JES2 spool and see if the job has a hold condition or if it's sitting in a waiting state for a specific input. If it's a low-priority job holding up a higher-priority one, you can release the hold or adjust the priority class. If the job is actually running but taking an extremely long time, check the WLM (Workload Manager) classifier to see if it's being penalized by a misconfigured service goal. I had a situation where a nightly batch job was stuck in a TSO/E session limbo — someone had cancelled a task during execution but the task still held a lock on a dataset. The fix was to identify the task via the ISPF system panel, send a cancel signal with the appropriate force flag, and then restart the blocked job. Took about six minutes total, but the initial diagnostic phase took 40 because nobody documented the lock-holding procedure. What should you ask about a COBOL program's linkage section if you're inheriting someone else's code? The linkage section defines what parameters the program expects from its caller. Key things to check: are the parameters passing by reference or by value, which affects how you modify them inside the program. Are there any overlay issues where two parameters share the same storage area. Is the program using the CALL convention correctly, meaning the caller and callee agree on parameter ordering and type. I inherited a program once where the linkage section declared a parameter as COMP-3 (packed decimal) but the calling program was passing it as DISPLAY format. The program ran fine for positive numbers and produced wildly incorrect results for anything with a negative sign. Took a week to track down because neither programmer had tested the negative path.
Describe the process of applying a PTF (Program Temporary Fix) to a production system. The process starts with identifying the specific PTF number from the IBM support documentation, which maps to a particular APAR. You verify the PTF is applicable to your system by checking the prerequisite list — what other PTFs must be applied first, what z/OS version it targets. Then you schedule a maintenance window because applying a PTF typically requires taking the affected system offline or at least placing it in a restricted state. You use the SMP/E zone to receive and apply the PTF, which involves receiving the delivery media, applying the fix to the target zone, and then verifying the apply was successful with a report. After the PTF is applied, you often need to recompile dependent programs and re-IPL the system. The whole process for a single PTF on a moderately sized system takes anywhere from 45 minutes to two hours depending on dependencies and whether you need to rebuild load modules. What's your approach when a production job completes successfully but produces visibly wrong output?
A completed job with wrong output is harder to debug than an abend, because there's no explicit error signal. My first move is to pull the job's SMF 30 or 80 records to see the actual execution path — which programs ran, how long each step took, and what datasets were accessed. Then I compare the output against a known-good baseline from the previous run. I look for record count differences, field value differences, and sorting anomalies. In one case, a payroll job was producing correct-looking results but the OVERTIME calculations were off by exactly 8 hours across all employees. The bug was a single-character change in a COMPUTE statement where a multiplication by 1.5 had been accidentally changed to a division by 1.5. The job never abended. It just did the wrong math perfectly. How do you decide between using VSAM, VSAM with KDS indexing, and DB2 for a new data store? The decision depends on access patterns, transaction volume, and existing infrastructure. VSAM KSDS is appropriate when you need direct keyed access to a relatively static dataset with moderate update frequency. It's fast for sequential scans and random keyed reads but doesn't handle high concurrent update contention well. DB2 is the choice when you need complex querying, referential integrity, high concurrency, and SQL-based access. The tradeoff is that DB2 has a much heavier footprint and requires more specialized staffing. I've worked on systems where a VSAM dataset was the right answer — simple keyed access, predictable workloads, minimal ad-hoc querying — and the initial recommendation from the architecture team was DB2 because it was the trendy choice. Six months later, we were paying for DB2 licenses on a dataset that would have fit in a VSAM cluster for a fraction of the cost and with better performance.

What's the role of SMF in mainframe operations, and what are the most important record types to monitor? SMF, or Systems Management Facilities, is the primary source of operational data on a mainframe. It records everything: job execution, system events, resource usage, security violations, and performance metrics. The record types that matter most day to day are Type 30 for job summary data, Type 110 for dispatcher statistics, and Type 42 for storage management. For capacity planning, Type 70 and Type 71 give you CPU utilization at the processor and LPAR level. Type 43 records show I/O statistics. I rely heavily on Type 30 reports to track job performance trends over time. If a job that normally completes in five minutes starts taking 25, the SMF history will show whether it's a one-time spike or a gradual degradation pattern. How do you manage COBOL copybooks across a large codebase with hundreds of programs?
Copybook management is one of those things that seems straightforward until a change in one copybook breaks twenty programs. The standard approach is to maintain a centralized copybook library with version control, typically managed through a tool like Endevor or Panvalet. Every copybook change requires a documented reason, a reviewer, and a compatibility assessment. Before promoting a copybook to production, you should run a dependency analysis to identify all programs that include it. I found a tool configuration once where the dependency analyzer was skipping programs that referenced the copybook through a macro-extended INCLUDE statement rather than a direct INCLUDE. That meant 15 programs were never flagged when a critical copybook field length was changed, and the resulting compile-time errors didn't surface until the next deployment cycle. What's your understanding of CICS transaction processing, and when would you use it versus batch? CICS, or the Customer Information Control System, is a transaction processing monitor that handles online, real-time workloads. It's designed for high-volume, short-duration transactions — banking inquiries, reservation systems, order entry. Batch is for processing large volumes of data without user interaction, like end-of-day journal posting or monthly report generation. The line between them isn't always clean because CICS can invoke batch programs, and batch can invoke CICS transactions under certain configurations. I've seen organizations use CICS for everything because it's more flexible, which led to a CICS region that was handling both real-time customer queries and overnight reconciliation processing in the same address space. That's a recipe for resource contention. The right answer is to keep them separated: CICS for interactive work, batch for volume processing.
How do you handle a situation where a mainframe job is failing due to a storage constraint, but the allocation looks correct? Storage constraint failures in mainframe jobs are notoriously tricky because the allocation might look fine on paper but the system can't actually satisfy it at runtime. The first place to look is the JOB class in the WLM policy — the memory limits defined there might be tighter than the DD statement allocations suggest. Next, check the STORAGE class for the specific datasets involved. I had a job fail with a space allocation error even though the DD statements requested 50 tracks and the volume had 200 tracks free. The issue was that the job's storage class specified a minimum track count of 200 per dataset, and the system was trying to pre-allocate the full amount across multiple volumes simultaneously, which the volume management couldn't satisfy. Reducing the storage class constraint fixed it without changing any JCL. These questions cover the range from basic terminology to real troubleshooting scenarios. The candidates who do best are the ones who can talk through their thought process, not the ones who have memorized the textbook definitions. If you've actually worked on a mainframe — debugged an abend at 2 AM, tracked down a data corruption issue, or optimized a batch job that was eating into your overnight window — you'll recognize these scenarios and know how to approach them. If you haven't, no amount of studying the questions will substitute for that experience.

