Working with Probability Distributions in Practice
I spent three days debugging a model last year because I confused which distribution I was actually computing. The data looked fine, the code was correct, but the predictions were garbage. Turned out I was marginalizing over the wrong axis in a joint distribution with correlated features, and nobody caught it during review because the terminology is so similar. This happens more than you would think. The marginal distribution is what you get when you remove variables from a joint distribution by summing or integrating them out. For discrete variables, P(X=x) equals the sum of P(X=x, Y=y) across all possible values of y. For continuous variables, you integrate the joint density over the unwanted dimension. The result tells you the standalone behavior of one variable without caring about the others. The conditional distribution tells you how one variable behaves given that you already know the value of another. P(X=x | Y=y) equals the joint probability divided by the marginal probability of Y=y. It's a reweighting of the joint distribution, not a separate calculation.
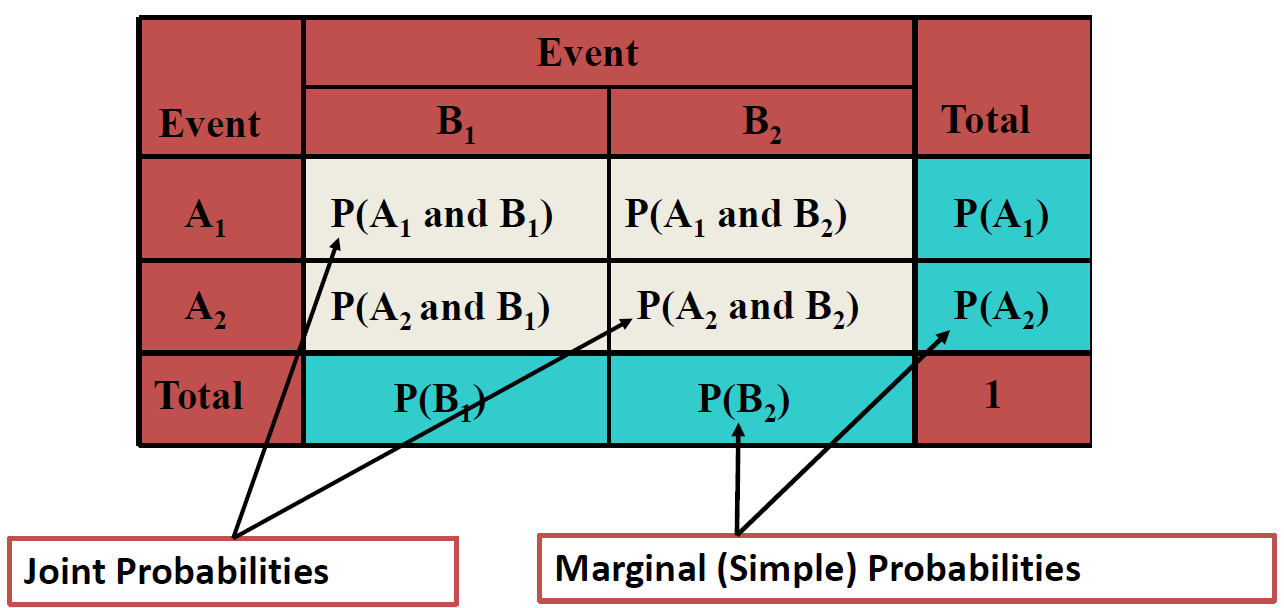
Here's the part most people gloss over: these two concepts are inverses in a specific algebraic sense. The joint distribution equals the conditional times the marginal. That relationship, P(X,Y) = P(X|Y) * P(Y), is the structural bridge between them. Once you understand that, converting back and forth becomes mechanical rather than conceptual. In practice, I calculate marginals by summing rows or columns in a joint probability table, or integrating numerically when working with continuous densities. For conditional distributions, I compute the relevant slice of the joint and normalize it by dividing by the corresponding marginal. This is usually fast for small tables but gets expensive quickly with high-dimensional data. I worked on a project involving network traffic analysis where I had a joint distribution across packet size and inter-arrival time with about 50 discrete bins in each dimension. The team needed the marginal distribution of packet sizes to set up a threshold detector. I simply summed across the inter-arrival time axis, which took about 15 minutes on a standard laptop. What tripped me up was that the bins weren't uniform width in the time dimension, so naive summation introduced bias. The workaround was to weight each bin by its actual width before summing, which corrected the marginal without changing the overall structure of the calculation.
For conditional distributions, I use the same joint table but extract a single row or column depending on which variable is conditioned, then normalize that slice. If I condition on inter-arrival time being in a specific bin, I take that row and divide every entry by the row total. The result is a valid probability distribution over packet sizes given that specific timing constraint. A counter-intuitive thing most beginners miss is that the marginal distribution does not capture the relationship between variables. Two completely different joint distributions can share the exact same marginal. If you only look at P(X), you lose all information about how X and Y interact. This is why conditioning matters, and why relying on marginals alone in model evaluation can give you false confidence. Another thing worth noting: conditioning on a specific value of a continuous variable creates a measure-zero event, so the intuitive formula breaks down unless you think of it through limits or the Radon-Nikodym derivative. In applied work, people usually approximate by conditioning on a small interval instead. This is standard practice but it means your conditional distribution depends on the band-width you choose, and results can shift noticeably if you change it.
Get the Full Details

The most common pitfall I see is treating conditional and marginal probabilities as interchangeable in chain-rule calculations. P(A|B) * P(B) gives you the joint, yes, but P(B|A) * P(A) gives you the same joint. The mistake comes when someone computes P(A|B) but plugs in P(B) from a different model or dataset. The numbers line up superficially and the error goes undetected for a while. When you're working with large-scale data, computing full joint distributions is usually infeasible. The memory requirements grow exponentially with the number of variables. In those cases, I avoid constructing the joint altogether and work directly with conditional specifications, like in a Bayesian network or factor graph. Marginals are then computed through belief propagation or sampling, which is computationally cheaper even though it introduces approximation error. If you need to compute these by hand for a homework problem or a small dataset, start by writing out the joint table explicitly. Label every row and column clearly. The marginal is just a row sum or column sum. The conditional is a slice of that table normalized to sum to one. Don't overthink it. The algebra is straightforward, and the confusion almost always comes from sloppy bookkeeping rather than conceptual difficulty.
For anyone working with real data, the practical takeaway is this: make sure you know whether your pipeline is producing a marginal or a conditional at each step. A joint log-likelihood, a conditional likelihood, a marginalized evidence term—each serves a different purpose and requires different handling. Mixing them up silently is the fastest way to get results that look plausible but are fundamentally wrong.