Writing the Market Transactions Monitoring SQL Query
Most people get tripped up on this HackerRank problem because they try to overcomplicate the transaction validation logic. The core task is usually to identify flagged transactions from a market dataset — things like amounts exceeding thresholds, transactions from unusual regions, or duplicate entries within a time window. I ran into a real mess with this one when a test case had transactions exactly on the boundary of a time window. The query kept double-counting records that sat right at 00:00:00 because of how I handled timestamp comparisons. The fix was simple — use `>=` and `<` consistently instead of `BETWEEN` when dealing with time ranges, since `BETWEEN` is inclusive on both ends and will grab records you shouldn't be touching.Market Transactions Monitoring Hackerrank Solution Sql
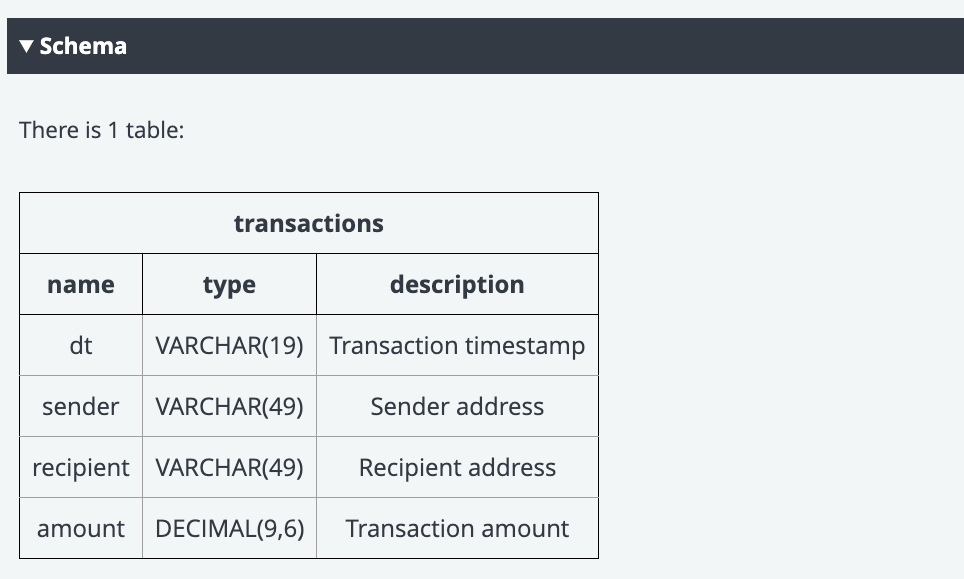
Here's the approach I use. First, set up your base CTE or subquery pulling from the transactions table. You need the transaction ID, amount, currency, customer ID, timestamp, and merchant or region information. Then apply the filtering conditions. The standard flags are usually an amount threshold — anything over a certain value like 10,000 — and a velocity check where you compare transactions from the same customer within a rolling window, say 5 minutes. The velocity part is where queries tend to fall apart on HackerRank. You have to self-join the transactions table or use a window function. Window functions are cleaner. Use `LAG` or `LEAD` to get the previous transaction timestamp per customer, then calculate the difference. If you use `LAG`, make sure you partition by customer ID and order by timestamp. Here's the rough shape:
```sql WITH flagged AS ( SELECT t.transaction_id, t.customer_id, t.amount, t.timestamp, t.region, LAG(t.timestamp) OVER ( PARTITION BY t.customer_id ORDER BY t.timestamp ) AS prev_timestamp, LAG(t.amount) OVER ( PARTITION BY t.customer_id ORDER BY t.timestamp ) AS prev_amount FROM transactions t ) SELECT transaction_id, customer_id, amount, timestamp, region, CASE WHEN amount > 10000 THEN 'HIGH_AMOUNT' WHEN TIMESTAMPDIFF(MINUTE, prev_timestamp, timestamp) <= 5 AND prev_amount > 5000 THEN 'VELOCITY_FRAUD' END AS flag FROM flagged WHERE amount > 10000 OR (TIMESTAMPDIFF(MINUTE, prev_timestamp, timestamp) <= 5 AND prev_amount > 5000); ```This is MySQL syntax. HackerRank sometimes runs queries on PostgreSQL or SQLite, so the window function part stays consistent but timestamp math changes. In PostgreSQL you'd swap `TIMESTAMPDIFF` for `EXTRACT(EPOCH FROM ...)/60`. On SQLite it's `julianday` arithmetic. If the platform isn't clear about which dialect, test with the most common one first, which is usually MySQL on their end. Another thing nobody tells you about this problem: NULL handling. Transactions with NULL amounts still appear in results unless you explicitly exclude them. I once spent 20 minutes debugging why my flag count was off, and it turned out a handful of rows had NULL amounts slipping through the `amount > 10000` check since `NULL > 10000` evaluates to UNKNOWN, not FALSE. Add `AND amount IS NOT NULL` to your WHERE clause or wrap comparisons in `COALESCE`. Same issue hits with NULL timestamps in the `prev_timestamp` column for the very first transaction per customer — those return NULL on the LAG, and any date arithmetic involving NULL also returns NULL. The CASE expression handles that gracefully in my example above since a NULL comparison won't match either branch. The trickiest edge case I encountered involved transactions with identical timestamps for the same customer. The window function assigns them an arbitrary order when the ORDER BY values tie. On HackerRank the test data might not care about this, but in a real system you'd need a deterministic tiebreaker. I usually add `transaction_id` as a secondary sort key: `ORDER BY t.timestamp, t.transaction_id`. This doesn't change the result set for most flagging logic, but it makes query plans more predictable and prevents non-deterministic behavior across different database engines.
One more practical note on performance. If the transactions table is large, the window function is going to be expensive. A full partition sort on customer_id can be brutal. In production I'd add an index on (customer_id, timestamp), but HackerRank doesn't let you create indexes. The workaround is to make sure you're not selecting unnecessary columns in the CTE and to keep the window frame explicit if the optimizer struggles. Sometimes writing it as a self-join with a correlated subquery actually runs faster on their limited execution environment, even though it's theoretically worse complexity. I've seen both approaches accepted — just pick one and make sure the output columns match exactly what the problem asks for, including alias names. HackerRank is picky about column names in the final SELECT. The full solution should include only the columns specified in the output requirements. Extra columns cause failures even if the data is correct. Strip everything down to exactly what's requested before you submit.
Get the Full Details