Setting Up a Research Pipeline That Doesn't Collapse
Most teams skip the infrastructure step and jump straight into running surveys or pulling data from dashboards. That's where things go wrong. You end up with numbers you can't explain and insights your stakeholders won't trust because the methodology was never documented or reproducible. I once spent three weeks trying to trace why two datasets from the same campaign had different conversion rates. Turns out one team had applied a 30-day click window and the other used a 7-day window, and nobody had written that down anywhere. The fix was a simple metadata tag system added to every dataset before any analysis began. That single change reduced our reconciliation time from days to about twenty minutes per project.
Marketing Research And Analytics: A Practical Framework
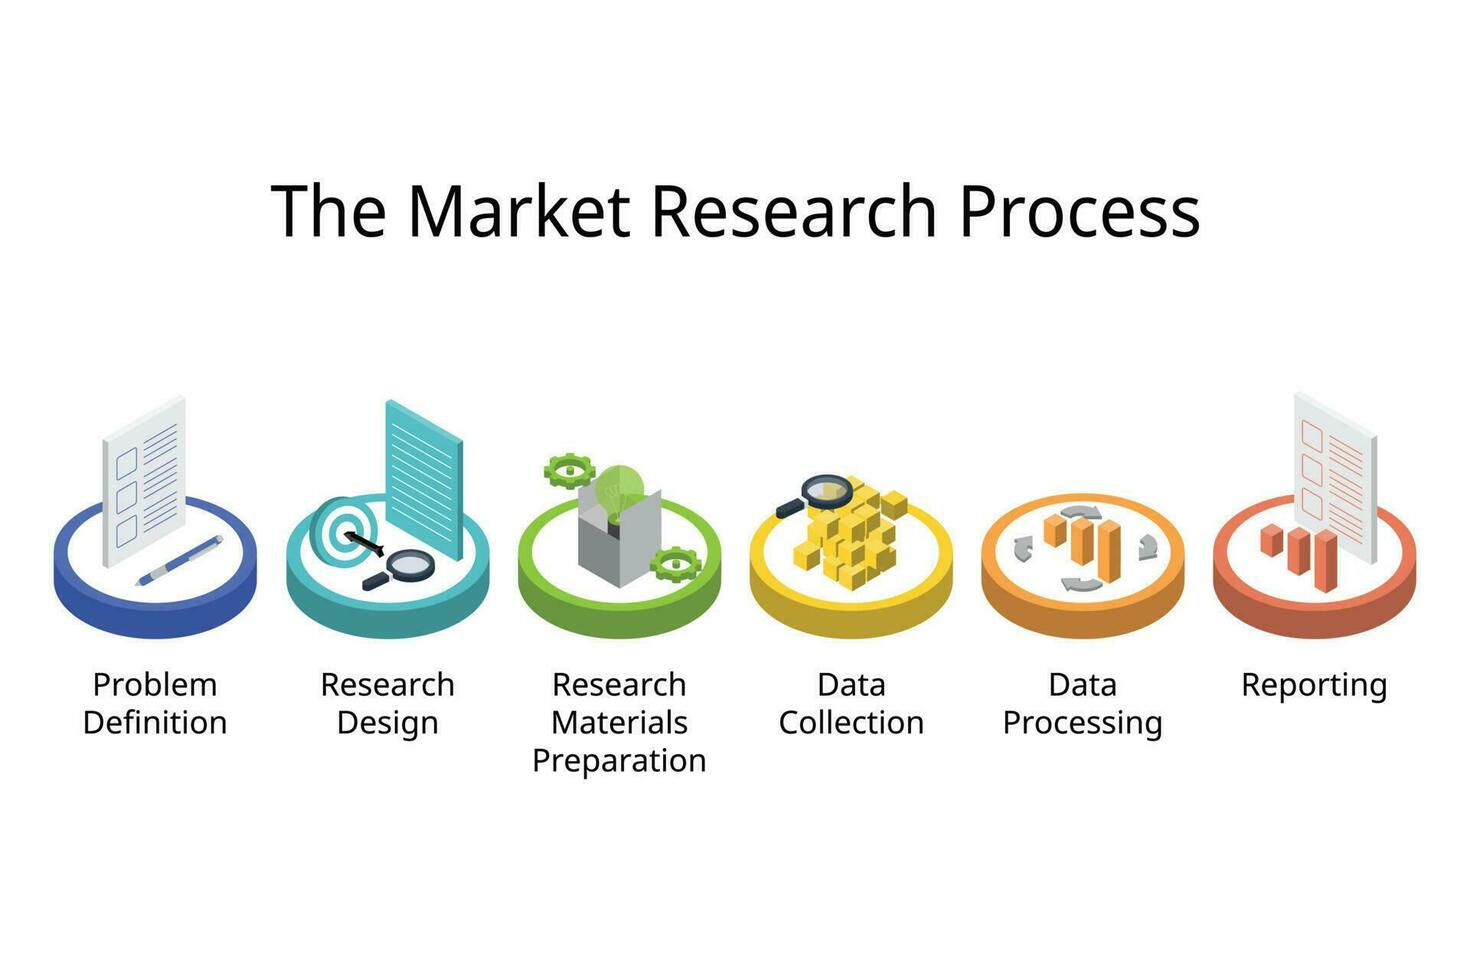
The field combines qualitative research methods with quantitative analytics to understand consumer behavior and measure campaign performance. It's not two separate disciplines. The qualitative piece gives you context for the numbers, and the quantitative piece validates whether your qualitative findings hold up at scale. Here's the workflow I actually use, in order: Start with a research question so specific that a yes or no answer would be useful. "How do we increase engagement?" is not a research question. "Does adding social proof elements to product pages change add-to-cart rates for customers under twenty-five?" is a research question. The specificity matters because it determines your method selection, your sample size calculation, and your success metrics before you've spent a dollar.
Then choose your data sources. Primary data comes from surveys, interviews, focus groups, and experiments you design. Secondary data comes from analytics platforms, industry reports, and public datasets. I always start with secondary data because it takes hours to pull rather than weeks, and it usually reveals gaps that tell you exactly what primary research is actually needed for. For primary research, I recommend starting with open-ended qualitative interviews before designing any survey. Five to eight interviews with your target segment typically surfaces the language people actually use, the objections they raise, and the features they mention unprompted. That vocabulary becomes the foundation of your survey instrument. Surveys built without that step tend to ask questions respondents don't understand or answer in ways that look meaningful but aren't. Sample size matters more than people think. A rule of thumb I use: for descriptive studies you need roughly one hundred respondents per segment you're analyzing. For hypothesis testing with statistical significance at ninety-five percent confidence and a five percent margin of error, you need between three hundred and four hundred respondents minimum. Anything less and your confidence intervals are too wide to act on reliably. I've seen teams make product decisions based on forty-person surveys and then wonder why the rollout underperformed.
Get the Full Details
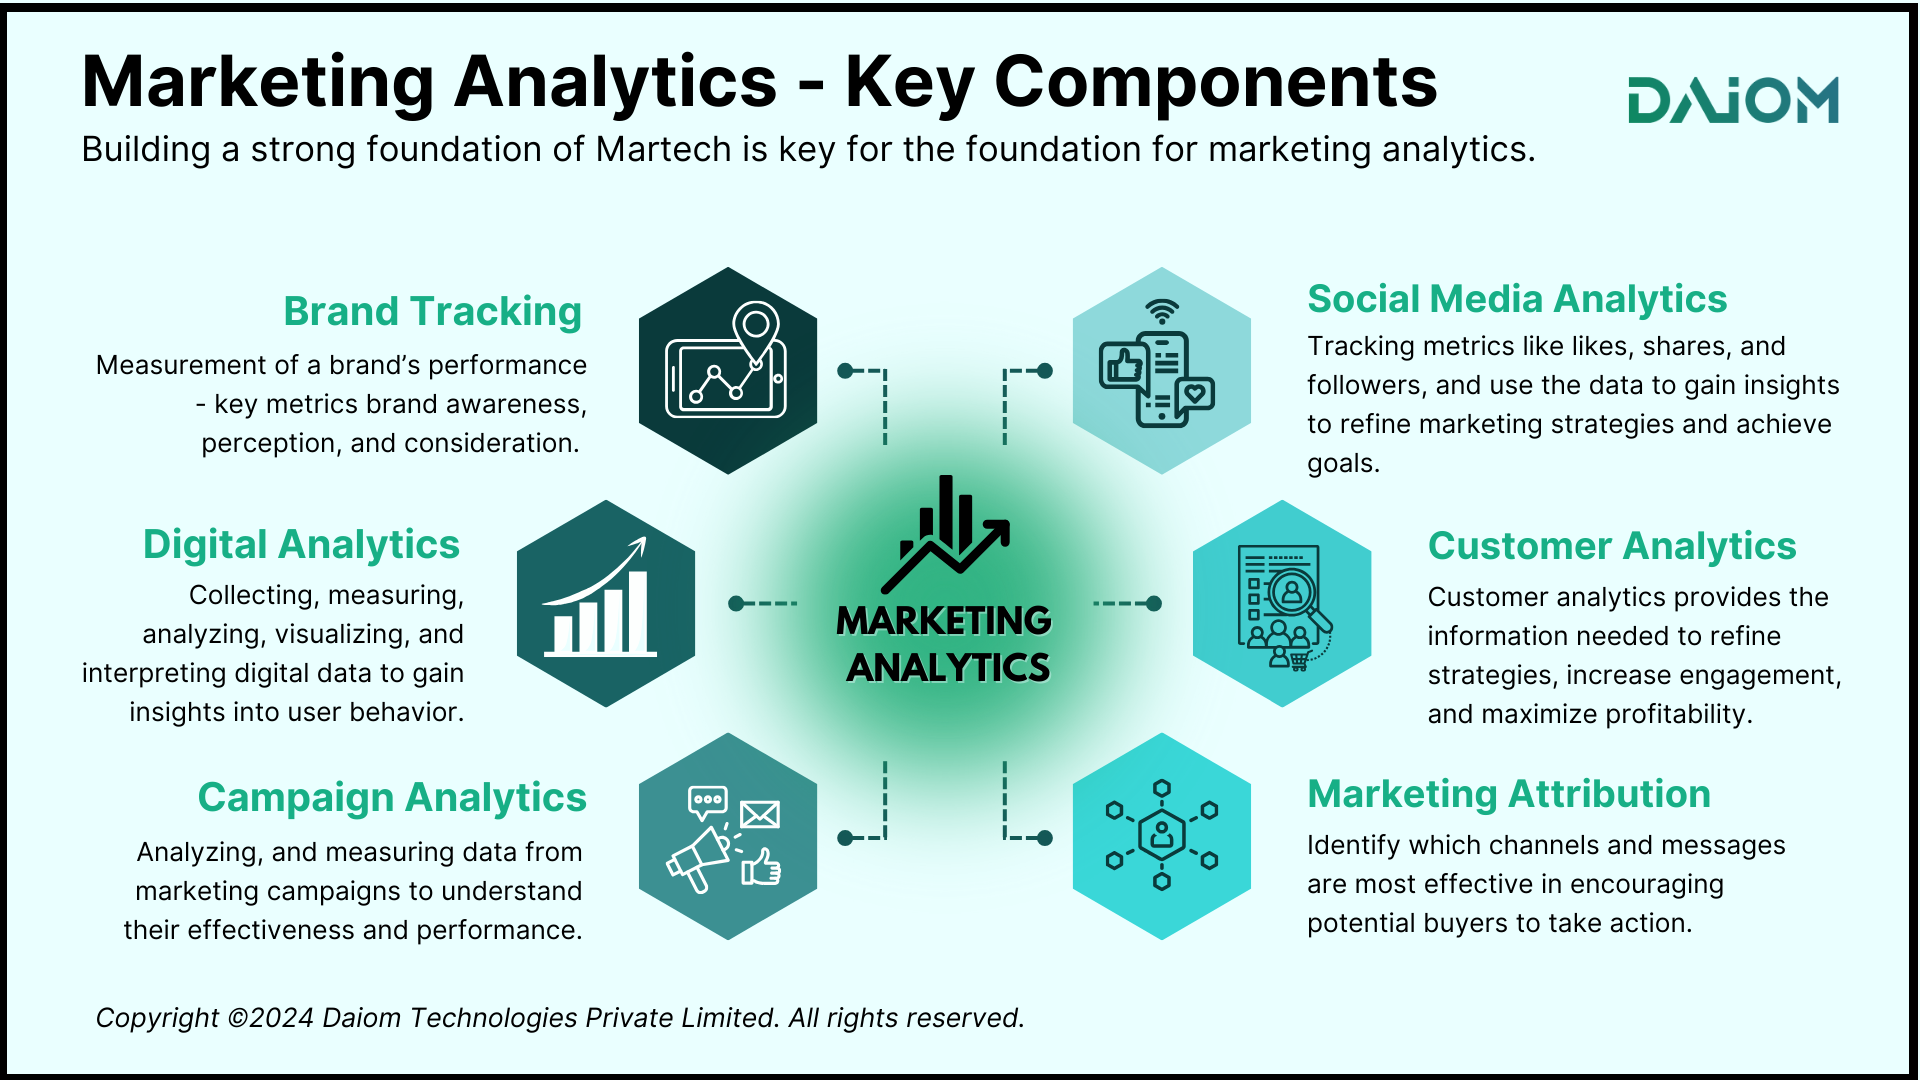
When you move to analysis, cross-tabulation is where most people stop and that's a mistake. The real insight comes from segmentation analysis. You break your data down by demographics, behavior patterns, purchase history, and geographic variables simultaneously. A campaign might look like a failure overall while actually performing above average for a specific segment. That segment is usually where your next budget allocation should go. A/B testing deserves special attention because it's the most common tool in analytics and also the most misused. The biggest pitfall I see is peeking at results before the test reaches statistical significance. If you check daily and stop when something looks good, you're almost certainly seeing noise, not a real effect. Run the test for the full predetermined duration or use sequential testing methods that account for multiple looks at the data. Another common error is not accounting for seasonality. A summer promo test might look impressive and then fail in November because you never isolated the seasonal variable. Attribution modeling is another area where beginners waste time. First-touch and last-touch attribution are fine for quick checks, but they systematically misallocate credit. If you're spending money on analytics infrastructure, even a basic multi-touch model like time-decay or position-based will give you meaningfully better insights. The improvement usually pays for itself within a single quarter of improved spend allocation.
Data cleaning consumes more time than anything else in this work. I budget roughly sixty percent of my project timeline for it. Missing values, duplicate entries, inconsistent formatting across sources, and outlier detection all need manual review. Automated cleaning scripts catch the obvious stuff, but they miss the subtle issues like a respondent who selected "strongly agree" for every statement on a Likert scale, which skews your sentiment analysis without any automated flag catching it. For visualization, keep it simple. A well-labeled bar chart beats a fancy interactive dashboard that nobody understands. The people receiving your research findings usually need to make decisions quickly. If they can't grasp the main finding in ten seconds, you've failed regardless of how accurate the underlying analysis is. Tools. I use Google Analytics and Adobe Analytics for web data depending on what the organization already has licensed. For survey design and distribution, Qualtrics handles most needs, though SurveyMonkey is adequate for smaller projects. SPSS remains solid for statistical analysis if your team already has access, but Python with pandas and scipy gives you more flexibility at no licensing cost. Tableau or Looker for visualization, depending on whether your company leans toward on-premise or cloud analytics. Excel should never be the final tool in your pipeline for anything beyond simple spreadsheets. The moment you're joining more than two datasets or running regressions, move to a proper statistical environment.
The biggest limitation of marketing research as a field is that it describes what happened, not what will happen. Predictive analytics models can forecast trends with reasonable accuracy, but they break down during market disruptions. The 2020 pandemic showed this clearly for every team that built their forecasts on pre-existing data patterns. No amount of rigorous methodology fixes a model trained on irrelevant historical context. The workaround is to incorporate leading indicators like search trend data and social listening metrics that shift before traditional sales data does. Another hard truth: research doesn't always change decisions. Stakeholders often want validation for choices they've already made. The best researchers I know learn to present findings in a way that acknowledges what the stakeholder already believes while clearly surfacing the contradictory evidence. It's slower and requires more emotional intelligence than just delivering a slide deck, but it actually influences outcomes instead of being archived and forgotten. If you're building a research capability from scratch, start with one or two high-impact questions your organization actually cares about. Don't try to build a comprehensive analytics department on day one. Get one clean study done that produces a decision-changing insight, document the process thoroughly, then expand from there. The teams that try to do everything at once usually end up with no clear answers and a lot of expensive software licenses they barely use.