What Actually Goes Into Math 1530 Introductory Statistics Answers
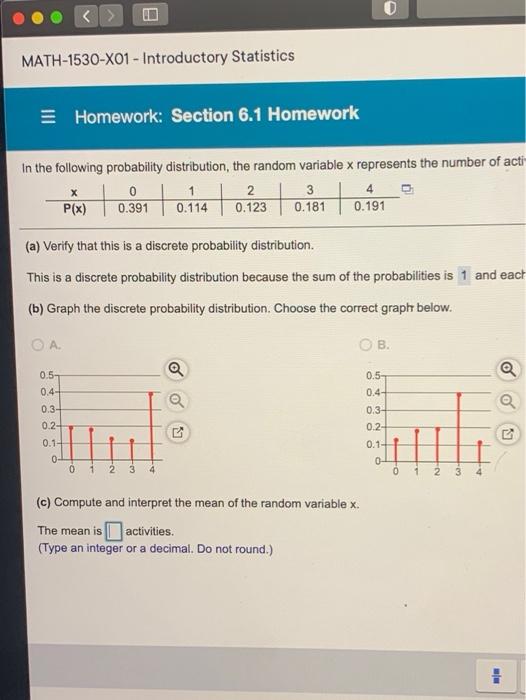
Introductory statistics courses tend to follow the same general outline no matter which college you're at. Probability distributions, confidence intervals, hypothesis testing, regression, and a few topics that nobody really remembers past the final exam. Math 1530 is no exception. If you're looking for Math 1530 Introductory Statistics Answers, you've probably hit a problem set or a homework assignment that feels like it's moving faster than the lecture material covered. The first thing to understand is that introductory statistics isn't about memorizing formulas. It's about recognizing what question the problem is actually asking you and then mapping that onto the right framework. Most students lose points not because they can't compute a number but because they set up the wrong test or misidentified the distribution to use. I've seen it repeatedly over the years.
Getting Math 1530 Introductory Statistics Answers Right
When you're working through problem sets, start by identifying the type of data you're dealing with. Is it categorical or quantitative? Are you comparing one group or two? Are the samples independent or paired? These three questions will determine almost everything else. A lot of textbook problems bury these details inside wordy scenarios. Don't skip the setup phase. For hypothesis testing, which tends to dominate the second half of the course, the standard approach goes like this. State the null and alternative hypotheses clearly. Pick your significance level, usually 0.05 unless stated otherwise. Calculate the test statistic using the appropriate formula. Find the p-value, either from a table or software. Make your conclusion in the context of the problem, not just in statistical jargon. That last part is where points routinely disappear. One thing that trips people up constantly is confusing the p-value with the probability that the null hypothesis is true. A p-value of 0.03 does not mean there's a 3% chance the null is correct. It means that if the null were actually true, you'd see data this extreme or more extreme about 3% of the time. The distinction matters when you're writing conclusions and when you're interpreting results on exams.
I ran into a problem recently where a student was asked to test whether a new teaching method improved pass rates on a statistics placement exam. The data came from two separate groups of students, one using the old method and one using the new. The straightforward move would be a two-sample z-test for proportions. But the sample sizes were both under thirty, which technically violates the large-sample approximation. The correct workaround was to use a two-proportion z-test anyway since introductory courses usually accept it at those sizes, but flag the assumption. Alternatively, if the course covers it, an exact test via software would be more defensible. I had students who lost points for not mentioning the sample size concern even though their numerical answer was correct. That's a real scenario I've dealt with. Confidence intervals follow a similar logic but in reverse. Instead of testing a claim, you're building a range that likely contains the true parameter. The width of that interval depends directly on your sample size and the variability in your data. More data narrows the interval. Higher variability widens it. The formula is usually something like the point estimate plus or minus a critical value times the standard error. Remembering which critical value to use—z or t—is the part that causes confusion. Use z when the population standard deviation is known or when your sample is large enough that the normal approximation holds. Use t when you're estimating the standard deviation from your sample and the sample is small. Most calculator and software tools handle this automatically now, but you still need to know which output to trust. On a TI-84, for example, a T-Test is different from a Z-Test. Picking the wrong one gives you the wrong p-value and the wrong interval, and the calculator won't warn you.
Get the Full Details
Regression is another area where students tend to just plug numbers into a calculator and hope. The math itself is simple—the least squares line minimizes the sum of squared residuals—but interpreting the output is where the real work happens. Your slope coefficient tells you the expected change in the response variable for each one-unit increase in the predictor. Your R-squared value tells you what percentage of the variation in the response is explained by the model. Neither of those numbers means anything useful without understanding what the variables actually represent in context. A couple of counter-intuitive points that tend to get missed. First, correlation does not imply causation sounds like a cliché but students still write causal language in their conclusions when the study design was observational. Just because two variables are correlated doesn't mean one causes the other. There could be a lurking variable or pure coincidence. Second, a non-significant result does not prove the null hypothesis. Failing to reject H0 simply means you don't have enough evidence to support the alternative. It's a subtle distinction that shows up on exams more often than you'd think. Now, regarding where to find Math 1530 Introductory Statistics Answers, there are a few practical routes. Your textbook's companion website usually has worked examples and occasionally full solution sets for selected problems. The course professor's posted solutions, if available, are the most reliable source since they match the exact notation and expectations of your class. Online forums and study groups can help when you're stuck on a specific step, but be careful copying answers wholesale. Professors can spot when your work doesn't match your usual style, and the learning benefit disappears entirely.
Some students prefer solution manuals that walk through problems step by step. Those exist for most standard textbooks like Triola, Moore, or OpenStax. The trade-off is that they sometimes use slightly different methods than what your professor emphasizes in class. A z-test versus a t-test choice, for instance, might differ based on how your instructor teaches it. Always cross-check your class notes against any external solution you use. Here's the blunt part. No single set of answers will cover every variation your professor might throw at you. Textbook problems get renumbered, numbers change, and professors create their own hybrids. The skill that actually helps you pass this course is being able to adapt a known method to a new problem, not having seen the exact problem before. I've watched students who memorized answer patterns struggle when the exam questions were worded differently but required the same underlying technique. That's a real bottleneck. If you're struggling with a specific topic, regression analysis tends to be the hardest conceptual leap after hypothesis testing. It combines several ideas—you need to understand variables, relationships, and probability—all at once. Spend extra time there. Practice interpreting output from both hand calculations and software. The exam will likely ask you to read a regression table and explain what the numbers mean, not just compute a line.
For quick reference, here's a summary of the main tests you'll encounter and when to use them. One-sample z-test for proportions when testing a single proportion with large samples. Two-sample z-test for independent proportions when comparing two groups. Paired t-test when the same subjects are measured twice or when data comes in natural pairs. One-sample t-test for a mean when the population standard deviation is unknown and the sample is small. Two-sample t-test for independent means under the same conditions. Chi-square test for independence when working with categorical data in a contingency table. ANOVA when comparing three or more group means. Each of these has specific assumptions you should verify before applying it, and your exam may include a question that asks you to check those assumptions. Time management during exams is another practical issue worth addressing. Most introductory statistics exams have about twenty to thirty problems spread across multiple choice, short answer, and calculation sections. The calculation problems take the longest, especially if you're setting up hypotheses and showing work. Budget your time so you don't spend ten minutes on one problem and run out of time for three easier ones you could have finished. Leave yourself at least ten minutes at the end to review calculations for silly arithmetic errors, which are surprisingly common even among students who understand the concepts. Finally, if you're using online resources for Math 1530 Introductory Statistics Answers, pick sources that show their work rather than just giving final numbers. Understanding the path from the problem statement to the answer is what actually prepares you for the test. A source that skips steps might save you five minutes on homework but cost you twenty minutes figuring it out during an exam when there's no help available.