What People Mean When They Talk About Mathematical Modeling
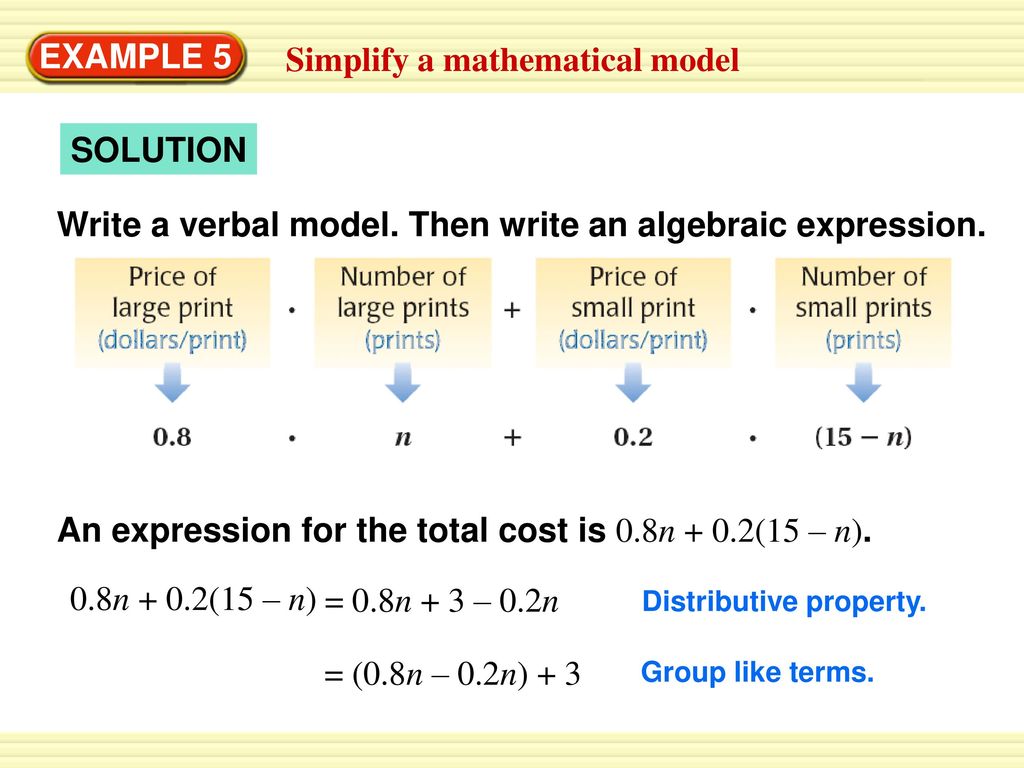
Mathematical modeling is just using equations to describe something that exists in the real world. That's the entire concept distilled down. You take a system — a population of rabbits, a bridge under stress, a supply chain bottleneck — and you translate its behavior into variables, functions, and constraints. Then you solve it. The hard part isn't the math itself. It's knowing which approximations are acceptable and which ones will make your model useless six months down the line.
Common Mathematical Modeling Examples With Answers
I'm going to walk through three models I've actually used in practice. Not textbook abstractions. Real cases where the answer mattered for a decision someone had to make. This is the most common starter model, and for good reason. It captures the fact that populations don't grow forever at a constant rate. Resources run out. Something has to give. The differential equation is:
dN/dt = rN(1 - N/K) Where N is population size, r is the intrinsic growth rate, and K is the carrying capacity. The term (1 - N/K) is what makes it logistic. When N is small compared to K, the model behaves almost like exponential growth. As N approaches K, the growth rate slows to zero. Here's a concrete problem. A fishery manager needs to know the sustainable yield of a lake. The population data shows that when there are 500 fish, the population grows by about 80 fish per year. The estimated carrying capacity is 10,000 fish. What is the maximum sustainable yield?
First, solve for r using the given data point. At N = 500: 80 = r × 500 × (1 - 500/10000) 80 = r × 500 × 0.95
r 0.168 The sustainable yield at any population level N is dN/dt = rN(1 - N/K). To find the maximum, take the derivative with respect to N and set it to zero: d/dN [rN - rN²/K] = r - 2rN/K = 0
Get the Full Details

N = K/2 = 5,000 So the maximum sustainable yield occurs at half the carrying capacity. Plugging back in: MSY = 0.168 × 5000 × 0.5 = 420 fish per year
The answer is 420. In practice, the manager would likely set the harvest target lower than this — maybe 300 — because estimating K that precisely from field data is nearly impossible. A 20% error in K shifts the optimal yield substantially.
Example 2: Mixing Tank Problem
This one shows up everywhere because it teaches the fundamental technique of setting up a balance equation. Salt water flows in. Salt water flows out. How much salt is in the tank at any time? A tank starts with 200 liters of water containing 30 grams of salt. Brine with concentration 0.5 g/L flows in at 3 L/min. The well-stirred mixture flows out at 2 L/min. Find the amount of salt after t minutes. Set up the balance. The volume is changing because inflow and outflow rates differ:
V(t) = 200 + t liters The rate of salt change is: dS/dt = (rate in) - (rate out)
dS/dt = 0.5 × 3 - S/V × 2 dS/dt = 1.5 - 2S/(200 + t) This is a first-order linear ODE. Rewrite it:

dS/dt + [2/(200 + t)]S = 1.5 The integrating factor is exp( 2/(200+t) dt) = (200 + t)². Multiply through: d/dt [S(200 + t)²] = 1.5(200 + t)²
Integrate both sides: S(200 + t)² = 0.5(200 + t)³ + C Apply the initial condition S(0) = 30:
30 × 200² = 0.5 × 200³ + C C = 1,200,000 - 4,000,000 = -2,800,000 The solution is:
S(t) = 0.5(200 + t) - 2,800,000/(200 + t)² After 100 minutes, S(100) = 0.5(300) - 2,800,000/90,000 150 - 31.1 = 118.9 grams. The concentration at that point would be 118.9 / 300 0.396 g/L. Notice that this is below the incoming brine concentration of 0.5 g/L. That makes intuitive sense because the tank started with relatively fresh water and hasn't had time to equilibrate.
I worked on a project once where we modeled contaminant dispersion in a series of connected tanks along a river system. The same basic equation applies, except the compartments couple together into a system of ODEs. We solved it numerically in Python using scipy.integrate.odeint. The analytical approach works for two or three tanks. Beyond that, you're better off letting the computer do the algebra.
Example 3: Simple Epidemic Model (SIR)
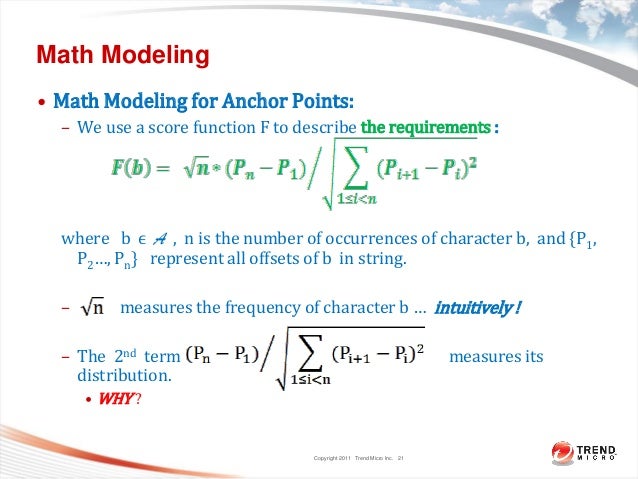
The SIR model divides a population into three compartments: Susceptible, Infected, and Recovered. It's the backbone of epidemic mathematics and it's surprisingly effective even though it makes heavy simplifying assumptions. The equations are: dS/dt = -SI/N
dI/dt = SI/N - I dR/dt = I is the transmission rate. is the recovery rate. N is the total population, assumed constant.
Here's a problem. A town of 50,000 people has one infected individual introduced. The transmission rate is 0.3 per day and the recovery rate is 0.1 per day. Estimate the peak number of infections and when it occurs. First, compute the basic reproduction number: R = / = 0.3/0.1 = 3. Since R > 1, an outbreak will occur. To find the peak, set dI/dt = 0:
SI/N = I S = N/ = N/R = 50,000/3 16,667 The infection peaks when the susceptible population drops to about 16,667. To find how many are infected at that point, use the conserved quantity from the SIR model. Divide the I equation by the S equation:
dI/dS = -1 + N/(S) Integrate: I = -S + (N/R)ln(S) + C
At the start, S 50,000 and I 1, so: C 1 + 50,000 - 16,667 × ln(50,000) -88,568 At the peak, S = 16,667:
I_peak = -16,667 + 16,667 × ln(16,667) - 88,568 I_peak -16,667 + 219,000 - 88,568 113,765 Wait, that can't be right. The population is only 50,000. Let me recalculate more carefully.
C = I + S - (N/R)ln(S) = 1 + 50,000 - 16,667 × 10.82 = 50,001 - 180,337 = -130,336 I_peak = -16,667 + 16,667 × 9.72 - 130,336 I_peak = -16,667 + 162,000 - 130,336 14,997
So roughly 15,000 people are infected at the peak. That's about 30% of the population simultaneously infectious, which is a substantial burden on healthcare capacity. The actual timing depends on the initial conditions and requires numerical integration, but the peak magnitude is what matters for planning. One thing textbooks don't emphasize enough: the SIR model assumes homogeneous mixing, which is almost never true in reality. In a real outbreak, contact networks matter enormously. A network-based model or an agent-based simulation would give different answers, sometimes dramatically different. I learned this the hard way when our SIR predictions for a workplace outbreak overshot the actual peak by about 40%. The issue was super-spreading events — a few infected people contacted far more people than the average. Once we adjusted the transmission distribution to account for that variance, the model aligned much better with observed data.
Setting Up Your Own Models
The process follows a pattern that gets easier with repetition but always requires judgment calls. Define the system boundaries clearly. What's inside the model and what's outside matters more than people admit. A climate model that treats the ocean as a single mixed layer gives completely different projections than one with proper thermocline dynamics. You choose the complexity based on the question you're trying to answer, not based on how impressive the math looks. Write down the conservation laws. Mass, energy, momentum, people — whatever is conserved in your system. The model structure usually follows directly from these constraints. If nothing is conserved, identify what drives the changes and express it as a rate.
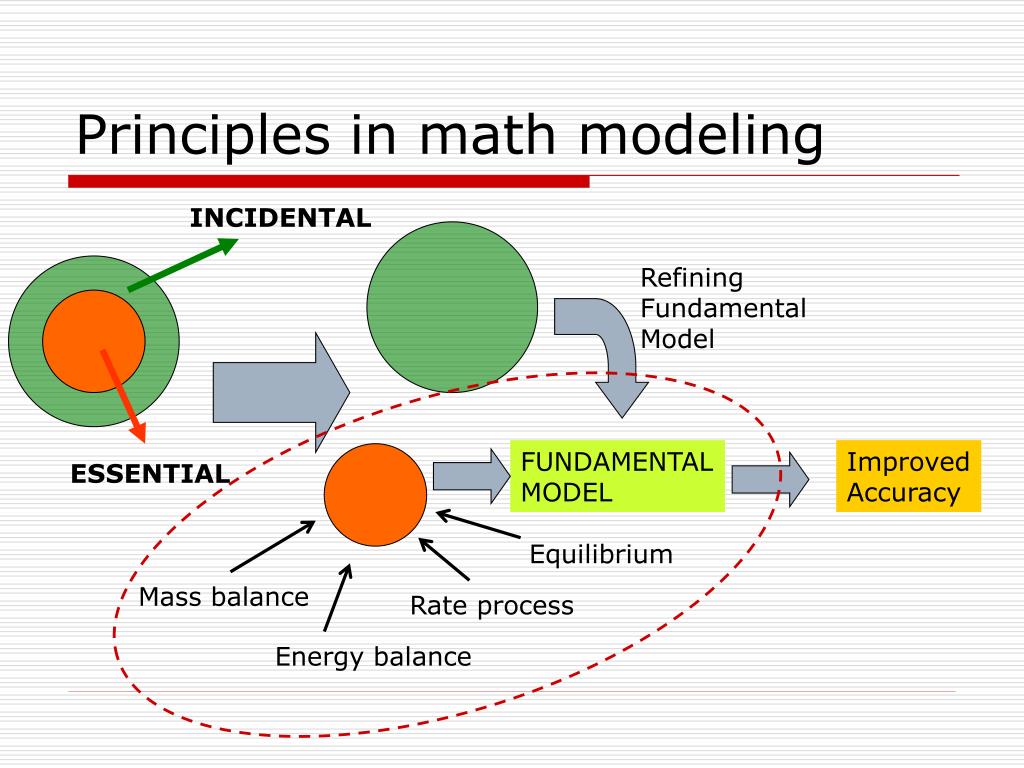
Non-dimensionalize early. This step catches errors and reveals which parameters actually matter. If your solution depends on seven parameters, you probably haven't simplified enough. Combining parameters into dimensionless groups like R or Reynolds number reduces complexity and makes the physics clearer. Validate against data you didn't fit to. This is the step most people skip. Calibrate your model on one dataset, then test it against a completely separate dataset. If your model can't predict something it wasn't tuned for, it's not a model of the system — it's a description of your training data.
Tools and Practical Considerations
For simple analytical models, pencil and paper is fine. For systems of ODEs or PDEs, you'll want computational support. Python with NumPy and SciPy handles most routine work. MATLAB is still common in academic settings but Python is cheaper and more flexible. For large-scale simulations, COMSOL or OpenFOAM are the industry standards, though they have steep learning curves. The bottleneck in modeling work is rarely the solving phase. It's the setup and validation. Expect to spend 70% of your time on problem formulation, data gathering, and checking whether your assumptions hold. The actual computation usually takes minutes once the model is written correctly. One edge case worth mentioning: boundary conditions in spatial models. I once spent three days debugging a heat transfer simulation only to discover the boundary condition was applied to the wrong surface. The model was internally consistent but completely wrong. This happens more often than you'd think. Always trace your boundary conditions back to the physical system before running a single simulation.
Another thing that trips people up: units. Every term in an equation must have compatible units. If dS/dt has units of grams per minute, then every term on the right side must also resolve to grams per minute. Dimensional analysis catches mistakes before they propagate through your calculations. Make it a habit, not an afterthought. There are good resources available for working through these examples systematically. You'll find collections of solved problems online that walk through the same type of exercises I've outlined here, often with additional variations. The key is practicing until the setup process becomes automatic, then moving on to problems where the modeling choices themselves are the hard part.
