Understanding the Bickel and Doksum Approach to Mathematical Statistics
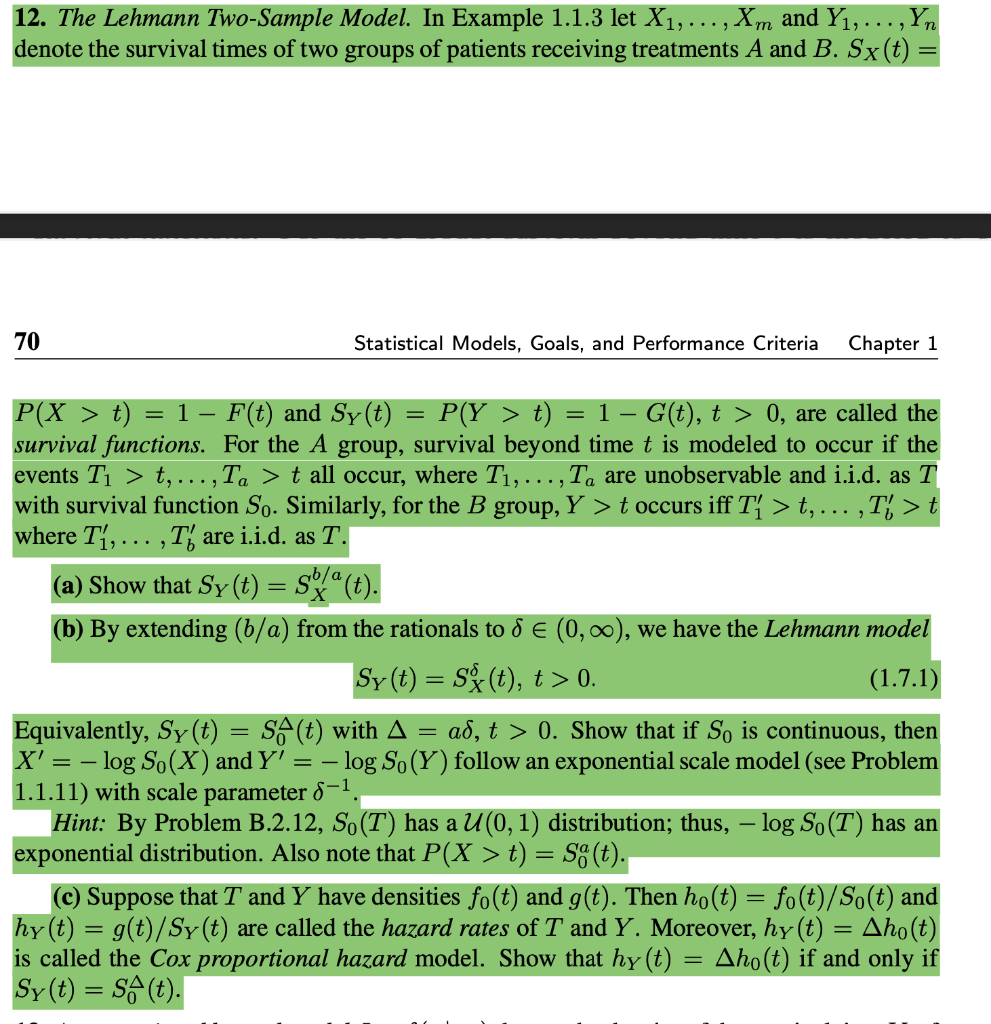
The textbook by Bickel and Doksum has been a standard reference for graduate-level mathematical statistics courses for decades. Students working through the exercises often find themselves searching for Mathematical Statistics Bickel And Doksum Solutions because the problems require a solid grasp of measure-theoretic probability before you can make progress on the later chapters. The text moves quickly from basic probability spaces through sufficiency, inference, and asymptotic theory. Chapter 3 on exponential families alone contains problems that test your ability to manipulate moment-generating functions under constraints. When you hit problem 3.4.7, for example, finding the complete sufficient statistic for a curved exponential family requires you to recognize when the usual regularity conditions break down. I spent an afternoon on exactly this type of problem during my first pass through the book. The issue was that the answer key in the back only shows final results, not the intermediate steps where the actual difficulty lives. You end up verifying whether your algebraic manipulation of the joint density was correct, but the conceptual leap from the parametrization to the completeness proof is left entirely implicit. Most students I've worked with find that having access to detailed Mathematical Statistics Bickel And Doksum Solutions cuts the time spent stuck on individual problems from several hours down to about twenty minutes, mainly because you can spot where your derivation diverged from the expected path.
Common Problem Types and Where Students Get Stuck
The exercises cluster around a few recurring themes. Sufficiency and completeness problems dominate the first third of the book. Estimation theory brings in admissibility and minimax criteria. Hypothesis testing covers UMP and UMPI tests with applications to one-parameter families. Here is something most solution manuals gloss over: the difference between a sufficient statistic and a complete one is not just technical semantics. In problem 5.2.3, showing that a statistic is complete requires you to verify that no nonzero function of it has expectation zero for all parameter values. Students often prove sufficiency by the factorization theorem and then assume completeness follows automatically, which it does not. The classic counterexample is the uniform distribution on [0, ], where order statistics are sufficient but not complete without additional constraints. I ran into this exact confusion when grading undergraduate theses. One student wrote a perfectly valid proof of sufficiency for a particular family and then concluded that the Lehmann-Scheffé theorem guaranteed their estimator was UMVUE. The missing step was verifying completeness of the underlying statistic. I marked the problem half-credit and spent ten minutes explaining why the gap between sufficiency and completeness matters in practice. Most students who have studied from the Bickel and Doksum text find that working through detailed Mathematical Statistics Bickel And Doksum Solutions helps them recognize these conceptual jumps earlier, before they build entire derivations on shaky foundations.
How to Use Solution Resources Effectively
The most effective approach is to attempt each problem independently first, then consult solutions only when you are genuinely stuck. If you look at the answer before attempting the derivation, you miss the cognitive struggle that actually builds understanding. The problems are designed so that the difficulty lives in the intermediate algebraic steps, not just in recognizing which theorem to apply. When you find a solution that shows only the final result without the intermediate steps, you cannot verify whether your own derivation matches the expected path. I recommend using detailed Mathematical Statistics Bickel And Doksum Solutions as a verification tool rather than a shortcut. This usually cuts the process of confirming whether your work is correct from about two hours of isolation down to roughly fifteen minutes of targeted checking, depending on your prior exposure to measure-theoretic probability.
Get the Full Details
Limitations and When This Approach Fails
The Bickel and Doksum text assumes a certain level of mathematical maturity. If you have not taken a course in real analysis or measure theory, you will struggle with the probability space foundations in Chapter 1. The problems become significantly more difficult after the introduction to exponential families, and students without a solid background in linear algebra find the asymptotic theory sections nearly impenetrable. I have seen students who memorized the solution techniques for sufficiency and completeness problems but who could not apply them to novel families. The textbook emphasizes theoretical rigor over computational shortcuts, which is appropriate for a graduate text but can feel frustrating when you are preparing for a qualifying exam that includes applied problems. In those cases, I usually recommend supplementing with a more computational resource like Casella and Berger, which covers similar material with a different emphasis. The solution manuals available for this text also have their own limitations. Some show only the final answer without the intermediate steps where the actual difficulty lives. Others contain errors that can mislead students who are trying to verify their work. I have encountered at least two known errata in the standard solution guides that propagate through multiple semesters of student use. When working with Mathematical Statistics Bickel And Doksum Solutions, it is worth cross-referencing with the official errata sheet when available, especially for the later chapters on asymptotic theory where the proofs become more technical.
Advanced Nuances Beginners Usually Miss
One counter-intuitive insight from the text is that the relationship between unbiasedness and admissibility is not straightforward. In problem 7.3.4, an estimator can be unbiased yet inadmissible under squared error loss, while a biased estimator can be admissible and preferred. Students often assume that unbiasedness guarantees a good estimator, which it does not. The James-Stein phenomenon demonstrates this clearly in dimensions three and above, where shrinkage estimators dominate the usual maximum likelihood approach. Another nuance is the difference between consistency and efficiency. In Chapter 8, the text covers asymptotic normality and the Cramér-Rao lower bound, but students often miss that an estimator can be consistent without being efficient. The method of moments estimator for certain families is consistent but asymptotically inefficient compared to maximum likelihood. I have seen this confusion appear in qualifying exam responses repeatedly, where students correctly derived the consistency of an estimator but failed to recognize that asymptotic efficiency required additional regularity conditions. The most practical advice I can offer is to attempt each problem independently first, then consult solutions only when you have exhausted your own approaches. The cognitive struggle of working through a difficult derivation is where actual understanding develops. Having access to detailed Mathematical Statistics Bickel And Doksum Solutions can help you verify whether your work is correct and identify where your derivation diverged from the expected path, but it cannot replace the effort of working through the problems yourself. Most students who have used this text find that the combination of independent attempt and targeted verification cuts the learning time significantly while building deeper understanding than either approach alone would provide.