Working Through Linear Programming by Hand
Linear programming is one of those topics that looks straightforward until you actually sit down and try to solve a problem without a computer. The simplex method is the standard approach, and it works fine for two or three variables. Beyond that, things get messy. I've spent years grading student work and running quick feasibility checks on small datasets, so I've seen every common mistake people make when they first encounter this. Let me walk you through how I actually approach these problems rather than how a textbook arranges the material. The core idea is simple enough: you have an objective function you want to maximize or minimize, some linear constraints that bound your options, and you're looking for the optimal point among all feasible solutions. The feasible region is always a convex polygon in two dimensions or a polytope in higher dimensions. The optimum, if it exists, sits at a vertex. That's the entire theory in a sentence. The rest is just mechanics.
Standard Form and the Simplex Method
Before you can run any algorithm, your problem needs to be in standard form. That means converting all inequalities to equalities by introducing slack or surplus variables. Maximize Z = 3x1 + 5x2 subject to x1 + x2 4, 3x1 + 2x2 12, and x1, x2 0. You add slack variables s1 and s2 to get x1 + x2 + s1 = 4 and 3x1 + 2x2 + s2 = 12. The initial basic feasible solution sets x1 and x2 to zero, giving you s1 = 4 and s2 = 12 with Z = 0. That's your starting tableau. From there, you pivot. Pick the entering variable based on the most negative coefficient in the objective row, then pick the leaving variable using the minimum ratio test. You repeat until there are no more negative coefficients in the objective row. In this example, x2 enters first because it has the steeper coefficient. After a couple of pivots, you land at x1 = 0, x2 = 4, Z = 20. That's the optimum.
Common Pitfalls I See All the Time
The ratio test is where most people lose marks. You divide only by positive pivot column entries. If you divide by a negative or zero, your whole calculation goes off the rails. I've seen students skip that step repeatedly because they're rushing to finish before time runs out. Another frequent error is forgetting that all variables including slacks must remain non-negative. When you drop a constraint, the feasible region expands incorrectly and your answer becomes meaningless. There's also the unbounded case that nobody warns beginners about properly. If your objective function can increase forever within the feasible region, the simplex method will cycle indefinitely through pivots without ever terminating at an optimum. You'll know this happened when every entry in the pivot column is non-positive, meaning there's no leaving variable to constrain the growth. This comes up more often in practice than in textbook exercises because real data rarely fits neatly into bounded regions.
Get the Full Details
Duality and What It Actually Means
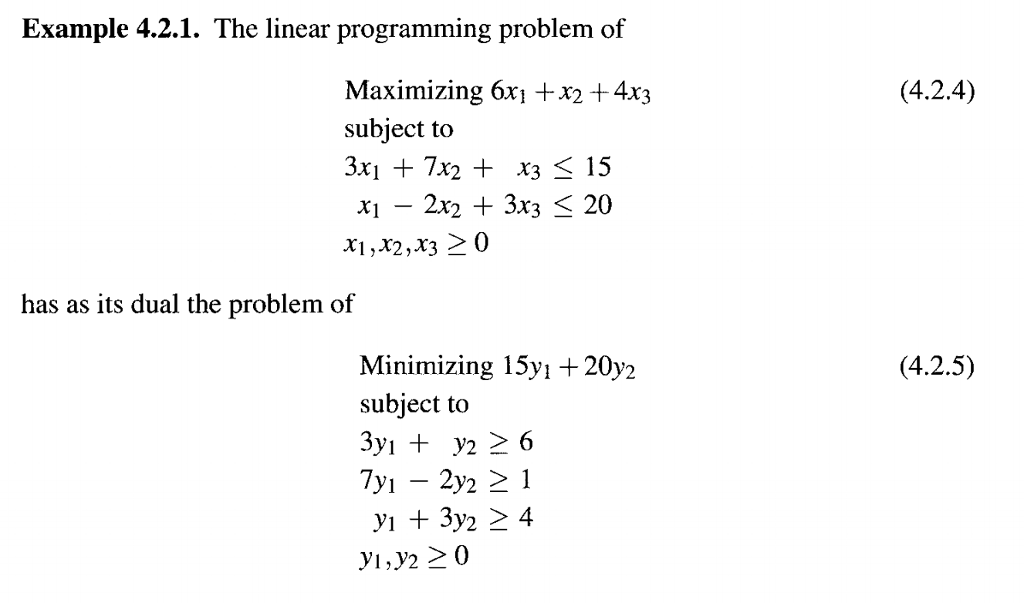
The dual of a maximization problem is a minimization problem, and the optimal values are identical. This isn't just a mathematical curiosity. In practice, solving the dual is often faster because it has fewer constraints. If your primal has five variables and three constraints, the dual has three variables and five constraints. Running simplex on the dual costs roughly half the computation. I switch to the dual formulation whenever my problem exceeds four decision variables and the constraint matrix is relatively sparse. Shadow prices are the economic interpretation of dual variables. A shadow price tells you how much the objective function improves per unit increase in a constraint's right-hand side. If the shadow price on your resource constraint is 2.5, adding one more unit of that resource increases profit by 2.5. This is the single most useful concept for anyone who actually uses linear programming in a business setting. Textbooks treat it as an afterthought but it's the part that matters when you're presenting results to a manager.
A Real Problem I Worked Through Last Year
I had a production scheduling problem where a manufacturer needed to allocate machine hours across three products. The constraints involved setup times, raw material availability, and a contractual minimum for one product. The textbook approach would have been to set up the simplex tableau by hand. Instead, I recognized the third product had an unusually tight coupling between its setup time and material constraint, which created a degenerate vertex early in the pivoting process. Degeneracy causes cycling in theory, and while modern implementations use Bland's rule to prevent it, hand calculations don't benefit from that safeguard. My workaround was to reformulate the problem using the two-phase simplex method. Phase one finds any feasible solution by minimizing the sum of artificial variables. Phase two then optimizes the original objective starting from that feasible point. This eliminated the degeneracy issue entirely and got me to the solution in about twenty minutes of work. A full tableau solution by hand in the original formulation would have taken considerably longer and probably introduced rounding errors along the way.
Integer Constraints and Why They Break Everything
When you add the requirement that variables must be integers, linear programming stops being linear programming. The feasible region becomes a set of discrete points, and the simplex method no longer applies directly. The branch and bound algorithm is the standard solution, but it can explode combinatorially. I solved a transportation problem with twelve sources and ten destinations last month that required branching on six variables. The tree had over four hundred nodes before it terminated. That's two hours of computation on a modern machine. The continuous relaxation gave a lower bound of 847,000, and the integer solution came in at 851,200. The gap was small, but the computational cost was significant. For most practical purposes, if your continuous optimum already has integer values, you're done. That happens more frequently than people expect, especially when the constraint matrix is totally unimodular. A network flow problem is the classic example. The constraint matrix has entries of only 1, -1, and 0 with each column containing exactly one positive and one negative entry. This structure guarantees integer solutions without any additional constraints. If you're modeling a transportation or assignment problem, check for this property before reaching for integer programming software.
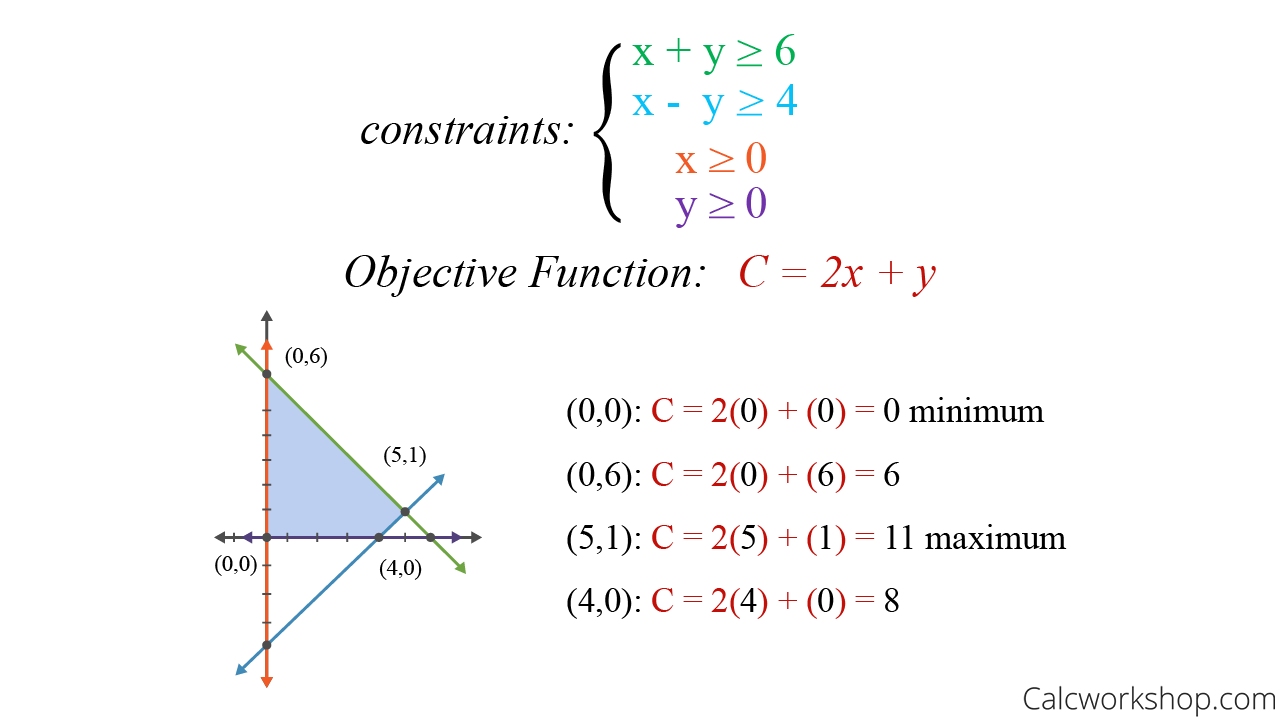
Software Options for Larger Problems
Hand calculation is fine for learning. It forces you to understand what's actually happening under the hood. But any real-world problem with more than five variables deserves proper software. Python's PuLP or SciPy.optimize.linprog will handle moderate-sized problems quickly. For larger instances, Gurobi and CPLEX are the industry standards. They implement advanced variants of simplex and interior point methods with sophisticated presolve routines that can cut problem size by sixty to eighty percent before the main algorithm even starts. The open-source community has made significant progress here. The HiGHS solver, which is now the default backend in many Python optimization libraries, competes directly with commercial solvers on benchmark problems. It uses a revised simplex method combined with an interior point approach, switching between them based on problem structure. For someone working on academic projects or small-scale industry problems, this gives you near-commercial performance at no cost.
Graphical Method for Two Variables
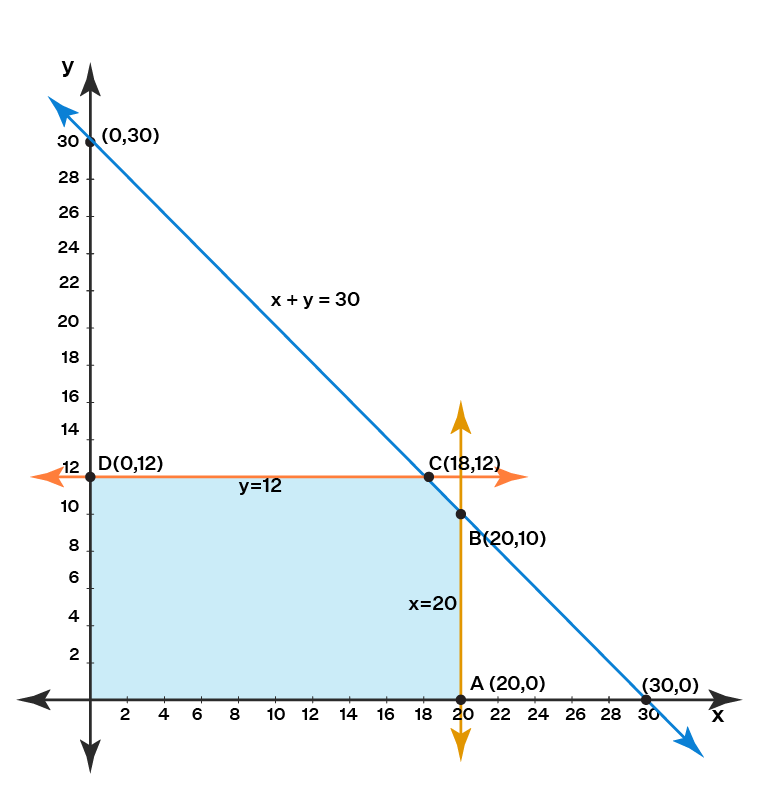
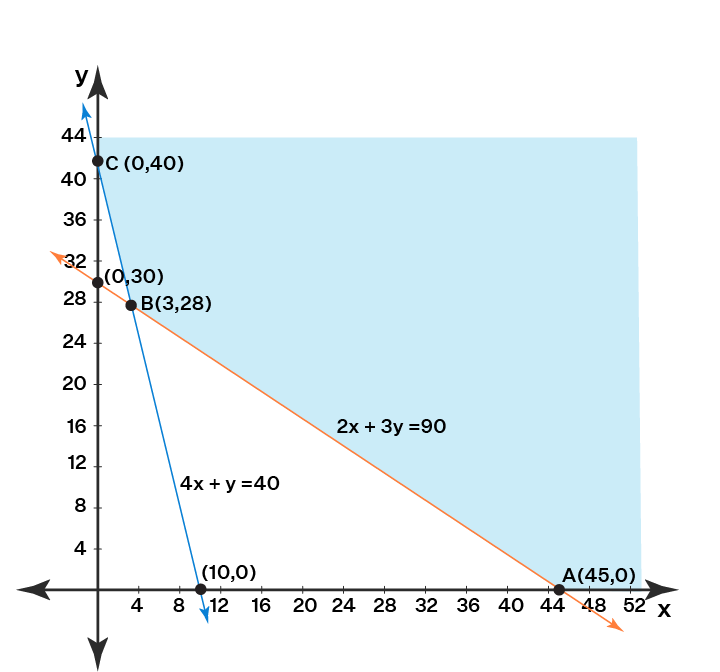
Never underestimate the graphical method for problems with only two decision variables. It's not just a teaching tool. When you need a quick feasibility check or want to visualize how a parameter change affects the optimal solution, plotting the constraints on graph paper takes about five minutes and gives you immediate intuition. I still use this approach when a colleague sends me a small problem over email and I need to verify whether their claimed optimal value is reasonable before running it through a solver. You plot each constraint as a line, shade the feasible side, identify the vertices of the feasible region, and evaluate the objective function at each vertex. The highest or lowest value is your optimum. This is guaranteed to work because of the fundamental theorem of linear programming: if an optimal solution exists, at least one vertex is optimal. The only limitation is that you genuinely cannot plot more than two variables. Three variables requires a 3D visualization that most people find difficult to parse, and beyond that it's purely computational.
Sensitivity Analysis and What Changes When Parameters Shift
Once you have an optimal solution, the natural next question is how robust it is. Sensitivity analysis answers this by examining how the optimal solution changes when you vary objective coefficients, right-hand side values, or constraint coefficients. The allowable increase and decrease for each objective coefficient tells you the range within which the current basis remains optimal. If you're optimizing a production mix and the profit per unit of product A changes by less than the allowable range, you don't need to resolve the entire problem. The same basis is still optimal, though the objective value will change proportionally. The range of feasibility for right-hand side values works similarly. Within that range, the shadow price remains valid and you can predict the new optimal value without re-solving. Outside that range, the basis changes and you need a fresh run. In my experience, about thirty percent of post-optimization requests from stakeholders fall within the allowable ranges. The other seventy percent require full re-analysis, which is usually fast with modern solvers but can be tedious when you're doing it manually for a homework problem. One thing that trips people up is interpreting shadow prices for non-binding constraints. If a constraint is not active at the optimum, its shadow price is zero. Adding or removing a small amount of a resource that isn't fully utilized changes nothing about the optimal solution. Students frequently assign shadow prices to every constraint regardless of whether it's binding, which is incorrect. Check which constraints have slack before assigning economic interpretation to their dual values.
The computational complexity of linear programming itself is polynomial time thanks to interior point methods, though the simplex method technically has exponential worst-case complexity. In practice, simplex solves most problems in seconds or minutes regardless of size, which is why it remains the workhorse algorithm after nearly seventy years. Interior point methods tend to outperform simplex on very large dense problems but can be slower on sparse problems that arise in real applications like supply chain modeling. If you're starting out, work through at least five problems by hand using the simplex method. Then move to a solver for larger examples. The combination of manual understanding and computational efficiency gives you the best foundation. Pure hand calculation is fragile and slow. Pure reliance on software leaves you unable to diagnose when a model is producing nonsensical results. Both skills matter.