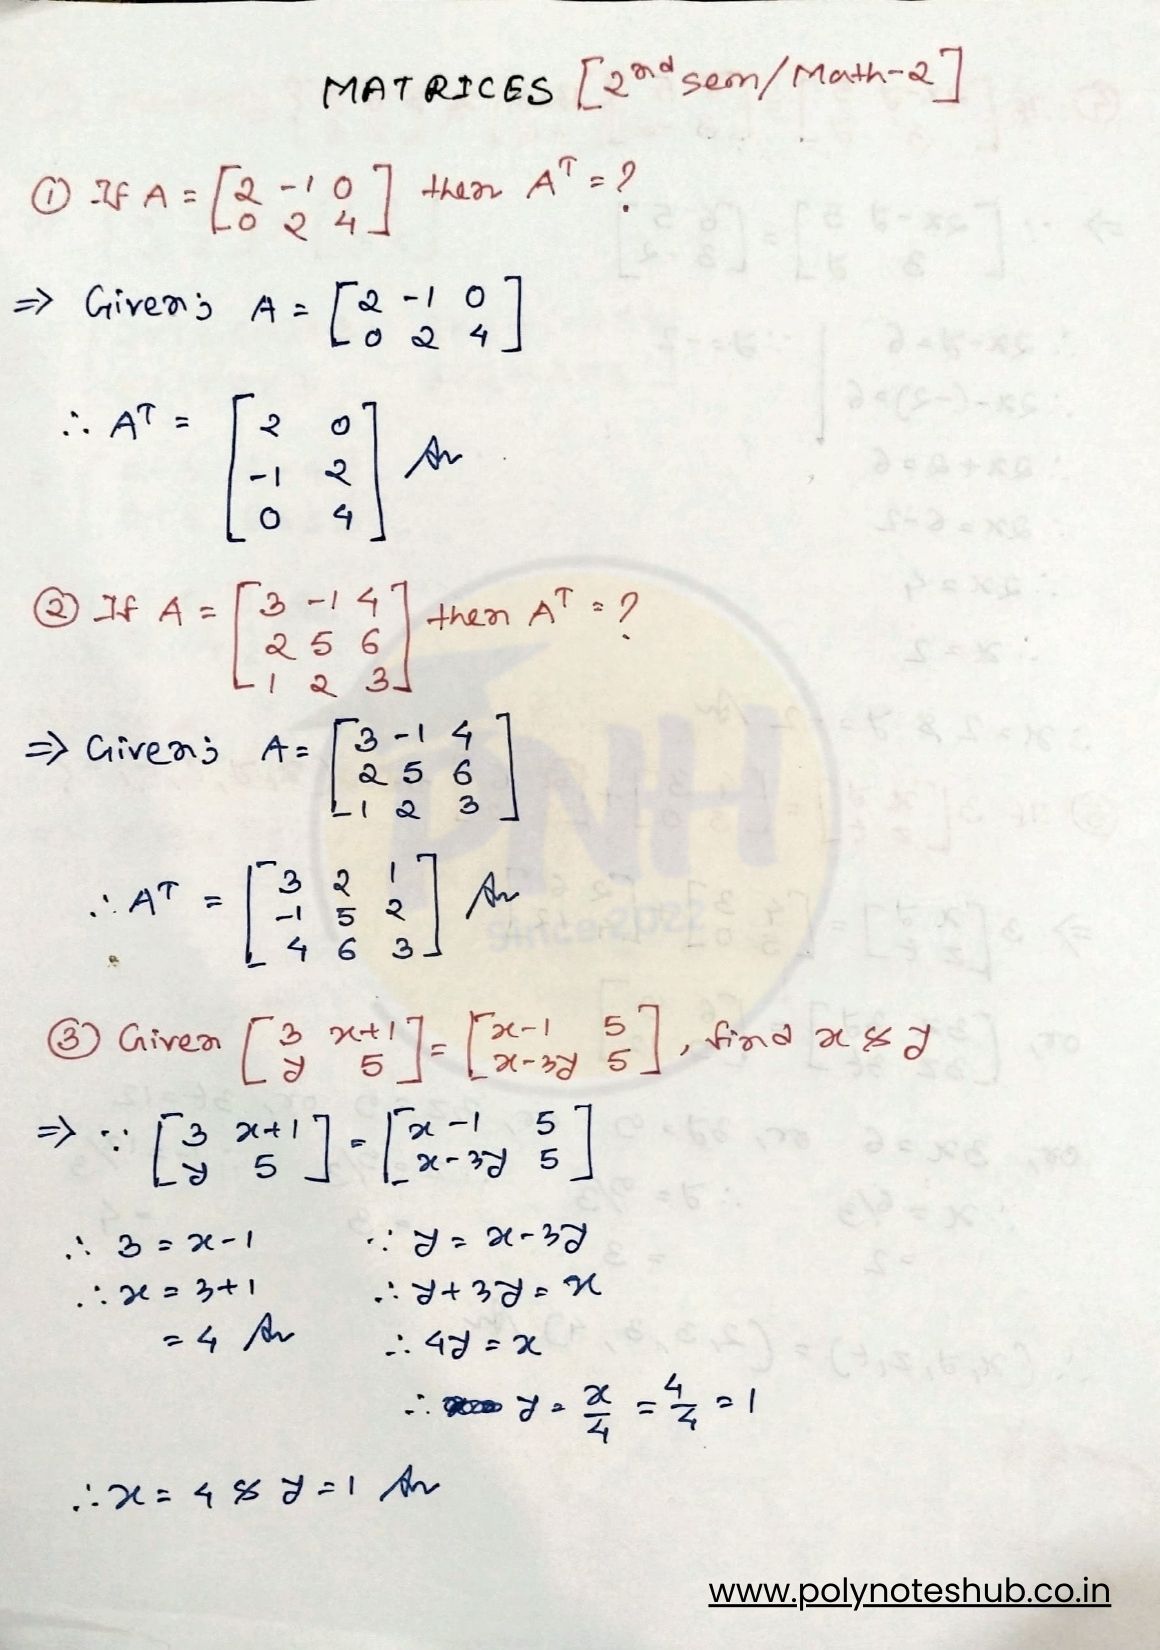
Working With Matrix Problems in Practice
Matrices show up everywhere once you get past introductory math. Whether you are solving systems of linear equations, working with transformations, or setting up data structures for machine learning, you will run into the same core question types repeatedly. Most people treat matrices as abstract symbols on paper, but they become much easier when you think about what they actually do: they transform vectors. I spent years grading linear algebra exams and later reviewing code that relied on matrix operations. The problems students and engineers struggle with tend to fall into predictable patterns. Understanding the patterns matters more than memorizing procedures.
Common Matrices Questions And Answers You Will Actually Use
The most frequent question asks how to solve a system of linear equations using matrices. You write the system in augmented form, then apply row reduction. The practical shortcut most textbooks skip is recognizing when a matrix is already in a convenient form. If it is upper triangular, you do not need full Gaussian elimination. Back substitution gets you the answer directly. This alone cuts computation time significantly on medium-sized systems. Another standard question involves finding the determinant. The cofactor expansion method works fine for small matrices, but it scales terribly. For anything beyond a three-by-three, I recommend using row operations to convert the matrix to upper triangular form first, then multiplying the diagonal entries. The determinant equals the product of those diagonal elements, adjusted by any row swaps you performed. Each swap flips the sign. People also ask frequently about matrix inversion. The formula using the adjugate and determinant is correct but impractical for anything larger than two-by-two. In real work, you use numerical methods like LU decomposition. If you are doing this by hand for a four-by-four or larger, you are either testing yourself or the problem is set up to reward spotting a shortcut. Sparse matrices are a common case where the shortcut exists. If most entries are zero, exploiting that structure changes the entire calculation.
I ran into a specific issue last year when a student was debugging a signal processing script. The matrix in question was supposed to be symmetric positive definite, but numerical precision errors made the Cholesky decomposition fail intermittently. The fix was not to switch algorithms but to add a small regularization term to the diagonal, effectively nudging the matrix away from the boundary where floating point errors become problematic. That solved the instability without materially changing the results.
Get the Full Details

Understanding Eigenvalues and Eigenvectors
Eigenvalues and eigenvectors generate a large number of questions because the concept is abstract until you see it in action. The defining equation is straightforward: a vector v is an eigenvector of matrix A if multiplying A by v produces a scalar multiple of v. That scalar is the eigenvalue. The standard approach finds eigenvalues by solving the characteristic equation, which is the determinant of A minus lambda times the identity matrix set to zero. This gives you a polynomial whose roots are the eigenvalues. Once you have an eigenvalue, you substitute it back and solve for the corresponding eigenvector by finding the null space of A minus lambda times identity. Here is a detail many guides miss: repeated eigenvalues do not guarantee repeated eigenvectors. A matrix can have a repeated eigenvalue but still possess a full set of independent eigenvectors, or it can be defective and lack them. The Jordan normal form handles the defective case, but for most practical purposes you just need to check the rank of A minus lambda times identity. If the nullity matches the algebraic multiplicity, you are fine.
For symmetric matrices, which come up constantly in physics and engineering, eigenvalues are always real and eigenvectors from different eigenvalues are always orthogonal. This property is extremely useful. If you encounter a symmetric matrix in practice, you can rely on these guarantees without verification. Most non-symmetric matrices do not share this behavior, so assuming it applies broadly is a common mistake.
Matrix Multiplication and Beyond
Matrix multiplication questions dominate introductory courses, and for good reason. The operation is foundational, and misunderstanding it creates cascading errors later. The basic rule is that the element in row i and column j of the product equals the dot product of row i from the first matrix and column j from the second. The inner dimensions must match, which is the first thing to check before attempting any multiplication. One counter-intuitive point is that matrix multiplication is not commutative. AB is generally not equal to BA. This matters in applications like computer graphics, where the order of rotations and translations determines the final transformation. Swapping the order produces a completely different result, and people who write transformation code without internalizing this often spend hours tracking down bugs that stem from a single swapped multiplication. Vectorization is another area where matrix thinking helps. If you need to apply the same linear transformation to many vectors, stacking those vectors as columns in a single matrix and multiplying once is dramatically faster than looping over individual vectors. This is not just a theoretical advantage. In practice, it can reduce runtime from minutes to seconds depending on the library and hardware you are using.

Singular Values and Decomposition
Singular value decomposition comes up in advanced courses and in applied work across statistics, image processing, and recommendation systems. Any matrix can be decomposed into U times Sigma times V transpose, where U and V are orthogonal matrices and Sigma contains the singular values on its diagonal. The singular values are always non-negative real numbers, which makes them more stable to work with than raw eigenvalues for general matrices. A useful but often overlooked application of SVD is rank approximation. If you keep only the largest k singular values and their corresponding vectors, you get the closest rank-k matrix to your original in terms of Frobenius norm. This is the mathematical basis for data compression and noise reduction. The tradeoff is obvious: you lose information, but sometimes the lost information is just noise. I once reviewed a project where a team was using a full covariance matrix for a classification task, and the matrix was nearly singular due to high correlation between features. Standard inversion failed or produced wildly unstable results. Applying SVD and dropping the near-zero singular values stabilized everything. The model accuracy actually improved because the noise from those near-zero components was removed. It is a reminder that a mathematically singular matrix is not always a dead end.
Handling Boundary Cases
Not every matrix behaves nicely. Ill-conditioned matrices are the most common practical problem. A matrix can be invertible in theory but numerically unstable, meaning tiny changes in the input produce enormous changes in the output. The condition number, which is the ratio of the largest to smallest singular value, tells you how bad the conditioning is. When it is very large, direct methods become unreliable, and you should consider iterative solvers or regularization instead. Another edge case is the zero matrix, which is trivial but worth noting explicitly. Its determinant is zero, it has no inverse, and every vector is mapped to zero. Questions involving the zero matrix sometimes appear in exams to catch people who apply formulas mechanically without checking whether the formula is valid. Division by a zero matrix is undefined, for instance. Complex entries add another layer of complication. If your matrix contains complex numbers, the concepts remain the same, but the conjugate transpose replaces the regular transpose in many formulas. Hermitian matrices, which equal their own conjugate transpose, generalize symmetric matrices to the complex domain. Their eigenvalues are real, which preserves one of the useful properties from the real case.
Practical Computation Tips
When working with matrices in code, always prefer established numerical libraries over writing your own routines. Libraries like NumPy, SciPy, or LAPACK handle edge cases, precision issues, and algorithm selection automatically. Writing your own Gaussian elimination may be educational, but it will fail silently on matrices that these libraries handle without comment. Memory layout matters more than most people realize. Row-major and column-major storage affect cache performance, which becomes noticeable with large matrices. If you are working with matrices large enough that performance is a concern, the choice of language and library can be as important as the algorithm itself. BLAS routines are optimized for this, and tapping into them through higher-level libraries gives you most of the benefit without managing details manually. For hand calculations, the best strategy is to identify the matrix structure first. Banded matrices, triangular matrices, diagonal matrices, and sparse matrices each have shortcuts that generic algorithms ignore. A generic solver will treat a diagonal matrix the same as a dense one, which is wasteful. Recognizing structure early saves time and reduces error risk.

I have found that the students and engineers who handle matrices well are not necessarily the ones who memorize the most formulas. They are the ones who have seen enough variations to recognize the underlying structure quickly. A few hours working through diverse examples builds that intuition faster than endless problem sets of the same type. The goal is to develop a feel for when a standard method applies and when the matrix is doing something unusual that requires a different approach.
Where to Find Additional Matrices Questions And Answers
There are several reliable sources for practice material. Textbook companion websites often provide worked solutions. Online platforms like Khan Academy and MIT OpenCourseWare cover the standard curriculum with varying levels of depth. For more advanced problems, mathematical competitions and graduate-level problem sets tend to feature matrices in less routine contexts. If you want a curated collection, the Linear Algebra community on academic forums maintains question banks organized by topic. The quality varies, but the most upvoted solutions tend to be thorough. I have also found that working through past exams from university courses is useful because it exposes you to the style of questions your instructor is likely to use. The patterns repeat within a department even if the specific numbers change. For coding-focused practice, Project Euler and similar sites include matrix problems that require both mathematical understanding and implementation skill. These are worth attempting after you are comfortable with the theory, since they force you to confront the practical constraints of working with matrices in software.
Whether you are studying for an exam or building something that depends on linear algebra, the matrix question types are largely consistent. The ones that trip people up are usually the ones that combine multiple concepts, like finding eigenvalues of a matrix defined through a transformation or using decomposition to simplify an otherwise difficult calculation. Practicing those hybrid problems is where the real learning happens.


