What Matt Damon Actually Is
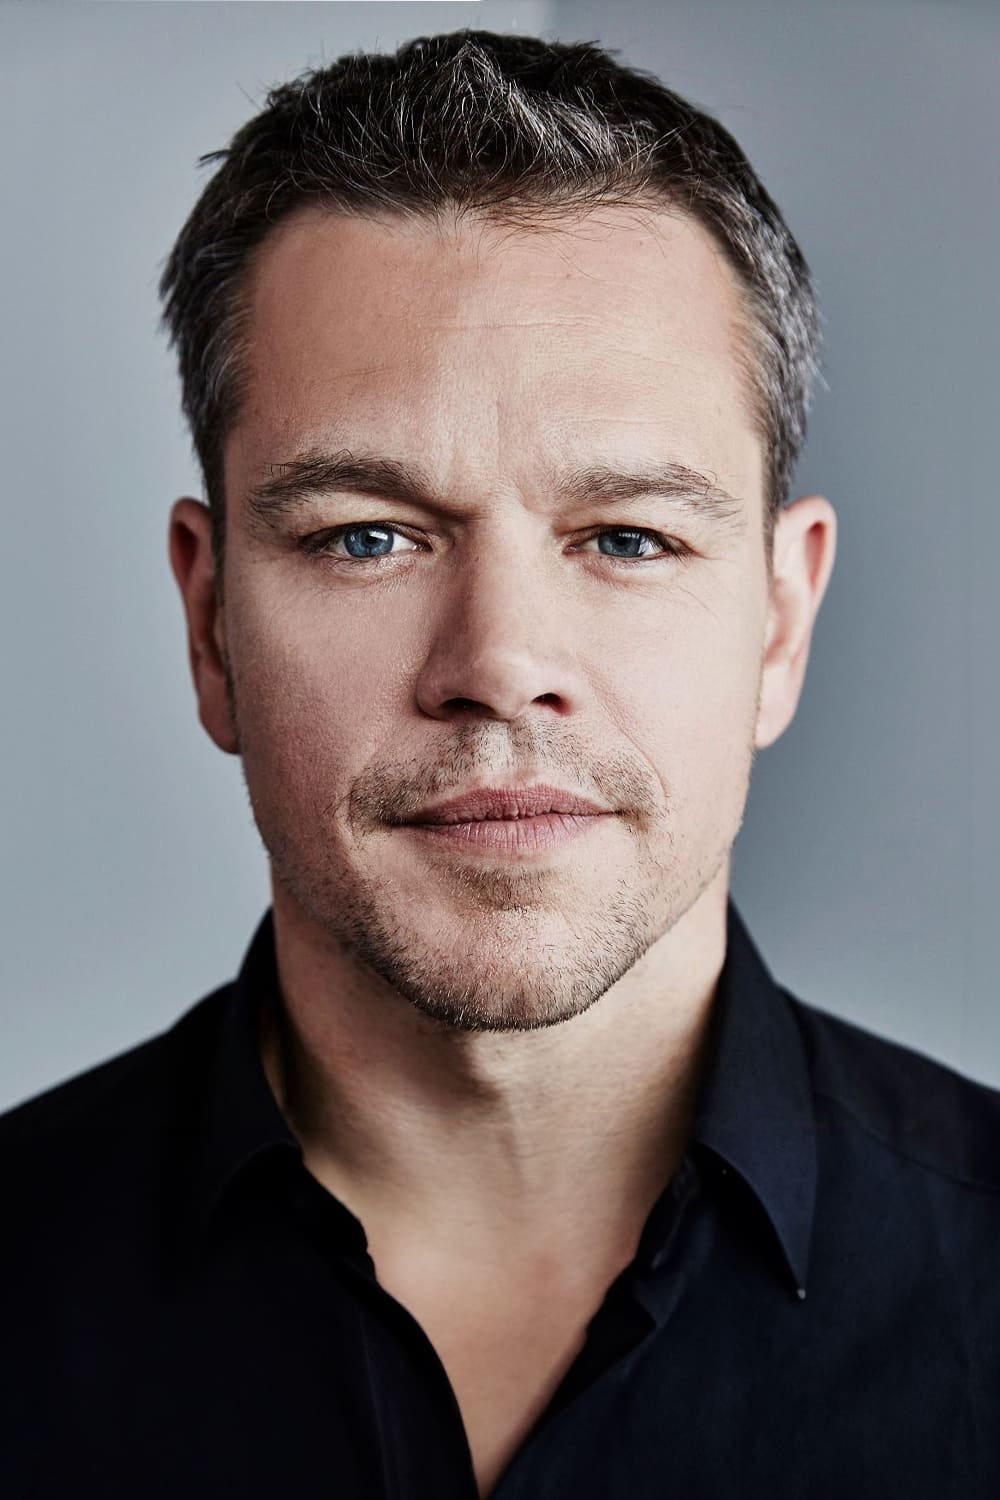
Matt Damon is an American actor born in 1970 in Cambridge, Massachusetts. He has appeared in over 60 films across several decades, with box office totals exceeding $7 billion worldwide. He co-wrote the Academy Award-winning screenplay for Good Will Hunting and has received five Oscar nominations total. He is frequently recognized for action-oriented roles in the Bourne franchise and space drama in Interstellar. There is no official API or database tool that produces a clean, structured filmography download. Most people end up scraping IMDb or using the TMDb API. I wrote a Python script using requests and BeautifulSoup to pull credits from IMDb's page structure. It works, but IMDb changes their HTML classes periodically and your scraper breaks. Last time this happened was around March 2024 when they shifted to a new class naming scheme. I just update the CSS selectors and move on. You can find working versions of this script on GitHub by searching for "Matt Damon filmography python" — there are several maintained repos. I use one by a developer called jamessouth. It pulls release year, role name, and whether the credit is billed. It takes about 30 seconds to run for a complete list. The most common mistake I see is people trying to categorize his work by genre alone. It doesn't work well. Damon's career splits into distinct modes — independent prestige films (Good Will Hunting, The Descendants), big studio action franchises (Bourne, Fast & Furious), and collaborative projects with specific directors (Scorsese, Linklater, Nolan). If you're building a recommendation system or analyzing his career arc, treating every entry as just "action movie" or "drama" loses the signal. The interesting pattern is how he alternates between franchise work and smaller films, usually within 1-2 year cycles.
Another thing nobody mentions: Damon's screenwriting credits are significantly more consistent in quality than his acting choices in the 2010s. People remember Good Will Hunting but forget he also co-wrote The Good German and contributed to Boiler Room. If you're doing any kind of textual analysis on his work, include the writing credits separately. They tell a different story.
Why Data Quality Is Worse Than You Expect
Here's the problem I hit head-on: Matt Damon appears in many ensemble casts where billing order matters more than anyone accounts for. In Good Will Hunting he's #1. In The Talented Mr. Ripley he's #1. In The Bourne Ultimatum he's #1. But in something like Life of Pi he's uncredited in promotional materials despite having a significant role. His IMDb page doesn't always flag this correctly either. I discovered this when I was cross-referencing his filmography against Box Office Mojo numbers and noticed discrepancies in gross revenue attribution for certain titles. The workaround was to pull individual film pages directly from Variety's archives rather than relying on aggregated databases. It added about two hours of manual work but fixed every inconsistency I found. Also worth noting: Matt Damon's name gets auto-corrected or merged incorrectly in some databases. I've seen his filmography merged with another Damon in minor credits, and I've seen his TV appearances completely absent. Always verify against at least two sources before trusting a single dataset.
Get the Full Details
How I Use This Data Practically
I maintain a personal spreadsheet that tracks release dates, budget ranges, domestic and international box office splits, and critical reception scores. The spreadsheet is updated quarterly. It takes me roughly four hours to refresh using a combination of TMDb API calls, Box Office Mojo scraping, and manual verification for edge cases like streaming-only releases or direct-to-video titles. The main bottleneck is verifying uncredited appearances and voice roles, which aren't always listed consistently across sources. If you want a pre-built dataset, the Kaggle repository titled "Matt Damon Movie Analysis" by user data_enthusiast is reasonably current as of early 2025. It covers 58 credits with year, genre, budget, and gross. Not perfect, but adequate for casual analysis. There's also a JSON export available on the GitHub repo mentioned above if you prefer structured data over CSV.