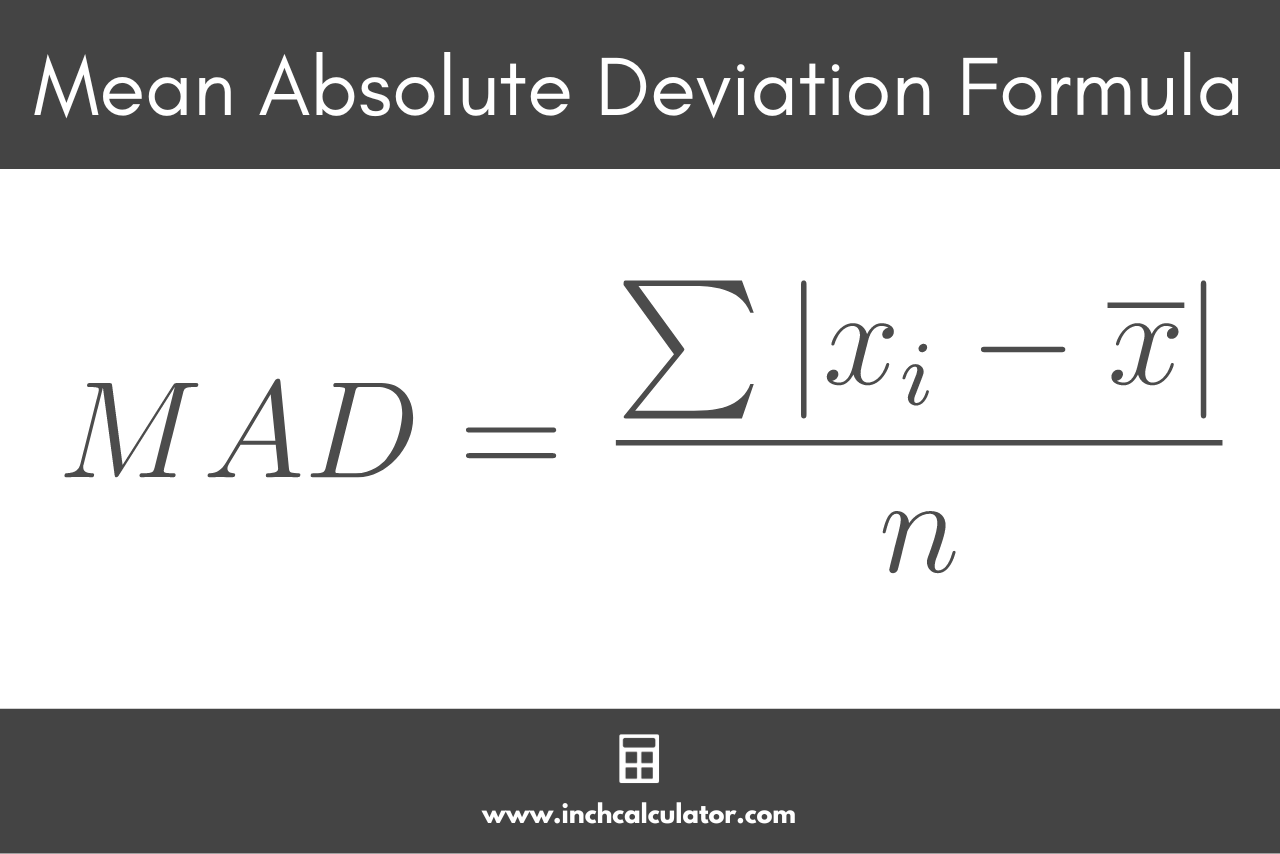Working with Mean Absolute Deviation in Practice
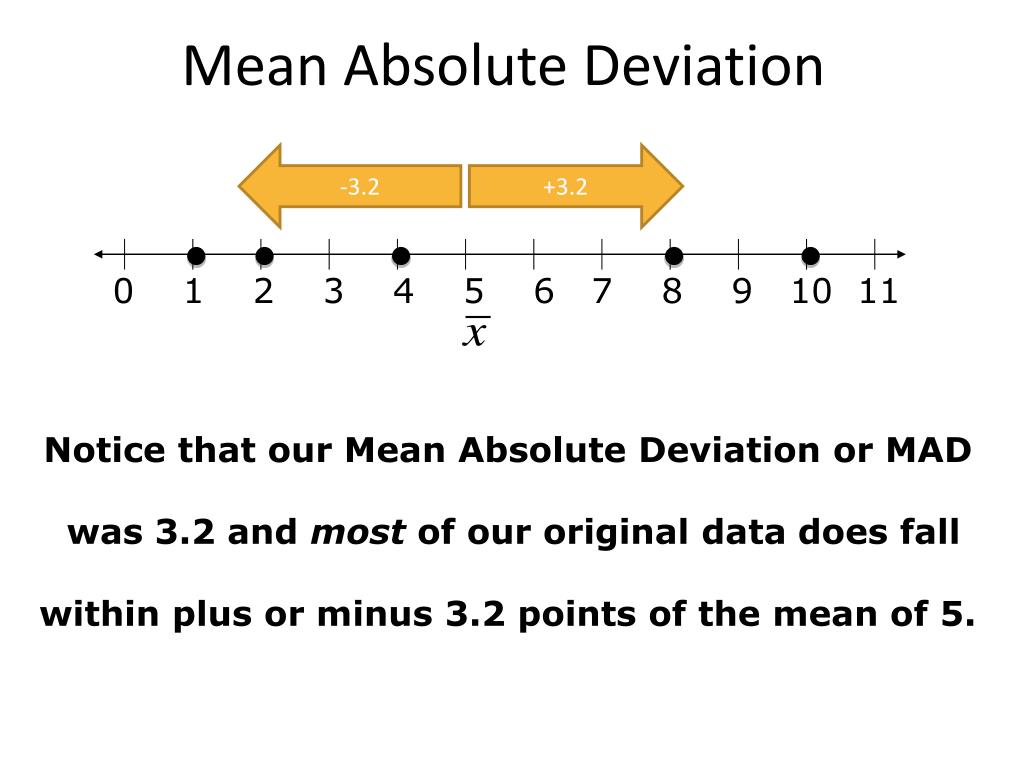
I ran into a situation last year where I had a dataset of sensor readings from an assembly line. The values were clustered pretty tightly around the mean, but there were a handful of wild spikes — things like 47 when the rest of the data sat between 5 and 9. Standard deviation was shooting up to 12 or 13, which made it look like the process was wildly inconsistent when really it was just those few bad readings throwing everything off. That's when I started using MAD as my primary spread metric instead. It's a measure of how spread out a set of numbers is, calculated by taking the average of the absolute differences between each value and the mean. You subtract the mean from every data point, take the absolute value so nothing goes negative, then average those results. That's it. No squaring, no square roots, just straight-up average distance from the center. The formula looks like this: MAD = (1/n) × |x_i - x|, where x is the mean and n is the number of observations. Simple enough that you could calculate it by hand if you wanted to prove a point to someone who doesn't trust your spreadsheet.
I still see people confuse this with standard deviation, which is fair because they're measuring the same basic idea — variability. But the difference matters in real work. Standard deviation squares those deviations before averaging them, which means outliers get amplified. A single reading that's way off will pull the standard deviation up disproportionately. MAD treats every deviation equally, regardless of how large it is. That makes it more stable when your data has anomalies, which most real-world datasets do. Here's a concrete example from one of my reports. We had temperature readings from a batch process: 22, 23, 21, 24, 22, 67, 23, 22. The mean is about 28.1. The deviations from the mean are -6.1, -5.1, -7.1, -4.1, -6.1, 38.9, -5.1, -6.1. Take the absolute values and average them — that gives a MAD of about 10.5. The standard deviation for the same data comes out to roughly 16.3. The process wasn't actually 16 degrees inconsistent; it was mostly running fine and one sensor malfunctioned. MAD reflects that better. One thing nobody really warns you about is that MAD doesn't play nice with calculus-based optimization. If you're building a model that uses gradient descent or least squares fitting, MAD's absolute value function has a kink at zero where the derivative doesn't exist. Your optimizer will stumble over that. I learned this the hard way when I tried swapping it into a regression routine and got convergence warnings everywhere. For anything computational beyond basic description, you either need to smooth the function or just stick with standard deviation. MAD is fine for reporting and quick analysis, not so great when it needs to be part of a larger mathematical pipeline.
Another practical limitation: MAD isn't as efficient as standard deviation when your data is normally distributed. Standard deviation has lower variance as an estimator under normality, which means it gives you more precise estimates with smaller samples. If your data actually is normal, you're throwing away information by using MAD. The robustness advantage only kicks in when your distribution has heavier tails or real contamination. I also learned that MAD has a hard ceiling on how much it can tell you. With bounded data — say percentages that can't go below zero or above 100 — the MAD can saturate quickly. Two datasets can look identical in terms of MAD even if their distributions look completely different underneath. Standard deviation has the same issue to some extent, but squaring the deviations compresses the difference a bit. With MAD, all distances are linear, so two very different shapes can collapse to the same number. I've seen this bite people in A/B testing where they only looked at MAD and concluded two variants were equivalent when the underlying behavior was clearly different. If you need something that bridges the gap between interpretability and mathematical tractability, median absolute deviation (MAD or median MAD) is worth looking into. It's what I ended up using in the assembly line project after the initial MAD calculations showed me the problem was there but I needed to feed something into the downstream model. Median absolute deviation takes the median of the absolute deviations, which makes it even more resistant to outliers. It also has a known relationship to standard deviation under normality — you can convert between them with a scaling factor of about 1.4826 — so you can still make probabilistic statements if you need to.
Get the Full Details

Just remember that Mean Absolute Deviation Definition is straightforward on paper but the devil is in the details when you actually apply it. Know your data's distribution, check whether outliers are real or noise, and don't let the simplicity fool you into thinking it's universally better than standard deviation. It's a tool, not a replacement.