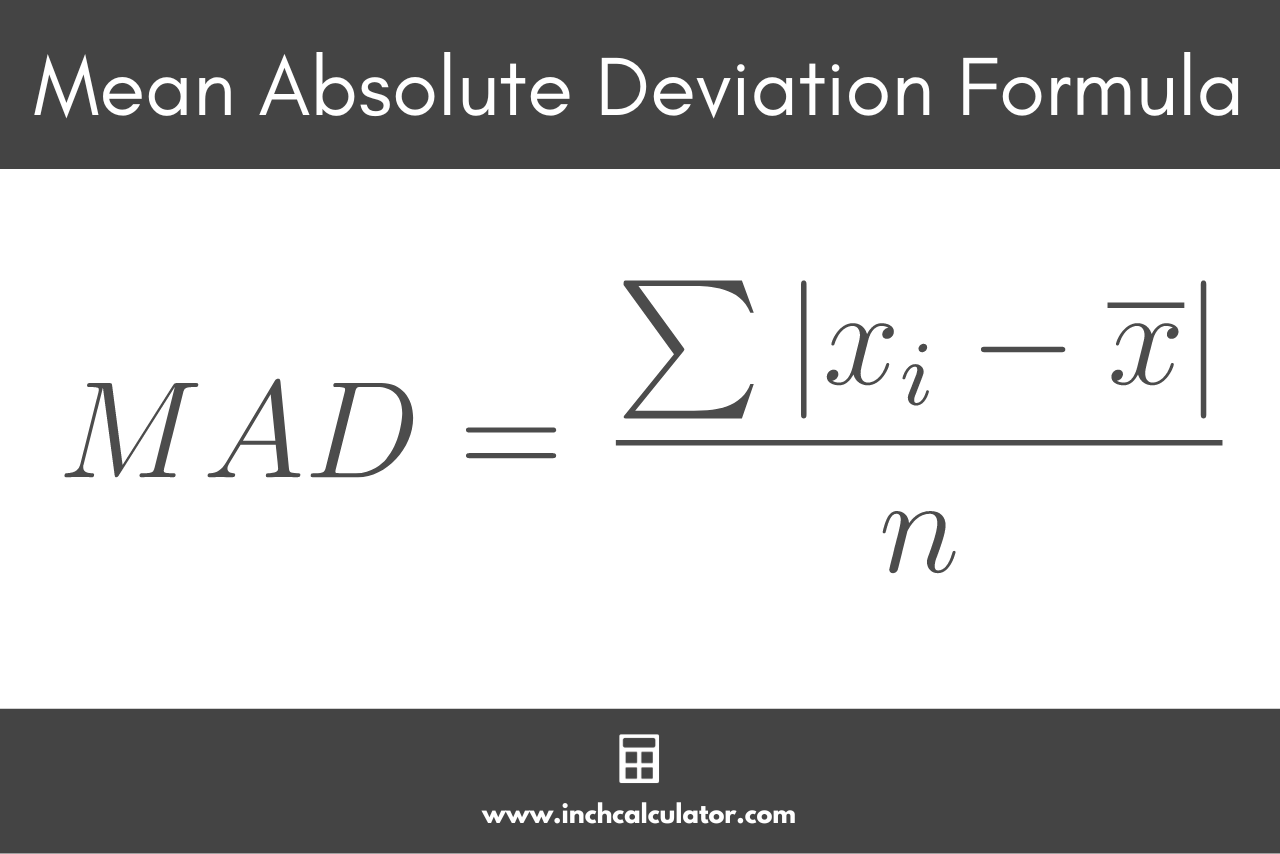
What MAD Actually Measures
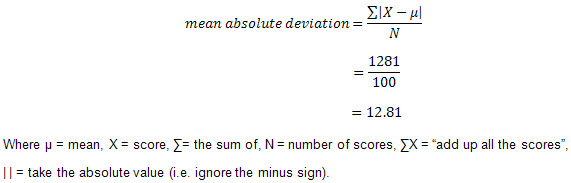
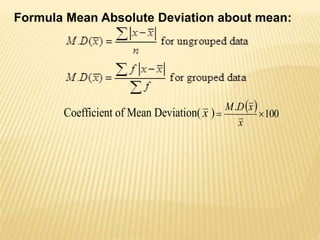
The mean absolute deviation is just the average of how far each data point sits from the mean. You subtract the mean from every value, take the absolute difference, then divide by the count. That's it. No squaring. No square roots. The result tells you the average distance of your observations from the center, expressed in the same units as your data. The formula is straightforward: MAD = (|x - x|) / n
Where x is each individual value, x is the mean, and n is the total number of observations. Simple arithmetic, nothing fancy about it. I still remember working with a manufacturing quality team back in 2014 who were trying to use standard deviation to flag bad production batches. The problem was their tolerances weren't symmetric — they cared way more about being under-spec than over-spec. Standard deviation penalized both directions equally through squaring, which made their control charts unnecessarily strict on one side and loose on the other. I had them switch to MAD for that particular line because it treats deviations linearly, and it gave them a much clearer picture of actual spread without the quadratic blowup that standard deviation produces on heavy-tailed data.
How to Calculate It by Hand
Let's say you have these five numbers: 4, 7, 9, 12, 18. First you find the mean. Sum is 50, divided by 5 equals 10. Then you take the absolute difference of each value from 10: |4-10| = 6, |7-10| = 3, |9-10| = 1, |12-10| = 2, |18-10| = 8. Add those up: 6 + 3 + 1 + 2 + 8 = 20. Divide by 5, and your MAD is 4. That means on average, each observation in this dataset sits 4 units away from the mean. Easy enough to do in your head if the numbers are clean.
Get the Full Details

When MAD Beats Standard Deviation
Standard deviation squares deviations before averaging, which means outliers get amplified. A single extreme value can dominate the result and make the measure of spread feel inflated. MAD doesn't do that. Because it uses absolute values, every deviation contributes proportionally to its actual size. This makes MAD more robust when your data has outliers or isn't normally distributed. The tradeoff is that MAD doesn't play as nicely with higher-level statistics. You can't decompose it the way you can with variance in ANOVA. If you're doing regression or building predictive models, standard deviation and variance are baked into the math everywhere. MAD exists outside that framework mostly, which means fewer built-in tools support it directly.
Common Pitfalls
One mistake I see people make constantly is confusing the mean absolute deviation with the mean absolute percentage error, or MAPE. They're related but not interchangeable. MAPE divides each absolute deviation by the actual value before averaging, so it expresses error as a percentage. If your data contains zeros or near-zero values, MAPE blows up. MAD doesn't have that problem because it stays in the original units. Another issue is sample versus population. The formula above gives you the population MAD. For a sample, some people apply a correction factor similar to Bessel's correction used for variance. The unbiased correction factor for MAD isn't as universally agreed upon as it is for standard deviation, and different textbooks handle it differently. In practice, if you're just describing your dataset, the unadjusted formula is fine. If you're doing inferential work, be explicit about which version you're using.
Using MAD in Excel and Python
Excel doesn't have a built-in MAD function, which is surprising given how common the metric is. You can construct it with SUMPRODUCT and AVERAGE in one formula. If your data is in cells A2 through A101, the formula would be: =SUMPRODUCT(ABS(A2:A101-AVERAGE(A2:A101)))/COUNT(A2:A101) In Python, you can compute it quickly with numpy or even from scratch. Here's the numpy approach:

import numpy as np
data = [4, 7, 9, 12, 18]
mad = np.mean(np.abs(data - np.mean(data)))
print(mad) This runs in milliseconds on datasets of any reasonable size. If you're processing time series data with thousands of rolling windows, a vectorized approach like this beats any loop-based implementation by orders of magnitude.
Where MAD Falls Short
The biggest limitation is that MAD is not differentiable at zero, which matters if you're trying to optimize it as part of a larger mathematical model. Gradient-based methods hit a wall there. If you need smooth optimization, you'd be better off using root mean square deviation or the standard deviation. Also, MAD ignores the direction of deviation entirely. In applications where you care about whether errors are consistently positive or negative — like forecast bias analysis — MAD alone won't tell you anything about systematic over- or under-prediction. You'd need to pair it with the mean signed deviation or look at a separate bias metric. For most descriptive work, though, it's a solid, interpretable measure of spread. It's easy to explain to non-technical stakeholders because the units stay the same. A MAD of 4 dollars means what it says. A standard deviation of 4 dollars also means that, but the calculation behind it involves operations that don't translate as cleanly into plain language.