Understanding Central Tendency Without Overthinking It
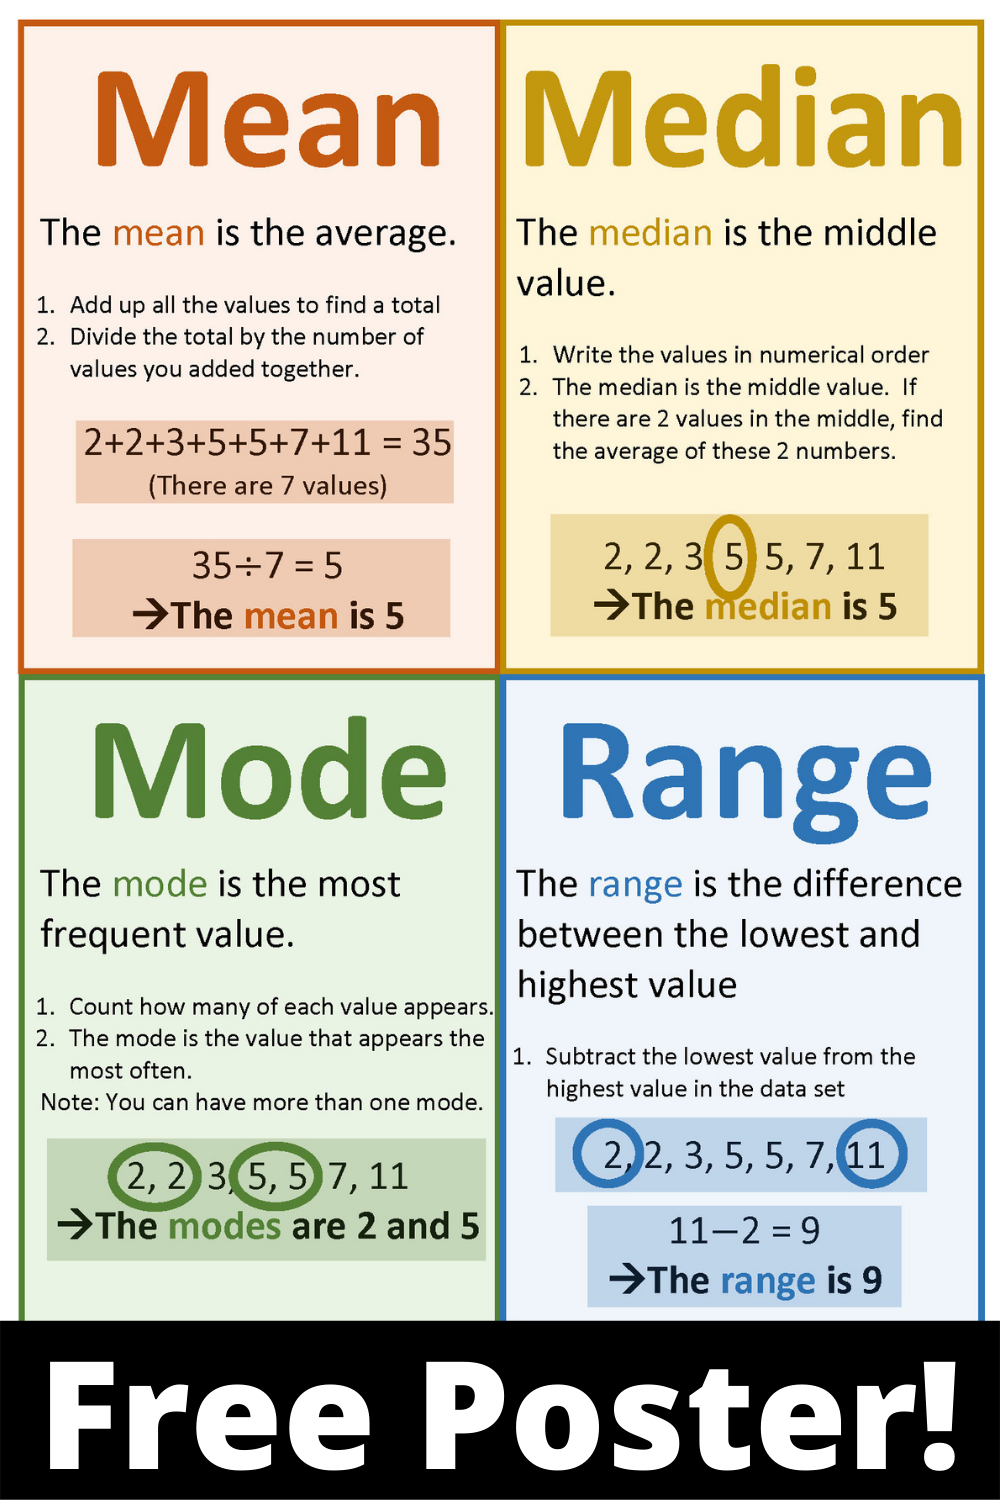
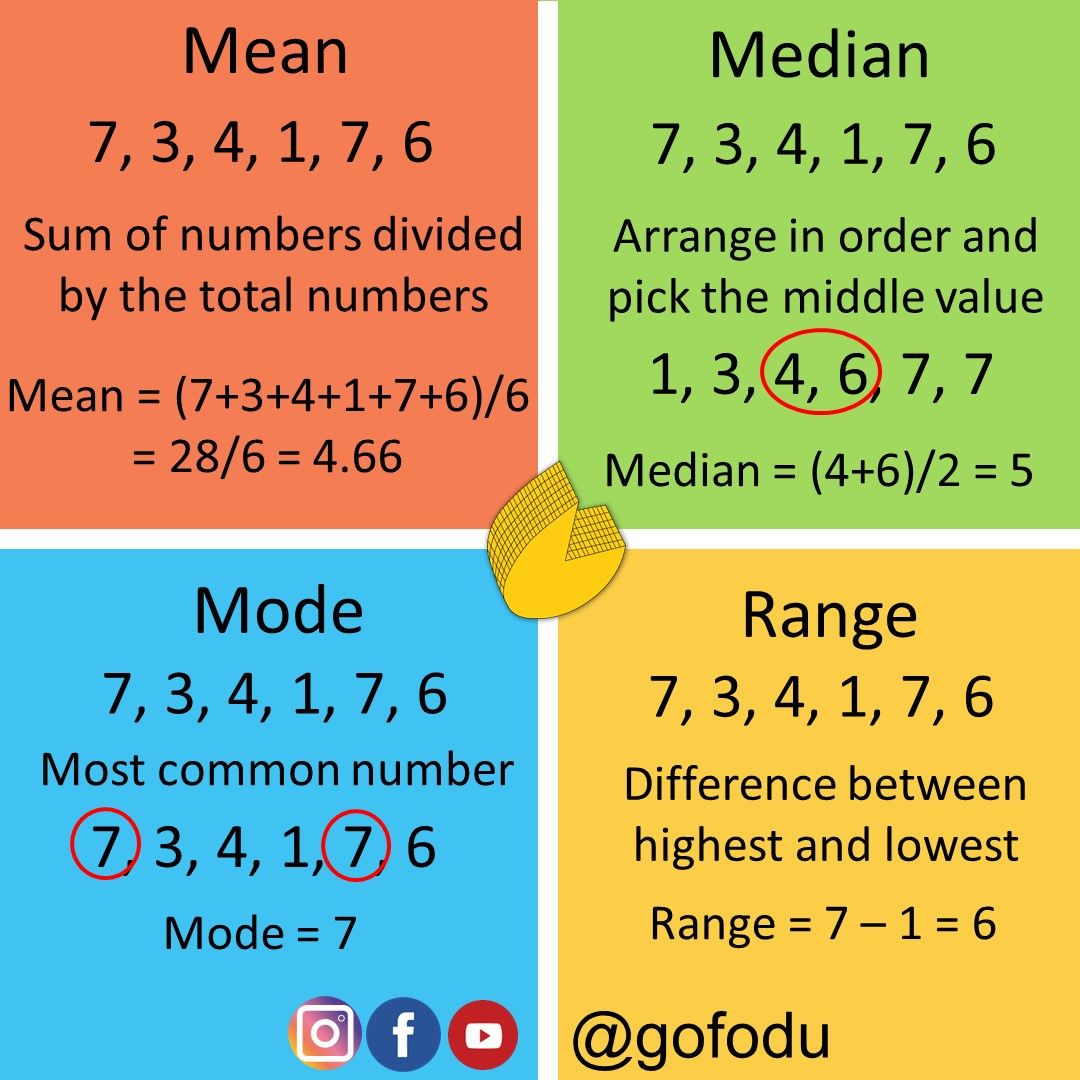
When you look at any dataset, you want a single number that summarizes where most of the values sit. The tools for that job are mean, mode, and median. Each one answers a slightly different question, and using the wrong one will quietly distort your conclusions. The mean is the arithmetic average. Add all your values together and divide by how many there are. It gives every single data point equal weight, which is powerful when your data is evenly spread. It is also fragile. A handful of extreme outliers can pull the mean far away from where most of your observations actually live. The median is the middle value when your data is sorted from lowest to highest. If you have an even number of observations, it is the average of the two middle numbers. The median does not care about magnitude, only position. That makes it robust against outliers and skew. It also means it ignores useful information about how extreme your tail values are.
The mode is the most frequently occurring value in your dataset. It works with both numerical and categorical data, which the other two measures cannot do. A dataset can be unimodal, bimodal, multimodal, or have no mode at all if every value appears exactly once. That ambiguity is something beginners rarely expect.
Mean Mode Median In Statistics: When to Use Which
I used to default to the mean for everything because it is simple and appears in every introductory textbook. That changed when I was analyzing annual home sale prices in a mid-sized city. The dataset had about twelve hundred records. The mean came out to roughly $412,000. The median was $298,000. The skew was caused by a small number of luxury properties selling in the $2 million to $5 million range, which dragged the mean upward by over a hundred thousand dollars. Presenting the mean as the typical home price would have been misleading. The median told the real story about what most buyers encountered. Here is how you decide in practice. Use the mean when your distribution is roughly symmetric and free of extreme outliers. This is common in controlled experiments, measurement errors around a stable process, or standardized test scores in large populations. Use the median when your data is skewed, has outliers, or comes from an ordinal scale where the gaps between values are not meaningful. Income data, response times, and housing prices fall here. Use the mode when you need to identify the most common category or value, especially with discrete or categorical data. It is also useful as a quick sanity check alongside the mean and median. I ran into another edge case that illustrates why context matters more than formulas. I was working with a dataset of customer support ticket resolution times. Most tickets closed within two hours, but a few required escalation and took three to five days. The mean resolution time was 18.4 hours. The median was 1.9 hours. The mode was one hour, which corresponded to the single most common outcome in the system. If I had reported only the mean, stakeholders would have assumed the support team was slow across the board. The median and mode together revealed a different pattern: the team handled the vast majority of cases quickly, with a long but thin tail of complex escalations. That distinction changed how we allocated staffing resources.
Get the Full Details
There are nuances that are easy to miss. One is that the mean minimizes the sum of squared deviations from itself. That property makes it the optimal summary point for least squares regression and variance calculations. The median minimizes the sum of absolute deviations, which is why it is preferred in robust statistics and certain optimization problems. Knowing which property you need matters more than memorizing definitions. Another nuance involves grouped or binned data. When your data is presented in intervals rather than raw values, you cannot compute a true mean, median, or mode without making assumptions. For the mean, you use the midpoint of each bin weighted by frequency. For the median, you interpolate within the median class. For the mode, you can estimate it using the modal class or apply Karl Pearson's empirical approximation, though that formula is unreliable with highly skewed distributions. I learned this the hard way when a report I relied on used binned salary data and a crude mode estimation that overstated the most common salary bracket by a significant margin. Going back to the raw data took longer than I wanted to admit. A counter-intuitive point that catches people off guard: the mean, median, and mode of the same dataset can all be valid summaries, yet they can each be correct for different reasons. In a perfectly symmetric distribution, all three coincide. In a right-skewed distribution, the mean is typically greater than the median, which is greater than the mode. But the relationship is not fixed. Bimodal distributions can invert that order entirely. A dataset with two peaks separated by a wide gap can have a mean that sits in the valley between them, a median that lands near one of the peaks, and a mode at the higher peak. Reporting only the mean would hide the fact that your data is not concentrated around a single center at all.
Here is the blunt part that people do not always want to hear. These three measures are descriptive, not predictive. They tell you where the center of your data is, not what will happen next. They also break down when your sample is too small, your measurement scale is inconsistent, or your data contains recording errors. A median calculated from fifty observations can swing dramatically if you add or remove a few values near the middle. A mode calculated from continuous data with little rounding is often meaningless because every value appears once. I have seen analysts pick the mode of temperature readings recorded to two decimal places and declare it the most common temperature, which is technically true but practically useless. If your data is heavily contaminated by outliers and you need a measure that resists their influence, consider the trimmed mean or the winsorized mean. A trimmed mean removes a fixed percentage of the lowest and highest values before calculating the average. A five percent trimmed mean discards the bottom 5 percent and top 5 percent, then averages the rest. This keeps the interpretability of the mean while reducing sensitivity to extreme values. I use trimmed means routinely for income and pricing data where outliers are real but not representative of the core population. For the actual calculations, the steps are straightforward once you know which measure fits your data. To compute the mean, sum all observations and divide by the count. To compute the median, sort the data and locate the middle position. To compute the mode, count the frequency of each value and select the highest. In software, these are one-line functions in almost every environment. R gives you mean(), median(), and which.max(table()) for the mode. Python with pandas gives you df.mean(), df.median(), and df.mode(). Excel has AVERAGE, MEDIAN, and MODE.MULT for datasets with multiple modes.
One practical tip that saves time: always plot your data before committing to a single summary number. A histogram, box plot, or strip chart will reveal skew, clustering, and outliers faster than any mental calculation. I spend about ten seconds looking at a plot before I decide which measure to report. That ten seconds has prevented me from publishing wrong conclusions more times than I can count. Let me be clear about what these measures cannot do. They collapse an entire distribution into one number, which means they discard information about spread, shape, and tail behavior. Two datasets can have identical means, medians, and modes but look nothing alike when plotted. Answer A's and B's distributions with the same central tendency often differ in variance or modality. Never let a single number stand in for a full description of your data. If you are working with small samples, non-normal data, or data with known measurement bias, the median or a trimmed mean is usually safer than the arithmetic mean. If you are working with categories, the mode is your only option among the three. If your data is clean and symmetric, the mean gives you the most mathematically convenient summary for downstream analysis. Pick the tool that matches your data, not the one that is easiest to explain.