Sample Mean Calculation in Practice
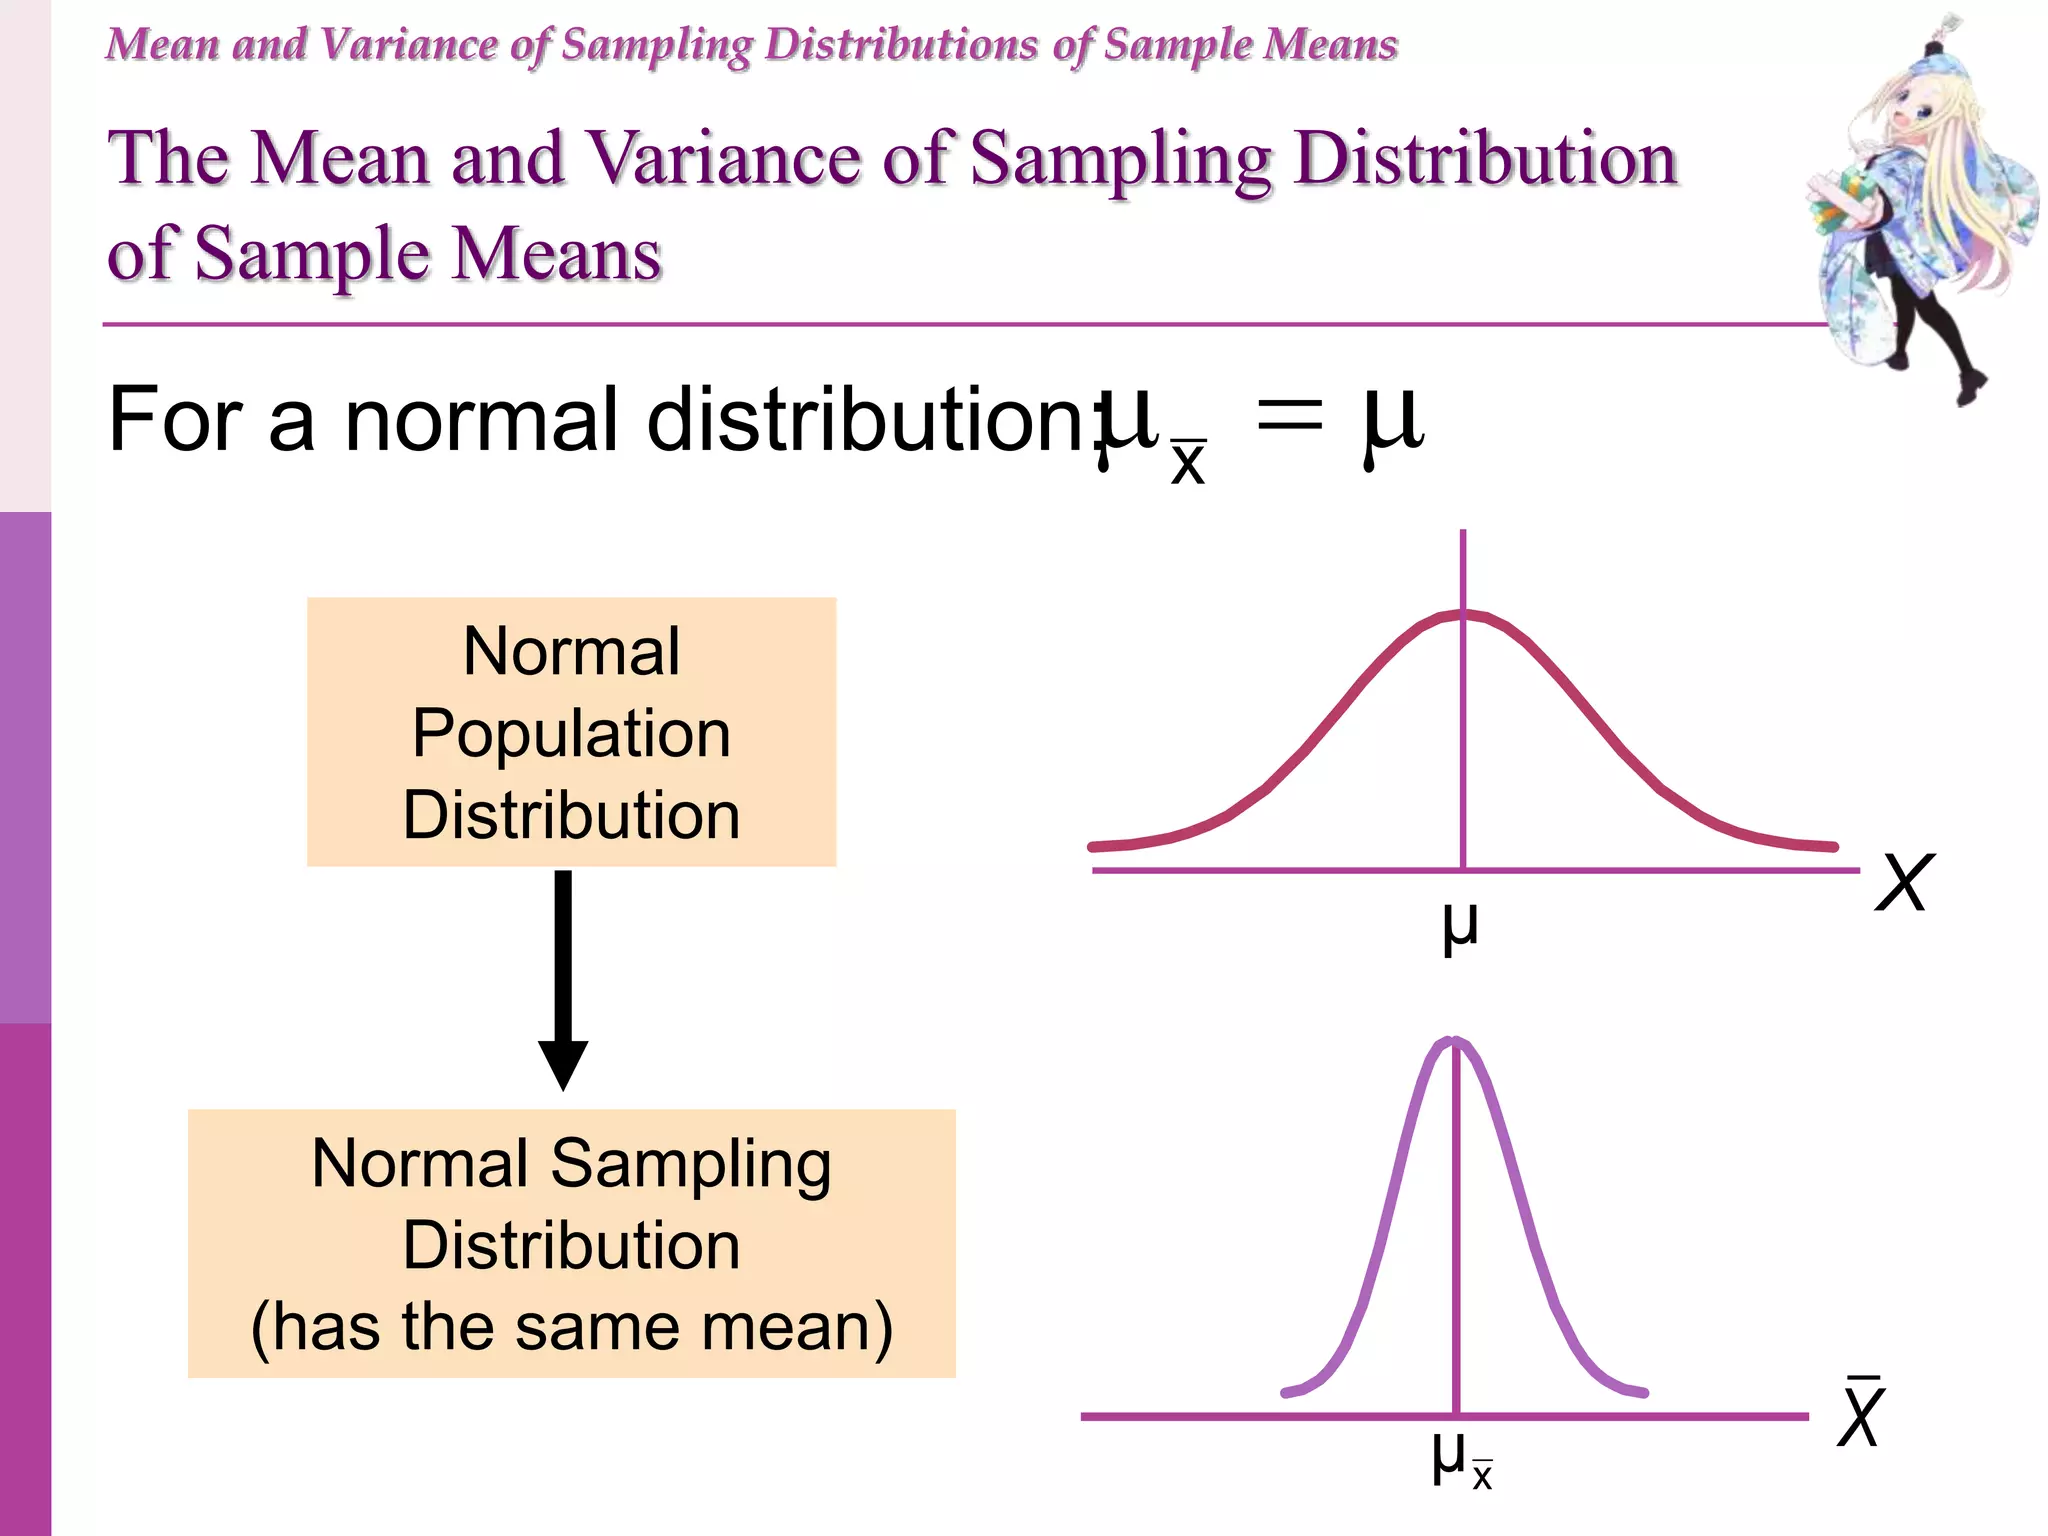
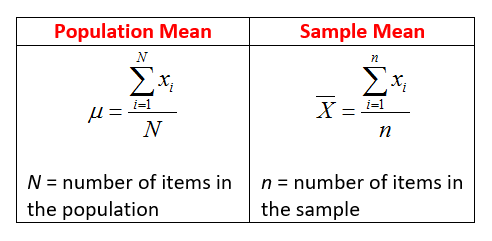
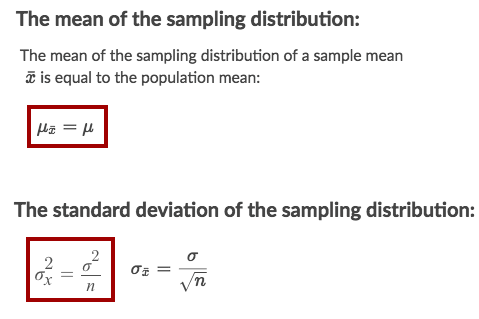
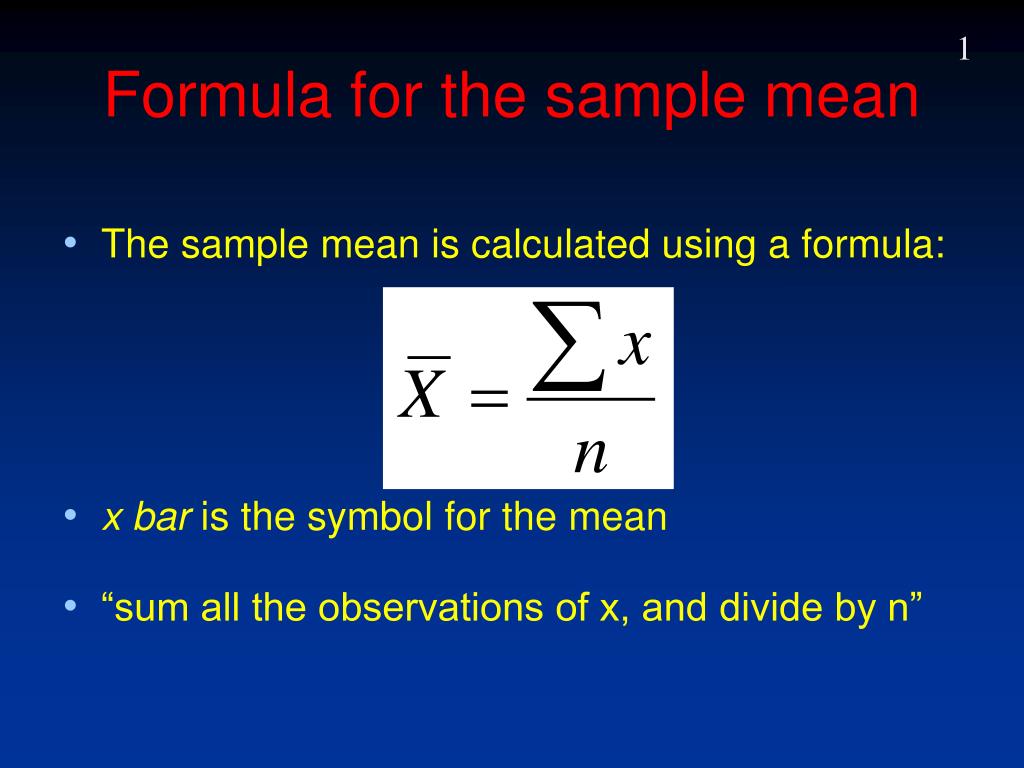
The sample mean is the sum of all observations divided by the count of observations. It sounds trivial, which is exactly why most people get tripped up when the numbers start misbehaving. I learned this the hard way when I was building a reporting pipeline for a logistics company in 2019. We were tracking delivery times across five regional hubs, and the mean delivery time looked perfectly reasonable at 3.2 days. The median was 1.8 days. That discrepancy should have been the red flag, but we shipped the dashboard anyway. Two weeks later, operations realized the mean was being dragged upward by a handful of shipments stuck in customs for three weeks straight. The actual typical delivery was nowhere near 3.2 days. This happened because the distribution was heavily right-skewed, and the mean of sample data doesn't account for skew on its own. You have to know what you're looking at before you trust the number. Take your dataset and add every value together. Then divide that total by how many values you have. That's it. Here's a concrete example from something I actually worked with last year. I had a small batch of customer satisfaction scores collected from a pilot study: 7, 8, 6, 9, 7, 8, 7. The sum is 52. There are 7 observations. 52 divided by 7 equals approximately 7.43. That's the sample mean. In Python, this is trivial with pandas or numpy, but doing it by hand at least once helps you internalize what's actually happening under the hood. One thing people routinely miss is the distinction between the population mean and the sample mean. The sample mean estimates the population mean, but they are not the same thing. When you compute the mean of sample data, you're getting a point estimate, not the true parameter. The difference between them is sampling error, and it shrinks as your sample size grows, following the relationship where the standard error of the mean equals the population standard deviation divided by the square root of n. This means doubling your sample size only reduces the standard error by about 29 percent, not 50 percent. If you need a tighter confidence interval, you have to quadruple your sample size, which costs four times as much in data collection.
There are practical edge cases where the formula breaks down or needs adjustment. One I ran into involved grouped frequency data. Say you have survey responses binned into categories: 10 people rated 1, 25 rated 2, 40 rated 3, 15 rated 4, and 10 rated 5. You can't just average 1, 2, 3, 4, 5 because that ignores the frequencies. The correct approach multiplies each value by its frequency, sums those products, and divides by the total count. That gives you (10 times 1 plus 25 times 2 plus 40 times 3 plus 15 times 4 plus 10 times 5) divided by 100, which equals 290 divided by 100, or 2.9. This is the weighted mean and it's the only way to handle grouped data correctly. Another edge case I deal with regularly involves missing values. If your dataset has NaN or null entries and you naively sum everything and divide by the total count including blanks, you'll get the wrong answer. The workaround is to filter out missing values before calculating. In pandas, the mean() function does this automatically by default, but older spreadsheet-based workflows don't always handle it cleanly. I once spent half a day tracking down why a rolling mean in an Excel model was drifting. The issue was that merged cells in the source data were being silently included as zeros, inflating the denominator. Once I unmerged and cleaned the data, the means aligned with the Python output within two decimal places. When the data is heavily skewed or contains extreme outliers, the arithmetic mean becomes a poor descriptor of central tendency. In those situations, consider using the median or a trimmed mean instead. A 10 percent trimmed mean, where you discard the top and bottom 10 percent of values before averaging, often gives a much more stable estimate. I use this approach for anything involving income data, response times, or transaction amounts. The mean of sample data is still mathematically valid in those cases, but it's describing something different from what most people expect it to describe. It's telling you the balance point of the distribution, not the typical experience.
There's also the matter of computational stability. When you're working with very large datasets containing values in the millions or billions, naive summation can introduce floating-point precision errors. The order in which you add numbers matters slightly due to how floating-point arithmetic works. For most everyday use this is negligible, but in high-frequency trading or scientific computing pipelines, Kahan summation or pairwise summation algorithms reduce the accumulated error significantly. numpy's mean function uses pairwise summation internally, so you get better precision than a simple loop would provide without writing any extra code. If you're working with time series data, be aware that the arithmetic mean treats every observation as equally spaced in time, which may not reflect reality. A mean of daily temperatures over a period where some days are missing is still valid as a descriptive statistic, but it shouldn't be interpreted as a time-weighted average without explicit adjustment. I've seen this mistake in quarterly business reviews where the mean revenue per day was calculated across uneven reporting periods, making one quarter look artificially strong compared to another simply because more days were captured. Here's a quick reference for the standard calculation workflow I use:
Get the Full Details
Step one is data cleaning. Remove or explicitly handle missing values. Step two is checking the distribution. Plot a histogram or box plot to spot skew and outliers. Step three is choosing the right measure. If the data is roughly symmetric, the mean is fine. If it's skewed, the median or trimmed mean is better. Step four is computing the mean with the appropriate function for your tool. Step five is reporting the standard error or confidence interval alongside the mean so people understand the uncertainty around the estimate. For implementation, the most common setup involves loading your data into a pandas DataFrame and calling mean() on the column of interest. The function accepts a numeric dtype, returns a float, and ignores NaN values by default. You can verify the result by cross-checking with numpy's mean function or even a manual sum divided by count on a small subset to confirm the output matches your expectation. The sample mean is foundational because it feeds into nearly every other statistical procedure. Variance, standard deviation, t-tests, confidence intervals, regression coefficients—they all build on or relate to the mean in some way. Understanding how to compute it correctly and when to question it is more useful than memorizing the formula. I still keep a small notebook of sample means from past projects as a sanity check when something looks off. Not because the formula is hard, but because the context around the number is where mistakes actually happen.