Computing The Mean Of Sample Means In Practice
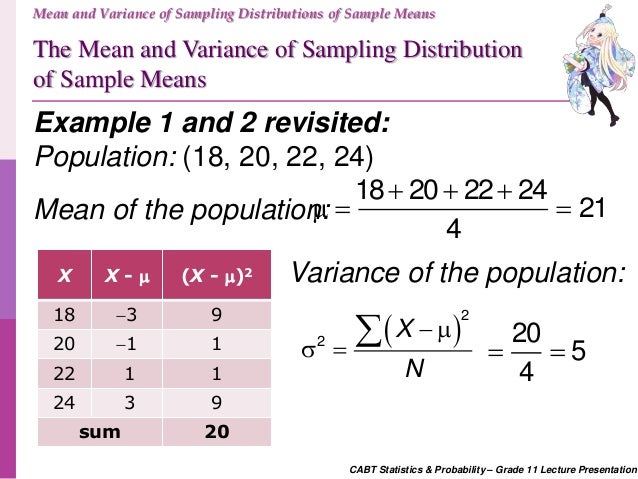
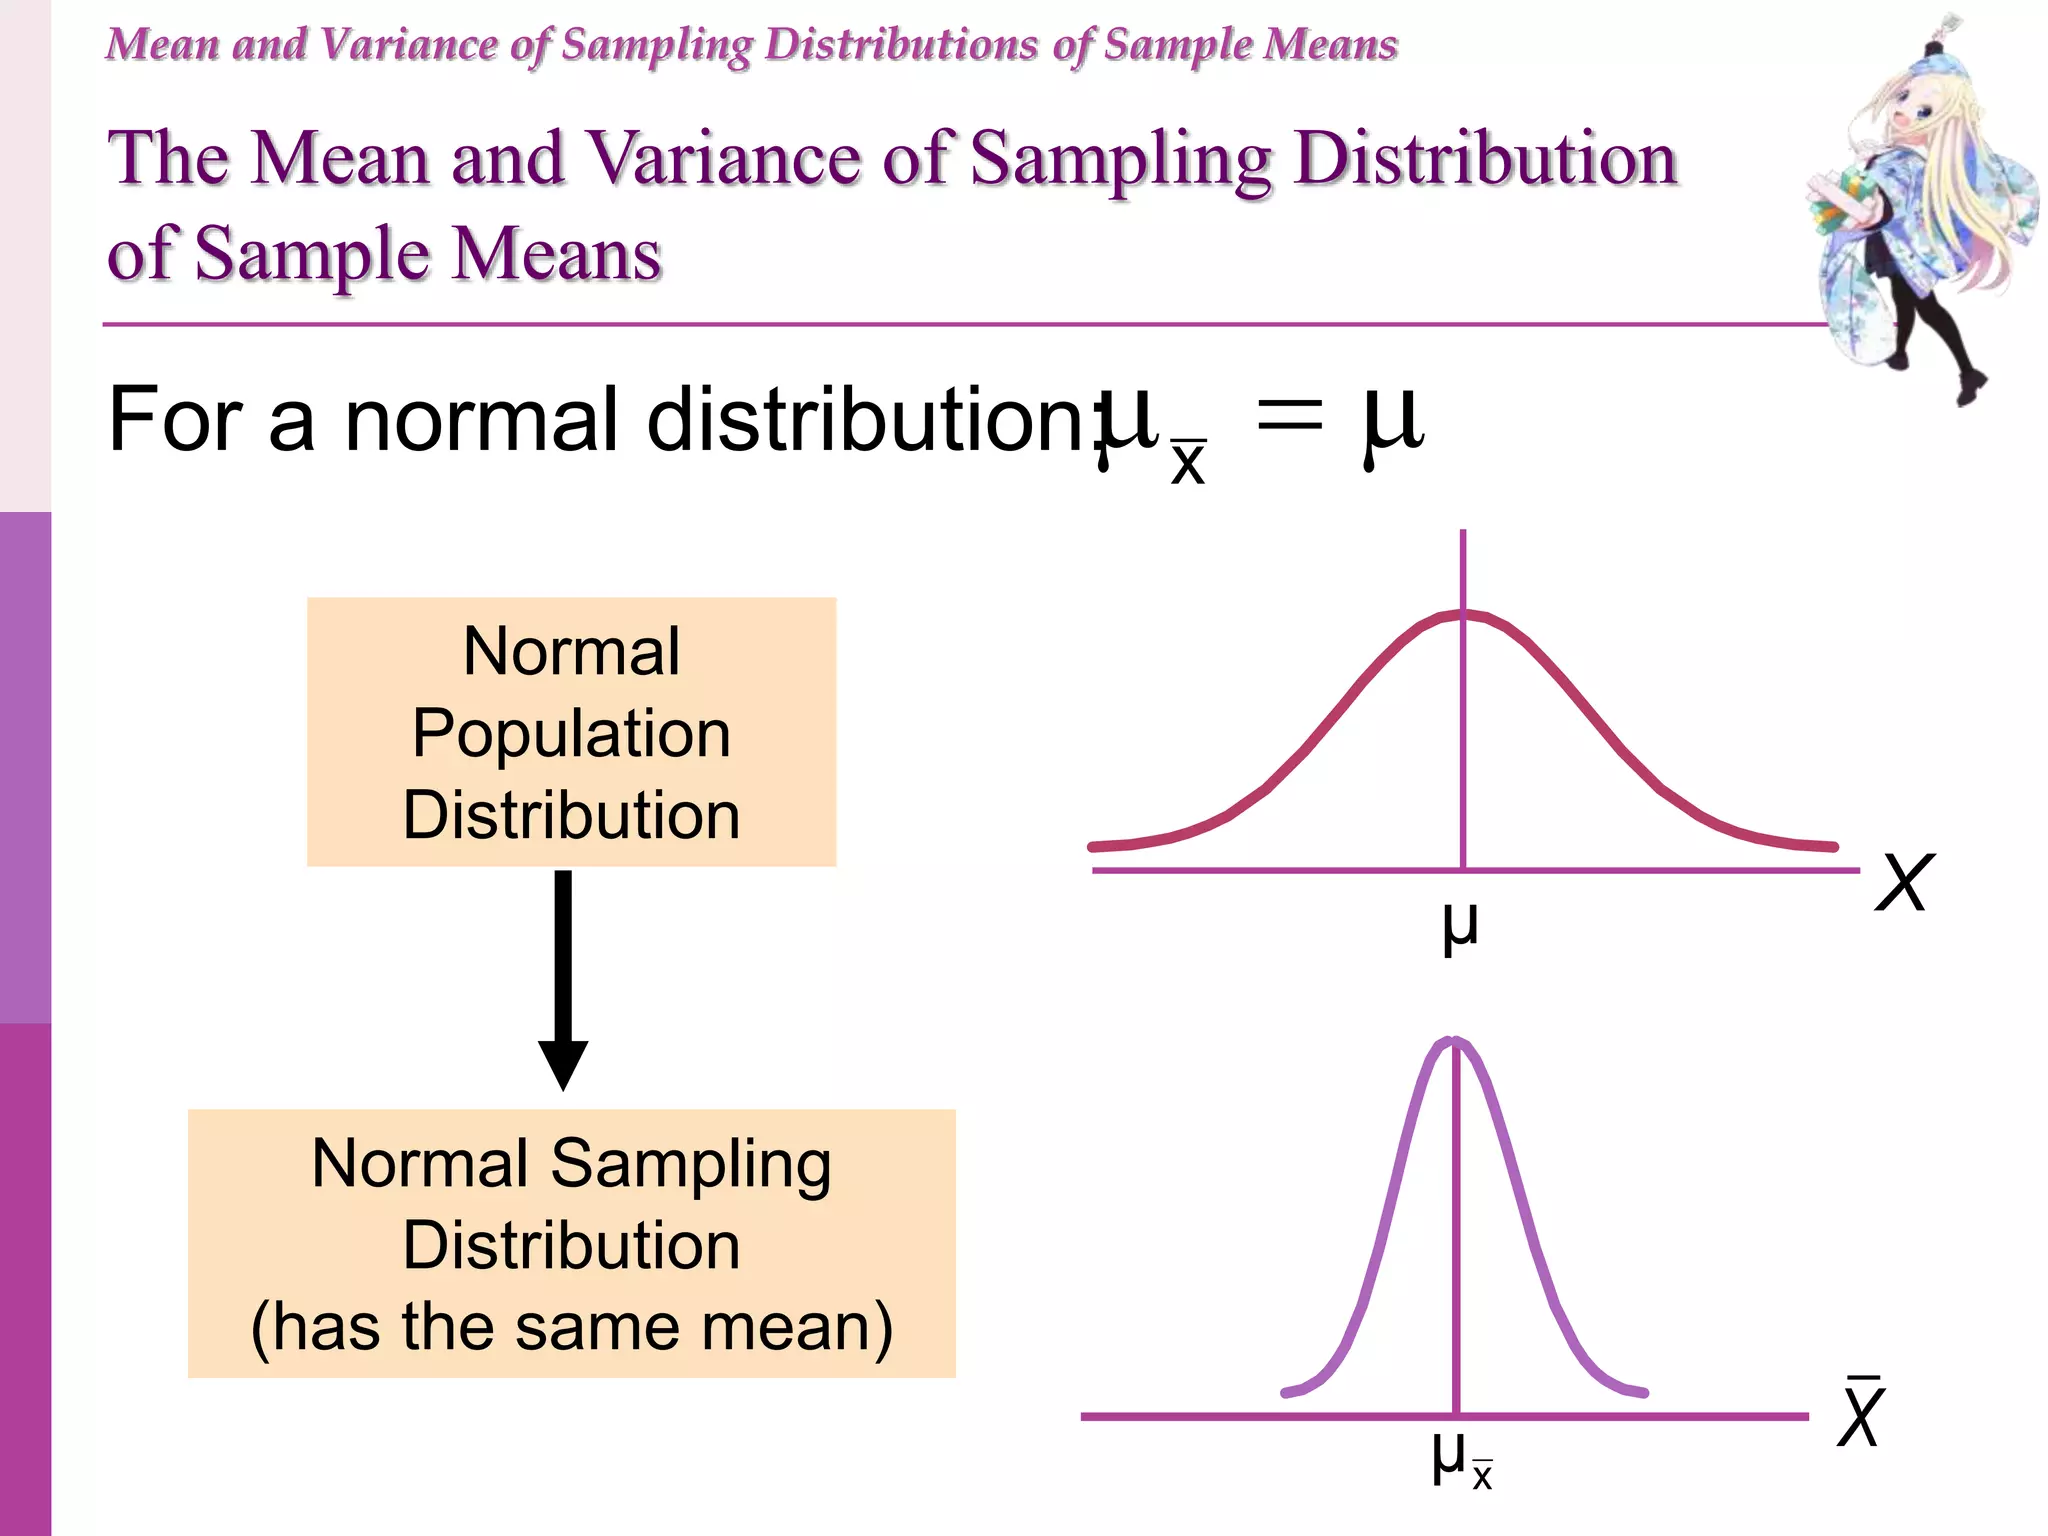
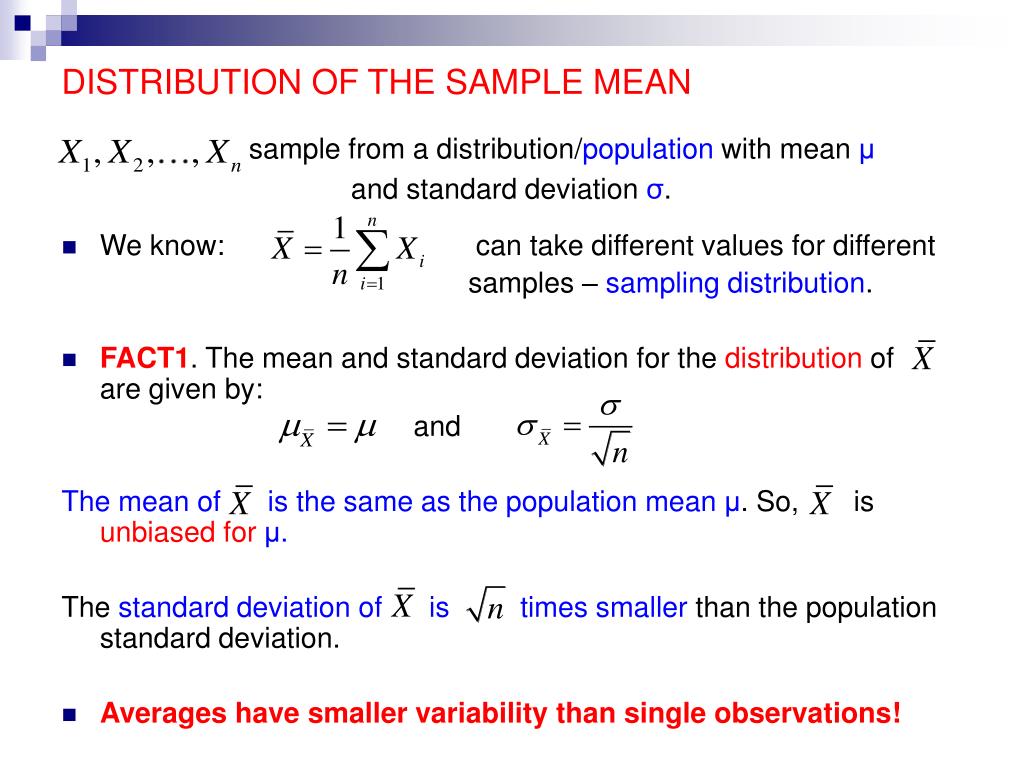
I keep running into people who treat the mean of sample means like it solves everything. It doesn't. It's one tool in a messy toolbox, and knowing when it fails matters more than knowing the formula. The mean of sample means is what you get when you draw multiple independent samples from the same population, compute each sample's average, then average those averages together. Mathematically, it converges toward the population mean as your number of samples grows. That's the textbook version. Here's the part most people skip. The standard error of the mean of sample means equals the population standard deviation divided by the square root of your total sample size across all groups. So if each sample has 30 observations and you draw 10 samples, your effective N is 300, and the standard error shrinks accordingly. This is why the method looks attractive—more samples, smaller error bars. But real data doesn't always cooperate.
The catch is that this only works cleanly when your samples are independent and drawn from a stable distribution. Violate either condition and the numbers start lying to you.
How To Compute It Without Breaking Anything
Here's how I actually set this up when someone brings me a dataset and says "just give me the mean of sample means." First, you confirm your sampling units make sense. Are the observations within each sample independent? If you're pulling time series data where observations are autocorrelated, treating them as independent samples will artificially deflate your standard error. I learned this the hard way on a manufacturing quality project where sensor readings every 30 seconds were being treated as independent. The computed confidence intervals were roughly half the width they should have been. I had to group the data into hourly blocks first, then compute means at that level before averaging across hours. Second, check that your sample sizes are roughly comparable. When you have wildly different sample sizes—say some groups with 10 observations and others with 200—the simple unweighted mean of sample means becomes biased toward the larger groups' population segments. In that case you'd want a weighted mean where each sample mean is weighted by its sample size. The difference can shift your result by several percent depending on how skewed your sample sizes are.
Get the Full Details

The actual computation steps:
Pull your raw data and define your sampling groups. These could be pre-defined groups like batches, shifts, or regions. Or you could be doing a resampling exercise where you draw random subsets.
For each sample group, calculate the individual sample mean. Store both the mean and the count for that group.
Average those sample means. If group sizes vary significantly, apply size-based weighting. If they're roughly equal, a simple arithmetic mean works fine.
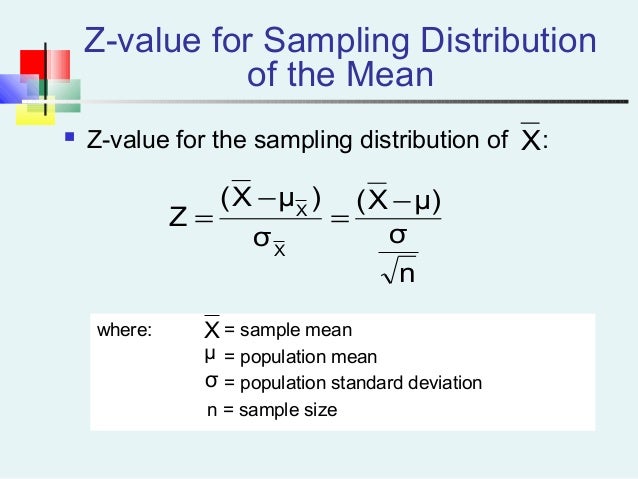
Calculate the standard error. For equal-sized samples, use the standard deviation of your sample means divided by the square root of the number of samples. For varying sizes, use a pooled approach or bootstrap the standard error. I'll be blunt about the scenarios where this approach gives you garbage results. If your underlying population is multimodal—say you're measuring transaction amounts where small purchases and large institutional transfers live in different clusters—averaging sample means won't reveal the structure. Each sample mean collapses two distinct behaviors into one number, and the mean of those means just gives you an average of averages with no information about the bimodality. In those cases you need mixture models or stratified sampling instead. Another failure mode: small sample sizes with heavy-tailed distributions. If each of your samples has fewer than 20 observations and your data comes from a distribution with high kurtosis like financial returns or network traffic spikes, the central limit theorem hasn't had enough room to smooth things out. Your mean of sample means will look stable but its standard error will be wrong. I ran into this with a dataset of server response times where most requests completed in under 100 milliseconds but a tiny fraction took over 10 seconds. With sample sizes of 15, the mean of sample means looked precise enough to act on. It wasn't. Switching to a bootstrap approach with 10,000 resamples gave me confidence intervals that were about three times wider.
Non-stationary populations are a third scenario. If the population mean drifts over time—which happens in A/B testing when seasonal effects interfere, or in longitudinal studies where the treatment changes the baseline—the mean of sample means becomes a average of different populations, not one population. You need to either model the drift explicitly or use methods like difference-in-differences that account for temporal changes.
A Practical Short Cut That Saves Time
When you're dealing with hundreds or thousands of samples and need this computed quickly, don't write a loop. Vectorize it. In Python with NumPy, you can stack your samples into a 2D array and call np.mean along the appropriate axis, then np.mean again. This is orders of magnitude faster than iterating through samples one by one, especially when you also need the standard error. A typical workflow with 500 samples of 50 observations each runs in under a second using vectorized operations versus maybe 15 to 30 seconds with a Python loop. If you're working in R, tapply or rowMeans does the same thing. In SQL, a subquery computing GROUP BY sample_id followed by an outer query averaging those results gets the job done without exporting data to a scripting language. I use the SQL approach when the data already lives in a warehouse because moving it out just to compute means adds unnecessary latency and coordination overhead.
Mean Of Sample Means Versus Other Aggregation Methods
People often compare this to a grand mean, which is the mean of all individual observations pooled together. These two are mathematically equivalent when all samples have the same size. They diverge when sample sizes differ. The grand mean weights each observation equally, while the unweighted mean of sample means weights each sample equally regardless of how many observations it contains. If you have five samples with 100 observations each and one sample with 10 observations, the unweighted mean of sample means gives the small sample the same influence as the large ones. That might be intentional if the small sample represents a genuinely important subgroup. It might also be nonsense if it's an outlier or an incomplete data collection. Know what you're optimizing for before you pick the aggregation method. There's also the median of sample means, which some practitioners use when they expect outliers in individual sample means. It's more robust but less efficient under normality assumptions. The choice between mean and median here depends on whether your primary concern is precision under clean conditions or resistance to contamination. Most of the time I've worked on, the data was clean enough that the mean was the right call, but I've seen teams default to the median out of habit without checking whether outliers were actually present. When the assumptions hold and your sampling design is sound, the mean of sample means remains a straightforward and computationally cheap way to estimate a population parameter. When they don't hold, it produces numbers that look reasonable but carry false confidence. The difference between those two states is usually visible in the distribution of your individual sample means. Plot them. Check for patterns. If they look like noise around a single center, you're probably fine. If they show structure, the simple aggregation method isn't giving you the answer you think it is.