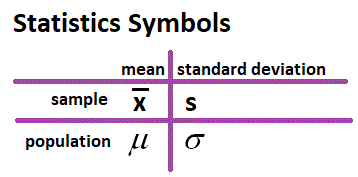Understanding the Mean Symbol In Statistics
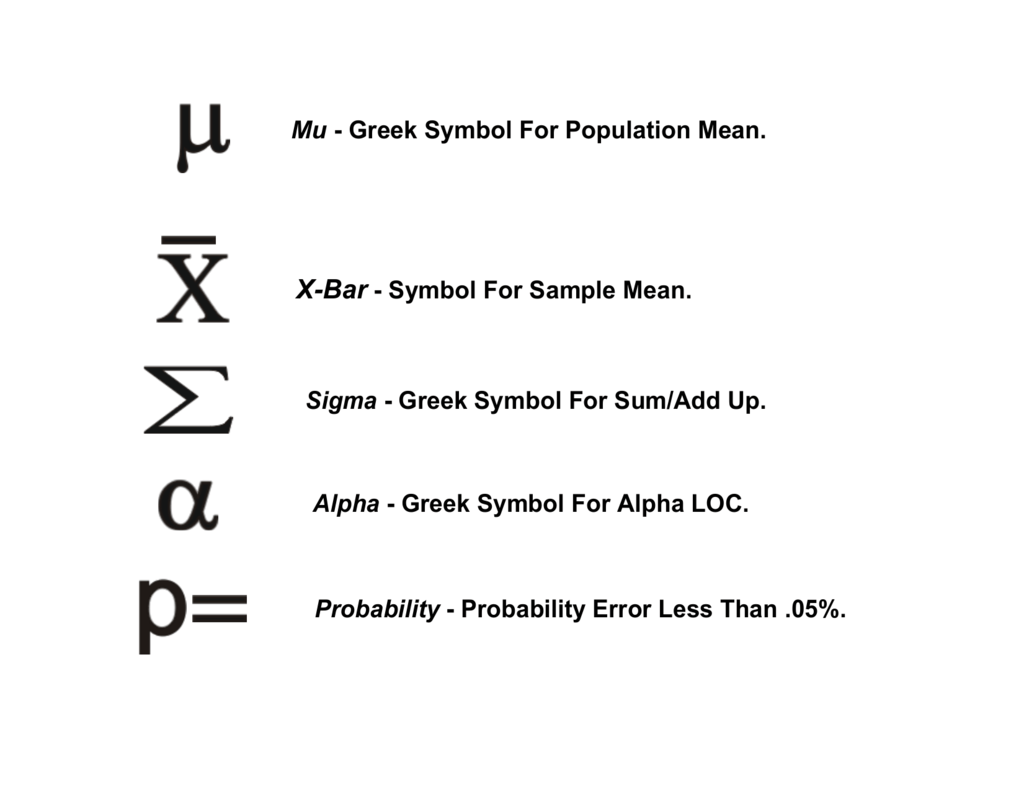
The Greek letter x-bar (x) is what you see in almost every introductory statistics textbook when someone writes about the sample mean. It's not decorative. It exists for a single reason: to distinguish a calculated average from a single raw observation. When you write x, you're saying "this number came from a set of values," not "this is one data point." The population equivalent is the Greek letter mu (), and mixing those two up in a paper or report will get you corrected within ten seconds by anyone who knows the field. The calculation itself is trivial. Add every value in your dataset, then divide by how many values there are. That's it. What people don't tell you early on is that the symbol carries assumptions. X assumes the data is interval or ratio scaled, symmetric enough that the mean is a meaningful central tendency measure, and that outliers aren't going to dominate the result. If any of those conditions are violated, the symbol still shows up in your output, but the number it represents becomes less useful. I ran into this exact problem last year working with a dataset of medical laboratory test results. The variable was serum creatinine levels across a patient population. On paper, calculating x was straightforward. In practice, the distribution had a heavy right tail caused by a small cluster of patients with renal impairment. The mean came out to 1.32 mg/dL, but roughly 60% of the patients actually had values below 1.1 mg/dL. The x was pulling the narrative in a direction that didn't represent the majority. I switched to reporting the median alongside the mean, and in the methods section I noted the skew. That's standard practice now, but it took me seeing it in production before I understood why textbooks always pair those two numbers together.
Here's how you actually compute it step by step with a real dataset. Say your values are 4, 7, 3, 9, 5. Sum them: 28. Count them: 5. Divide: 5.6. That's x. Done. Now do it with 200 values and you'll want a tool. Excel uses =AVERAGE(). R uses mean(). Python with pandas uses .mean(). All three give the same answer if your data is clean. None of them handle missing values the same way by default, which is worth knowing before you trust the output blindly.
When the Mean Symbol Misleads You
The biggest pitfall I see people fall into is treating x as a universal descriptor of central tendency. It isn't. In a bimodal distribution, the mean sits in the valley between two peaks and describes neither group. I worked on a project analyzing customer satisfaction scores from a product that had two distinct user segments: power users who rated it highly and casual users who found it confusing. The overall x was 3.4 out of 5, which sounded mediocre. But breaking it down, segment A averaged 4.2 and segment B averaged 2.6. The single mean obscured a real segmentation problem that needed addressing. Aggregating before analyzing is one of the most expensive mistakes you can make, and it costs almost nothing to check the distribution first. Another issue is weighting. The standard x treats every observation equally. In survey data, that's often wrong. If your sample has 80 young respondents and 20 older ones, the unweighted mean skews toward the younger demographic's answers. A weighted mean corrects for that, but it requires you to know the correct population proportions upfront. I've seen analysts use weighting variables incorrectly, applying them to the wrong column or applying them after filtering, which produces a number that looks precise but is actually biased. Always verify your weights sum to the expected total after any subsetting.
Get the Full Details

Computing the Mean Across Different Tools
In R, the mean() function has a trim argument that drops a percentage of observations from each tail before calculating. Setting trim=0.05 removes the top and bottom 5 percent, which is a quick way to get a more robust center estimate without switching to a median. The argument is undocumented in the help file but widely used in practice. In Python, numpy.mean() and pandas.Series.mean() both skip NaN values by default, but pandas hasna() behavior can change depending on the version, so checking your data for hidden nulls before calling .mean() saves debugging time later. Excel's AVERAGE function ignores text and empty cells, which is convenient until you have a column where zero is a valid data point and you've accidentally entered it as text. The function will skip it and give you a slightly inflated mean. AVERAGEA counts everything including text as zero, which is usually worse. The workaround is to verify your column with COUNT and COUNTA side by side. If they don't match your expectations, something in the data isn't numeric.
Reporting the Mean Correctly
When you write x into a report or paper, include the sample size and the standard deviation. X = 5.6, n = 5, SD = 2.3. That's the minimum. Anything less forces the reader to guess how reliable your estimate is. Confidence intervals are better. A 95% CI around the mean tells you the range where the true population mean likely falls, assuming your sample is representative and the central limit theorem applies. With small samples, that assumption is shaky, and the t-distribution should be used instead of the normal distribution. Most statistical software handles this automatically, but you need to know which one it's using. For grouped or frequency data where individual observations aren't available, the mean is calculated differently. You multiply each unique value by its frequency, sum those products, and divide by the total frequency. This is common in published tables where raw data isn't shared. The result is an approximation if the original grouping was wide, but it's the best you can do without the raw data. I've had to reconstruct means from published frequency tables for meta-analyses, and the rounding error from coarse bins can add up fast. Always note when your mean is derived from grouped data.
Alternatives When the Mean Isn't Appropriate
If your data is heavily skewed, ordinal, or contains extreme outliers that you can't justify removing, the median is the default alternative. It's the middle value when observations are ordered. Half are above it, half are below. It doesn't care about the magnitude of extremes, only their direction. In income data, which is almost always right-skewed, the median is the standard reported measure. The mean is still calculated and sometimes reported, but the median carries more interpretive weight. For robust estimation in the presence of contamination, the trimmed mean or the winsorized mean are better choices. A 20% trimmed mean drops the lowest and highest 20 percent of values before averaging. A winsorized mean replaces those same extremes with the nearest remaining value instead of removing them. Both reduce sensitivity to outliers while preserving more information than the median. They're standard in psychology and economics but underused in other fields where they'd be appropriate. If you're working with data that has measurement errors or data entry mistakes, these approaches clean up the signal without requiring you to manually hunt down individual bad values. The mean symbol is simple. The situations where it fails are not. Knowing when to use it, when to adjust it, and when to abandon it is what separates someone who can run a calculation from someone who can interpret the result correctly.