Let's Get the Terminology Straight Before This Goes Any Further
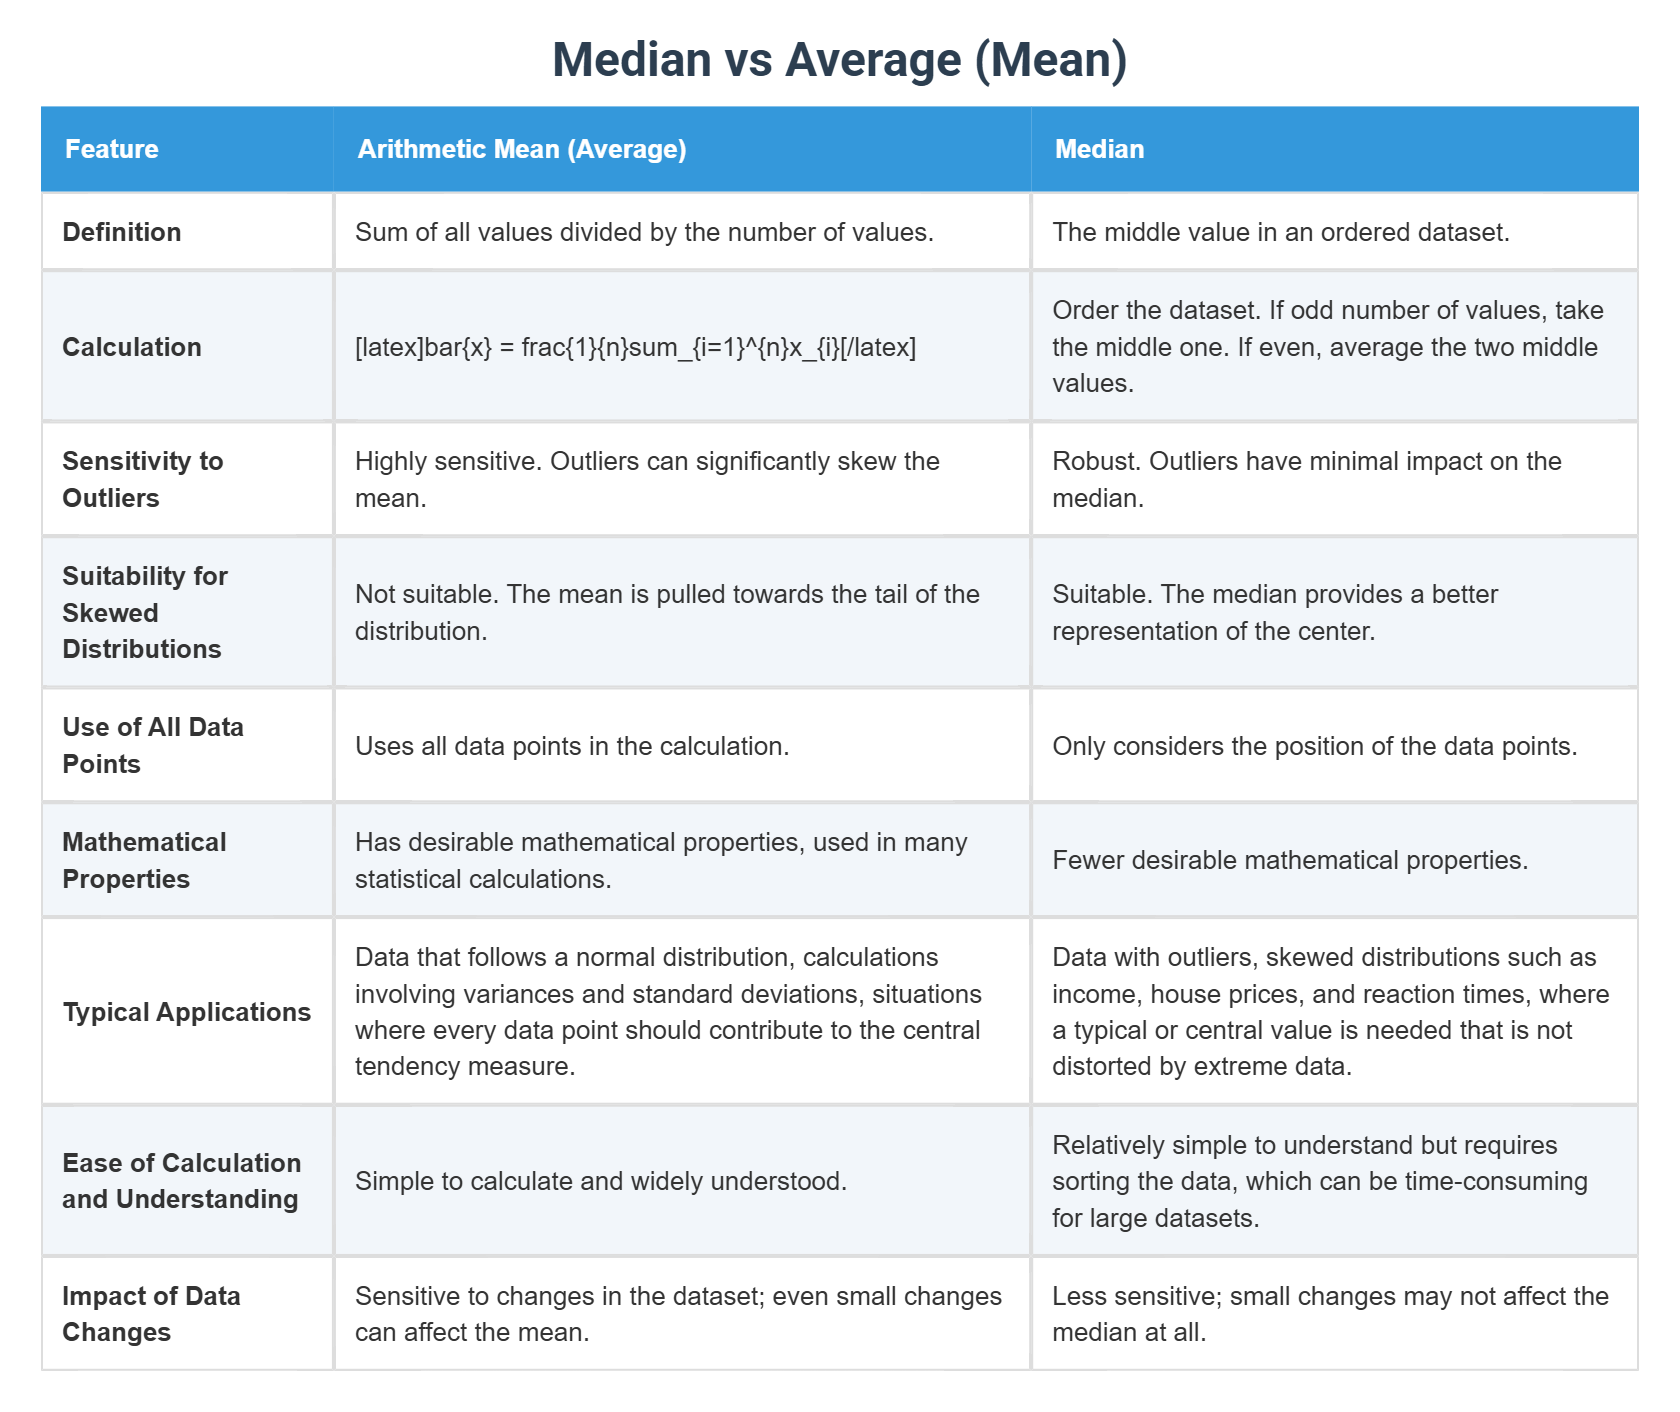
People use the word "average" to mean three different things depending on who they're talking to. If you're in finance, average usually means the mean. If you're talking about house prices with a realtor, they might actually be referring to the median without realizing it. This mismatch causes more bad decisions than anything else I see in data work. I've spent years cleaning up confusion between these three measures, and the problem isn't that people don't understand the math. It's that they don't understand which one applies to their specific situation. Start by writing down your dataset. A simple list of values on paper or in a spreadsheet is fine. To get the mean, add every value together and divide by the total count. That's it. For a dataset of 12, 15, 18, 22, and 28, the sum is 95. Divided by 5, the mean is 19. The median requires you to sort the data first, then find the middle value. Sorted, the same dataset stays 12, 15, 18, 22, 28, and the median is 18. If you have an even number of values, take the two middle numbers and average them. The mode is simply the value that appears most frequently. In this dataset there is no mode because each value appears once. The mean is sensitive to outliers by design. I learned this the hard way in 2019 when I was analyzing support ticket resolution times for a SaaS company. The mean resolution time looked healthy at 4.2 hours. The median was 1.8 hours. My initial report would have told leadership everything was fine. It wasn't. A small cluster of tickets involving a failed database migration had resolution times of 800 plus hours because they were stuck in an approval queue nobody knew about. The mean was being dragged upward by those long-tail cases while the median showed that most customers were getting reasonable service. I ended up switching the primary metric to median and reporting mean separately with a footnote explaining the distribution skew. Leadership actually cared more about the honest picture once they understood what was happening instead of being shown a single smoothed-over number.
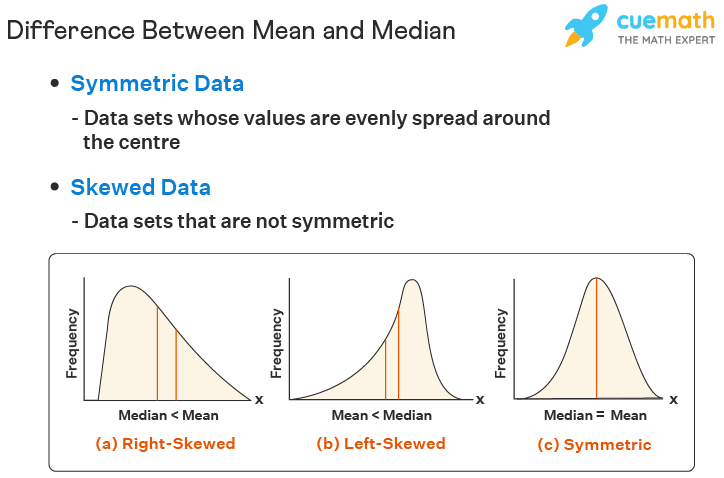
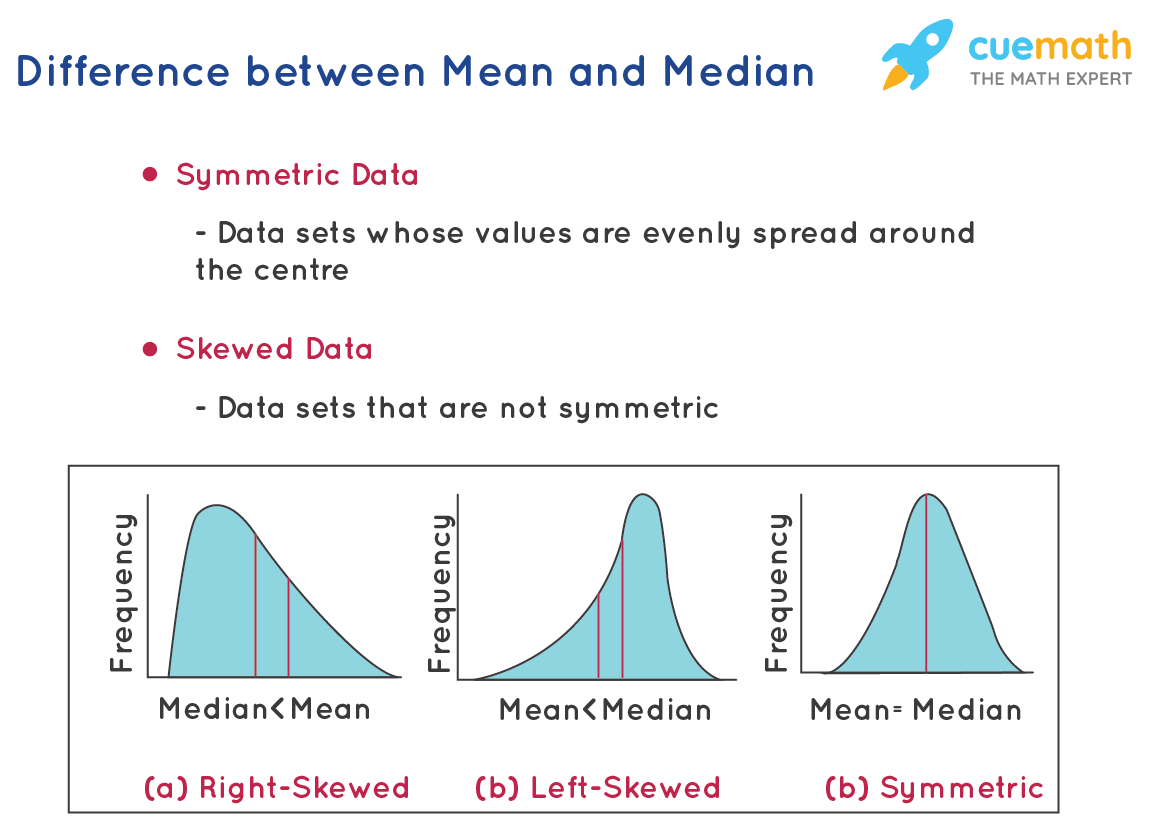
Here's the part most people skip. The choice between mean and median isn't just a statistical preference. It determines whether your stakeholder sees a central tendency that reflects their own experience or one that reflects the influence of extreme values. When you're looking at income data, salary surveys, or housing costs, the median will almost always give you a more useful number for understanding what a typical case looks like. The mean tells you where the center of gravity sits when every data point gets equal mathematical weight. Those are two different questions, and they often require two different answers. There are edge cases where the median misleads too. I ran into this with a dataset of customer lifetime values for a subscription product where roughly 60 percent of users churned within the first month. The median LTV was nearly zero because the majority of the population contributed almost nothing. The mean was significantly higher and reflected the revenue from the small segment of long-term customers. If I had only reported the median, the business would have underestimated its actual monetization potential. In that scenario, the mean paired with a full distribution breakdown was the correct approach. The takeaway is that neither metric is universally superior. You need to understand the shape of your data before picking one. A common pitfall is applying the mean to heavily right-skewed distributions and calling the result representative. Skewed data is everywhere in real-world analytics. Revenue, website traffic, response times, and medical costs all tend to have long right tails. When a distribution is skewed, the mean sits further out in the tail than the median does. The distance between them is a direct visual cue that your data is not symmetric. I always check that gap first before deciding which measure to emphasize in a report. A rule of thumb that works about 70 percent of the time is using the median for skewed data and the mean for roughly symmetric data, but rules of thumb are not substitutes for looking at the actual distribution.
Another thing people overlook is how the mean behaves with missing data. If your dataset has gaps and you calculate the mean using only the non-missing values, you are implicitly assuming the missing values are random. That assumption is wrong more often than not. In one project involving employee satisfaction scores, about 15 percent of respondents skipped a question. The mean calculated on complete cases was higher than the mean calculated when I imputed the missing values with the group median. The difference was small but consistent, and it pointed to a systematic pattern where dissatisfied employees were more likely to skip the question. Ignoring that pattern meant the headline number was quietly biased. When your data is categorical or ordinal, neither the mean nor the median may be appropriate. The mode becomes the most useful measure in those cases. If you're analyzing the most common browser type among your users or the most frequently selected feature request, the mode gives you the answer directly. The mean of categorical codes is meaningless unless you have a genuine numerical scale behind those categories. For reporting purposes, the cleanest approach is to present the mean and median side by side whenever your data could be skewed or contain outliers. This takes two seconds to compute and eliminates most downstream arguments about what the number actually represents. If you include a quick note about the standard deviation or interquartile range, you give your audience enough information to judge the spread without needing to ask follow-up questions. That reduces the number of clarification emails by a noticeable margin.
Get the Full Details
Which Measure Should You Trust and When
The mean is your default when the data is approximately normal and there are no extreme values distorting the picture. That covers a surprising amount of everyday data like test scores in a controlled environment, measurement errors around a stable mean, or aggregate metrics over large sample sizes where individual outliers cancel out. The central limit theorem does its work here, which is why the mean remains the standard for many statistical tests. The median is your default when the data is skewed, contains outliers, or represents something like income, pricing, or duration where a few extreme cases can dominate the mean. It is also the better choice when you need a single number that describes a typical individual in the population rather than the center of gravity of the entire distribution. If you're communicating with non-technical stakeholders, the median is often easier to explain because it maps directly to the idea of a middle case. Neither the mean nor the median handles bimodal distributions well. A bimodal distribution has two distinct peaks, which usually means you're looking at two different populations mixed together. In that situation, splitting the data by the underlying factor and reporting separate statistics for each group is the only honest approach. I've seen analysts report a single mean for a bimodal dataset and then act surprised when half the audience felt the number didn't represent their experience. That's not a statistics problem. It's a segmentation problem.
If you want to dig deeper into any of these concepts with worked examples and practice datasets, the Khan Academy statistics section has solid tutorials, and the scipy documentation covers robust estimation methods that go beyond basic mean and median calculations. For Excel users, the functions AVERAGE, MEDIAN, and MODE.SNGL do exactly what you need for most routine work. The real skill isn't picking the right measure. It's recognizing when your data structure makes any single summary statistic misleading. I still occasionally catch myself reaching for the mean out of habit on skewed data, and I have to pause and rerun the calculation with the median. That habit formed from years of doing exploratory analysis quickly, and breaking it took deliberate practice. Your first step should always be a histogram or a simple sorted list, not a formula. Mean Vs Median Vs Average isn't a debate about which one is better. It's a question of which one answers the question you actually have. Get the question right, look at the distribution, and let the data tell you which measure fits.