What Means End Analysis Actually Is
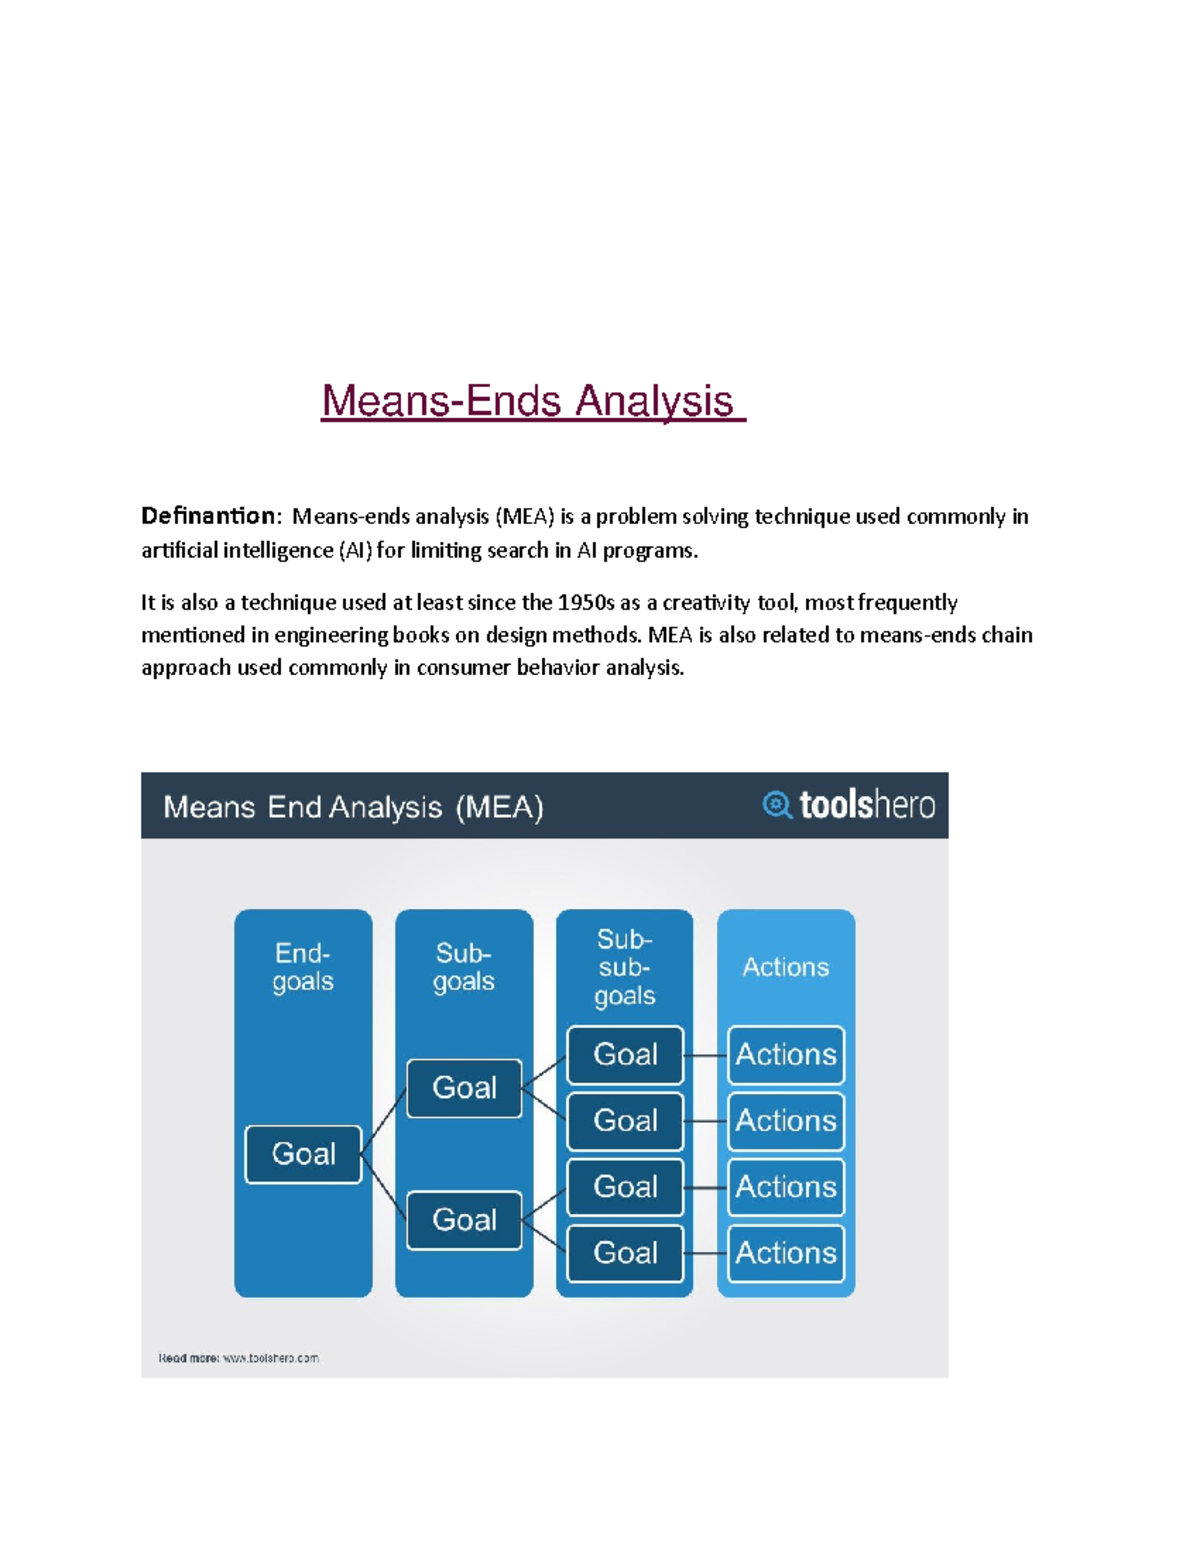
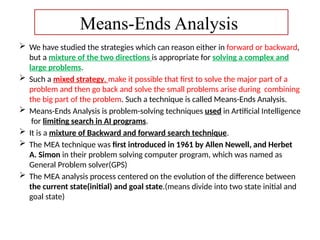
Most people think of means end analysis as this clever problem-solving strategy from early AI research, but in practice it is just a way of breaking a gap between where you are and where you want to be into smaller, solvable pieces. The core idea is simple. You identify your current state, identify your goal state, look at what differs between them, and then pick an operator that can reduce that difference. You repeat until the gap closes. That is it. The trick is not in the theory, the trick is in knowing which operators to try and when to stop. I worked on a routing optimization project years ago where we applied this exact method to scheduling delivery trucks. The means end analysis approach was supposed to shrink the search space dramatically, but the first version of our implementation just spiraled into useless branches because we kept applying the same operator over and over without checking whether it was actually reducing the distance metric we cared about. The fix was brutal but obvious. We added a hard cap on operator applications per subgoal and we switched to a priority queue that ranked which gap to close next based on actual impact rather than discovery order. That single change cut runtime from about forty minutes down to roughly three for the datasets we were running.A Concrete Means End Analysis Example
Here is a straightforward Means End Analysis Example that you can walk through in under a minute. Say your current state is "truck at warehouse A, 5 deliveries to make, 2 hours remaining" and your goal state is "all 5 deliveries completed by end of shift." The difference is five unfulfilled delivery points. Now you look at your available operators. There is load_truck, which gets packages on board. There is drive_to_location, which moves the vehicle. There is deliver_package, which marks a destination as complete. You start by applying load_truck because you cannot deliver anything without the packages in the vehicle. That reduces one difference. Then you apply drive_to_location for the nearest delivery point. That reduces another. Then deliver_package. Each operator application moves you one step closer to the goal state, and you keep cycling through them until there are no unfulfilled deliveries left. The whole thing takes maybe ten lines of pseudocode and five minutes to run through by hand. What most beginners miss is that means end analysis does not guarantee you will find the optimal path. It guarantees you will find a path, and usually a reasonable one if your operator set is well designed. But "reasonable" is doing a lot of work there. The quality of your result depends entirely on how you define your operators and how you measure the difference between states. If your operator for "drive to location" ignores traffic patterns, your analysis will still technically work, it just will not produce a useful schedule during rush hour. I learned that the hard way on a logistics model where we assumed static travel times. The analysis completed in seconds. The actual deliveries took 40% longer than predicted because the model had no operator for rerouting around congestion. We added a reroute_avoid_traffic operator and a dynamic time estimator and suddenly the whole thing became usable.
How to Build Your Own Means End Analysis
Start by writing down your initial state and your goal state as clearly as you can. Vague states lead to vague operator choices. "Fix the server" is not a state. "Server is returning 503 errors, database connection pool is exhausted" is a state. Pick the latter. Then list every operator you have available to you. These should be concrete actions, not aspirations. "Optimize query performance" is not an operator. "Increase connection pool size to 200" is an operator. Next, map each operator to what difference it reduces. This is the part people skip and then spend hours debugging. You need to know, before you start applying anything, exactly which gaps each operator closes. Create a simple table. Operator in the left column. Differences reduced in the right. It takes maybe five minutes and it prevents you from wasting cycles on operators that look relevant but actually do not touch the gap you are trying to shrink. Then you apply the analysis. Pick the largest difference between your current and goal state. Find the operator that reduces it. Apply it. Update your current state. Repeat. There is a subtle variation worth mentioning here. Some implementations use a means-ends table, which is essentially a matrix that cross-references every operator against every possible difference. For small problems this is elegant. For anything beyond roughly ten difference types, the table becomes unwieldy and you are better off just maintaining a lookup function that tells you, given a current difference, which operators are applicable. The lookup function approach scales much better and is easier to update when your operator set changes.
One thing that will trip you up: operators can introduce new differences. Delivering package A might mean you now have an empty slot in the truck that makes it impossible to pick up package B from a different route without backtracking. Means end analysis does not inherently account for this unless your state representation is detailed enough to capture it. In my experience, under-specifying the state representation is the number one reason a means end analysis produces a plan that looks correct on paper but falls apart in execution. Always make your state representation slightly richer than you think you need it to be.
Get the Full Details
Where This Approach Breaks Down
Means end analysis is not a silver bullet. It struggles in environments where operators have non-local effects, meaning applying one operator changes the applicability of other operators in unpredictable ways. It also gets expensive quickly in terms of computation when your state space is large. If you have fifty possible differences and twenty operators, you are looking at potentially thousands of operator-application combinations before you narrow down to a viable path. Without good heuristics guiding your choice of which difference to close first, the search can balloon into something that takes hours instead of minutes. I would recommend combining means end analysis with a heuristic search strategy like best-first search or A* if your problem space is more than trivially small. The means end framework gives you the structure for thinking about the problem, but the heuristic tells you which branches to explore and which to prune. Without that pruning step, you are essentially doing breadth-first search with extra steps. There is also the issue of operator completeness. If your operator set does not include everything you need to reach the goal, the analysis will terminate with an unresolved difference and you will not know whether the gap is unsolvable or whether you simply forgot to include a relevant operator. This happened to me on a deployment automation project where the analysis kept failing on a particular configuration step. We thought the pipeline was broken. Turns out someone had defined the operator as "restart_service" when the actual action required was "restart_service_and_clear_cache." Two different operators that looked the same from the outside but had very different state effects. Adding the missing operator resolved the issue immediately, but it took three days of tracing through the analysis output to find it because the state representation did not distinguish between cached and uncached service states.
If your problem involves significant uncertainty or probabilistic outcomes, means end analysis in its pure form is not the right tool. You are better off with something like Markov decision processes or Monte Carlo tree search, depending on the scale and structure of your problem. Means end analysis assumes you know what each operator does. When that assumption breaks, the whole framework gets shaky fast.
Quick Reference
Here is a stripped-down version of what a means end analysis implementation looks like in practice. This is not production code, it is the conceptual skeleton that most working implementations are built on. Define your state as a set of properties. Define your goal as a target set of property values. Define your operators as functions that take a current state and return a new state, along with a list of differences they resolve. Run a loop: find the first unresolved difference, find the first operator that resolves it, apply the operator, update the state, check if the goal is reached. If not, repeat. If no operator resolves the current difference, backtrack or report failure. The loop itself is maybe twelve lines. The complexity lives entirely in how you define your states and operators. Get those right and the analysis runs clean. Get them wrong and you spend your time chasing ghost differences that your poorly written state representation created in the first place.

I still use this approach when I need to decompose a complex technical problem into a sequence of actionable steps. It is not the most sophisticated method available, but it is transparent, it is debuggable, and it forces you to be explicit about what you are trying to change and how you plan to change it. Those are valuable constraints even if the output is not always optimal.