How to Actually Use Measures of Central Tendency Without Misleading Yourself
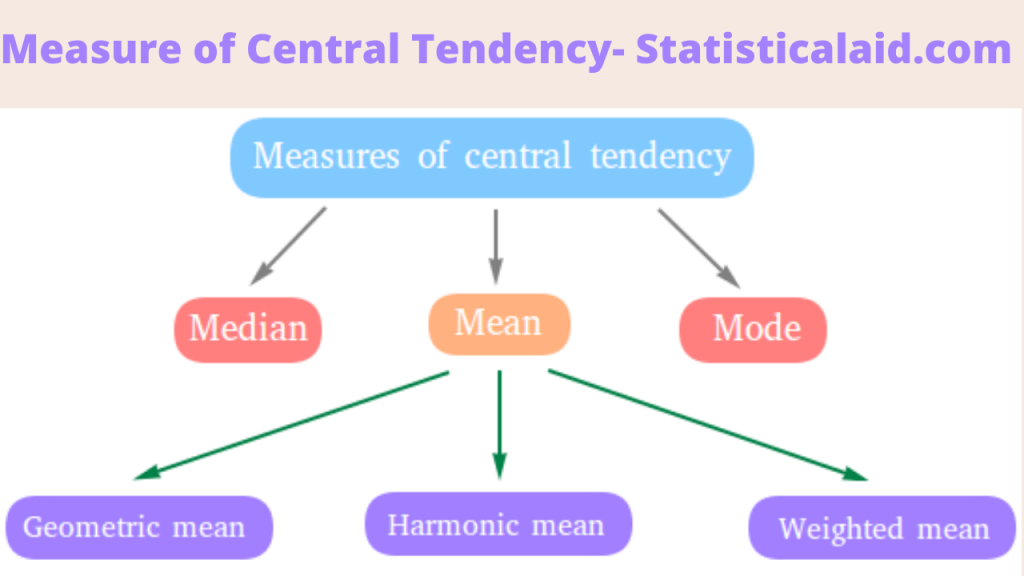
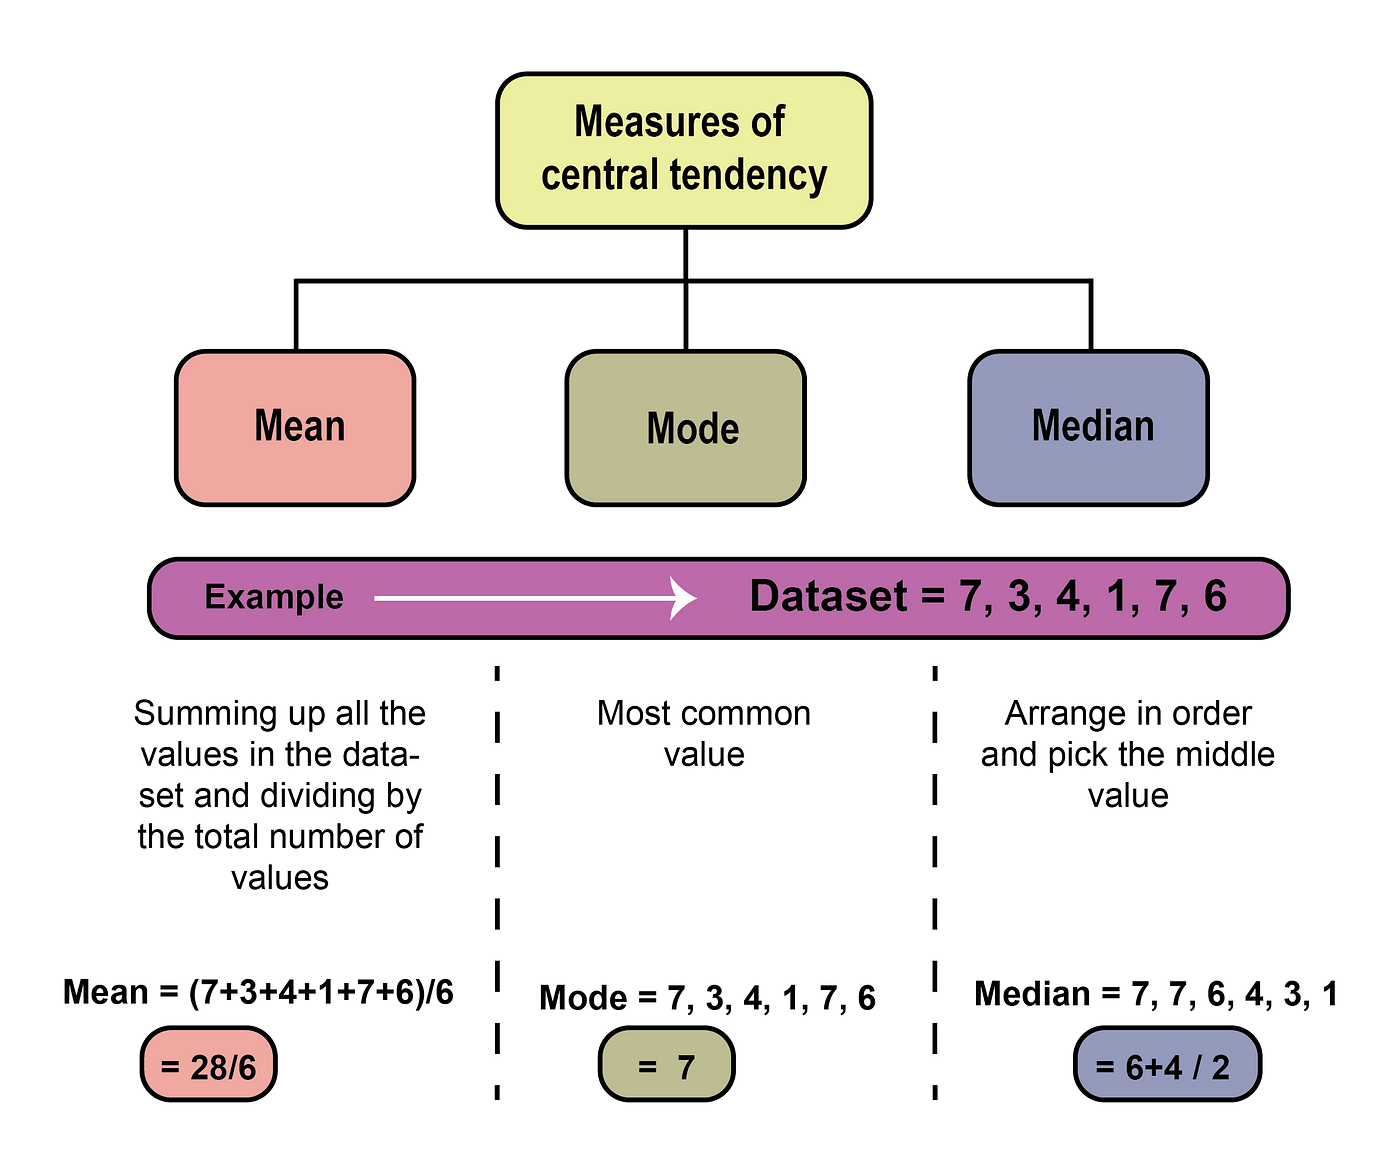
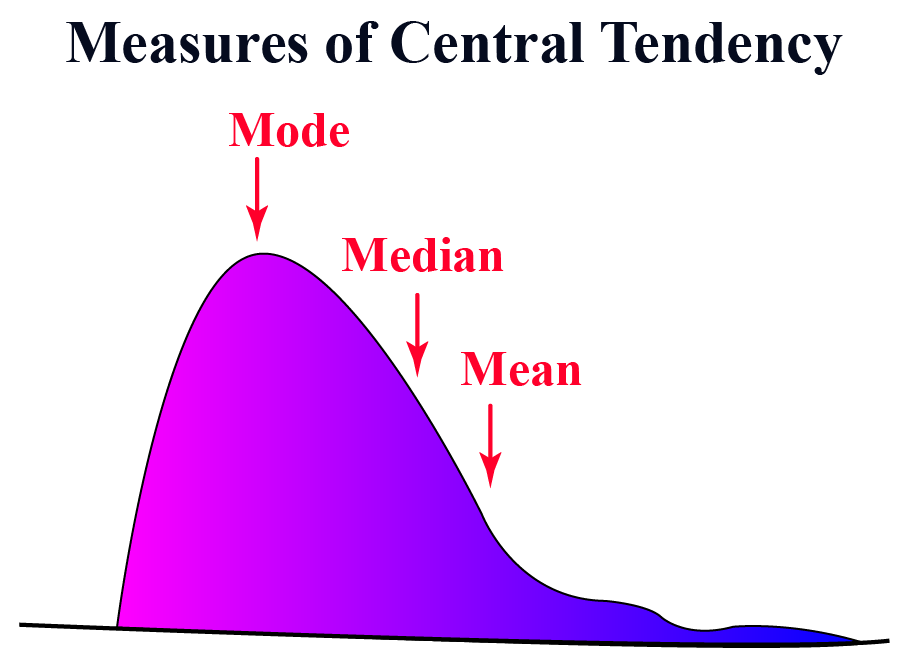
You have a dataset and you want to know what a "typical" value looks like. That's where central tendency comes in. It's just a way of finding the middle or center of your data. There are three main ways to do it: mean, median, and mode. Most people learn the definitions and stop there. The problem is that picking the wrong one quietly ruins your analysis, and you won't even notice until someone points out that your results don't match reality. The mean is what most people default to. You add everything up and divide by the count. It's straightforward. The median is the middle value when your data is sorted. Half the numbers fall above it, half below. The mode is simply the most frequently occurring value. That's the whole list. The hard part is knowing which one to use when, and more importantly, when none of them actually tell you the truth. I ran into this about two years ago working on a compensation dataset for a mid-size tech company. We were looking at salary distributions across departments. The mean salaries looked reasonable at first glance, but they were sitting $40,000 to $60,000 above what most employees actually made. The distribution was heavily right-skewed because a small number of senior roles pulled the averages up. Using the mean as the central measure gave leadership the impression that typical compensation was far higher than it actually was. I switched to the median, which reflected what a typical employee in each department actually earned, and then supplemented it with the interquartile range so nobody could pretend the spread didn't exist. It changed the entire conversation in the room.
Here's the thing beginners miss: central tendency without measures of spread is basically a guess with extra steps. A mean of 50 could come from data points tightly clustered around 50, or it could come from values ranging from 0 to 100. The number alone doesn't tell you which. Always pair your central tendency measure with standard deviation, variance, or at minimum a range. Otherwise you're presenting a single number and asking people to trust it implicitly. Another counter-intuitive point that doesn't get enough attention. The mean is not always the most representative value. In skewed distributions, the median can be dramatically more useful, and in some cases the mode is the only measure that makes practical sense. Think about customer support ticket resolution times. If your mode is 2 hours, your median is 4 hours, and your mean is 8 hours, the mode is probably what most people experience. The mean is being dragged up by a handful of tickets that took days because they got misrouted or escalated. Reporting the mean as the "average" resolution time would be honest mathematically but misleading operationally. There are also edge cases where central tendency breaks down entirely. Bimodal distributions are the classic problem. If your data has two distinct peaks, any single measure of central tendency will land in the valley between them and describe nothing that actually exists in your dataset. I've seen this happen with exam scores where half the class aced the test and the other half failed it badly. The mean would be around 50 percent, which sounds like a mediocre performance, but nobody actually scored near the middle. In those situations, reporting a single central tendency number is actively deceptive. You need to acknowledge the two groups and analyze them separately.
Missing data compounds these problems. If you're calculating a mean and you have 15 percent missing values, you're either imputing (which introduces its own biases) or you're working with a smaller sample that might not be representative. The median handles missing data slightly better because it only cares about rank order, not magnitude, but it still reduces your effective sample size. I usually flag missingness upfront and report it alongside the central tendency measure rather than silently dropping rows and pretending the analysis is cleaner than it is. For most routine work, here's the decision framework I actually use instead of the textbook definitions. If your data is roughly symmetric with no extreme outliers, use the mean with standard deviation. If it's skewed or has outliers, switch to the median with interquartile range. If you're dealing with categorical data, use the mode. If your distribution is multimodal, don't use any single measure and explain why instead. That last one matters more than people think. Saying "the distribution is bimodal so a single central tendency measure is not meaningful here" is more honest and more useful than forcing a number that obscures the structure of your data.
Get the Full Details
Common Pitfalls That Waste Time
One mistake I see constantly is using the mean for ordinal data. Likert scales, rankings, satisfaction scores rated 1 through 5. The mean of a Likert scale is technically defensible if you treat it as interval data, but it often produces results that don't map to anything respondents actually experienced. A mean score of 3.2 on a 1 to 5 scale doesn't mean anyone picked 3.2. The median or mode almost always communicates the finding more clearly to stakeholders who aren't familiar with statistical conventions. Another issue is rounding. Reporting a mean to two or three decimal places gives a false impression of precision. If your data was collected on a scale where individual responses are whole numbers, your mean shouldn't be presented with more precision than the underlying measurements justify. A mean of 4.73 on a 1 to 5 scale implies you know the true average to within hundredths, but your data never captured that level of detail in the first place. Round to one decimal place at most, and usually just one. There's also the problem of comparing central tendencies across groups with very different variances. Two departments might have the same median salary, but if one has a tight distribution and the other has a wide one, the experience of "typical" is very different even though the central tendency number is identical. I always present the measure alongside a spread metric in tables and charts. It takes five extra seconds and it prevents about half the follow-up questions I used to get after presenting findings.
When to Look Beyond Central Tendency
Central tendency is useful but it's a starting point, not an endpoint. If you need to make decisions based on your data, you'll almost always need more than a single number. Confidence intervals give you a range rather than a point estimate. Distribution shapes tell you whether your central tendency is actually representative. In regression or prediction contexts, central tendency measures become even less directly useful because the relationships between variables matter more than where the center sits. For a quick reference on the three measures and when each applies, the basics are covered in any introductory statistics textbook, but the practical judgment calls are what actually matter day to day. Pick the measure that matches your data structure, report the spread alongside it, acknowledge when your data doesn't have a meaningful center, and skip the dramatic conclusions. The numbers will be fine on their own.

.png/1767760850.png "Measures of Central Tendency, Mean, Median & Mode")