Why Your Standard Deviation Is Lying To You
I spent three weeks trying to figure out why our A/B test results looked so clean on paper but absolutely fell apart in production. The variance was tiny. The standard deviation was minimal. The confidence intervals were tight. And yet, every single user-facing metric was all over the place. It wasn't until I actually plotted the individual data points on a log scale that I realized the distribution was heavily right-skewed with a long tail of extreme values. The standard deviation was dominated by maybe 5% of our users who happened to be running extremely slow connections, and it made the other 95% look artificially consistent. This is the thing nobody tells you upfront about Measures Of Statistical Dispersion. Most of the standard textbook formulas assume you're working with symmetric data or at least acknowledge that your data isn't perfectly normal. In real engineering work, that assumption fails more often than not. Understanding which dispersion measure actually applies to your situation matters more than memorizing five formulas and plugging numbers into them.
Understanding Measures Of Statistical Dispersion
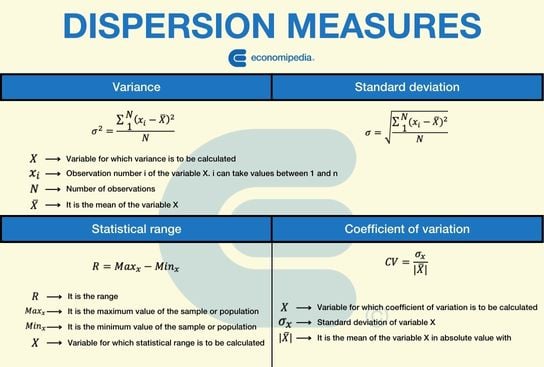
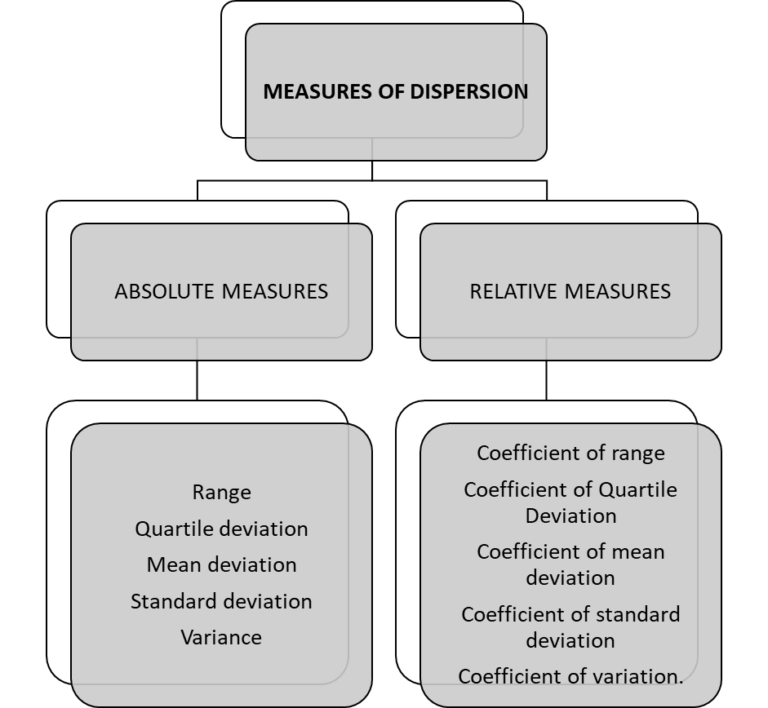
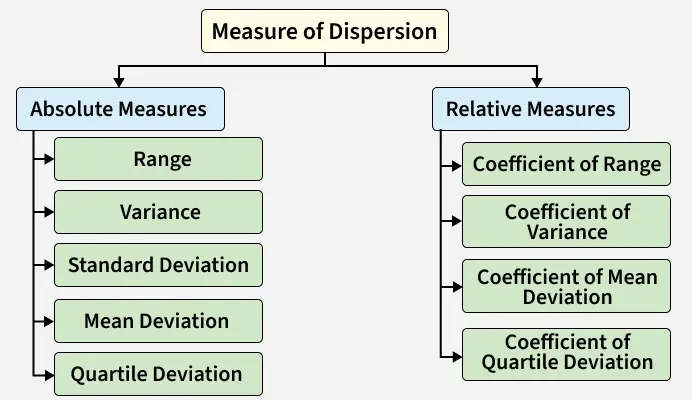
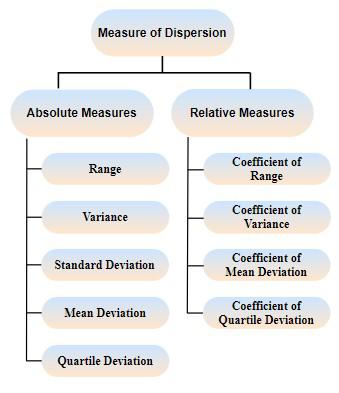
Dispersion measures tell you how spread out your data is. That's it. Everything else is just implementation detail. The most common ones are variance, standard deviation, interquartile range, mean absolute deviation, and range. Each one does a slightly different job, and each one breaks under different conditions. Knowing which condition is what matters to you. Variance is just the average of squared deviations from the mean. Standard deviation is the square root of variance, which brings the units back to something interpretable. If your data is in milliseconds, standard deviation is in milliseconds too. Variance is in milliseconds squared, which is meaningless in any practical context. That's why people use standard deviation instead. But here's the catch: squaring those deviations gives enormous weight to outliers. A single data point that's four standard deviations away from the mean contributes sixteen times as much to the variance as a data point that's one standard deviation away. In a dataset of a thousand observations, that one outlier can inflate your standard deviation enough to make the whole distribution look much more variable than it actually is for the bulk of your data. I learned this the hard way when I was analyzing error rates across a fleet of servers. One server had a power supply issue that caused occasional massive latency spikes. The standard deviation across all servers looked terrible because of that one machine. I ended up using the median absolute deviation instead, which is the median of the absolute deviations from the median. It ignored the outlier almost entirely and gave me a much more honest picture of what was actually happening across the fleet. MAD is less commonly discussed in introductory statistics courses but it's the right tool for that kind of situation.
The Practical Breakdown
Range is the simplest measure and also the least useful one in practice. It's just the difference between the maximum and minimum values. A single corrupted data point can swing your range by orders of magnitude. I've seen datasets where the range was useful as a rough sanity check but completely unusable for anything requiring statistical rigor. It's still worth computing because it tells you the bounds of your data quickly, but don't treat it as a serious measure of spread. Interquartile range, or IQR, is the difference between the 75th percentile and the 25th percentile. This captures the middle 50% of your data and ignores everything outside that window. It's extremely robust to outliers. If you have a dataset with extreme values and you want to know how much your typical observations vary, IQR is your answer. It doesn't use every data point the way variance does, which some people see as a weakness. It's actually a strength in those cases. The tradeoff is that IQR gives you less information about the tails of the distribution, and if your analysis depends on understanding those tails, IQR won't help you. Mean absolute deviation is another robust option that you should keep in your toolkit. It's the average of the absolute deviations from the mean. Unlike variance, it doesn't square the deviations, so outliers don't get that amplified treatment. MAD is about 80% as efficient as standard deviation for normally distributed data, meaning it loses very little precision while being noticeably more robust. In my experience with performance testing and user behavior data, which is rarely normal, MAD tends to give more stable results than standard deviation across different samples.
Get the Full Details
Here's a scenario where the choice of dispersion measure changed my entire conclusion. I was comparing two routing algorithms for a load balancer. Algorithm A had a mean response time of 45ms with a standard deviation of 12ms. Algorithm B had a mean of 48ms with a standard deviation of 31ms. On standard deviation alone, Algorithm A looked significantly better. But when I calculated the IQR for both, Algorithm A had an IQR of 8ms while Algorithm B had an IQR of 6ms. The middle 50% of Algorithm B's responses were actually more consistent. The high standard deviation for B was driven by a small number of pathological requests that went through a particularly slow path. For most traffic, B was better. The standard deviation misled me into recommending A outright. I would have made a worse engineering decision if I hadn't looked at multiple dispersion measures.
How To Actually Use These In Practice
Start by plotting your data. A histogram or a kernel density estimate will show you immediately whether your distribution is symmetric, skewed, or multimodal. This single step determines which dispersion measure is appropriate. If the distribution looks roughly normal and you have no extreme outliers, standard deviation is fine. If there's skew or outliers, switch to IQR or MAD. Don't skip the visualization step. I used to compute dispersion measures directly from spreadsheet output because it was faster. That approach cost me weeks of reanalysis when I discovered the metrics I was relying on were artifacts of skewed data. When you report dispersion, always report the measure you're using. Writing "the standard deviation was 12ms" is transparent. Writing "the standard deviation was 12ms and the IQR was 8ms" is more useful because it lets the reader assess robustness. If you're writing documentation or a report, including both standard deviation and IQR takes about thirty seconds and prevents a lot of follow-up questions. For grouped data or frequency distributions, the calculations shift slightly. You weight each deviation by its frequency rather than treating every observation equally. The formulas are straightforward but easy to get wrong if you're working from memory. I keep a reference sheet with the weighted variance formula and the weighted standard deviation formula pinned in my notes. It saves me from re-deriving them during tight deadlines.
When working with very large datasets, computational efficiency matters. The two-pass algorithm for variance is numerically stable but requires two passes over the data. The one-pass algorithm is faster but can suffer from catastrophic cancellation when the variance is small relative to the mean. For datasets over a million observations where numerical precision matters, I use the Welford online algorithm. It's a single pass, numerically stable, and implements the incremental variance calculation correctly. The Python implementation is about twenty lines of code. Once I started using it consistently, I stopped seeing the occasional strange variance results that I used to get from the naive two-pass approach on borderline cases.
When Dispersion Measures Fail You
The biggest limitation most people encounter is that all of these measures assume your data has a meaningful central tendency. If your distribution is bimodal, the mean and standard deviation become almost meaningless. Consider a dataset where half the observations cluster around 10 and the other half cluster around 100. The mean would be 55 with a standard deviation of about 45. Neither number describes any actual data point. In cases like this, you need to identify the subpopulations first and compute dispersion within each group. There's no single dispersion measure that will save you from a fundamentally multimodal dataset. Another failure mode is circular reasoning. If you select features based on their variance across training data and then report that variance as evidence of model quality, you're measuring the same thing twice. I've seen this happen in feature selection pipelines where high-variance features were automatically preferred without checking whether the variance was signal or noise. The dispersion measure itself isn't wrong. The application was. For time series data, standard dispersion measures are almost never appropriate on their own because they collapse the temporal structure. A dataset with values oscillating between 0 and 100 every second has the same standard deviation as a dataset that starts at 0 and drifts to 100 over the entire series. If you're working with temporal data, compute dispersion within rolling windows instead. This preserves the time dimension and usually reveals patterns that global dispersion measures completely miss.
What To Do When You're Not Sure
Compute multiple measures and compare them. If standard deviation and IQR tell similar stories, you're probably in a safe zone. If they diverge significantly, your data has structure that a single number can't capture, and you should investigate further before making decisions based on dispersion alone. This comparison usually takes less than five minutes and prevents a lot of downstream errors. It's the single most practical habit I've picked up from years of working with messy real-world data.