Why Most Variation Worksheets Miss the Point
The four standard measures of variation—range, interquartile range, variance, and standard deviation—are almost always presented in textbooks as if they operate in a vacuum. The datasets are tidy, integer-only, and entirely free of the edge cases that show up in actual work. Range equals the maximum minus the minimum. IQR is the third quartile minus the first quartile. Sample variance divides the sum of squared deviations from the mean by n minus one, while population variance divides by N. Standard deviation is just the square root of the variance you computed. The mechanics are straightforward. The application is where most students and practitioners trip. Range is fragile. One outlier can make it completely uninformative. I once worked with a logistics team that tracked delivery times across a regional hub. The distribution had a long right tail, and their range jumped from twelve minutes to nearly eight hours when a single truck broke down on a frozen highway. Standard deviation told a similar story but in squared units, which nobody wants to interpret directly. That's why we switched to IQR for their dashboards. It ignored the outlier and showed the actual spread of normal operations.
Measures Of Variation Worksheet With Answers
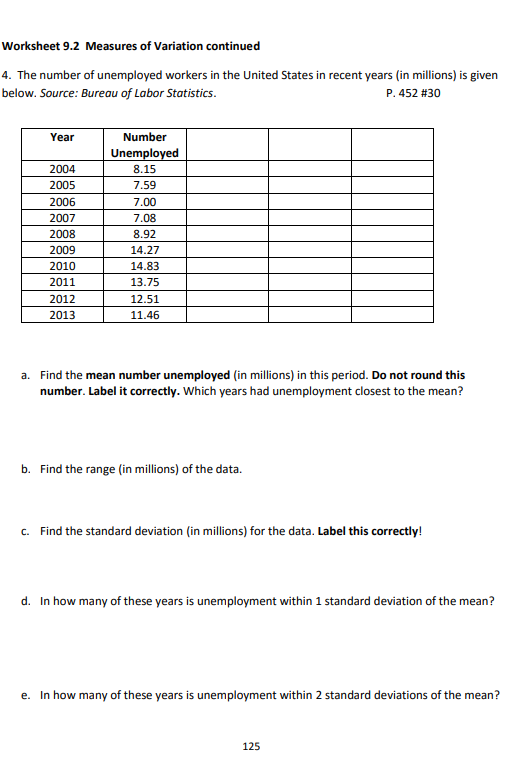
When you're working through a worksheet on this topic, the answers are rarely the hard part. The questions are designed so the math works out cleanly. The harder question is knowing which measure to report and when to ignore one entirely. If your data is skewed or contains outliers, standard deviation becomes misleading because every extreme value gets squared and amplified. In those cases, IQR gives you a more honest picture of central spread. If your distribution is approximately symmetric with no extreme outliers, standard deviation is the better choice because it incorporates every data point. There are a few traps that even experienced people fall into. The first is confusing sample and population formulas. Using the population variance formula on sample data systematically underestimates the true variability. The fix is trivial—use n minus one instead of N—but if you're writing code or building an automated pipeline, it's easy to hardcode the wrong divisor and carry the error through every downstream calculation. The second trap is quartile computation differences across tools. Excel's older QUARTILE function, Excel's newer QUARTILE.EXC, Google Sheets, and R all use slightly different interpolation methods. On small datasets the difference is negligible. On larger datasets it can shift your IQR enough to matter, especially if you're comparing results across platforms. Variance by itself is nearly useless for communication because it's expressed in squared units. A variance of 256 for a dataset measured in centimeters means the standard deviation is 16 centimeters. Reporting the squared number confuses almost everyone who reads it. Always convert to standard deviation before presenting results to anyone outside the statistical team.
One thing that rarely appears on worksheets but proves useful in practice is the coefficient of variation. It's the standard deviation divided by the mean, expressed as a percentage. When you need to compare variability across datasets measured in different units—say, comparing the relative spread of product weights in grams against packaging dimensions in millimeters—the coefficient of variation gives you a dimensionless number that makes the comparison possible. Standard deviation alone cannot do this. Here is a typical worksheet problem and how I would walk through it. Consider the dataset: 12, 15, 14, 10, 13, 16, 11, 14, 15, 13. The mean is 13.3. The deviations from the mean are approximately minus 1.3, plus 1.7, plus 0.7, minus 2.3, minus 0.3, plus 2.7, minus 2.3, plus 0.7, plus 1.7, minus 0.3. Squaring those deviations and summing them gives roughly 29.1. Dividing by nine for the sample variance yields about 3.23. The sample standard deviation is approximately 1.80. The range is six. The first quartile is 11.75 and the third quartile is 14.5, making the IQR approximately 2.75. The answer key will list these numbers. The practical takeaway is that the IQR and standard deviation tell slightly different stories here. The data is nearly symmetric, so both are reasonable, but the IQR is tighter because it ignores the lower tail. If you are building a worksheet for students or training materials, avoid datasets that are too clean. Include at least one outlier. Include a skewed distribution. Ask learners to justify their choice of measure rather than simply computing all four. The gap between computation and interpretation is where actual understanding lives, and most ready-made worksheets skip straight past it.
Get the Full Details
The common worksheet resources you find online tend to follow the same pattern. They list a dataset, ask for each measure in sequence, and provide answers at the end. This approach teaches mechanical fluency but not judgment. A better approach is to present two datasets with similar means but different spreads, ask which one is more variable, and require an explanation. The answer changes depending on whether the data is symmetric or skewed, and that tension is what the standard worksheets fail to create. When grading or self-checking worksheets, the most reliable method is to compute standard deviation twice—once by hand with the formula and once in a spreadsheet or calculator—and verify they match. If they do not, you have likely made a rounding error mid-calculation or used the wrong divisor. For variance calculations, keep extra decimal places through every intermediate step and round only at the final answer. Rounding early compounds errors quickly, especially with small datasets where each deviation carries more weight. There are scenarios where none of the standard measures work well. Heavy-tailed distributions, like those found in financial returns or certain biological measurements, produce variance estimates that are unstable and highly sensitive to sample size. In those cases, robust measures like the median absolute deviation provide more reliable information, though they are almost never covered in introductory worksheets. If your data comes from that kind of domain, the standard worksheet answers will mislead you.
Practical Checklist
Before finalizing any worksheet or assignment on this topic, verify the following. Check that the dataset includes at least one outlier. Confirm that the answer key uses n minus one for sample variance unless the problem explicitly states the data represents a full population. Verify quartile values against two different tools to catch interpolation discrepancies. Include a question that asks the learner to choose the most appropriate measure of variation and explain why. Skip the question that asks for all four measures on every problem in sequence—that practice reinforces calculation without building judgment.