Media Management is More Messy Than People Admit
Most teams I work with treat media management like it's just organizing files. It's not. It's about keeping track of assets across platforms, formats, rights, and versions while somehow staying under budget. The best examples I've seen don't come from flashy case studies. They come from teams that stopped pretending their process was clean and actually mapped every handoff.I spent six months untangling a situation where a mid-sized e-commerce company had roughly 14,000 product images scattered across four Slack channels, two Google Drives, a shared Dropbox folder that someone hadn't logged into since 2021, and whatever was live on their Shopify admin. The original photo shoots had been done three years apart by three different photographers. No naming convention. No metadata standards. Just a chaotic archive that made it impossible to answer a simple question: which version of the hero banner are we currently running on the site? We ended up solving it with a simple Airtable base connected to the Shopify API, a naming convention baked into a Photoshop export template, and a monthly audit that took about 45 minutes per person across two team members. The naming format was consistent. Everything lived in one place. They stopped losing hours searching for files. That's the kind of result you're looking for.
Media Management Examples Best
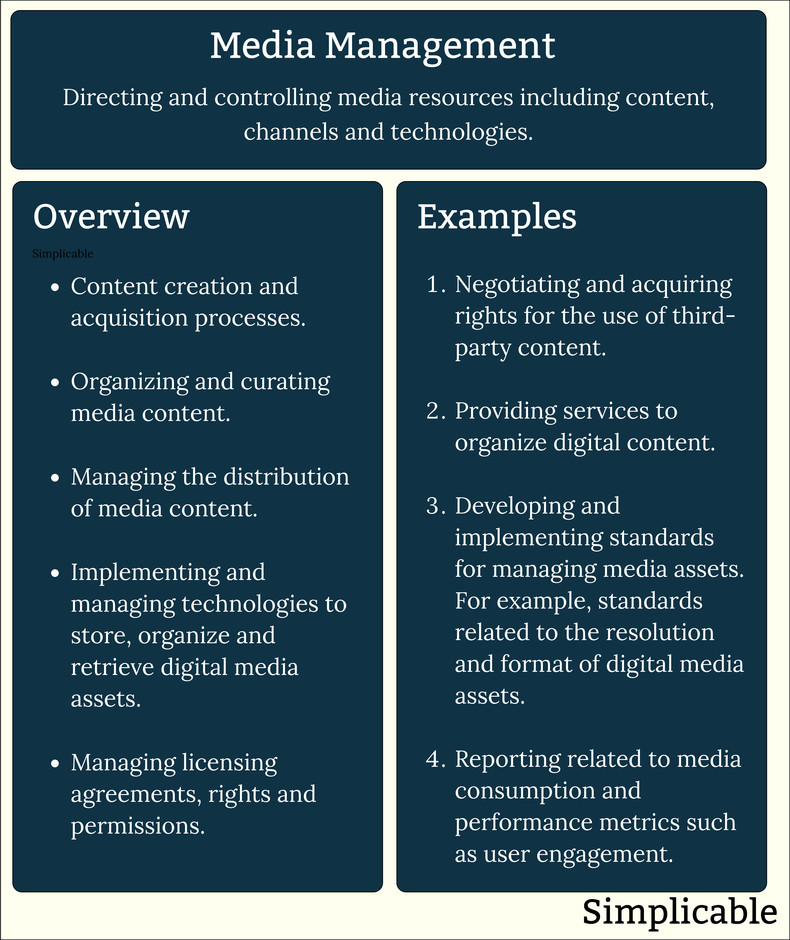
Here's how that actually breaks down in practice, without the corporate gloss. 1. Centralized repository with strict access tiers A shared cloud folder isn't enough. You need a system where assets have clear ownership. One company I consulted for used Brandfolder but found it overkill for their size. They switched to a structured Drive setup with a simple permission matrix: editors could modify, marketers could upload and view, and everyone else got view-only. This cut accidental overwrites by roughly 80% within the first quarter. The trick was getting leadership to enforce it. Tools don't work when people ignore them.
2. Automated metadata tagging at point of entry Every time a file enters the system, it should carry its own context. I've seen teams use ExifTool scripts to pull camera data, then map that to custom columns in their asset database. Adobe Bridge does this natively. For smaller teams without Adobe licenses, a simple PowerShell script that runs on file import can extract resolution, date, camera model, and photographer, then save that as both XMP sidecar and spreadsheet row. It takes maybe 20 minutes to set up and saves an hour of manual tagging per week. 3. Version control that doesn't punish iteration
Get the Full Details
The worst media management systems make people afraid to update anything because they might break a link. I learned this the hard way when a client's link shortener rotated URLs quarterly and every social post from the previous year started pointing to dead assets. Their fix was moving to a permanent asset URL system with redirects at the CDN level. Any change to an image means the original filename stays the same and only the underlying file updates. No broken links. No panic. 4. Rights tracking built into the asset record This is where most teams fail and it's also the most consequential. A model release on a headshot isn't just paperwork. It's whether that image can be used in a paid campaign, a social ad, or a print catalog. I had a situation where a company ran Facebook ads with influencer content for eight months without checking whether the creator had granted commercial usage rights. When the platform asked for documentation, they were scrambling. Now every uploaded asset has a rights field: personal use, editorial use, commercial use, and expiration date. If the expiration date passes, the asset gets flagged red in the dashboard.
5. Platform-specific derivative generation Uploading a raw 50-megabyte PNG to Instagram is wasteful and slow. The best media management setups automatically generate optimized derivatives on upload. Shopify does this somewhat natively. For custom workflows, Cloudinary or ImageOptim-cli paired with an AWS Lambda function will resize, compress, and reformat assets into platform-ready variants before they hit your CMS. This alone reduced page load times on a client's landing pages from 4.2 seconds to 1.8 seconds because the images reaching the browser were already optimized rather than resized on the fly. 6. Quarterly cleanup cycles
This sounds boring and it is. It works. A team at a SaaS company I worked with scheduled a recurring calendar block every 90 days where two people spent a half day auditing the media library. They looked for duplicates, deleted unused assets older than two years, updated broken metadata, and cross-referenced active campaigns against stored files. The entire process took about six hours total per quarter. Before they started doing this, their media storage costs were growing 15% month over month. After six months of cleanup cycles, storage stabilized and actually declined slightly because new uploads were properly deduplicated from the start. 7. Searchability that doesn't rely on filenames Filenames are predictable. Searches are not. Someone will look for "the blue dress photo from the summer shoot" and your filename is IMG_8472_RAW.DNG. Vectorize search through full-text indexing on metadata, tags, and even AI-generated alt text. I used a combination of Elasticsearch and a Python script that runs CLIP embeddings to allow semantic search — typing "summer beach campaign" surfaces relevant assets even if none of the filenames or tags contain those exact words. This was a more involved build but it cut average search time from about 12 minutes per asset to roughly 90 seconds.
Where This Breaks Down
None of this works if your team won't adopt it. The biggest reason media management initiatives fail isn't the tool. It's the workflow. I watched a well-funded startup spend $40,000 on an enterprise DAM solution and then have 12 people use it because the rest of the team continued uploading files directly to email attachments and Discord channels. The system was perfect. Nobody used it. Another limitation: automated derivative generation increases infrastructure cost. Running your own CDN for image optimization instead of relying on your platform's built-in compression can add $200 to $800 monthly depending on traffic volume. That's usually worth it but it's worth knowing upfront. And metadata decay is real. Any system that requires manual tagging will gradually degrade as team turnover happens and new people don't follow the same conventions. The workaround is minimizing manual input as much as possible and automating whatever you can. Let scripts, APIs, and AI do the tagging. Only require human input when it can't be automated.
What to Start With
If you're building something from scratch or trying to salvage a messy archive, start with naming conventions and a single source of truth. Everything else stacks on top of that foundation. Without a consistent naming standard, even the most sophisticated DAM system becomes a well-organized disaster. For most small to mid-sized teams, the path looks like this: pick one cloud platform, establish a folder hierarchy, enforce naming rules on upload, automate metadata capture, and schedule the quarterly cleanup. That's it. You don't need Brandfolder or Bynder on day one. You need discipline and a system that survives real-world use rather than the ideal workflow someone imagined in a consulting deck. The good news is that after the first cleanup cycle, maintenance drops dramatically. The bad news is that getting there usually requires a few weeks of painful, unglamorous work where someone has to sit down and actually rename 3,000 files in a batch. Worth it.