Setting Up a Media Management Tutorial Yearly Workflow
My approach to a Media Management Tutorial Yearly setup
I don't plan these yearlies the way most people do. Most folks start by creating folders and hoping a naming convention will sort itself out. That usually falls apart within six months when someone moves a file and everything breaks. I start with the export side first — where the files need to go at the end of the year — and work backward from there. It takes longer to set up initially, but it saves you from having to reorganize everything in February. The core structure I use has four top-level directories: Raw, Processed, Archive, and Distribution. Raw holds everything that comes off the camera or out of a tool. Processed is where edits live. Archive is the read-only backup. Distribution is what actually gets shipped out to wherever it needs to go. Everything else branches from those four. I know that sounds simple, but most systems I've seen have twelve or fifteen top-level folders and nobody remembers which one is which. File naming is where people waste the most time. I use YYYYMMDD_ProjectName_AssetType_Version.ext. Something like 20240315_SiteSurvey_OralHistory_v03.mov. The date at the front means files sort chronologically by default, which matters when you're doing annual reviews. The version number at the end prevents that nightmare where someone overwrites the only good take because they forgot to rename it.
Metadata and tag strategy
Embedding metadata into files from day one is non-negotiable. I use XMP sidecar files for video and IPTC fields for photos. XMP is portable and survives migration between systems. IPTC gets read by every CMS and asset management platform without requiring a separate database. The fields I care about are Title, Description, Creator, Copyright, Keywords, and a custom field I call ProjectCode. Everything else is noise at this scale. I run a Python script during import that reads the filename and auto-fills those metadata fields. It took me two days to write the first version and probably six hours total across all revisions since. The script checks whether the file already has metadata before overwriting anything. That last part is important because some cameras and editing tools already populate fields with garbage data that your script would blindly replace if you're not careful.
Storage and backup strategy
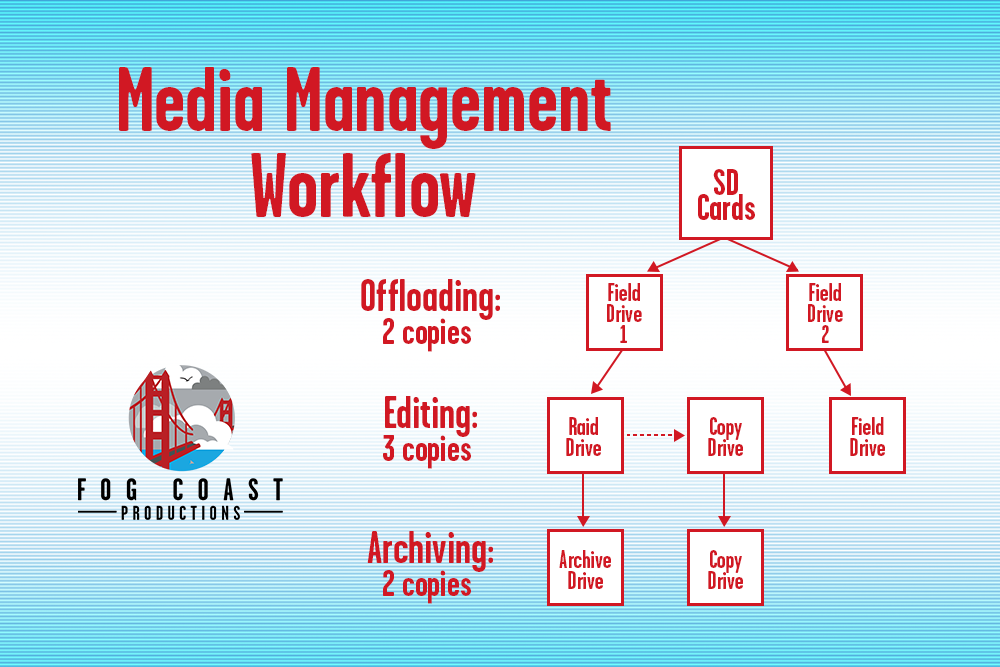
Three copies on three different media. That's the rule. I don't subscribe to the "just put it in the cloud" approach because cloud storage for media files gets expensive fast and retrieval times are unpredictable when you're working under deadline. My typical setup is the active project on SSD, a secondary copy on NAS, and an offsite cold storage backup that's either LTO tape or an encrypted S3 Glacier vault. The annual review process includes verifying checksums on the cold storage copy to make sure nothing degraded. One thing I learned the hard way: don't store your archive and your active project on the same RAID array. A single hardware failure takes out both. I had a controller card fail on a Synology unit and lost three years of organized footage because I didn't separate active from archived. After that, I started keeping the archive on entirely separate hardware with its own power supply and network path.
Get the Full Details

Review and cleanup cadence
The yearly part of this comes down to a structured review process. I go through the Raw directory and demote anything that hasn't been touched in twelve months to Archive. Processed files get checked for version overlap — you'd be surprised how many projects end up with five files named similarly that are actually the same content. Distribution files are audited against the delivery specs from the original project brief to catch anything that doesn't meet current standards. Last year I was working with a client who had roughly 40 terabytes of media scattered across five different systems — two local servers, two cloud services, and an external drive that someone kept at home. The metadata was inconsistent because each system used a different schema. There was no central index. Finding anything took twenty minutes minimum, and often much longer. What I ended up doing was building a simple SQLite database that pulled metadata from XMP and IPTC sources across all five locations without moving any actual files. The database became the single point of search. I wrote a small Flask app on top of it so the client could query by date range, project code, keyword, or asset type. File locations stayed where they were. The database just mapped where everything lived. It took about a week to get right, and the client went from twenty-minute searches to under ten seconds for most queries.
The workaround I settled on was running the metadata extraction in read-only mode on each source. That prevented any accidental modification of the original files during the indexing process. I also added a conflict resolution step that flagged entries where the same file appeared in multiple locations with different metadata values. Those needed manual review before being committed to the database.
Common pitfalls that slow everything down
People tend to over-index. Setting up automated metadata extraction sounds great until you realize it's scanning every file in your library every time something changes. With a large media library, that can take hours and tie up your storage controller. I run metadata updates incrementally — only scanning files that have been modified since the last run. That cuts the update time from something like two hours down to maybe fifteen minutes depending on how many files changed. Another issue is naming convention drift. Someone creates a folder called "2024_Summer_Project" while another person uses "Summer2024_Proj." These look different but point to the same phase of the same project. I solved this by maintaining a master naming convention document that every team member has to acknowledge before getting write access to the shared storage. It's a small administrative step that prevents a lot of confusion later.
Tools worth using
For bulk metadata operations, ExifTool is the standard and it does exactly what it says. For search and discovery across multiple locations, I've had good results with a custom SQLite backend combined with a simple web interface. For the actual yearly review workflow, a combination of bash scripts and manual checks works fine — there's no need to buy expensive software for something that basically amounts to looking at file lists and making decisions. Adobe Bridge is useful if you're already in the Adobe ecosystem because it reads XMP directly and lets you batch-edit metadata through a graphical interface. The downside is that it's not really designed for large-scale distributed media libraries and can be sluggish with tens of thousands of files.
When this approach falls apart
The system I've described works well for small to medium teams handling anywhere from a few hundred gigabytes up to maybe ten terabytes of active media. Beyond that, you start running into performance issues with any file-based metadata system. At that scale, you need a proper DAM (Digital Asset Management) platform with a real database backend, and the investment isn't trivial. If you're managing petabytes of media for a large production house, a Media Management Tutorial Yearly approach built around file structures and XMP files won't hold up. You'd be better off evaluating something like Canto, Bywast, or a custom solution built on top of a proper asset management database. Another scenario where this breaks down is when you're dealing with proprietary or encrypted media formats that don't support standard metadata embedding. Some broadcast-grade equipment writes files in formats where you can't modify IPTC or XMP without re-encoding. In those cases, you're stuck maintaining sidecar files exclusively, and your search and discovery tools need to be able to read those sidecars consistently across your entire workflow.
Getting started if you're not organized yet
If your current situation is messy, the fastest fix is to stop adding new files until you've set up the basic structure. I've seen people try to reorganize an existing library while continuing to work in it, and that always creates duplicates and confusion. Freeze your incoming media, set up the four top-level directories, write the naming convention document, run your metadata extraction script on the existing files, then resume work with the new structure in place. That's it for the yearly media management workflow. It's not fancy, and it won't solve every problem you have, but it keeps things findable and consistent without requiring a team of administrators or a six-figure software license.