Azure Cheat Sheets and Why I Still Use Mine
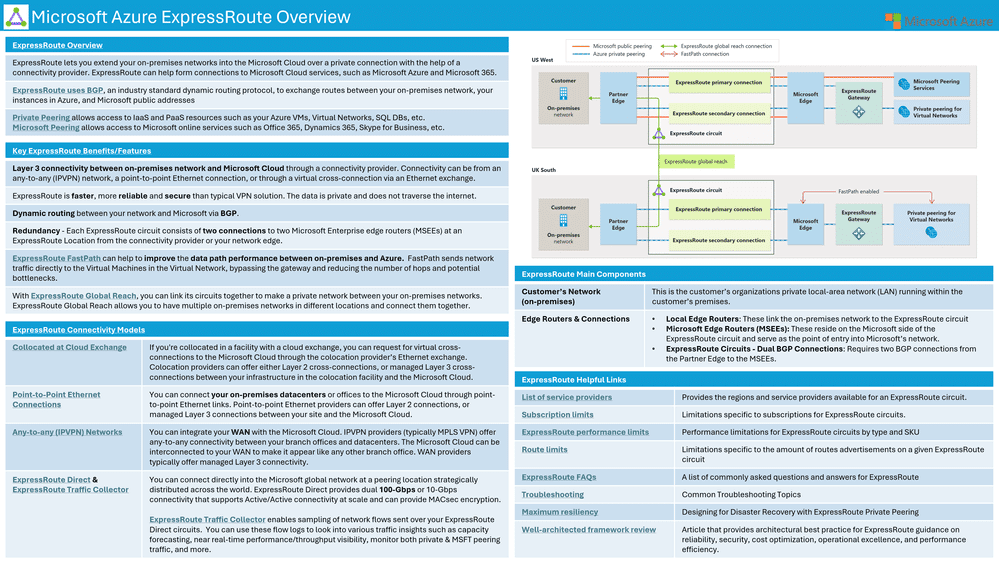
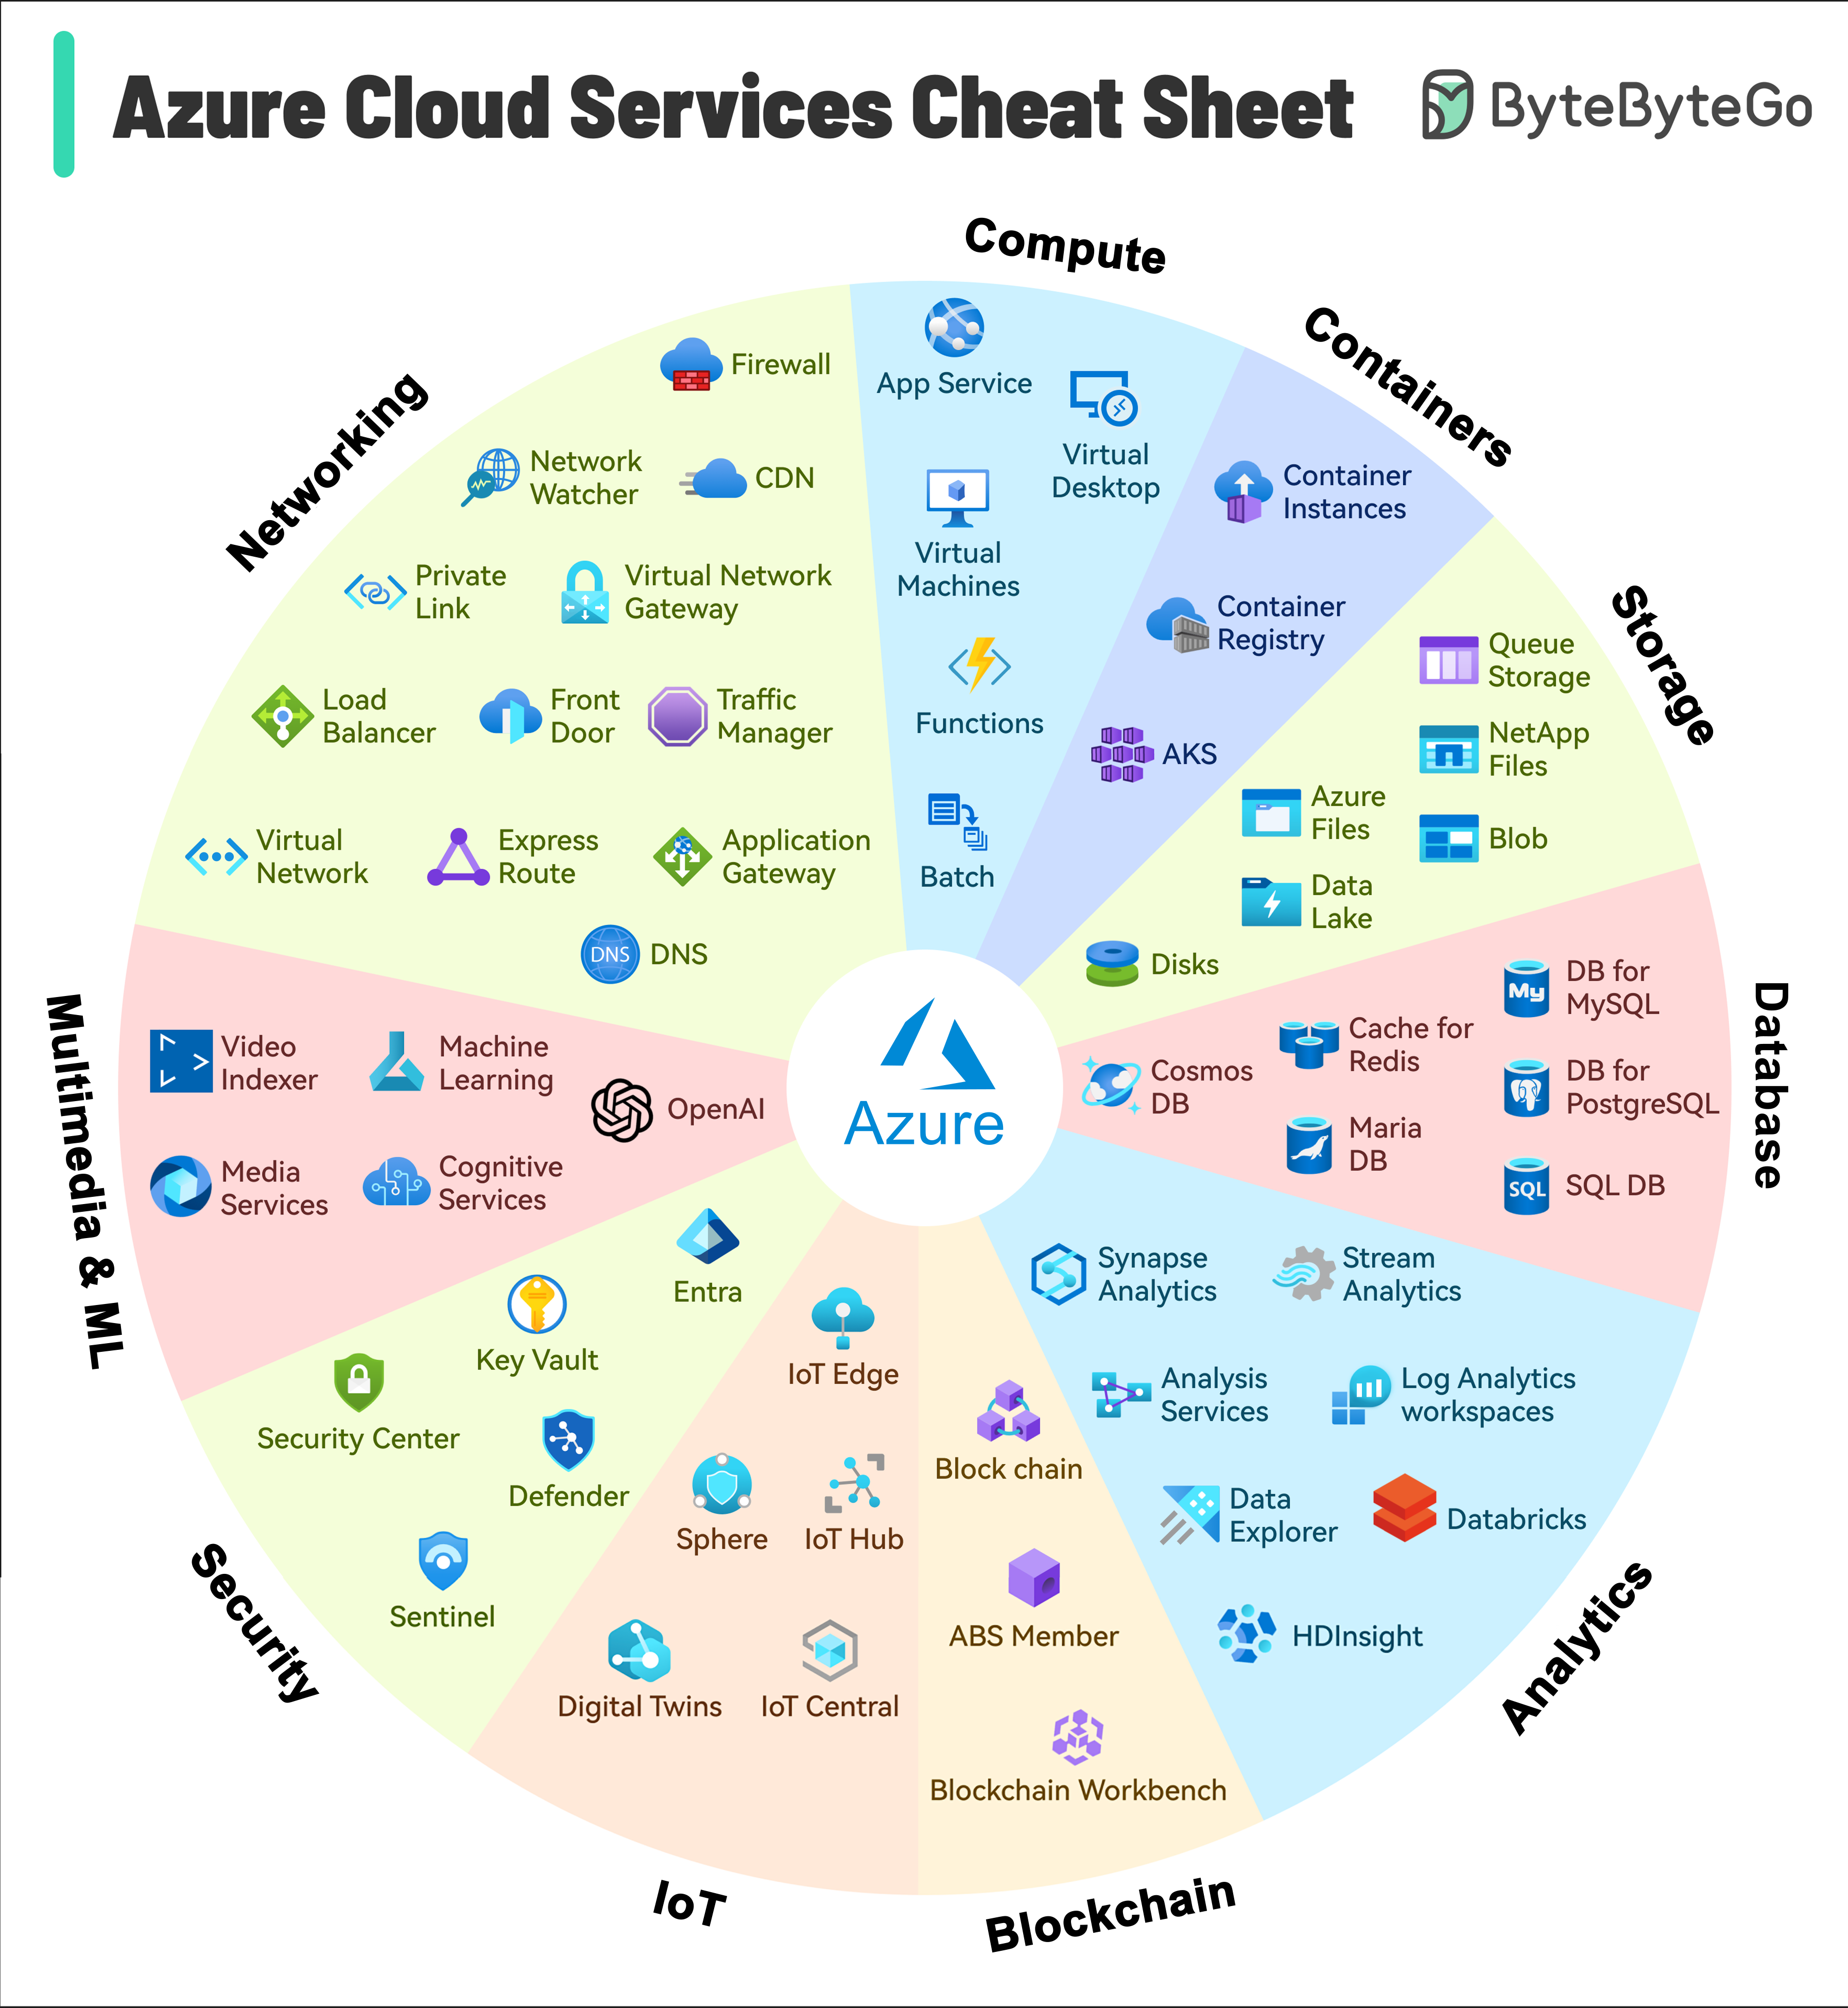
I keep a Microsoft Azure Cheat Sheet on my desk. Not because I forget commands, but because the portal UI changes every few months and I don't want to click through twenty menus to find something I used yesterday. It started as a single page of common CLI commands and grew into something more useful when I stopped trying to memorize everything and started documenting the patterns instead. Here is what my current version covers and how I actually use it in day-to-day work. The main sections are resource grouping, identity management, compute sizing, storage tiers, networking basics, and cost monitoring. Everything else tends to get messy. Resource groups follow a naming convention that matters more than people expect. My sheet lists the pattern I use: rg-{environment}-{service}-{region}. So something like rg-prod-vmwestus2. It sounds bureaucratic until you need to filter fifty resource groups in a PowerShell script at 2 AM during an incident and every other team has inconsistent naming. That takes twelve seconds instead of forty-five minutes of hunting.
The command shortcuts section is mostly for Azure CLI since that is what I run from my terminal. az login --tenant TENANT_ID is the starting point, but the part most people skip is az account set --subscription SUB_ID. I always set the subscription explicitly after login because my personal account has access to three different tenants and I have burned production resources on a dev subscription twice. The second time cost about eight hundred dollars in compute that ran over a weekend because a startup script pulled the wrong context. For compute, the cheat sheet has a table mapping workload types to recommended VM families. General purpose Dsv5, memory optimized Esv5, compute optimized Fsv2, storage optimized Lsv2. The counter-intuitive part most people miss is that burstable B-series VMs are not appropriate for continuous workloads. I saw a team put a SQL database on a B2s and wonder why it throttled during peak hours. B-series accumulate credits when idle and spend them under load. If your workload never idles, you are paying for a feature that does not help you and getting throttled performance anyway. The workaround is to right-size into the D family or use autoscaling with a minimum of two instances. Storage tiers are another area where the documentation is technically correct but practically misleading. Hot, cool, archive, and premium page blobs sound straightforward. What the docs do not emphasize enough is that cool tier has a 90-day minimum retention period and retrieving data early costs the same as the storage savings you earned. I had a log aggregation project that moved data to cool after thirty days and then needed access for a compliance audit. We ended up paying retrieval fees that exceeded the original hot storage cost for the entire year. The fix was to implement a lifecycle policy that transitioned data to archive after ninety days instead of moving it manually, which cost us almost nothing per terabyte and kept retrieval latency acceptable since the archive policy had explicit rehydration timelines baked in.
Networking section covers VNet peering, private endpoints, and the DNS resolver situation. Private DNS zones are the thing that catches people out. When you create a private endpoint, Azure does not automatically populate your private DNS records unless you configure it. You can pick integrated, manual, or none. Most people pick integrated and move on. But if you are peering across subscriptions or tenants, integrated creates a dependency on the peer VNet's DNS configuration, which breaks if the peer team changes anything. Manual DNS registration takes an extra five minutes but gives you full control and eliminates cross-tenant breakage. I document this distinction clearly in the cheat sheet now because we spent three weeks troubleshooting intermittent name resolution failures last year. Cost monitoring is not glamorous but it is the section I refer to most often. Azure Cost Management + Billing gives you budget alerts, cost analysis, and recommended actions. The key command I always reference is az costmanagement query --query-type Usage, which pulls detailed consumption data for scripting. What people do not realize is that cost data is not real-time. It typically lags by six to twelve hours for computed charges and can lag two to three days for marketplace items. If you are debugging a surprise cost spike on the day it happens, you will not see the full picture in the portal. The workaround is to enable diagnostic settings that stream cost data to Log Analytics, where you can query it with Kusto queries and set up alerts based on near-real-time ingestion rather than the delayed billing summary. Here is a practical snippet that covers about sixty percent of my daily workflow:
Get the Full Details

az group list --location westus2 --query "[].name" to enumerate resources in a region. az vm list --resource-group PROD-VM-WESTUS for inventory. az monitor metrics list --resource /subscriptions/SUB_ID/resourceGroups/RG_NAME/providers/Microsoft.Compute/virtualMachines/VM_NAME --metric CPUPercentage,CpuOverheadPercentage --query-time 2024-01-15T10:00:00Z --period PT1H for performance checks. These are not groundbreaking but they are the commands that take ten seconds instead of twenty minutes each time. The authentication section deserves a separate mention because it is where most scripts break. Managed identities are the standard answer and they are usually the right answer. But there are scenarios where they do not work cleanly. For example, running Azure CLI commands from a GitHub Actions pipeline requires either a service principal with a secret stored as an environment variable or a federated credential configuration. The cheat sheet has a step-by-step for federated credentials because it eliminates secret rotation headaches. You create an Azure AD app registration, assign the managed identity, configure the federated credential to trust the GitHub repository, and then authenticate without ever touching a password. It took me about forty minutes to set up the first time and saved roughly three hours per month going forward on secret management overhead. One more thing that deserves attention: resource locks. I see teams skip them entirely until someone deletes the wrong resource. There are two types: ReadOnly prevents modifications but allows reads. Delete prevents deletion but allows modifications. The one nobody mentions is that locks do not prevent resource deletion by the owner in all contexts, particularly through ARM templates with force deploy or certain automation workflows. I learned this the hard way when a deployment script removed a lock, deleted the resource group, and recreated it during a CI/CD run. The lock was technically active but the pipeline had elevated permissions that bypassed it. The lesson is that locks are a safety net for humans, not a hard guarantee against automation.
The cheat sheet lives as a Markdown file in our internal Git repository under docs/azure-reference.md. It is updated quarterly or whenever I hit a wall that the documentation did not answer clearly. The most useful entries are usually the ones I wrote after something broke, not the ones I copied from Microsoft Learn. If you want to build something similar, start with the commands and configurations you look up more than once per week. Do not try to document everything. Azure has thousands of resources and the surface area grows every release cycle. A well-maintained two-page reference beats an abandoned hundred-page wiki every time.