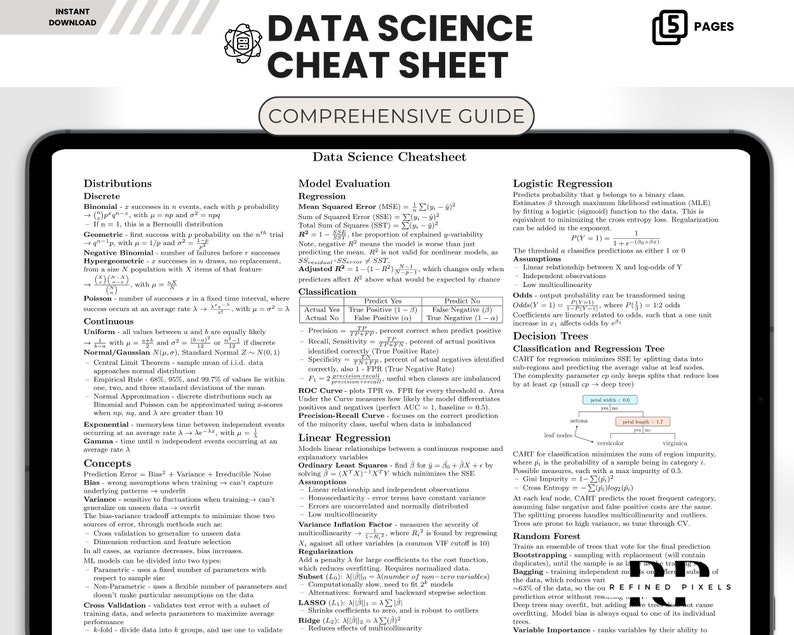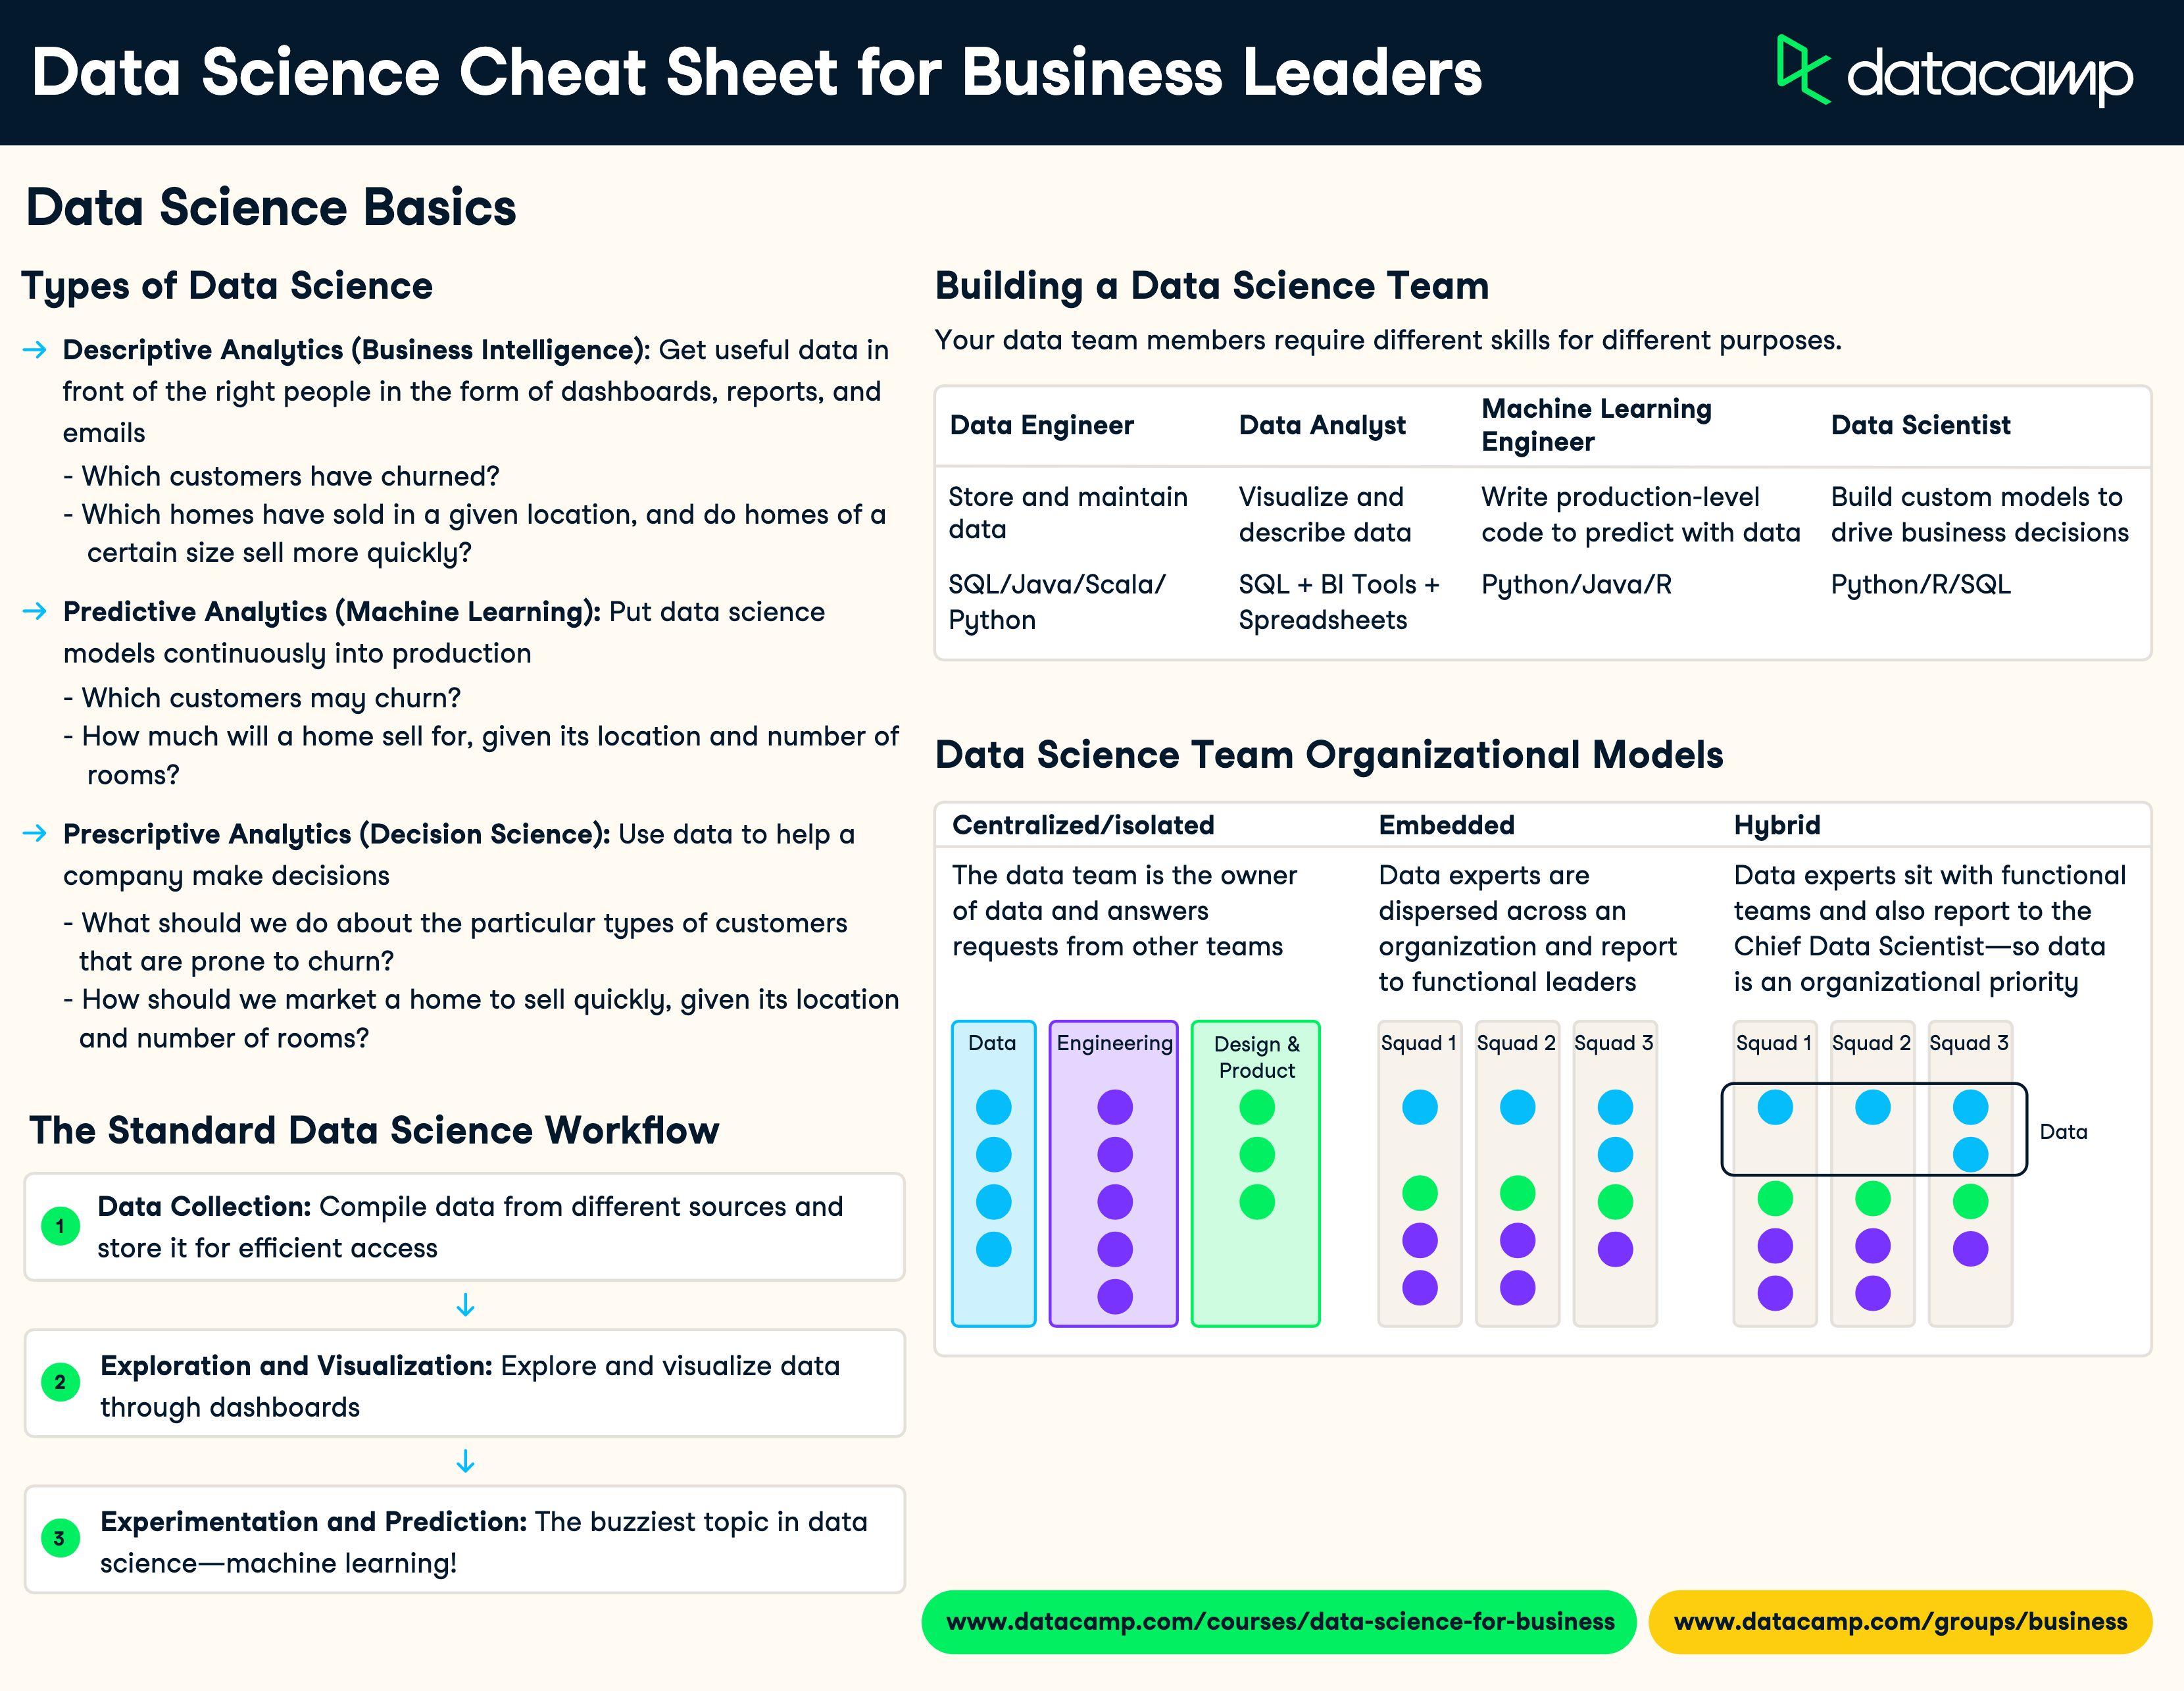
Why Most Data Science Cheat Sheets Are Garbage
Most of them are printed to 200 pages of dense syntax tables and never glanced at again. The ones that survive are the opposite — two or three pages, printed out, taped to the monitor bezel. That is what a Minimalist Data Science Cheat Sheet should be. A reference that fits your actual workflow, not a textbook compressed into a PDF. I have been building models and wrangling data for longer than I care to admit, and the cheat sheets I still use were assembled slowly over about eighteen months. I did not make a single master document. I made separate one-pagers for each task, and then I collapsed them down when I realized I was switching between five different prints during the same session. The result became what most people would call a Minimalist Data Science Cheat Sheet, and it lives on my second monitor in a plastic sleeve.
Minimalist Data Science Cheat Sheet: What Goes On It
The first thing you need to decide is scope. A minimalist sheet is defined by exclusion, not by inclusion. You are not trying to capture everything in pandas or scikit-learn. You are capturing the commands that break your flow because you cannot remember them on the spot. For data manipulation, I keep only the operations that cause the most repeated debugging. pd.read_csv with the common separators and encoding arguments. .loc[] versus .iloc[], clearly separated with one line showing the difference. Groupby aggregations in a compact form. A merge section that shows the four join types side by side, because that is where people waste time. Nothing about regex in strings. That lives in a separate file. For visualization, the sheet contains only the matplotlib and seaborn patterns that are non-obvious. Horizontal bar charts, rotated axis labels, subplots with shared axes, and color palette references. I once spent forty minutes debugging a layout issue that boiled down to forgetting plt.tight_layout(). That single function call is now the most highlighted thing on the entire sheet.
For modeling, I restrict myself to fit-transform-predict workflows, the three cross-validation strategies I actually use, and the parameter grid patterns for GridSearchCV. Feature scaling placement, train-test split ordering, and the difference between predict and predict_proba get their own boxed sections. For statistics, only the tests that matter in practice: t-test, chi-squared, ANOVA, and correlation with significance markers. Power analysis is excluded because it belongs in a planning notebook, not at a desk reference.
Get the Full Details

How to Build One Without Turning It Into Clutter
The construction process is the part nobody talks about. I started by keeping a running text file of every command I looked up each week for two months. Then I exported it, sorted by frequency, and cut anything below the threshold of appearing at least three times. The final output was roughly forty commands total across all categories. That number stayed stable for years. The format matters more than people realize. I use a single-column layout with clear visual grouping. Each section gets a thin border. Code blocks use a light gray background. Comments sit to the right of the code, not below it, because vertical space is expensive on a sheet you print at letter size. The trick is leaving breathing room. If you fill every millimeter, the sheet becomes a wall of text that slows lookup instead of helping it. I reserve approximately thirty percent of each page for margin notes and temporary reminders. That empty space gets used within a week.
I generate mine with a small Python script that reads a JSON configuration and outputs a PDF through reportlab. The script takes about twenty minutes to write and saves roughly an hour per month in lookup time. There are free templates online if you do not want to build the generator yourself. You can download a working version of this Minimalist Data Science Cheat Sheet from this repository. It includes the JSON config, the PDF generator, and a pre-built A4 print file.
A Problem I Hit and the Workaround
About a year ago, I was working on a classification task where the positive class made up less than two percent of the data. Standard stratified k-fold was collapsing in one of the folds and producing wildly inconsistent validation scores. The issue was not in the code logic. It was in how I had written the cross-validation section on the cheat sheet — it showed StratifiedKFold with no mention of the edge case where a minority class sample drops below the number of requested folds. The fix was adding a single line to the reference: StratifiedKFold(n_splits=min(5, min(y))), wrapped in a try-except comment explaining the fallback. After that, the breakdown stopped happening. It is a tiny detail but exactly the kind of thing that eats an afternoon if you do not have it visible. I also added a note about GroupKFold for time-series leakage scenarios. That one caught me twice before I put it down. A similar entry goes for TimeSeriesSplit, though I usually default to that one anyway.
What This Approach Gets Wrong
A minimalist cheat sheet will fail you in three specific situations, and you should know about them before you invest time in one. First, it cannot keep pace with library updates. Pandas drops support for functions. Scikit-learn deprecates parameters. If your sheet is six months old, some of the examples will raise warnings or errors without obvious explanation. The workaround is to review the sheet quarterly and run every example against the installed versions. I keep a changelog sidebar on the physical copy and update it with version numbers. Second, minimalist means you will forget nuances. The sheet will tell you how to do a merge, but it will not explain why a left merge duplicates rows when the key is not unique. You need a secondary resource for that. A good notebook with worked failures fills that gap better than expanding the sheet itself.
Third, the physical format introduces friction. If you print it, you must re-print when updates accumulate. If you keep it digital, you lose the benefit of glanceable proximity. I solved this by laminating the current version and keeping an archived folder of previous iterations with date stamps. When I notice something on the wall version that looks wrong, I check the archive to see if it changed.
What Beginners Miss
The biggest mistake I see is treating the cheat sheet as a learning tool rather than a retrieval tool. People read through it like a chapter and expect it to stick. It will not. The value comes from using it while the work is happening, then returning to it after to mark which sections became reference points and which gathered dust. Another mistake is building it alone. If you work with a team, merge sheets once a month. Two or three people catching different edge cases produces a far more durable reference than any single person's memory. I learned this the hard way when a colleague spotted a df.drop_duplicates() behavior I had been silently avoiding for months because my own sheet never mentioned the subset parameter.
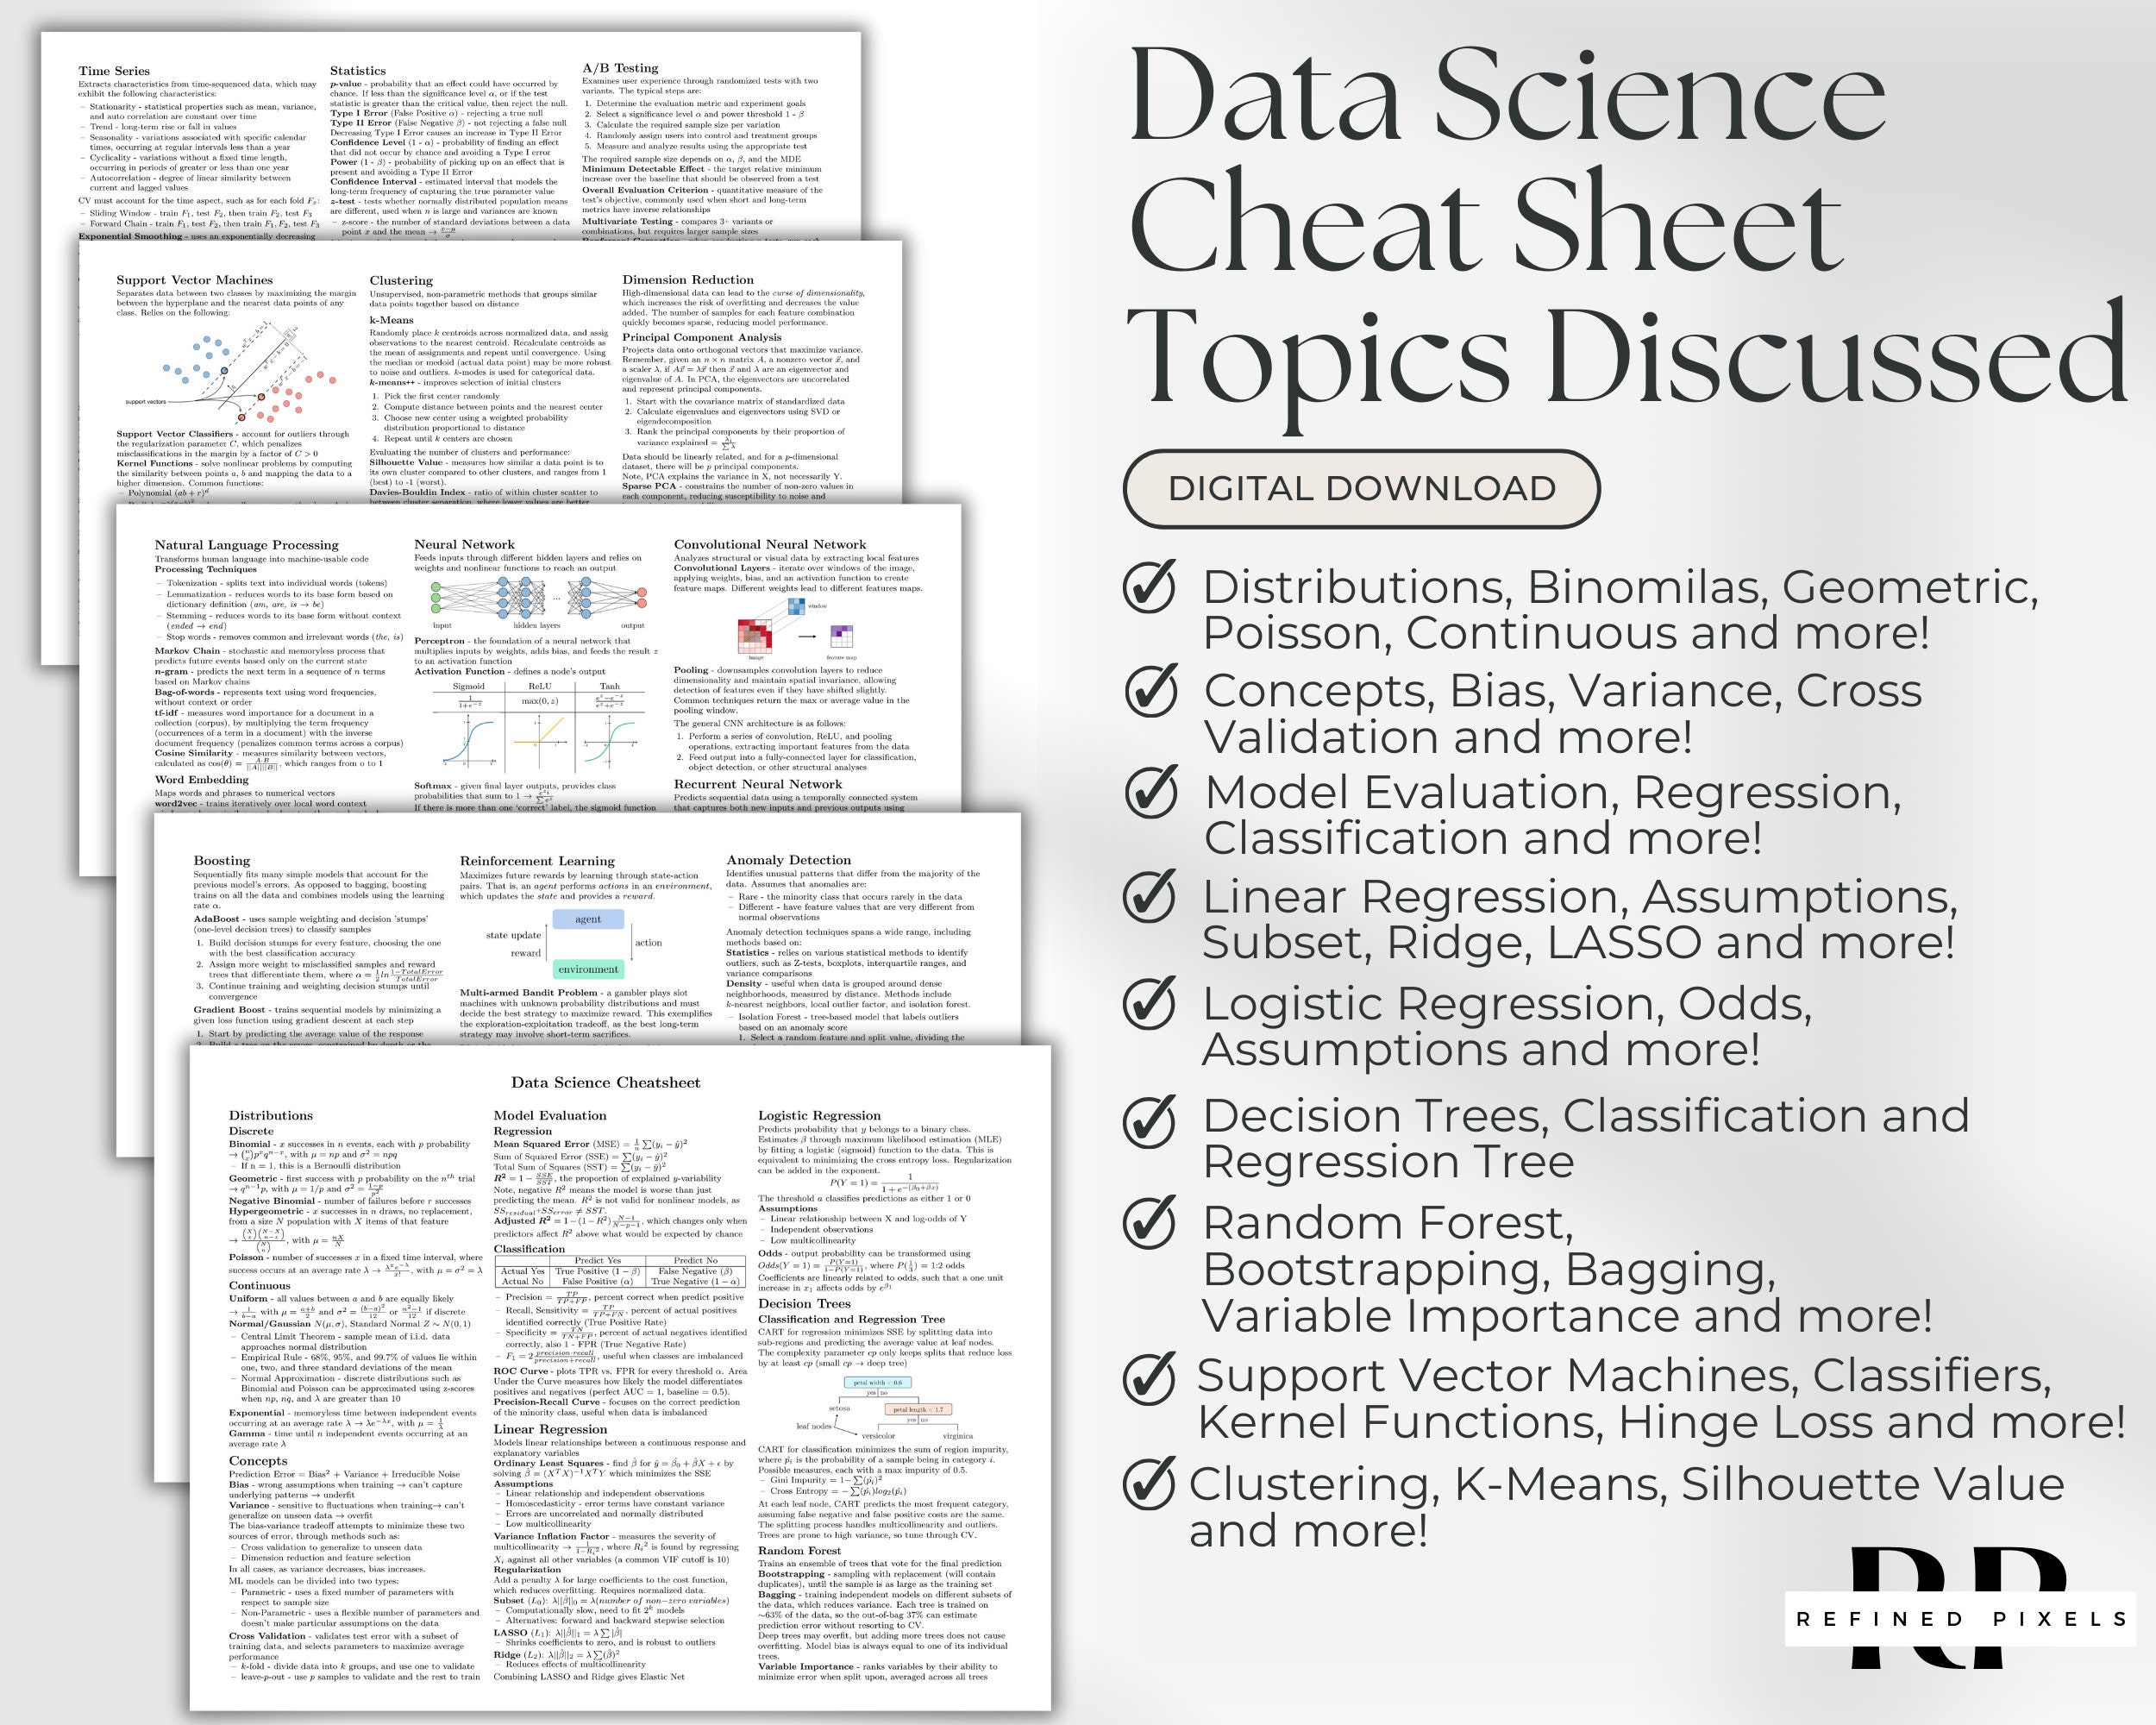
When a Cheat Sheet Is Not the Right Move
If you are still in the early learning phase, before you have done enough repeated work to identify patterns, a cheat sheet adds overhead without compensation. You are better off with a well-organized set of starter notebooks. The cost of maintaining a reference exceeds the cost of looking things up for another month or two. Similarly, if your work is heavily specialized — say you spend most of your time on NLP tokenization pipelines or reinforcement learning reward shaping — a general minimalist sheet will be too thin. You need a domain-specific reference instead, or you accept that lookup time will remain higher until you internalize the routine commands. The template available at the link above covers the generalist case. It is built around the workflows that appear in roughly eighty percent of data science roles: cleaning, exploration, feature engineering, model selection, and basic evaluation. Everything beyond that is a separate exercise.